# RAD Platform — Google Cloud Certification Guides (full text)
> Single-fetch export of every certification lab map and section exploration
> guide on https://docs.radmodules.dev — generated from the same markdown
> source as the site. Index: https://docs.radmodules.dev/llms.txt
> Note: on this site PDE = Professional Cloud DevOps Engineer (not Data
> Engineer) and PCDE = Professional Cloud Database Engineer.
---
# Associate Cloud Engineer (ACE) Certification Lab Map
The Associate Cloud Engineer certification validates that you can deploy applications, monitor operations, and manage enterprise solutions on Google Cloud using both the console and the command line. The RAD platform's four foundation modules — `Services_GCP` (shared VPC networking, Cloud SQL, Redis, Filestore, GKE Autopilot, service accounts), `App_CloudRun` (Cloud Run v2 deployment engine), `App_GKE` (GKE deployment engine), and the `App_Common` shared library (secrets, IAM, storage, CMEK, CI/CD plumbing) — give you a live, inspectable lab: every toggle in your deployment portal maps to real GCP resources you can then explore with `gcloud`, `kubectl`, and the console. Application wrapper modules (Django, WordPress, etc.) exist on top of these but are not needed for exam preparation.
## How to use this guide
- Deploy one of the profiles below from your deployment portal, then work through the matching section guide.
- Every section-guide subsection has a **Try it** block — do the CLI steps, not just the console clicks. The ACE exam assumes `gcloud`/`kubectl` fluency.
- Use the coverage legend to know which exam topics you must study outside the platform; the section guides flag these in **Beyond the modules** blocks.
- ACE is entry-level: focus on creating, inspecting, and modifying resources, not on architecture trade-offs.
**Coverage legend**
| Symbol | Meaning |
|---|---|
| ✅ | Fully demonstrated — deploy it, see it, modify it in the RAD platform |
| 🟡 | Partially demonstrated — the modules touch the concept; supplement with docs |
| 📘 | Concept-only — not implemented by the modules; study pointers provided |
## Deployment profiles
### Profile: Baseline platform
*Purpose:* the shared infrastructure layer every other profile builds on — VPC, Cloud NAT, private Cloud SQL, NFS/Redis VM, service accounts.
*Modules:* `Services_GCP` only.
| Variable | Value |
|---|---|
| `project_id` | your project ID |
| `tenant_id` | `demo` (default) |
| `create_postgres` | `true` (default) |
| `create_network_filesystem` | `true` (default) |
| `support_users` | your email address |
| `resource_labels` | `{ environment = "dev", cost-center = "lab" }` |
*Estimated incremental cost:* low–moderate — the dominant drivers are the `db-custom-1-3840` Cloud SQL instance and the `e2-small` NFS VM running 24/7.
### Profile: Serverless application
*Purpose:* Cloud Run service with database, storage buckets, NFS mount, revisions, and scheduled backups — covers most of Sections 2 and 3.
*Modules:* Baseline platform + `App_CloudRun`.
| Variable | Value |
|---|---|
| `container_image_source` | `prebuilt` |
| `container_image` | `us-docker.pkg.dev/cloudrun/container/hello` |
| `min_instance_count` | `0` (default — scale to zero) |
| `max_instance_count` | `3` |
| `database_type` | `POSTGRES` (default) |
| `storage_buckets` | one entry, e.g. `[{ name_suffix = "media" }]` |
| `support_users` | your email address |
*Estimated incremental cost:* low — Cloud Run scales to zero; cost is dominated by what the baseline platform already runs.
### Profile: Kubernetes application
*Purpose:* GKE Autopilot cluster plus a namespaced workload with HPA, ResourceQuota, PodDisruptionBudget, and NetworkPolicy — the `kubectl` half of the exam.
*Modules:* `Services_GCP` (re-applied with GKE enabled) + `App_GKE`.
| Variable | Value |
|---|---|
| `create_google_kubernetes_engine` (Services_GCP) | `true` |
| `gke_cluster_mode` (Services_GCP) | `AUTOPILOT` (default) |
| `container_image_source` (App_GKE) | `prebuilt` |
| `container_image` (App_GKE) | `us-docker.pkg.dev/cloudrun/container/hello` |
| `enable_resource_quota` (App_GKE) | `true` |
| `enable_network_segmentation` (App_GKE) | `true` |
*Estimated incremental cost:* moderate — Autopilot bills per pod resource request plus the cluster management fee.
### Profile: Operations & security add-ons
*Purpose:* billing budget, alerting, audit logs, edge security, and IAP for Sections 1, 3.4, and 4. Apply on top of either application profile.
*Modules:* `Services_GCP` + one application module.
| Variable | Value |
|---|---|
| `create_billing_budget` (Services_GCP) | `true` |
| `budget_amount` (Services_GCP) | `100` (default) |
| `configure_email_notification` (Services_GCP) | `true` |
| `notification_alert_emails` (Services_GCP) | your email address |
| `enable_audit_logging` (Services_GCP or app module) | `true` |
| `enable_cloud_armor` (App_CloudRun) | `true`; add `application_domains` only if you want your own hostname |
| `enable_iap` + `iap_authorized_users` (App_CloudRun) | `true` + `["user:you@example.com"]` |
*Estimated incremental cost:* moderate — the global external load balancer (forwarding rule + Cloud Armor policy) is the dominant driver; audit logging adds Cloud Logging volume.
## Section 1: Setting up a cloud solution environment (~23% of the exam)
The modules deploy into an existing project, enable ~45 APIs automatically, create least-privilege service accounts, and can create a real billing budget — but project creation, resource hierarchy, and Cloud Identity remain console/`gcloud` exercises.
| Exam topic | Coverage | Where in RAD | Guide |
|---|---|---|---|
| 1.1 Enabling APIs within projects | ✅ | `enable_services` (default `true`), `additional_apis` | [Section 1 guide](ACE_Section_1_Exploration_Guide.md#11-setting-up-cloud-projects-and-accounts) |
| 1.1 Granting IAM roles within a project | ✅ | dedicated SAs + predefined-role bindings | [Section 1 guide](ACE_Section_1_Exploration_Guide.md#11-setting-up-cloud-projects-and-accounts) |
| 1.1 Creating projects / resource hierarchy / Cloud Identity | 📘 | modules deploy into an existing `project_id` only | [Section 1 guide](ACE_Section_1_Exploration_Guide.md#11-setting-up-cloud-projects-and-accounts) |
| 1.1 Assessing quotas | 🟡 | `max_instance_count` and friends consume quotas; no quota management | [Section 1 guide](ACE_Section_1_Exploration_Guide.md#11-setting-up-cloud-projects-and-accounts) |
| 1.2 Budgets and alerts | ✅ | `create_billing_budget`, `budget_amount` (default `100`), `budget_alert_thresholds` | [Section 1 guide](ACE_Section_1_Exploration_Guide.md#12-managing-billing-configuration) |
| 1.2 Linking billing accounts / billing exports | 📘 | billing account is auto-discovered, never managed | [Section 1 guide](ACE_Section_1_Exploration_Guide.md#12-managing-billing-configuration) |
## Section 2: Planning and implementing a cloud solution (~30% of the exam)
The strongest section for the lab: Cloud Run and GKE deployments are fully demonstrated, along with Cloud SQL, GCS, Filestore, Memorystore, a custom-mode VPC, Cloud NAT, firewall rules, and a global external load balancer with Cloud Armor. Compute Engine appears only as the self-managed NFS VM; App Engine and Cloud Functions are not implemented.
| Exam topic | Coverage | Where in RAD | Guide |
|---|---|---|---|
| 2.1 Cloud Run deployment and autoscaling | ✅ | `min_instance_count` (default `0`), `max_instance_count` (default `1`), `container_resources` | [Section 2 guide](ACE_Section_2_Exploration_Guide.md#21-planning-and-implementing-compute-resources) |
| 2.1 GKE workloads (Deployment/StatefulSet, HPA) | ✅ | `workload_type`, `stateful_pvc_enabled`, `container_resources` | [Section 2 guide](ACE_Section_2_Exploration_Guide.md#21-planning-and-implementing-compute-resources) |
| 2.1 Compute Engine VMs / MIGs | 🟡 | the NFS VM MIG only | [Section 2 guide](ACE_Section_2_Exploration_Guide.md#21-planning-and-implementing-compute-resources) |
| 2.1 App Engine, Cloud Functions, Spot VMs | 📘 | not implemented | [Section 2 guide](ACE_Section_2_Exploration_Guide.md#21-planning-and-implementing-compute-resources) |
| 2.2 Cloud SQL, GCS, Filestore, Memorystore | ✅ | `create_postgres` (default `true`), `storage_buckets`, `create_filestore_nfs`, `create_redis` | [Section 2 guide](ACE_Section_2_Exploration_Guide.md#22-planning-and-implementing-storage-and-data-solutions) |
| 2.2 AlloyDB, Firestore | ✅ | `enable_alloydb`, `create_firestore` (both default `false`) | [Section 2 guide](ACE_Section_2_Exploration_Guide.md#22-planning-and-implementing-storage-and-data-solutions) |
| 2.2 BigQuery, Spanner, Bigtable, Pub/Sub messaging | 📘 | not implemented | [Section 2 guide](ACE_Section_2_Exploration_Guide.md#22-planning-and-implementing-storage-and-data-solutions) |
| 2.3 VPC, subnets, firewall rules, Cloud NAT, PSA | ✅ | `availability_regions`, `subnet_cidr_range` | [Section 2 guide](ACE_Section_2_Exploration_Guide.md#23-planning-and-implementing-networking-resources) |
| 2.3 Load balancing, Cloud Armor, CDN | ✅ | `enable_cloud_armor`, `application_domains`, `enable_cdn` | [Section 2 guide](ACE_Section_2_Exploration_Guide.md#23-planning-and-implementing-networking-resources) |
| 2.3 Shared VPC, Cloud DNS, VPN/Interconnect | 📘 | not implemented | [Section 2 guide](ACE_Section_2_Exploration_Guide.md#23-planning-and-implementing-networking-resources) |
| 2.4 Infrastructure as code workflow | 🟡 | the entire repository (OpenTofu modules), `deploy_application`, Cloud Build pipelines; portal abstracts state | [Section 2 guide](ACE_Section_2_Exploration_Guide.md#24-planning-and-implementing-resources-through-infrastructure-as-code) |
## Section 3: Ensuring successful operation of a cloud solution (~27% of the exam)
Revision management, traffic splitting, CI/CD with Cloud Build and Cloud Deploy, scheduled database backups, GCS lifecycle rules, static IPs, a full set of preconfigured alert policies, and synthetic uptime checks on publicly reachable endpoints are all live. Log routing/sinks are study-outside topics.
| Exam topic | Coverage | Where in RAD | Guide |
|---|---|---|---|
| 3.1 Revisions, traffic splitting, canary releases | ✅ | `traffic_split`, `max_revisions_to_retain` (default `7`) | [Section 3 guide](ACE_Section_3_Exploration_Guide.md#31-managing-compute-resources) |
| 3.1 CI/CD with Cloud Build and Cloud Deploy | ✅ | `enable_cicd_trigger`, `cloud_deploy_stages` | [Section 3 guide](ACE_Section_3_Exploration_Guide.md#31-managing-compute-resources) |
| 3.1 Kubernetes operations (kubectl, HPA, PDB, quota) | ✅ | `enable_resource_quota`, `enable_pod_disruption_budget` | [Section 3 guide](ACE_Section_3_Exploration_Guide.md#31-managing-compute-resources) |
| 3.1 VM lifecycle, SSH, snapshots, node pools | 🟡 | NFS VM MIG with daily snapshots | [Section 3 guide](ACE_Section_3_Exploration_Guide.md#31-managing-compute-resources) |
| 3.2 Database backups, restore, custom SQL | ✅ | `backup_schedule` (default `0 2 * * *`), `enable_backup_import`, `enable_custom_sql_scripts` | [Section 3 guide](ACE_Section_3_Exploration_Guide.md#32-managing-storage-and-database-solutions) |
| 3.2 GCS object lifecycle and versioning | ✅ | `storage_buckets[].lifecycle_rules`, `backup_retention_days` | [Section 3 guide](ACE_Section_3_Exploration_Guide.md#32-managing-storage-and-database-solutions) |
| 3.3 Static IPs, multi-region subnets | 🟡 | `reserve_static_ip` (default `true`), `availability_regions` | [Section 3 guide](ACE_Section_3_Exploration_Guide.md#33-managing-networking-resources) |
| 3.3 Routes, peering, DNS operations | 📘 | not implemented | [Section 3 guide](ACE_Section_3_Exploration_Guide.md#33-managing-networking-resources) |
| 3.4 Alert policies, channels, dashboards | ✅ | `support_users`, `alert_policies`, `alert_cpu_threshold` (default `80`) | [Section 3 guide](ACE_Section_3_Exploration_Guide.md#34-monitoring-and-logging) |
| 3.4 Audit logs | ✅ | `enable_audit_logging` | [Section 3 guide](ACE_Section_3_Exploration_Guide.md#34-monitoring-and-logging) |
| 3.4 Uptime checks | ✅ | `uptime_check_config` (default `{ enabled = false, path = "/" }` — opt in with `enabled = true`) | [Section 3 guide](ACE_Section_3_Exploration_Guide.md#34-monitoring-and-logging) |
| 3.4 Log sinks, log-based metrics | 📘 | not implemented | [Section 3 guide](ACE_Section_3_Exploration_Guide.md#34-monitoring-and-logging) |
## Section 4: Configuring access and security (~20% of the exam)
Strong coverage: every module creates dedicated least-privilege service accounts, App_GKE uses Workload Identity, Services_GCP can create a Workload Identity Federation pool, secrets live in Secret Manager with optional automatic rotation, and IAP can gate both platforms.
| Exam topic | Coverage | Where in RAD | Guide |
|---|---|---|---|
| 4.1 Viewing and creating IAM policies, role types | ✅ | predefined-role-only bindings, per-resource grants | [Section 4 guide](ACE_Section_4_Exploration_Guide.md#41-managing-identity-and-access-management-iam) |
| 4.1 Audit logs for access review | ✅ | `enable_audit_logging` | [Section 4 guide](ACE_Section_4_Exploration_Guide.md#41-managing-identity-and-access-management-iam) |
| 4.1 Custom roles, IAM Conditions, Policy Troubleshooter | 📘 | not implemented | [Section 4 guide](ACE_Section_4_Exploration_Guide.md#41-managing-identity-and-access-management-iam) |
| 4.2 Dedicated service accounts on compute | ✅ | `cloudrun-sa-*`/`gke-sa-*` runtime identities | [Section 4 guide](ACE_Section_4_Exploration_Guide.md#42-managing-service-accounts) |
| 4.2 Workload Identity (GKE) and WIF (keyless CI) | ✅ | KSA→GSA binding, `enable_workload_identity_federation` | [Section 4 guide](ACE_Section_4_Exploration_Guide.md#42-managing-service-accounts) |
| 4.2 Secret Manager and rotation | ✅ | `secret_environment_variables`, `enable_auto_password_rotation` | [Section 4 guide](ACE_Section_4_Exploration_Guide.md#42-managing-service-accounts) |
| 4.2 IAP identity-gated access | ✅ | `enable_iap`, `iap_authorized_users`/`iap_authorized_groups` | [Section 4 guide](ACE_Section_4_Exploration_Guide.md#42-managing-service-accounts) |
| 4.2 SA key management, short-lived tokens | 📘 | deliberately keyless — study `gcloud iam service-accounts keys` separately | [Section 4 guide](ACE_Section_4_Exploration_Guide.md#42-managing-service-accounts) |
---
# ACE Certification Preparation Guide: Section 1 — Setting up a cloud solution environment (~23% of the exam)
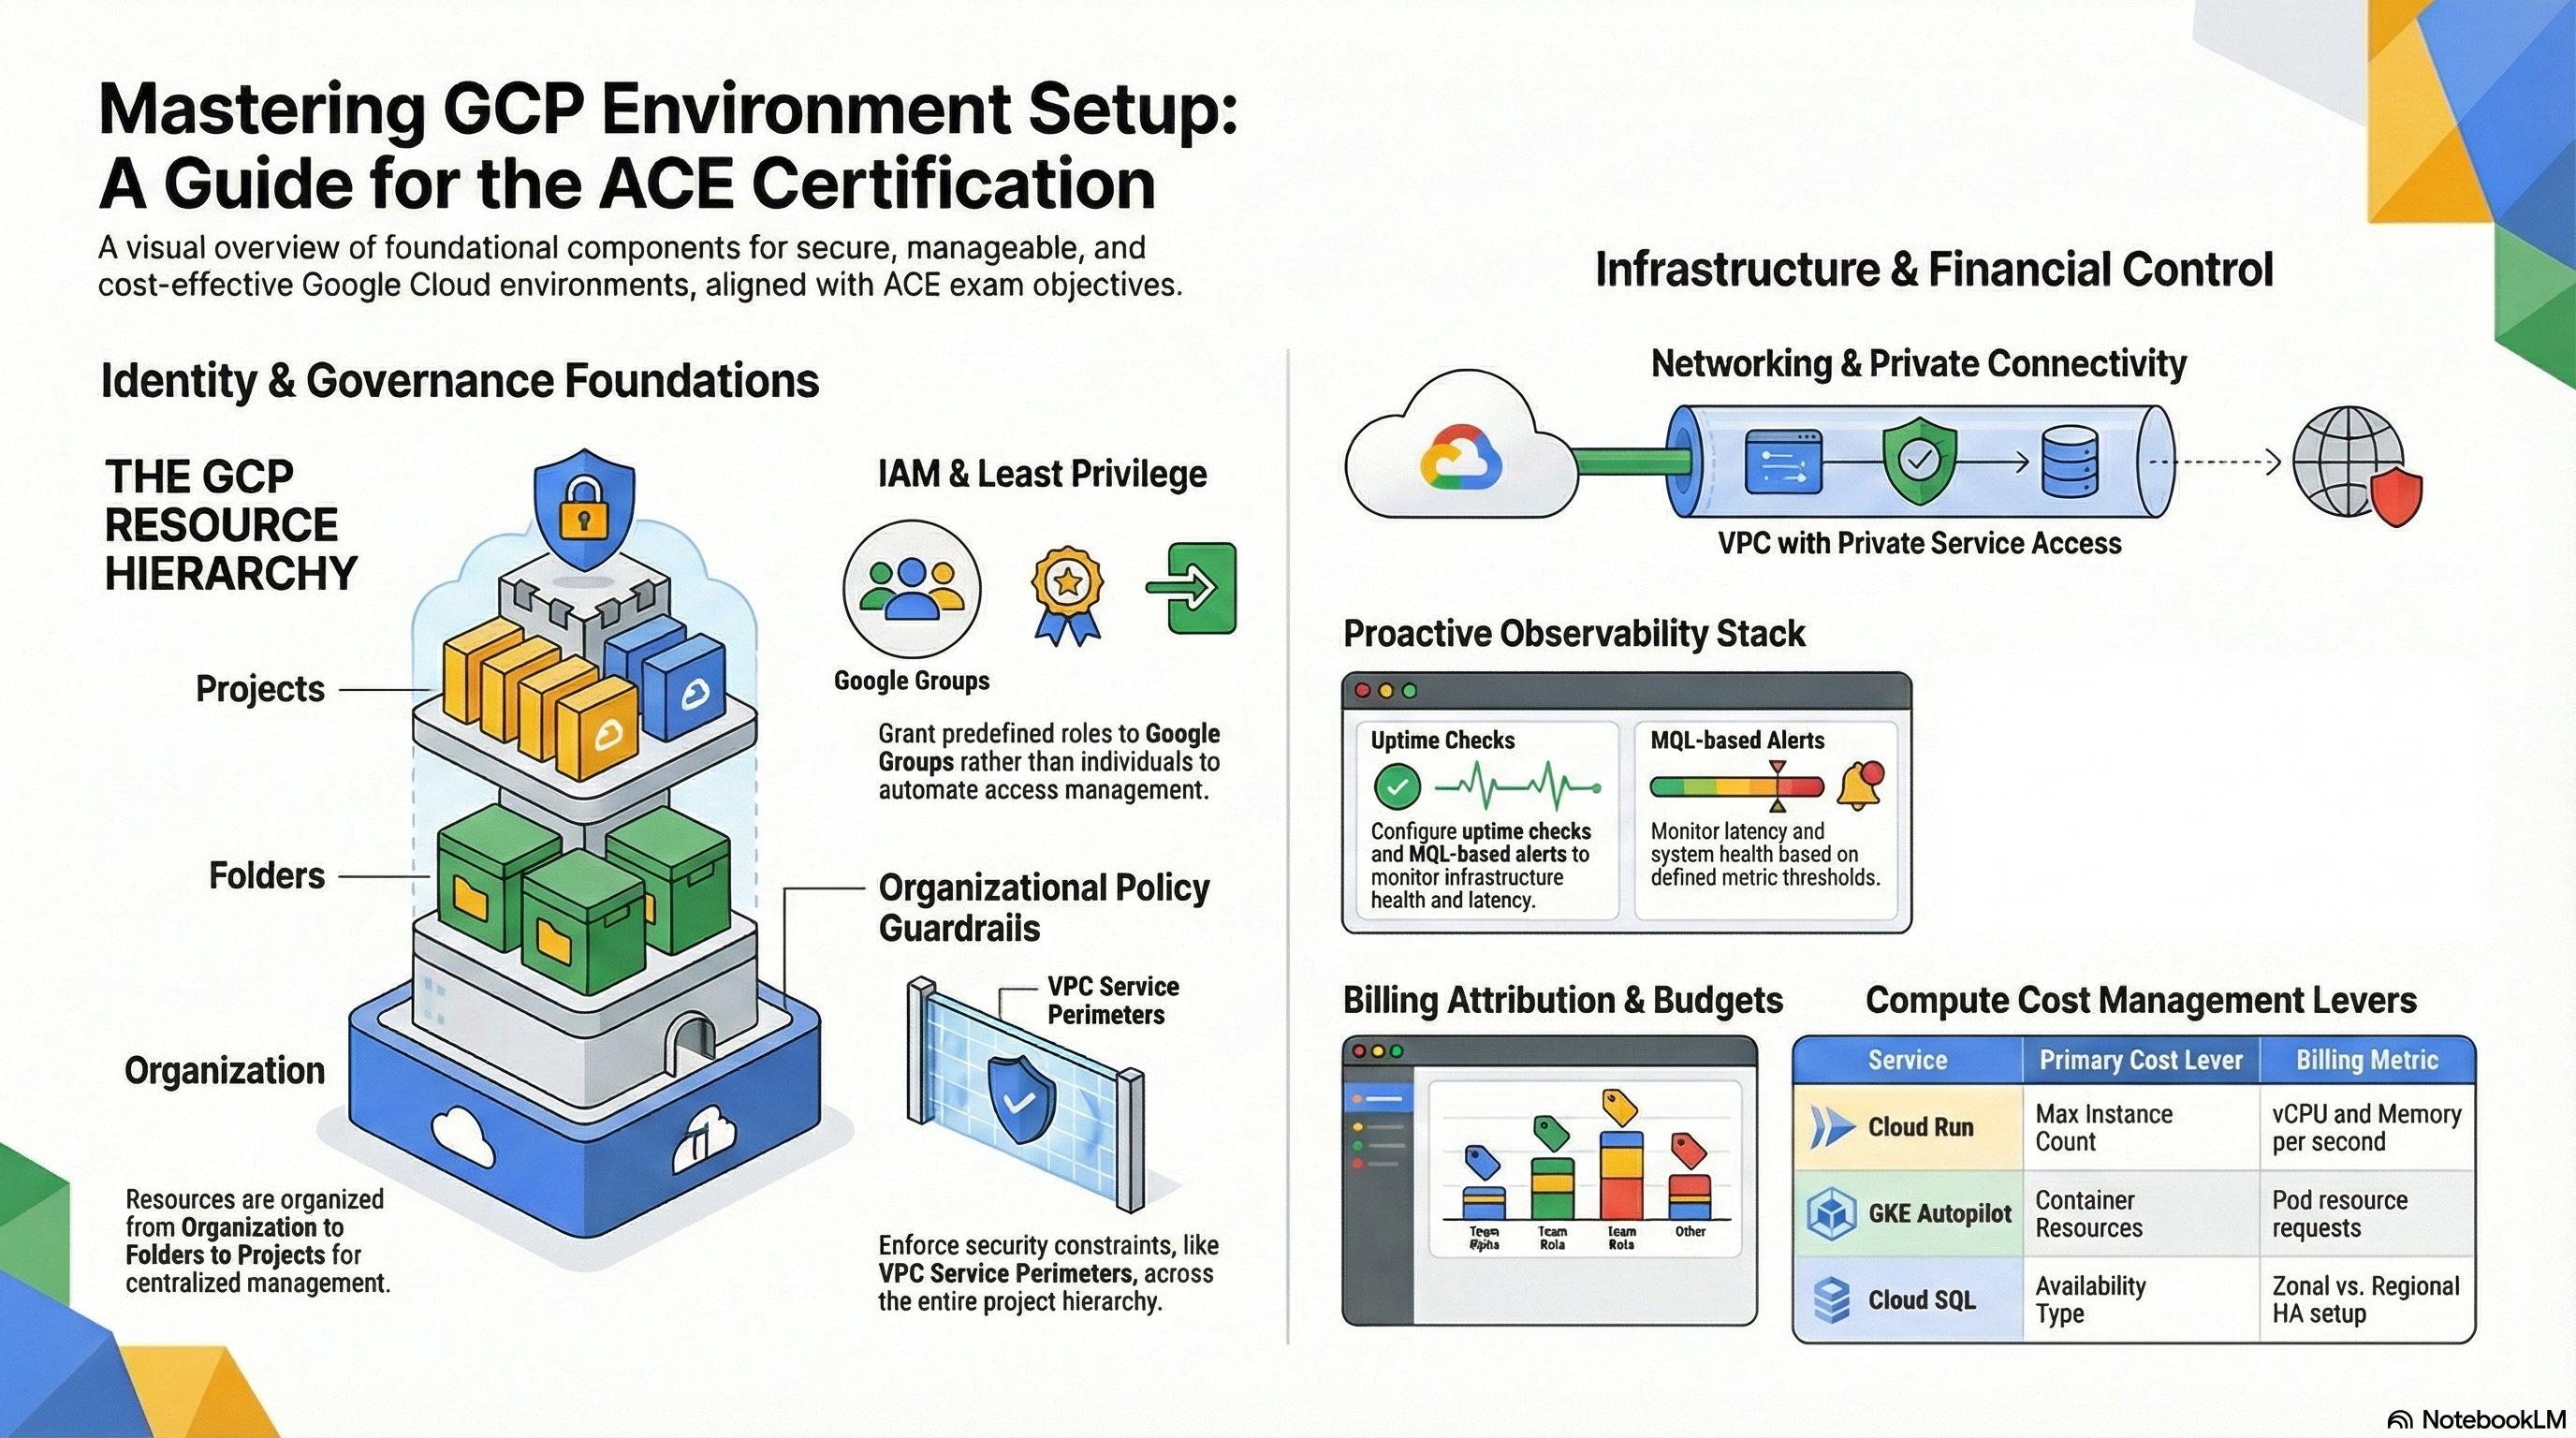 > 📚 **Official exam guide:** [Associate Cloud Engineer certification](https://cloud.google.com/learn/certification/cloud-engineer) — always confirm section weightings against the current Google Cloud exam guide.
This guide covers exam Section 1 using the RAD platform foundation modules as a hands-on lab. The module exercised here is almost entirely `Services_GCP` — the platform layer deployed once per project. Deploy the **Baseline platform** profile from the [Lab Map](ACE_Certification_Guide.md) before starting; add the **Operations & security add-ons** profile (specifically `create_billing_budget = true`) for subsection 1.2.
---
## 1.1 Setting up cloud projects and accounts
> ⏱ ~60 min · 💰 no additional cost beyond the baseline profile · ⚙️ Requires: default Baseline platform deployment
**Why the exam cares** — The exam tests whether you understand the project as the fundamental billing, IAM, and API boundary: how projects relate to folders and organizations, why APIs must be enabled before resources can be created, how identities (users, groups, service accounts) are granted roles, and how to check quotas before they bite you. Scenario questions often hinge on knowing that a project ID is immutable, that APIs are enabled per project, and that groups are preferred over individual user bindings.
**How RAD implements it** — Every module deploys into an *existing* project named by `project_id` (required, no default); the modules never create projects, folders, or organizations. On apply, `Services_GCP` enables roughly 45 service APIs when `enable_services` (default `true`) is set — the list includes `compute.googleapis.com`, `run.googleapis.com`, `container.googleapis.com`, `sqladmin.googleapis.com`, `secretmanager.googleapis.com`, `cloudkms.googleapis.com`, and more; `additional_apis` (default `[]`) appends your own. Identity wiring:
| Variable | Default | Effect |
|---|---|---|
| `project_id` | — (required) | Target project for all resources |
| `tenant_id` | `"demo"` | Tenant suffix used in resource naming |
| `enable_services` | `true` | Enables the ~45 required APIs at apply time |
| `additional_apis` | `[]` | Extra APIs to enable |
| `support_users` | `[]` | Emails that receive monitoring/budget notification channels |
| `resource_labels` | `{}` | Labels merged onto every module-managed resource |
| `resource_creator_identity` | platform deployer SA | Service account Terraform runs as |
`Services_GCP` creates five dedicated service accounts per deployment — `cloudbuild-sa-{prefix}`, `clouddeploy-sa-{prefix}`, `cloudrun-sa-{prefix}`, `nfs-sa-{prefix}`, and `gke-sa-{prefix}` — each bound to predefined roles only. Organization context is auto-discovered: the platform reads `org_id` from the project data source, and org-dependent features (VPC-SC, SCC notifications) skip gracefully when the project has no organization or the caller lacks org-level permission.
**Try it**
1. In the portal, set `resource_labels = { environment = "dev", team = "platform" }` and redeploy. In the console go to **Cloud SQL > your instance** and confirm the labels appear under the instance details.
2. Inspect the project and its enabled APIs from Cloud Shell:
```bash
gcloud projects describe $GOOGLE_CLOUD_PROJECT
gcloud services list --enabled --filter="config.name:run.googleapis.com OR config.name:sqladmin.googleapis.com"
```
Note the three identifiers in the `describe` output: project ID (immutable), project number, and display name (changeable).
3. List the service accounts the module created and inspect one binding:
```bash
gcloud iam service-accounts list --filter="email:cloudrun-sa"
gcloud projects get-iam-policy $GOOGLE_CLOUD_PROJECT \
--flatten="bindings[].members" \
--filter="bindings.members:cloudrun-sa" \
--format="table(bindings.role)"
```
4. Check a quota your deployment consumes: **IAM & Admin > Quotas & System Limits**, filter by *Cloud SQL Admin API*. CLI equivalent: `gcloud compute regions describe us-central1 --format="table(quotas.metric,quotas.usage,quotas.limit)"` for Compute quotas.
5. You know it worked when the IAM policy query returns only narrow predefined roles (no `roles/editor`) and the enabled-services list contains the APIs above.
**Check yourself**
Q1: A teammate deploys the Baseline platform profile into a fresh project and the apply fails with "API not enabled" errors for Compute Engine. They had set enable_services = false. What is the fastest fix, and why does the default avoid this?
A: Re-enable `enable_services = true` (or run `gcloud services enable compute.googleapis.com ...` manually). GCP refuses to create any resource whose API is disabled in the project; the module's default enables all ~45 required APIs up front precisely so that downstream resources (VPC, Cloud SQL, NAT) can be created in one apply.
Q2: You need 12 operations engineers to receive monitoring alerts. Should you list 12 addresses in support_users or one Google Group address?
A: Use one group address. The module creates one notification channel per entry, and IAM/notification management best practice is to bind groups, not individuals — membership changes in Cloud Identity / Google Workspace then propagate automatically without touching the deployment.
Q3: What is the difference between the project ID, project number, and project name?
A: The project ID is a globally unique, immutable, human-chosen string used in APIs and URLs; the project number is a globally unique, immutable numeric identifier assigned by Google (it appears in default service account emails); the project name is a mutable display label with no uniqueness requirement.
**Beyond the modules** — The exam also tests things the modules deliberately do not do:
- *Creating projects and hierarchy:* practice `gcloud projects create my-lab-project --folder=FOLDER_ID` and browse **IAM & Admin > Manage Resources** to see Organization → Folder → Project inheritance.
- *Cloud Identity:* user and group lifecycle is managed in admin.google.com, not in GCP. Know that IAM policies can bind `user:`, `group:`, `serviceAccount:`, and `domain:` principals.
- *Quota increases:* find a quota in **IAM & Admin > Quotas & System Limits** and walk through (without submitting) the **Edit Quotas** increase request flow; quota increases are requests, not instant changes.
- *Org policies:* browse **IAM & Admin > Organization Policies** (e.g. `constraints/compute.vmExternalIpAccess`). The modules do not manage org policy constraints.
**⚠️ Exam trap** — Enabling an API and granting IAM permission are independent: a user with `roles/run.admin` still cannot deploy to Cloud Run if `run.googleapis.com` is disabled in the project, and enabling the API grants no one any access.
---
## 1.2 Managing billing configuration
> ⏱ ~40 min · 💰 the budget itself is free; alert emails are free · ⚙️ Requires: `create_billing_budget = true` (Operations & security add-ons profile)
**Why the exam cares** — The exam expects you to link projects to billing accounts, create budgets with threshold alerts, and export billing data for analysis. Decision criteria: budgets *notify*, they never stop spending; billing exports to BigQuery are the only way to analyze historical cost by label; the Billing Account Administrator role is separate from project IAM.
**How RAD implements it** — `Services_GCP` creates a real Cloud Billing budget when `create_billing_budget` (default `false`) is enabled. The billing account is *auto-discovered* from the project — there is no billing-account variable, and the module never links or unlinks projects. The budget is scoped with a `budget_filter` to the current project only.
| Variable | Default | Effect |
|---|---|---|
| `create_billing_budget` | `false` | Creates the project-scoped budget |
| `budget_amount` | `100` | Budget amount in the billing account's currency |
| `budget_alert_thresholds` | `[0.5, 0.9, 1.0]` | One threshold rule per entry (50%, 90%, 100%) |
| `budget_alert_emails` | `[]` | Merged with `support_users` into email notification channels |
The budget wires the email channels and keeps the default IAM recipients enabled, so Billing Account Administrators/Users also get notified. Separately, `resource_labels` (default `{}`) propagates onto every module-managed resource, which is what makes label-based cost filtering in Billing Reports and BigQuery exports possible.
**Try it**
1. In the portal set `create_billing_budget = true`, `budget_amount = 50`, and add your email to `budget_alert_emails`. Redeploy `Services_GCP`.
2. Verify in the console under **Billing > Budgets & alerts** — you should see "Budget for ``" with three threshold rules. CLI:
```bash
BILLING_ACCOUNT=$(gcloud billing projects describe $GOOGLE_CLOUD_PROJECT \
--format="value(billingAccountName)")
gcloud billing budgets list --billing-account=${BILLING_ACCOUNT##*/}
```
3. Explore label-based cost attribution: **Billing > Reports**, open the **Labels** filter on the right and select a key you set in `resource_labels` (data appears with up to a day's delay).
4. You know it worked when `gcloud billing budgets list` shows your budget with `thresholdRules` at 0.5, 0.9, and 1.0.
**Check yourself**
Q1: Your budget fired its 100% alert but resources keep running and costs keep accruing. Is something broken?
A: No. Budgets only send notifications (email and optionally Pub/Sub) — they never cap spending or stop resources. Automated cost response requires you to wire a Pub/Sub budget notification to your own automation (e.g. a function that disables billing), which the exam expects you to know is a custom build, not a checkbox.
Q2: Finance wants a monthly per-team cost breakdown of everything the RAD platform deploys. Which two pieces make this possible?
A: (1) Consistent `resource_labels` (e.g. `team = "platform"`) on every resource, which the modules apply automatically, and (2) a billing export to BigQuery, configured at the billing-account level under **Billing > Billing export**, which you then query grouping by the label key. Billing Reports filtering by label works for ad-hoc views, but BigQuery is the answer for programmatic/chargeback reporting.
**Beyond the modules** — Not implemented by the foundation modules; practice these directly:
- *Linking a project to a billing account:* `gcloud billing projects link my-project --billing-account=0X0X0X-0X0X0X-0X0X0X` (requires Billing Account User on the account + Project Billing Manager or Owner on the project).
- *Billing exports:* enable the BigQuery export (standard usage cost) under **Billing > Billing export**; there is no Terraform in this repo doing it.
- *Billing IAM:* know `roles/billing.admin`, `roles/billing.user` (can link projects), and `roles/billing.viewer` and that they live on the billing account, not the project.
**⚠️ Exam trap** — Budget thresholds can alert on *forecasted* spend as well as actual spend; also, a budget scoped to a billing account is not the same as one scoped to a project — the module's budget uses a project filter, so other projects on the same billing account are not counted.
---
# ACE Certification Preparation Guide: Section 2 — Planning and implementing a cloud solution (~30% of the exam)
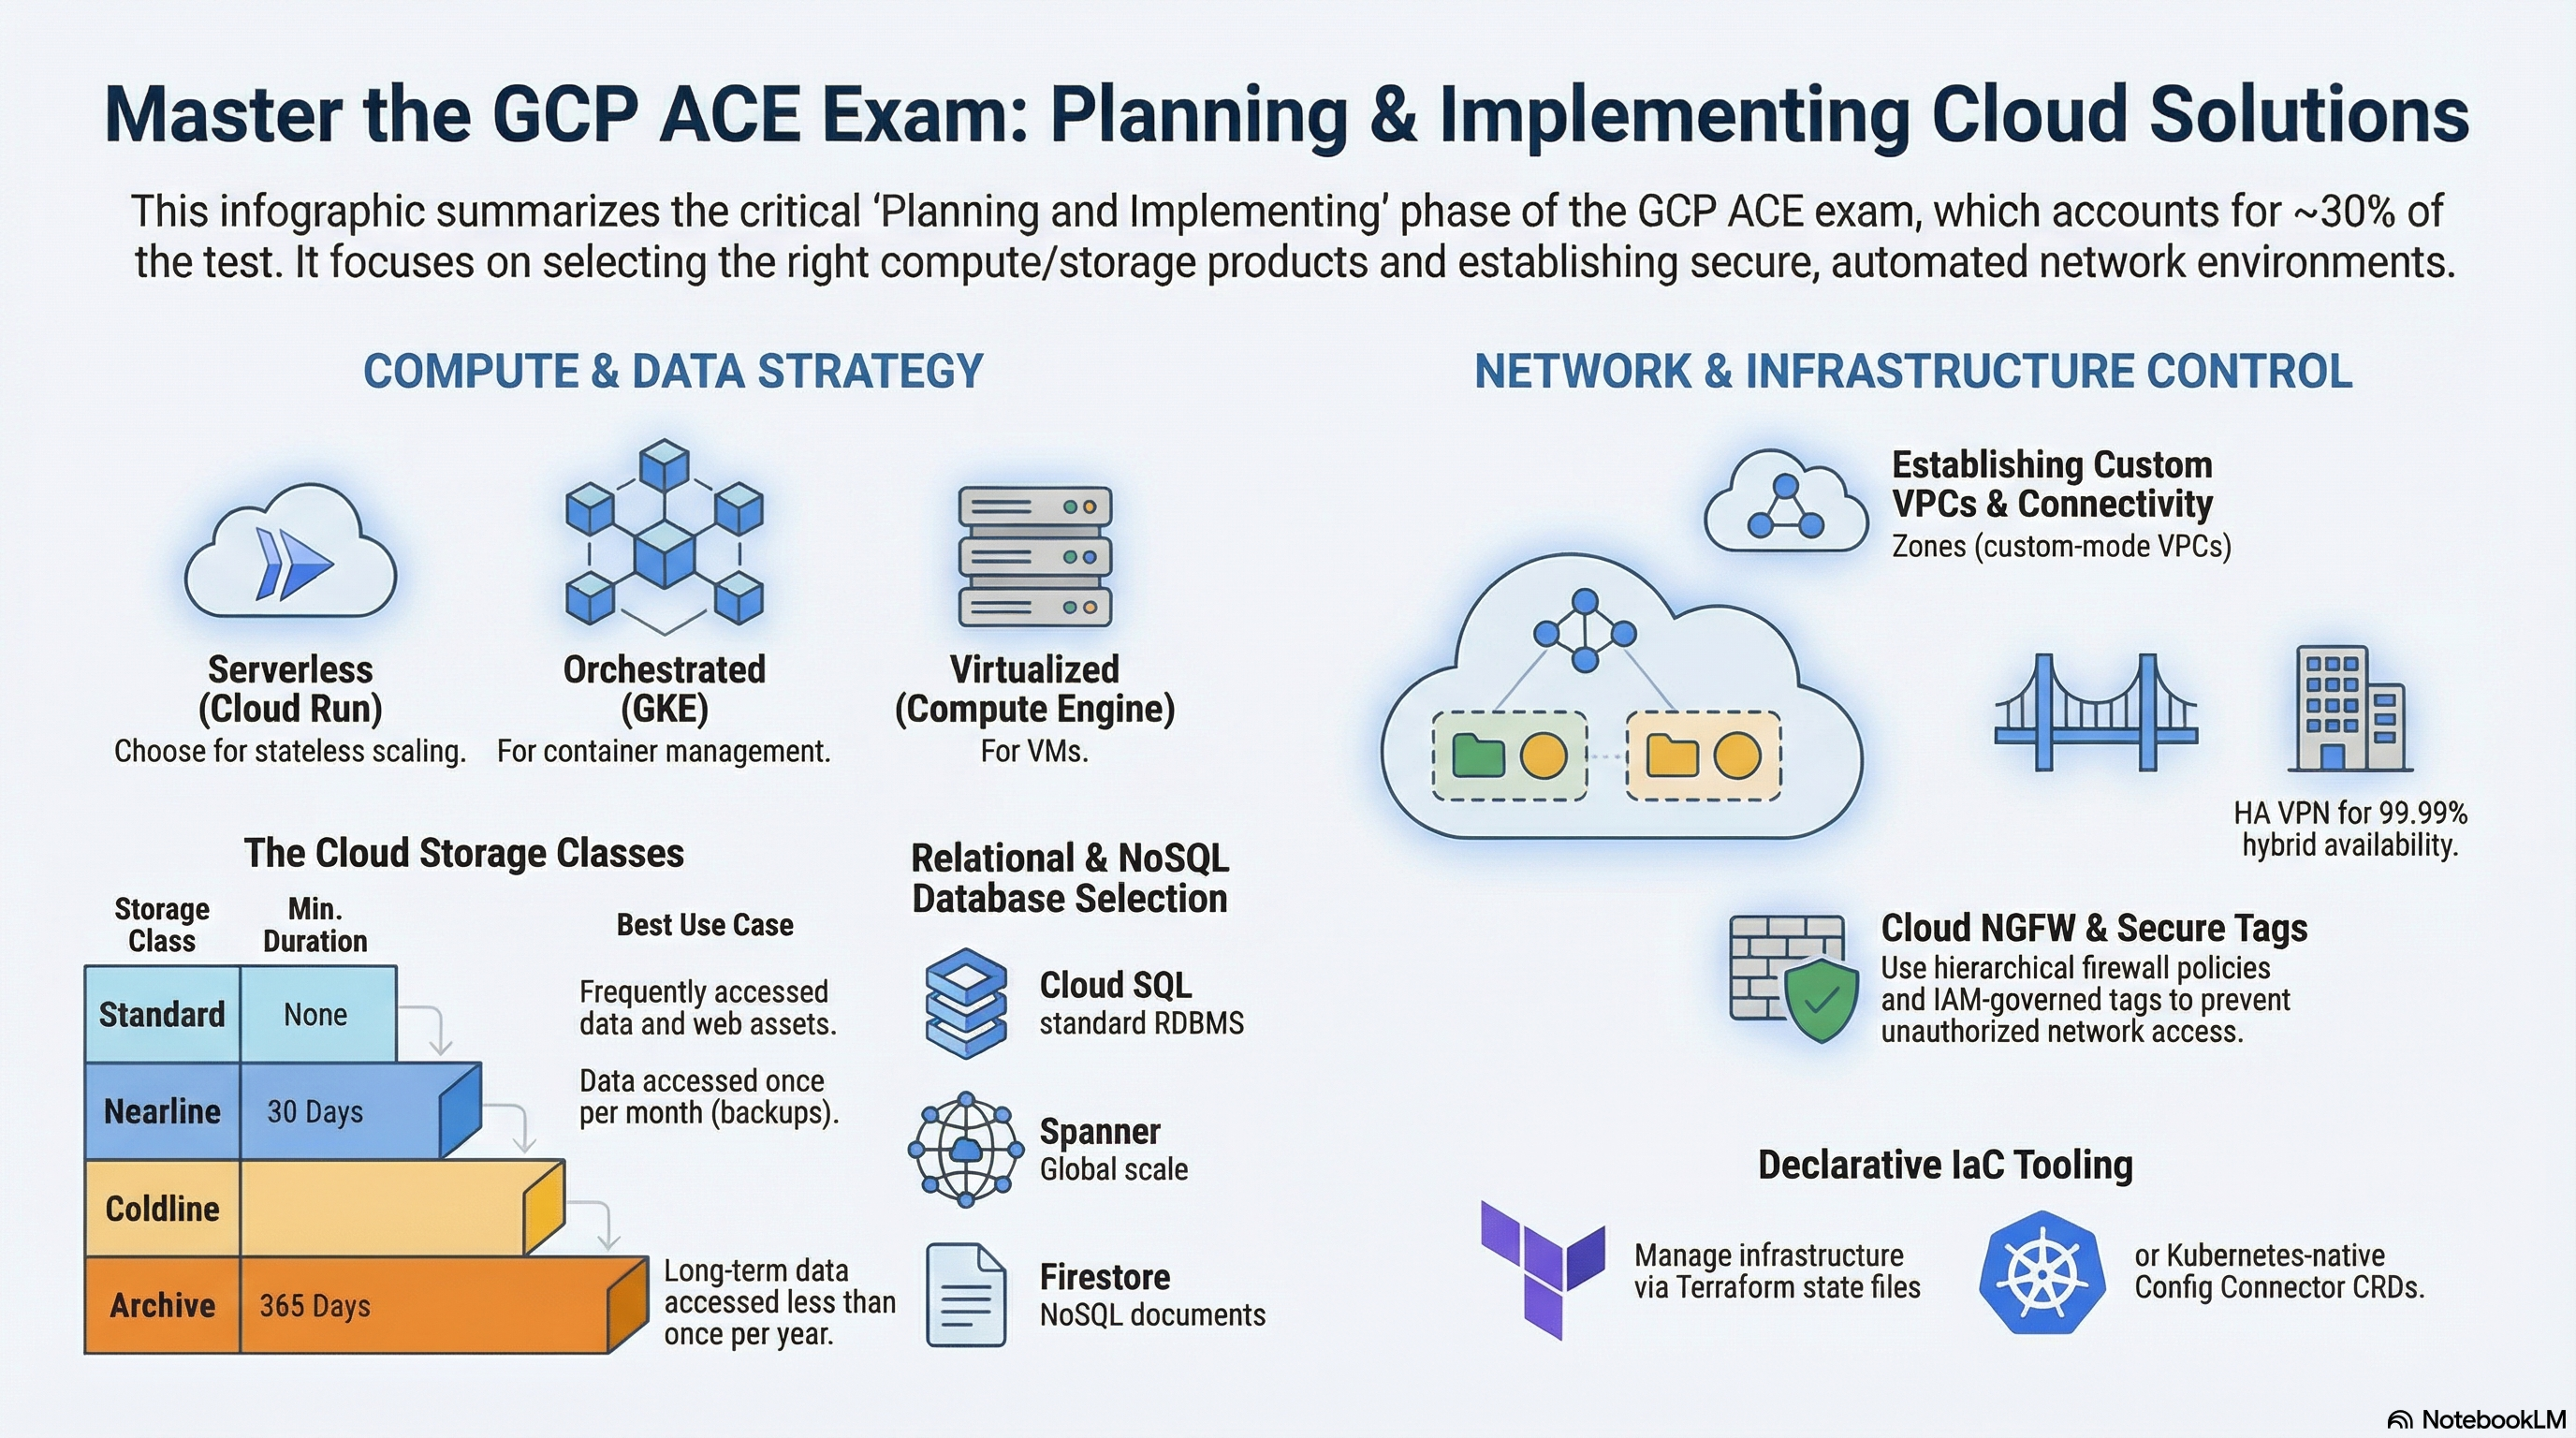 This guide covers exam Section 2 using the RAD platform foundation modules as a hands-on lab. All four foundation modules are exercised: `Services_GCP` provides the VPC, databases, and (optionally) the GKE Autopilot cluster; `App_CloudRun` and `App_GKE` are the two deployment engines; the `App_Common` shared library handles storage, secrets, and builds. Deploy the **Serverless application** profile first, then the **Kubernetes application** profile from the [Lab Map](ACE_Certification_Guide.md).
---
## 2.1 Planning and implementing compute resources
> ⏱ ~90 min · 💰 low for Cloud Run (scale-to-zero); moderate for GKE Autopilot · ⚙️ Requires: Serverless application profile; Kubernetes application profile for the GKE half
**Why the exam cares** — The biggest single skill in Section 2 is *choosing* the right compute platform — Compute Engine for full OS control, GKE for container orchestration, Cloud Run for stateless request-driven containers — and then configuring scaling and resources correctly on each. Expect scenarios contrasting scale-to-zero economics, cold starts, machine-type selection, and preemptible/Spot pricing.
**How RAD implements it** — The same application can be deployed through `App_CloudRun` or `App_GKE`, making the comparison concrete:
*Cloud Run* (`App_CloudRun`):
| Variable | Default | Notes |
|---|---|---|
| `container_image_source` | `"custom"` | `prebuilt` deploys `container_image` directly; `custom` builds with Cloud Build |
| `min_instance_count` | `0` | 0 = scale to zero; ≥1 eliminates cold starts |
| `max_instance_count` | `1` | Cost ceiling (1–1000) |
| `container_resources` | `cpu_limit = "1000m"`, `memory_limit = "512Mi"` | Per-instance capacity |
| `container_port` | `8080` | Port Cloud Run routes requests to |
| `execution_environment` | `"gen2"` | gen2 is required for NFS and GCS Fuse volumes |
| `timeout_seconds` | `300` | Request timeout, 0–3600 |
| `cpu_always_allocated` | `false` | Default is request-based billing (CPU only during request processing); set `true` to keep CPU allocated between requests |
`enable_image_mirroring` (default `true`) copies public images into Artifact Registry first (a digest-aware copy), so the service never pulls directly from Docker Hub.
*GKE* (`App_GKE`): `min_instance_count` (default `1`) and `max_instance_count` (default `3`) become an HPA's min/max replicas; `container_resources` becomes pod requests/limits (Autopilot bills by requests). `workload_type` (default `null`) resolves to a Deployment, but setting `stateful_pvc_enabled = true` auto-selects a StatefulSet with per-pod PVCs (`stateful_pvc_size`, `stateful_pvc_mount_path` required); explicitly combining `workload_type = "Deployment"` with `stateful_pvc_enabled = true` fails at plan time. `enable_vertical_pod_autoscaling` (default `false`) adds a VPA. The cluster itself comes from `Services_GCP`: `gke_cluster_mode` (default `AUTOPILOT`, or `STANDARD` with an explicit `e2-standard-4` node pool autoscaling 1–5 nodes via `gke_node_min_count`/`gke_node_max_count`), regional location, REGULAR release channel, Workload Identity, and Managed Prometheus.
*Compute Engine appears once:* `create_network_filesystem` (default `true`) runs an `e2-small` Ubuntu VM in a managed instance group of size 1, with a stateful data disk, TCP health checks with auto-healing, and a daily snapshot schedule (7-day retention) — a small but real MIG to inspect.
**Try it**
1. Deploy the Serverless application profile, then inspect the service and its revisions:
```bash
gcloud run services list --region=us-central1
gcloud run services describe --region=us-central1 \
--format="yaml(spec.template.spec.containers[0].resources, spec.template.metadata.annotations)"
```
In **Cloud Run > service > Revisions**, confirm CPU/memory match `container_resources`.
2. Change `max_instance_count` to `5` in the portal and redeploy; watch the new revision appear with `gcloud run revisions list --service= --region=us-central1`.
3. Deploy the Kubernetes application profile, connect, and inspect the workload:
```bash
gcloud container clusters get-credentials gke-cluster-1 --region=us-central1
kubectl get deployments,hpa,pods -n
kubectl describe hpa -n
```
4. Inspect the one Compute Engine VM and its MIG: `gcloud compute instance-groups managed list` and `gcloud compute instances list --filter="name~nfs"`.
5. You know it worked when the HPA shows `MINPODS 1 / MAXPODS 3` (or your overrides) and the Cloud Run revision shows your CPU/memory limits.
**Check yourself**
Q1: A stateless HTTP API has unpredictable, bursty traffic and the team wants to pay nothing during idle nights. Cloud Run or GKE — and which RAD variable expresses the decision?
A: Cloud Run with `min_instance_count = 0` — Cloud Run scales to zero between requests and bills only while serving. GKE Autopilot pods (HPA minimum of 1 in this module) keep billing for their resource requests around the clock. The trade-off is cold-start latency on the first request after idle.
Q2: You set stateful_pvc_enabled = true in App_GKE without touching workload_type. What gets deployed and why?
A: A StatefulSet. The module auto-selects StatefulSet whenever per-pod PVCs are requested, because Deployments cannot give each replica its own stable volume and identity. Forcing `workload_type = "Deployment"` alongside it fails validation at plan time.
Q3: On GKE Autopilot, what happens if a container spec has no CPU/memory requests, and why does the module always set them?
A: Autopilot requires resource requests — it either rejects the pod or applies defaults, and it bills per requested resource. The module always renders `container_resources` into requests/limits so scheduling and billing are deterministic.
**Beyond the modules** — General-purpose Compute Engine, App Engine, and Cloud Functions are not implemented. For the exam:
- Create a VM yourself: `gcloud compute instances create test-vm --zone=us-central1-a --machine-type=e2-micro`, then SSH with `gcloud compute ssh test-vm --zone=us-central1-a`. Study machine families (E2/N2/C3), Spot VMs, instance templates, and MIG autoscaling/rolling updates.
- App Engine: deploy a hello-world with `gcloud app deploy` in a scratch project; know Standard vs Flexible and that the region is permanent per project.
- Cloud Run functions (Cloud Functions): `gcloud functions deploy` with an HTTP or Pub/Sub trigger; know that 2nd gen runs on Cloud Run.
- GKE Standard node-pool operations (`gcloud container node-pools create/resize`) — the RAD cluster defaults to Autopilot where node pools are invisible.
**⚠️ Exam trap** — Cloud Run `max_instance_count` defaults to 1 in this module: a load test will plateau quickly and is not a Cloud Run limitation, just a deliberate cost ceiling. On the exam, "service stops scaling" scenarios are usually a max-instances setting, not quota.
---
## 2.2 Planning and implementing storage and data solutions
> ⏱ ~75 min · 💰 Cloud SQL is the dominant baseline cost; Filestore (`BASIC_HDD` 1 TiB) and Redis add meaningful cost — destroy after the lab · ⚙️ Requires: Baseline platform; toggle `create_redis` / `create_filestore_nfs` for those labs
**Why the exam cares** — Section 2.2 tests product selection: object storage (GCS) vs file storage (Filestore) vs block storage, relational (Cloud SQL/AlloyDB/Spanner) vs NoSQL (Firestore/Bigtable), and caching (Memorystore). It also tests basic creation parameters: storage classes, regional vs zonal availability, and private connectivity to managed databases.
**How RAD implements it** — `Services_GCP` provisions the data layer; the app modules consume and mount it.
| Variable (Services_GCP) | Default | What it creates |
|---|---|---|
| `create_postgres` | `true` | Cloud SQL PostgreSQL (`postgres_database_version` default `POSTGRES_17`, `postgres_tier` default `db-custom-1-3840`) |
| `postgres_database_availability_type` | `ZONAL` | Set `REGIONAL` for HA with a synchronous standby |
| `create_postgres_read_replica` | `false` | Zonal read replicas (`postgres_read_replica_count` default `1`) |
| `create_mysql` | `false` | Cloud SQL MySQL (`mysql_database_version` default `MYSQL_8_4`) |
| `enable_alloydb` | `false` | AlloyDB cluster + primary (`alloydb_cpu_count` default `2`) |
| `create_firestore` | `false` | Firestore database (Native mode) |
| `create_redis` | `false` | Memorystore Redis (`redis_tier` default `BASIC`, `redis_memory_size_gb` default `1`, AUTH enabled) |
| `create_filestore_nfs` | `false` | Filestore (`filestore_tier` default `BASIC_HDD`, `filestore_capacity_gb` default `1024`) |
The Cloud SQL instance is private-IP only (no public IPv4, encrypted-only SSL mode), reachable through Private Services Access, with automated daily backups (7 retained, 04:00 UTC) and point-in-time recovery enabled. Redis persistence (`redis_persistence_mode`, default `DISABLED`) is only configurable on `STANDARD_HA` tier, and plan-time preconditions reject `BASIC` tier when `resource_labels.environment = "production"` — and also reject `redis_persistence_mode = "DISABLED"` on a production `STANDARD_HA` instance, so production caches must enable `RDB` or `AOF` persistence.
On the application side, `storage_buckets` (default `[]`, with `create_cloud_storage` default `true`) provisions GCS buckets per entry — `storage_class` default `STANDARD`, `versioning_enabled` default `false`, `public_access_prevention` default `"enforced"`, optional `lifecycle_rules` and CORS (the platform's object-storage layer). `gcs_volumes` mounts buckets into the container via GCS Fuse, `enable_nfs` (default `true`) mounts the NFS share at `nfs_mount_path` (default `/mnt/nfs`), and `database_type` (default `POSTGRES`; `MYSQL`/`NONE`) selects which Cloud SQL engine the app binds to, connected through the Cloud SQL Auth Proxy (a unix-socket volume on Cloud Run via `enable_cloudsql_volume` default `true`; a proxy sidecar on GKE).
**Try it**
1. Inspect the database from the CLI and confirm it has no public IP:
```bash
gcloud sql instances list
gcloud sql instances describe \
--format="yaml(settings.availabilityType, settings.ipConfiguration, settings.backupConfiguration)"
```
Note `pointInTimeRecoveryEnabled: true` and the absence of a public address.
2. In the portal, add a bucket: `storage_buckets = [{ name_suffix = "media", versioning_enabled = true, storage_class = "NEARLINE" }]`, redeploy, then verify:
```bash
gcloud storage buckets list --format="table(name, storageClass, versioning_enabled)"
gcloud storage cp /etc/hostname gs:///test.txt && gcloud storage ls -L gs:///test.txt
```
3. Set `create_redis = true` and `create_filestore_nfs = true` in Services_GCP, redeploy, then: `gcloud redis instances list --region=us-central1` and `gcloud filestore instances list`. Check the Redis AUTH and private IP in the output.
4. You know it worked when the bucket shows `NEARLINE` class with versioning on, and the SQL instance shows `availabilityType: ZONAL` with backups enabled.
**Check yourself**
Q1: The application needs a shared read-write filesystem mounted by 10 Cloud Run instances simultaneously. GCS, Filestore, or a persistent disk?
A: Filestore (or the module's NFS server) — it is a managed NFS file share supporting concurrent multi-writer POSIX access, which RAD mounts via `enable_nfs`/`nfs_mount_path`. Persistent disks are single-writer block devices for VMs; GCS is object storage (the GCS Fuse mount is eventually-consistent object semantics, not a POSIX filesystem).
Q2: Production launch review: the Cloud SQL instance must survive a zone outage. Which single variable changes, and what does it actually do?
A: `postgres_database_availability_type = "REGIONAL"`. Cloud SQL then maintains a synchronous standby in a second zone of the same region with automatic failover. It roughly doubles instance cost and is not the same as a read replica (asynchronous, zonal in this module, no automatic failover).
Q3: Why does the module reject redis_tier = "BASIC" when resource_labels.environment = "production"?
A: BASIC tier is a single node with no replication and no SLA — a maintenance event or node failure flushes the cache and causes downtime. STANDARD_HA adds a replica with automatic failover, and only STANDARD_HA supports RDB/AOF persistence in this module.
**Beyond the modules** — Not implemented: BigQuery, Spanner, Bigtable, Datastore mode, Pub/Sub as an application messaging bus, Memcached, and Storage Transfer Service. For the exam: load a CSV into BigQuery (`bq load` + `bq query --dry_run` for cost estimation), create and delete a small Spanner instance, publish/pull a Pub/Sub message (`gcloud pubsub topics create t && gcloud pubsub subscriptions create s --topic=t`), and review GCS storage classes (Standard/Nearline/Coldline/Archive with 0/30/90/365-day minimums).
**⚠️ Exam trap** — "Backups enabled" ≠ unlimited recovery: PITR (enabled here with 7-day transaction log retention) lets you restore to a moment in time within the window; daily backups alone only restore to backup snapshots. MySQL in this module has binary logging but no PITR configuration block — don't assume parity between engines.
---
## 2.3 Planning and implementing networking resources
> ⏱ ~75 min · 💰 the Cloud Armor + global LB lab adds a forwarding-rule and policy cost · ⚙️ Requires: Baseline platform; `enable_cloud_armor = true` with a domain for the LB lab
**Why the exam cares** — You must be able to create a custom-mode VPC with subnets, write firewall rules with priorities and target tags, give private instances outbound internet via Cloud NAT, and choose the right load balancer (global external Application LB for HTTP(S), passthrough Network LB for TCP/UDP). Private access to managed services (Private Services Access vs Private Google Access vs Private Service Connect) is a recurring scenario.
**How RAD implements it** — `Services_GCP` builds a custom-mode VPC `vpc-network-{prefix}` (subnets are not auto-created) with one subnet per region in `availability_regions` (default `["us-central1"]`, CIDRs from `subnet_cidr_range`, default `["10.0.0.0/24"]`), a Cloud Router + Cloud NAT per region (`{network}-nat-gw-{region}`), and a Private Services Access peering range (`/16`) used by Cloud SQL, Redis, and Filestore for private IPs. Firewall rules are tag- and range-based: `{network}-fw-allow-lb-hc` admits Google health-check ranges `130.211.0.0/22` and `35.191.0.0/16`; `{network}-fw-allow-iap-ssh` admits IAP TCP forwarding range `35.235.240.0/20` on tcp:22; NFS/Redis rules target tags `nfsserver`/`redisserver`; HTTP rules target `httpserver`/`webserver` tags on 80/443/8080/8443. GKE secondary ranges (pods/services) are carved out of `gke_pod_base_cidr` (default `10.64.0.0/10`) and `gke_service_base_cidr` (default `10.8.0.0/16`) only when the cluster is enabled.
On the edge: in `App_CloudRun`, `vpc_egress_setting` (default `PRIVATE_RANGES_ONLY`, or `ALL_TRAFFIC`) controls Direct VPC egress (the service gets a network interface in the subnet — no Serverless VPC Access connector is used), and `ingress_settings` (default `all`) controls who can reach the service. `enable_cloud_armor` (default `false`) provisions a global external Application Load Balancer — serverless NEG → backend service with a Cloud Armor policy (preconfigured OWASP sqli/xss/lfi/rce rules, 500 req/min/IP rate limit, Adaptive Protection) → URL map → HTTPS proxy → global static IP — with `application_domains` optional (a zero-config `.nip.io` certificate is derived when it is empty); Google-managed certificates are issued per domain when you do supply one, and `enable_cdn` (default `false`) turns on Cloud CDN at the backend service. In `App_GKE`, `enable_custom_domain` uses the Gateway API (`gke-l7-global-external-managed` GatewayClass) with Certificate Manager, `reserve_static_ip` (default `true`) holds a global address, and `enable_cloud_armor` activates the same Gateway, falling back to a derived `.nip.io` HTTPS certificate when no custom domain is set.
**Try it**
1. Walk the network from the CLI:
```bash
gcloud compute networks list --filter="name~vpc-network"
gcloud compute networks subnets list --network=
gcloud compute routers list
gcloud compute routers nats list --router= --region=us-central1
gcloud compute firewall-rules list --filter="network~" \
--format="table(name, sourceRanges.list(), allowed[].map().firewall_rule().list(), targetTags.list())"
```
2. See Private Services Access: **VPC network > VPC network peering** shows `servicenetworking-googleapis-com`; `gcloud compute addresses list --global --filter="purpose=VPC_PEERING"` shows the reserved /16.
3. Enable `enable_cloud_armor = true` with `application_domains = ["app.example.com"]` (a domain you control), redeploy, then inspect the LB and the WAF policy:
```bash
gcloud compute forwarding-rules list --global
gcloud compute security-policies list
gcloud compute security-policies describe --format="table(rules[].priority, rules[].action, rules[].description)"
```
4. Flip `vpc_egress_setting` to `ALL_TRAFFIC` and observe in **Cloud Run > service > Networking** that all egress now routes through the VPC (and therefore out via Cloud NAT).
5. You know it worked when the firewall list shows the health-check and IAP ranges above, and the security policy shows deny(403) WAF rules plus a rate-based ban rule.
**Check yourself**
Q1: The Cloud SQL instance has no public IP, yet Cloud Run connects to it. Name the two mechanisms involved.
A: Private Services Access gives the Cloud SQL instance a private IP in a peered Google-managed range, and Cloud Run reaches that RFC 1918 address through Direct VPC egress (`vpc_egress_setting = "PRIVATE_RANGES_ONLY"` routes private-range traffic into the VPC), with the Cloud SQL Auth Proxy handling authentication/encryption.
Q2: A VM in the subnet must download OS packages but must never be reachable from the internet. What provides this, and what would you check if downloads fail?
A: Cloud NAT — it gives instances without external IPs outbound internet access with no inbound exposure. If downloads fail, check that the NAT gateway covers the subnet/region (`gcloud compute routers nats describe`) and that no egress-deny firewall rule outranks the default allow.
Q3: Why does enabling Cloud Armor in App_CloudRun also flip ingress away from "all"?
A: Cloud Armor evaluates traffic at the load balancer. If the Cloud Run service still accepted direct `run.app` traffic (`ingress = all`), attackers could bypass the WAF entirely; restricting ingress to `internal-and-cloud-load-balancing` forces every request through the protected path.
**Beyond the modules** — Not implemented: Shared VPC (host/service projects), VPC peering between your own VPCs, Cloud DNS zones and records, Cloud VPN / Interconnect, custom static routes, VPC flow logs, and internal load balancers. For the exam: create a private Cloud DNS zone (`gcloud dns managed-zones create`), peer two scratch VPCs and verify non-transitivity, review HA VPN (99.99% SLA, requires Cloud Router/BGP), and practice `gcloud compute networks subnets expand-ip-range` (ranges can grow, never shrink).
**⚠️ Exam trap** — Firewall rule priority: lower number wins, default rules sit at 65534, and an "allow" does not override a higher-priority "deny". Also remember health-check ranges (`130.211.0.0/22`, `35.191.0.0/16`) must be allowed or your load balancer marks all backends unhealthy — the module creates this rule for you, which is why it "just works".
---
## 2.4 Planning and implementing resources through infrastructure as code
> ⏱ ~45 min · 💰 no additional cost · ⚙️ Requires: any deployed profile
**Why the exam cares** — ACE expects you to understand what IaC buys you (declarative desired state, plan-before-apply diffs, repeatability, drift correction), the basic Terraform workflow (`init → validate → plan → apply`), remote state, and Google-native tooling (Cloud Foundation Toolkit, Config Connector). You don't need to write modules from scratch.
**How RAD implements it** — The entire RAD platform *is* IaC: your deployment portal collects variable values and runs OpenTofu inside Cloud Build (a create pipeline for the first deploy and an update pipeline for changes: `tofu init → plan → apply`). Every portal toggle in this guide is a Terraform variable; `deploy_application` (default `true`) is a good example of declarative control — set it to `false` and the next apply removes the workload while keeping the supporting infrastructure (VPC, database, buckets) intact. The modules also demonstrate plan-time *policy*: 23 preconditions in `App_CloudRun` and 32 in `App_GKE` reject invalid combinations (e.g. CDN without a custom domain) before any API call is made.
**Try it**
1. See the IaC workflow run end-to-end: trigger any deploy from the portal, then `gcloud builds list --limit=5` and open the latest build's log to watch the `init → plan → apply` steps execute in order.
2. In that plan output, find where your portal field (e.g. `min_instance_count`) lands on the Cloud Run service — connect a portal toggle to the concrete API attribute it sets.
3. Observe drift correction: in the console, manually change your Cloud Run service's memory limit (**Edit & deploy new revision**), then trigger an update from the portal with unchanged variables and watch the plan revert your manual edit.
4. Re-read the build log's plan/apply steps to see exactly which create/update/no-op actions the apply performed.
5. You know it worked when the plan output for step 3 shows your console edit being reverted (an in-place update back to `512Mi` or your configured value).
**Check yourself**
Q1: A teammate "fixed" production by editing a firewall rule in the console. The next scheduled IaC apply un-fixed it. What happened and what is the correct workflow?
A: Terraform reconciles real resources to the declared configuration, so out-of-band console edits are reverted as drift. The correct workflow is to change the variable/configuration in source (or the portal) and apply through the pipeline — console edits to IaC-managed resources should be reserved for break-glass emergencies and immediately backported.
Q2: Why does `tofu plan` matter on the exam (and in this platform) before `apply`?
A: `plan` computes the exact create/update/destroy diff against state without touching anything, letting you catch destructive changes (e.g. a database replacement) before they happen. The RAD pipeline always runs `plan -out=plan.tfplan` and applies that saved plan, guaranteeing what was reviewed is what executes.
**Beyond the modules** — The portal abstracts state management, so practice separately: configure a GCS backend with versioning for remote state (`terraform { backend "gcs" { bucket = "..." } }`), know why remote state + locking matters for teams, and skim Config Connector (GCP resources as Kubernetes CRDs) and the Cloud Foundation Toolkit/Terraform blueprints. Also drill the raw CLI equivalents the exam loves: `gcloud compute instances create`, `gcloud container clusters create-auto`, `gcloud run deploy` — IaC questions are often really "do you know what this automates".
**⚠️ Exam trap** — `terraform destroy` (and the portal's purge) deletes *everything in state*, not just "unused" resources. Conversely, resources created outside IaC are invisible to it — deleting the Terraform deployment won't clean up your console experiments.
---
# ACE Certification Preparation Guide: Section 3 — Ensuring successful operation of a cloud solution (~27% of the exam)
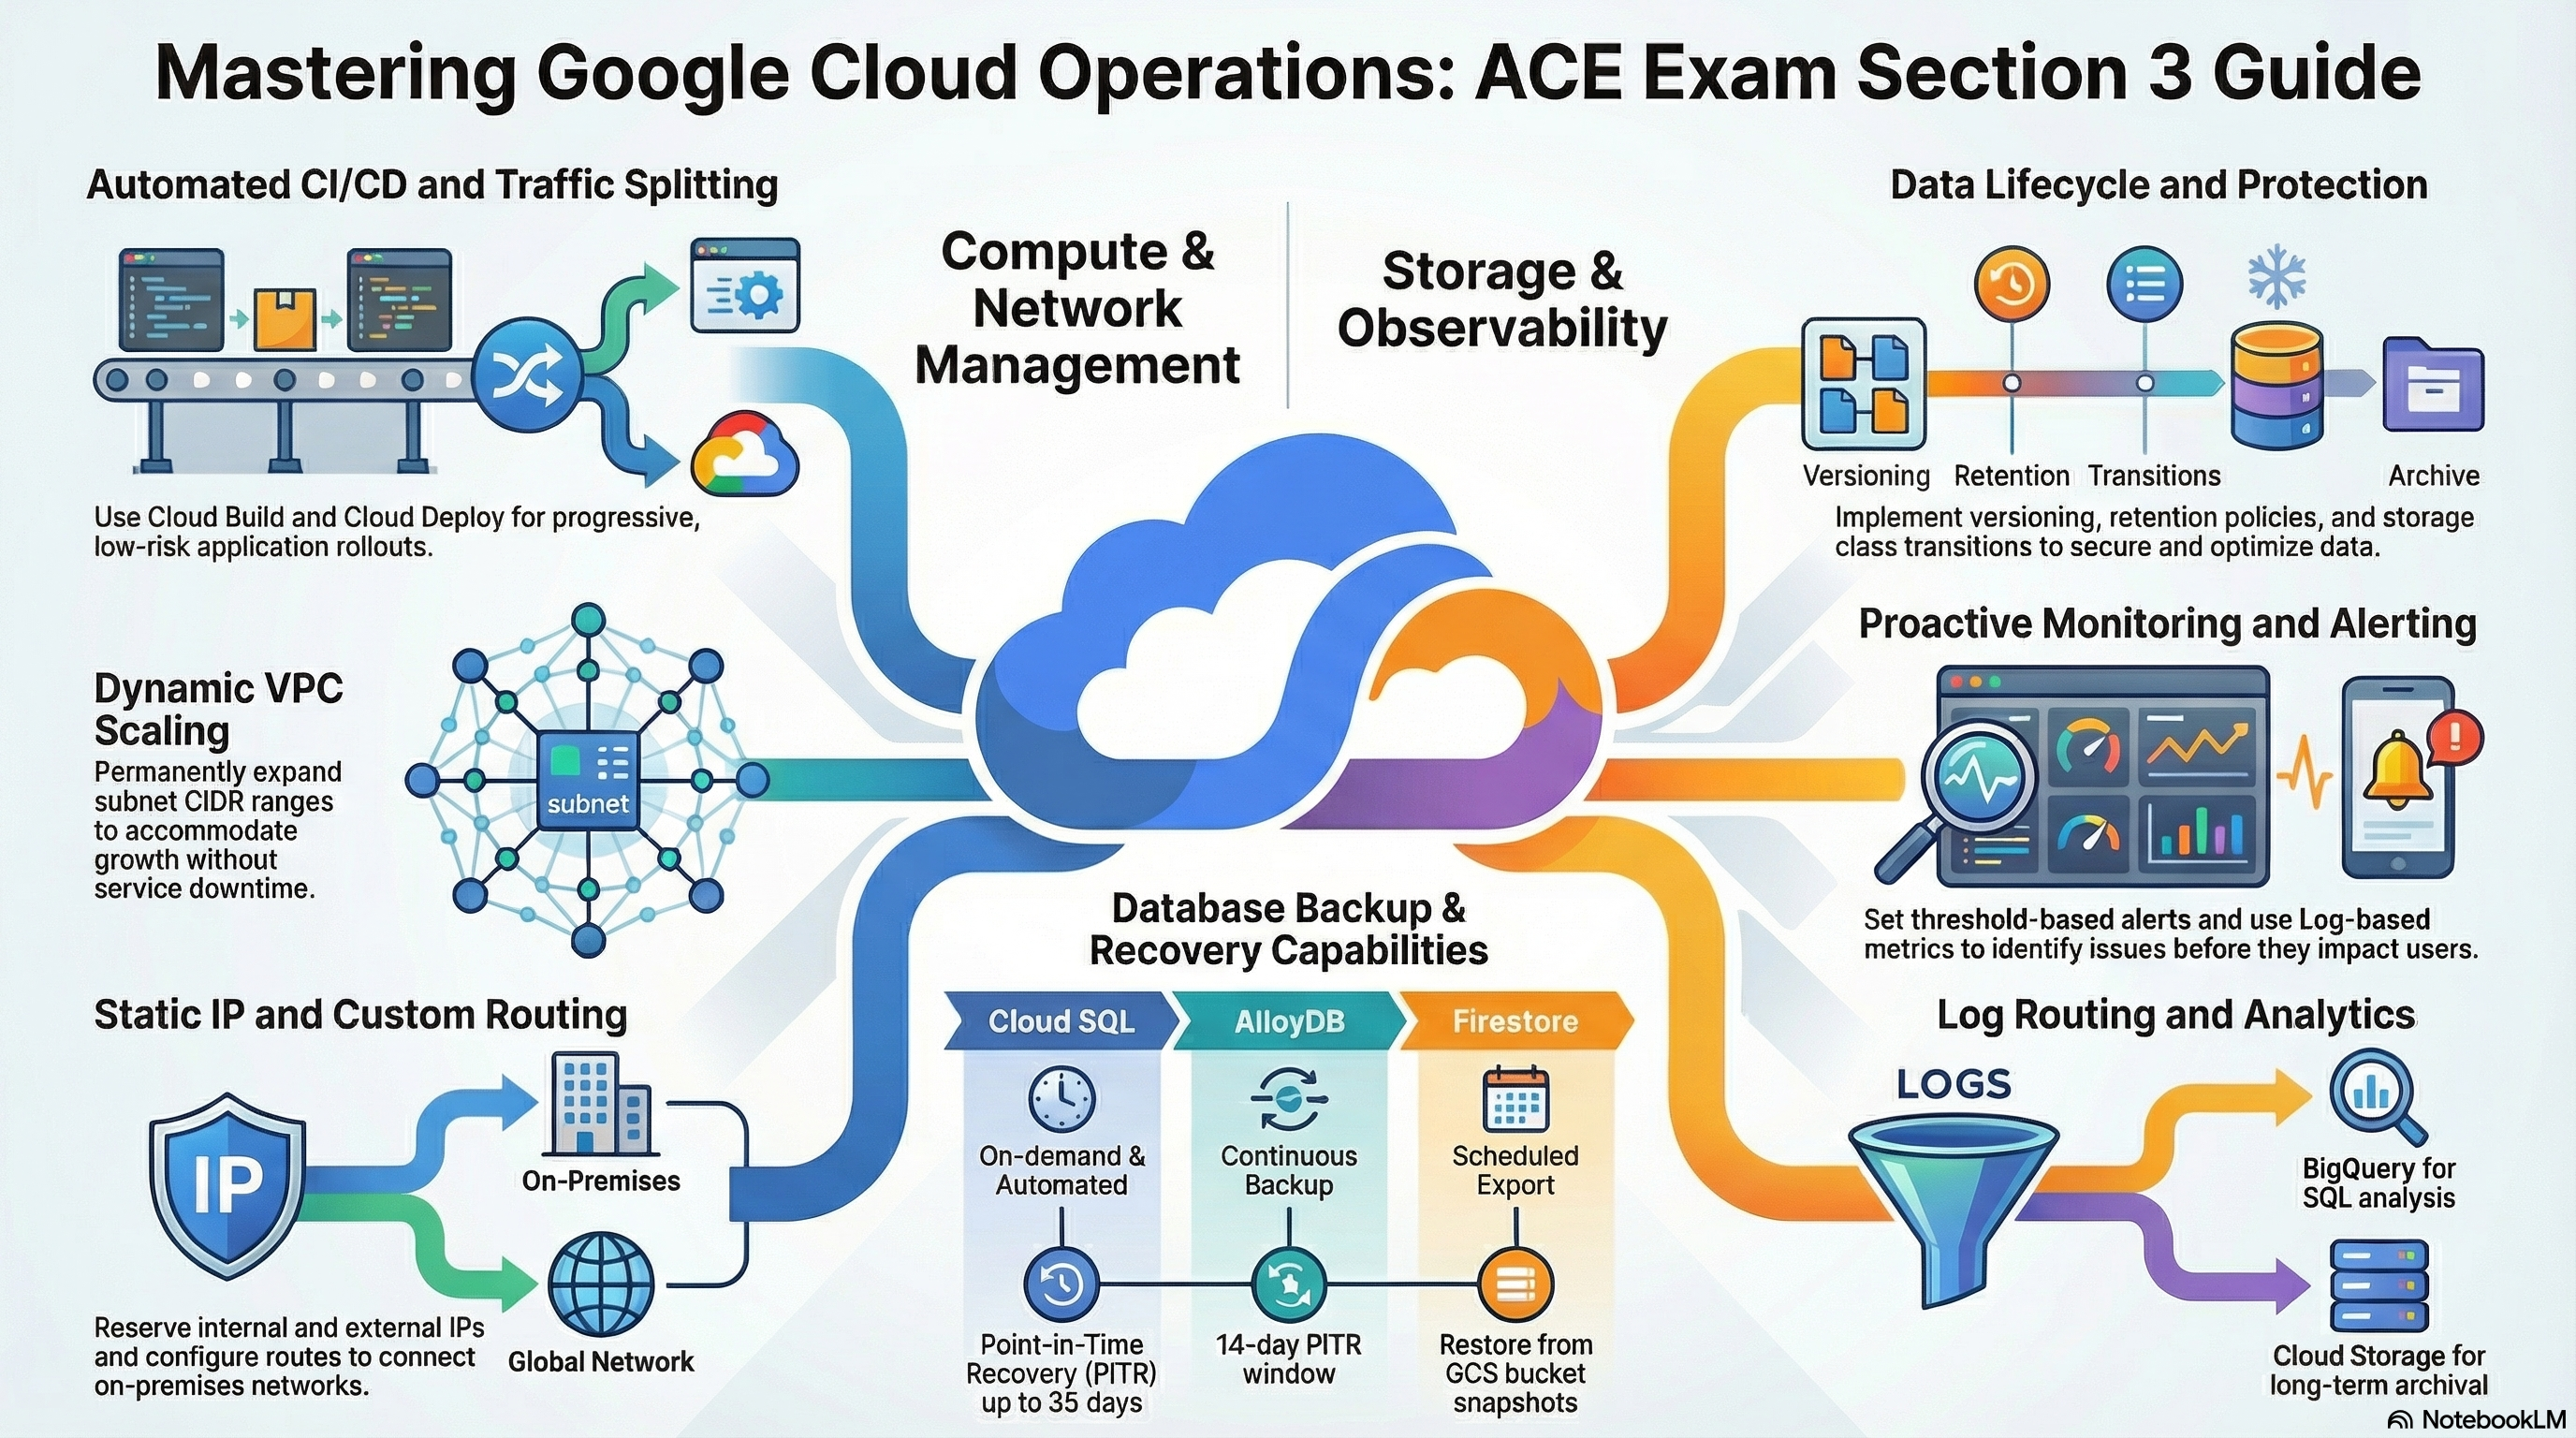 > 📚 **Official exam guide:** [Associate Cloud Engineer certification](https://cloud.google.com/learn/certification/cloud-engineer) — always confirm section weightings against the current Google Cloud exam guide.
This guide covers exam Section 3 — day-2 operations — using the RAD platform foundation modules. `App_CloudRun` and `App_GKE` carry most of the load (revisions, traffic, CI/CD, backups, alerts); `Services_GCP` supplies the infrastructure alerts and audit logging. Deploy the **Serverless application** profile (plus the **Kubernetes application** profile for the `kubectl` labs and the **Operations & security add-ons** profile for 3.4) from the [Lab Map](ACE_Certification_Guide.md).
---
## 3.1 Managing compute resources
> ⏱ ~90 min · 💰 low; Cloud Deploy stages each run their own service — destroy after the lab · ⚙️ Requires: Serverless application profile; `enable_cicd_trigger` + a GitHub repo for the CI/CD lab
**Why the exam cares** — Operating compute means deploying new versions safely (canary/blue-green via traffic splitting), scaling manually and automatically, and working a Kubernetes cluster from the CLI (`kubectl get/describe/logs/scale`). Expect questions on shifting Cloud Run traffic between revisions and on diagnosing pods.
**How RAD implements it** —
*Revisions and traffic (Cloud Run):* every portal update creates a new revision; `max_revisions_to_retain` (default `7`) prunes older non-serving revisions. `traffic_split` (default `[]` = 100% to latest) takes a list of `{ type, revision, percent, tag }` entries that must sum to exactly 100 (validated at plan time), e.g. 90% `TRAFFIC_TARGET_ALLOCATION_TYPE_LATEST` / 10% to a named revision — a declarative canary.
*CI/CD:* `enable_cicd_trigger` (default `false`) with `github_repository_url` and `github_token` creates a Cloud Build trigger (`cicd_trigger_config.branch_pattern` default `"^main$"`) that builds with Kaniko, pushes to Artifact Registry, and either updates the service directly or — when `enable_cloud_deploy = true` — creates a Cloud Deploy release through `cloud_deploy_stages` (default `dev` → `staging` → `prod`, with `require_approval = true` on prod). Note that `enable_cloud_deploy = true` without `enable_cicd_trigger = true` is rejected at plan time — Cloud Deploy releases only come from the CI/CD pipeline.
*Kubernetes operations (App_GKE):* the HPA spans `min_instance_count` (default `1`) to `max_instance_count` (default `3`); `enable_pod_disruption_budget` (default `true`) creates a PDB with `pdb_min_available` (default `"1"`, skipped when `max_instance_count = 1`); `enable_resource_quota` (default `false`) caps the namespace at `quota_cpu_requests`/`quota_cpu_limits` (default `"4"`), `quota_memory_requests` (default `"4Gi"`) / `quota_memory_limits` (default `"8Gi"`) — memory values *must* carry a binary suffix (`Gi`/`Mi`), enforced by a plan-time validation, because Kubernetes treats a bare `"4"` as 4 bytes and would block all scheduling. `cron_jobs` deploys Kubernetes CronJobs.
*Compute Engine operations:* the `Services_GCP` NFS VM runs in a MIG with auto-healing health checks and a daily snapshot schedule with 7-day retention — a live example of snapshot-based VM protection.
**Try it**
1. Deploy a visible change (e.g. set an env var in `environment_variables`), then split traffic in the portal: `traffic_split = [{ type = "TRAFFIC_TARGET_ALLOCATION_TYPE_LATEST", percent = 90 }, { type = "TRAFFIC_TARGET_ALLOCATION_TYPE_REVISION", revision = "-0000X", percent = 10, tag = "previous" }]`. Verify, then practice the imperative equivalent the exam tests:
```bash
gcloud run revisions list --service= --region=us-central1
gcloud run services update-traffic --region=us-central1 \
--to-revisions=-0000X=10,LATEST=90
gcloud run services describe --region=us-central1 --format="yaml(status.traffic)"
```
2. On GKE, exercise the core `kubectl` loop:
```bash
gcloud container clusters get-credentials gke-cluster-1 --region=us-central1
kubectl get pods -n -o wide
kubectl describe pod -n
kubectl logs -n --tail=50
kubectl scale deployment -n --replicas=3 # HPA will reconcile this
kubectl get pdb,resourcequota -n
```
3. With CI/CD enabled, push a commit to `main` and watch: `gcloud builds list --limit=3`, then **Cloud Deploy > Delivery pipelines** to promote dev → staging and approve prod (`gcloud deploy rollouts approve ...` is the CLI form).
4. You know it worked when `status.traffic` shows your 90/10 split and the tagged revision serves on its own tag URL.
**Check yourself**
Q1: Five minutes after a release, error rates spike on the new Cloud Run revision. Fastest rollback?
A: `gcloud run services update-traffic --to-revisions==100`. Revisions are immutable, so the previous one is still deployed and warm — shifting traffic is instant and requires no rebuild or redeploy. This is exactly what `traffic_split` declares in Terraform form.
Q2: You run kubectl scale deployment app --replicas=10 but pods drop back to 3. Why?
A: A HorizontalPodAutoscaler owns the replica count (the module creates one spanning `min_instance_count`–`max_instance_count`, default max 3). The HPA reconciles manual scaling back into its bounds; to scale higher you raise `max_instance_count` (or edit/remove the HPA), not the Deployment.
Q3: During cluster maintenance, why does at least one pod of the app always stay up?
A: `enable_pod_disruption_budget` (default true) creates a PDB with `minAvailable: 1`, so voluntary disruptions (node drains, upgrades) cannot evict the last available pod. Note it does not protect against involuntary failures like node crashes.
**Beyond the modules** — VM SSH workflows are not part of the app modules: practice `gcloud compute ssh --tunnel-through-iap` (the module's `fw-allow-iap-ssh` rule for `35.235.240.0/20` already permits this to the NFS VM), `gcloud compute instances list --filter="status=RUNNING"`, on-demand snapshots (`gcloud compute disks snapshot`), creating images from disks, and MIG rolling updates (`gcloud compute instance-groups managed rolling-action start-update`). Also study GKE Standard node-pool resize/upgrade commands, which Autopilot hides.
**⚠️ Exam trap** — `gcloud run deploy` always sends 100% of traffic to the new revision *unless* the service was previously set to manual traffic control (`--no-traffic` / explicit splits). If a question says "deploy without serving traffic", the answer involves `--no-traffic` and tags, mirroring the `traffic_split` `tag` field here.
---
## 3.2 Managing storage and database solutions
> ⏱ ~60 min · 💰 negligible (backup bucket storage) · ⚙️ Requires: Serverless application profile with a database (`database_type` ≠ `NONE`)
**Why the exam cares** — Day-2 data work: running and restoring backups, understanding PITR vs snapshot restore, lifecycle-managing objects, and connecting to databases to run queries. Scenario questions usually test whether you know *which* recovery mechanism fits an RPO, and how to keep storage costs down automatically.
**How RAD implements it** — `App_CloudRun`/`App_GKE` provision an automated logical-backup pipeline: a Cloud Scheduler job triggers a Cloud Run job that runs the backup export on `backup_schedule` (default `"0 2 * * *"` UTC), dumping the application database to a dedicated GCS backup bucket whose lifecycle rule deletes objects older than `backup_retention_days` (default `7`). Restores are first-class: `enable_backup_import` (default `false`) with `backup_source` (`gcs` or `gdrive`), `backup_file`, and `backup_format` runs a one-time import job. `enable_custom_sql_scripts` (default `false`) executes `.sql` files from `custom_sql_scripts_bucket`/`custom_sql_scripts_path` in lexicographic order (a non-empty path is enforced at plan time), optionally as the root DB user.
Independently of these logical dumps, the Cloud SQL instance itself keeps 7 automated daily backups (04:00 UTC) with PITR enabled and 7-day transaction-log retention. Bucket hygiene is demonstrated by the platform's object-storage layer: per-bucket `versioning_enabled`, `lifecycle_rules` (age, newer-version count, storage-class transitions), soft-delete policy, and `public_access_prevention` (default `enforced`).
**Try it**
1. Trigger a backup right now instead of waiting for the schedule:
```bash
gcloud scheduler jobs list --location=us-central1
gcloud scheduler jobs run --location=us-central1
gcloud run jobs executions list --region=us-central1 --limit=3
gcloud storage ls -l gs:///
```
2. Inspect the managed-backup side: `gcloud sql backups list --instance=` and `gcloud sql instances describe --format="yaml(settings.backupConfiguration)"` — note `transactionLogRetentionDays: 7`.
3. Add a lifecycle transition to a bucket in the portal (`lifecycle_rules` with an age-based `SetStorageClass` to `NEARLINE`), redeploy, and verify: `gcloud storage buckets describe gs:// --format="yaml(lifecycle_config)"`.
4. Run a custom SQL script: upload `001_create_table.sql` to a bucket, set `enable_custom_sql_scripts = true` with the bucket/path, redeploy, and read the job logs with `gcloud run jobs executions describe --region=us-central1`.
5. You know it worked when a fresh timestamped dump appears in the backup bucket and `gcloud sql backups list` shows the 7 retained automatic backups.
**Check yourself**
Q1: An engineer dropped a table at 14:32. The last nightly dump is from 02:00. What's the lowest-data-loss recovery, and why is it available here?
A: Point-in-time recovery — restore (clone) the Cloud SQL instance to 14:31. PITR is enabled on the instance with 7-day transaction log retention, so any second in that window is recoverable; the 02:00 GCS dump would lose 12.5 hours of writes. The exam expects you to know PITR creates a new instance rather than rewinding the existing one.
Q2: How do you keep backup-bucket costs flat without any manual cleanup?
A: An object lifecycle rule that deletes objects older than N days — exactly what `backup_retention_days` configures on the backup bucket. Lifecycle management is evaluated daily by GCS itself; no jobs or cron needed on your side.
**Beyond the modules** — `gcloud sql connect` is worth practicing but won't work against these instances directly because they have no public IP — connect via the Cloud SQL Auth Proxy (`cloud-sql-proxy `) or Cloud SQL Studio in the console. Also study: on-demand backups (`gcloud sql backups create --instance=...`), cross-product backup surfaces (Firestore export/import to GCS, GKE Backup — note `Services_GCP` has `enable_gke_backup`, default `false`, schedule `0 3 * * *`, 30-day retention), BigQuery job history (`bq ls -j`), and the Pricing Calculator for storage cost estimation.
**⚠️ Exam trap** — Object *versioning* and lifecycle *deletion* interact: deleting a versioned object creates a noncurrent version that still bills until a `num_newer_versions`/age rule purges it. "We enabled versioning and storage costs doubled" is a classic scenario.
---
## 3.3 Managing networking resources
> ⏱ ~40 min · 💰 a reserved-but-unattached static IP bills hourly — release after the lab · ⚙️ Requires: Kubernetes application profile (for `reserve_static_ip`) or any Cloud Armor deployment
**Why the exam cares** — Operations on live networks: reserving static internal/external IPs, adding subnets or expanding ranges as workloads grow, and keeping firewall rules current. The exam favors `gcloud compute addresses` and subnet-expansion commands.
**How RAD implements it** — Two operational patterns are live:
- *Static IPs:* `App_GKE`'s `reserve_static_ip` (default `true`) reserves a **global** static external IP for the Gateway/load balancer (`static_ip_name` optional override); `App_CloudRun` likewise creates a global static IP when its load balancer is enabled, and the `Services_GCP` NFS VM holds a reserved *internal* address so the share's IP survives instance replacement.
- *Subnets per region:* adding a region to `availability_regions` in `Services_GCP` creates a new subnet, router, and NAT gateway in that region on the next apply without touching existing subnets.
**Try it**
1. List reserved addresses and identify which are global vs regional, internal vs external:
```bash
gcloud compute addresses list
gcloud compute addresses describe --global
```
2. In the portal, set `reserve_static_ip = false` on App_GKE and redeploy; observe the Gateway now uses an ephemeral IP that can change on recreation — then set it back to `true` (production hygiene).
3. Practice the manual exam commands in your project:
```bash
gcloud compute addresses create lab-ip --region=us-central1
gcloud compute addresses delete lab-ip --region=us-central1 --quiet
```
4. You know it worked when `gcloud compute addresses list` shows the module's global address with status `IN_USE` (attached to a forwarding rule).
**Check yourself**
Q1: After a maintenance redeploy, customers report DNS no longer resolves to the application. The Gateway IP changed. What was misconfigured?
A: The load balancer was using an ephemeral IP (`reserve_static_ip = false`). Ephemeral external IPs can change whenever the fronting resource is recreated; production endpoints referenced by DNS must use a reserved static address — exactly why the module defaults to `true`.
Q2: A global external Application Load Balancer needs an IP. Regional or global reservation?
A: Global (`gcloud compute addresses create NAME --global`). Global LBs use a single anycast IP; regional addresses attach to regional resources (VMs, regional LB forwarding rules). Picking the wrong scope is a common wrong-answer option.
**Beyond the modules** — Not implemented: custom static routes, VPC peering management, Cloud DNS record operations, and subnet IP-range expansion (the module creates subnets but you should practice growing one): `gcloud compute networks subnets expand-ip-range --region=us-central1 --prefix-length=23` (expansion only — ranges can never shrink). Also review **VPC network > Routes** to understand system-generated routes vs custom routes with next hops.
**⚠️ Exam trap** — A reserved external static IP that is *not attached* to anything still incurs charges; releasing unused addresses is a standard cost-cleanup answer (and an Active Assist recommendation).
---
## 3.4 Monitoring and logging
> ⏱ ~75 min · 💰 audit logging increases Cloud Logging volume/cost · ⚙️ Requires: `support_users` set; `configure_email_notification = true` + `notification_alert_emails` on Services_GCP; `enable_audit_logging = true` for the audit lab
**Why the exam cares** — You must read and filter logs in Logs Explorer, create alert policies on metrics, understand notification channels, know which audit logs exist by default (Admin Activity: always on; Data Access: opt-in), and diagnose workloads from their telemetry.
**How RAD implements it** —
*Metrics and alerts:* setting `support_users` creates email notification channels plus built-in alert policies — for Cloud Run, CPU utilization > 90% and memory utilization > 90% (P99 over 60s windows, via the platform's monitoring layer); `alert_policies` (default `[]`) adds custom threshold policies on any metric type, auto-filtered to your service. `Services_GCP` adds infrastructure alerts when `configure_email_notification = true` with `notification_alert_emails`: Cloud SQL CPU/memory/disk against `alert_cpu_threshold`/`alert_memory_threshold`/`alert_disk_threshold` (all default `80`), and NFS VM CPU/memory/instance-down policies — the NFS memory alert reads the Ops Agent metric `agent.googleapis.com/memory/percent_used`. A Cloud Monitoring dashboard is created per application.
*Probes:* `startup_probe_config` and `health_check_config` define HTTP/TCP startup and liveness probes on both platforms — Kubernetes-style health checking you can see in the revision/pod spec.
*Logging:* GKE clusters ship `SYSTEM_COMPONENTS` and `WORKLOADS` logs and enable Managed Prometheus. `enable_audit_logging` (default `false`) turns on `allServices` ADMIN_READ/DATA_READ/DATA_WRITE Data Access audit logs plus explicit Secret Manager and KMS configs.
*Uptime checks:* `uptime_check_config` (default `{ enabled = false, path = "/" }` — you must set `enabled = true`; `check_interval` default `"60s"`, `timeout` default `"10s"`) creates a `-uptime-check` — an HTTP GET probe from multiple global regions — plus a `-uptime-check-alert` policy on `monitoring.googleapis.com/uptime_check/check_passed` that notifies the `support_users` channels (via the platform's monitoring layer). The check is only created when the endpoint is publicly reachable (e.g. a custom domain, the nip.io LB host, or the run.app URL with `ingress_settings = "all"`); internal-only deployments get none. The `uptime_check_names` output returns the created check's name.
**Try it**
1. List what monitoring the modules created:
```bash
gcloud beta monitoring channels list --format="table(displayName, labels.email_address)"
gcloud alpha monitoring policies list --format="table(displayName, enabled)"
```
(Console: **Monitoring > Alerting** and **Monitoring > Dashboards**. If your service is publicly reachable, also open **Monitoring > Uptime checks** and find `-uptime-check` probing from multiple regions.)
2. Read your application's logs with exam-style filters:
```bash
gcloud logging read 'resource.type="cloud_run_revision" AND severity>=ERROR' --limit=10
gcloud logging read 'resource.type="k8s_container" AND resource.labels.namespace_name=""' --limit=10
```
3. Enable `enable_audit_logging = true`, redeploy, perform an action (read a secret value in the console), then find it:
```bash
gcloud logging read 'logName:"cloudaudit.googleapis.com%2Fdata_access" AND protoPayload.serviceName="secretmanager.googleapis.com"' --limit=5
```
4. Break a probe on purpose: set `health_check_config.path` to `/broken`, redeploy, and watch the revision fail to become ready (Cloud Run) or the pod restart-loop (`kubectl describe pod` shows failing liveness probes). Revert.
5. You know it worked when the policies list shows the CPU/memory alerts and step 3 returns a Data Access entry naming your principal.
**Check yourself**
Q1: Security asks "who read the database password last Tuesday?" — can you answer with default settings?
A: No. Secret *reads* are Data Access (DATA_READ) audit events, which are disabled by default; only Admin Activity (e.g. changing IAM, creating secrets) is always on. With `enable_audit_logging = true` the module enables Data Access logs for Secret Manager (and all services), making the question answerable from Logs Explorer.
Q2: An alert policy exists and its condition fires, but nobody is emailed. First thing to check?
A: Notification channels — a policy with no (or unverified) channels evaluates conditions but notifies no one. In RAD terms: `support_users`/`notification_alert_emails` must be non-empty, which is what creates and attaches the email channels.
Q3: A GKE pod is in CrashLoopBackOff. Give the two-command diagnosis sequence.
A: `kubectl describe pod -n ` (events: image pull errors, OOMKilled, failing probes) then `kubectl logs -n --previous` (output of the crashed container, not the current restart). The `--previous` flag is the detail the exam likes.
**Beyond the modules** — Not implemented: log sinks/Log Router exports (to BigQuery, GCS, Pub/Sub), log-based metrics, log bucket retention configuration, Cloud Trace/Profiler, and Ops Agent *installation* (the module assumes it on the NFS VM for the memory metric). Practice: create a log-based counter metric from a Logs Explorer query and create a sink with `gcloud logging sinks create`. Know the `_Required` sink (Admin Activity, 400-day retention, cannot be disabled) vs `_Default` (30-day retention).
**⚠️ Exam trap** — Admin Activity audit logs are free and always on; Data Access audit logs are opt-in, billable, and high-volume (BigQuery is the one service with Data Access enabled by default). Mixing these up is the most common Section 3.4 error.
---
# ACE Certification Preparation Guide: Section 4 — Configuring access and security (~20% of the exam)
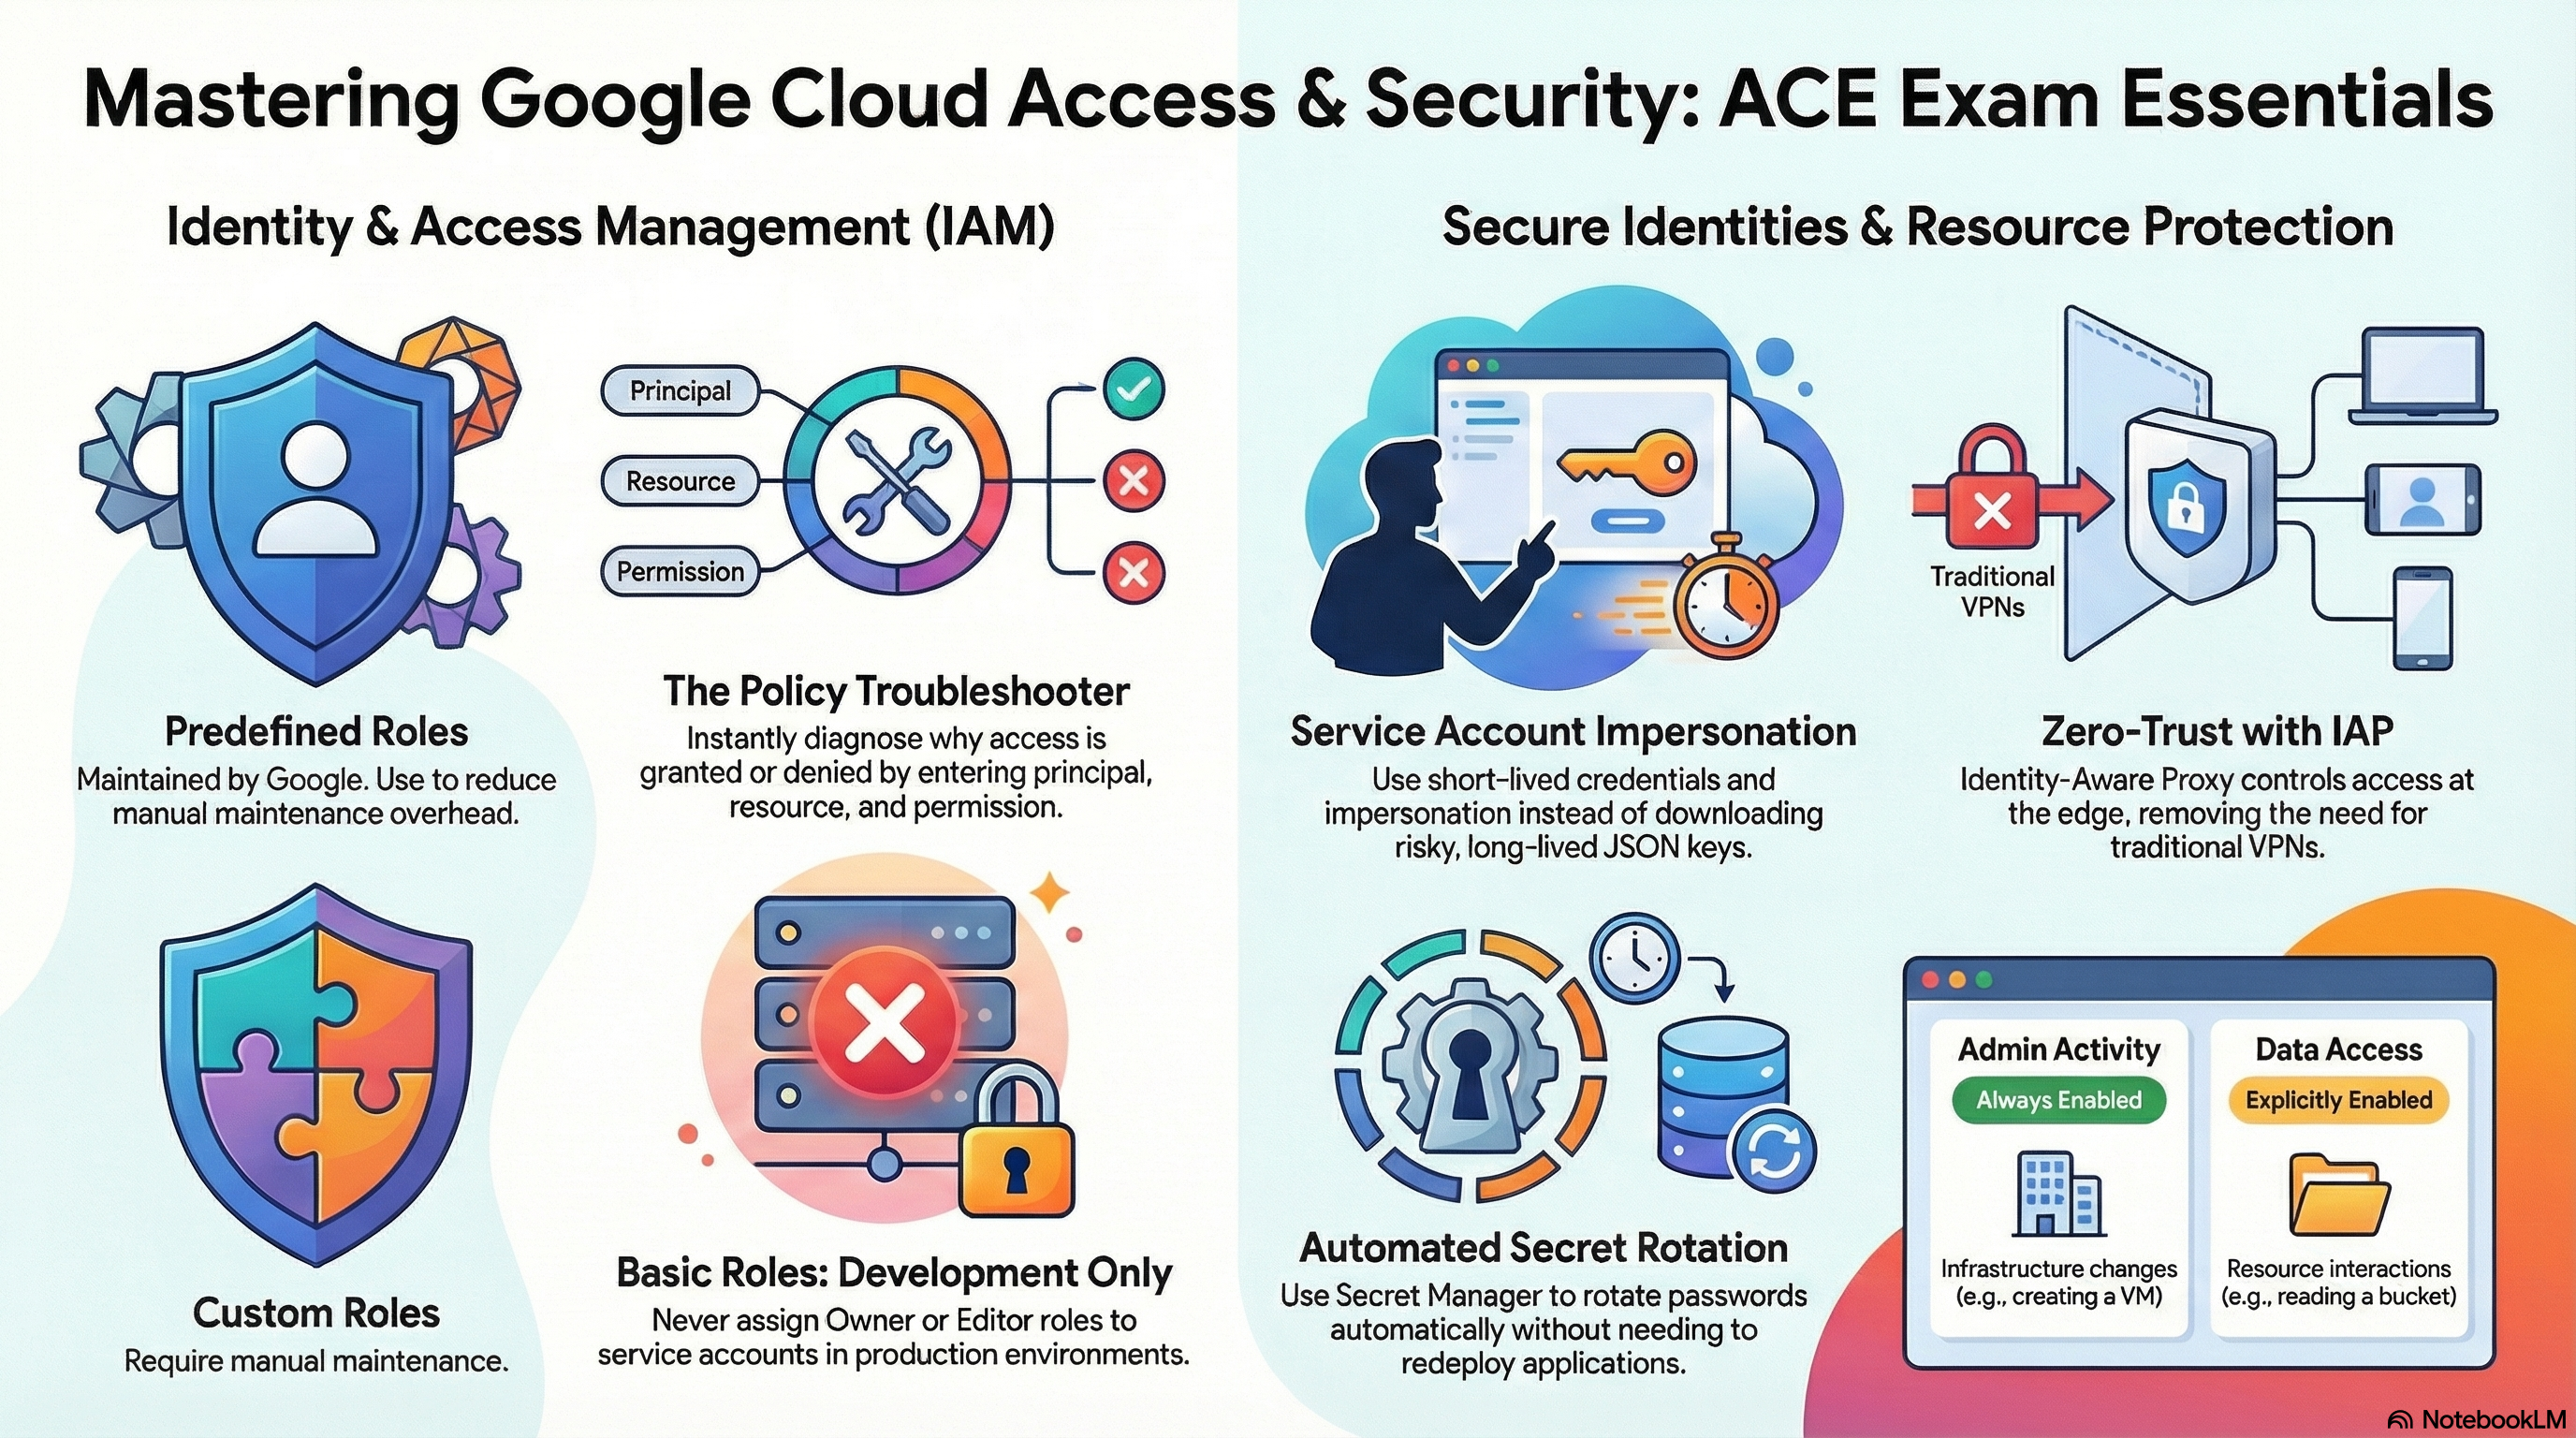 > 📚 **Official exam guide:** [Associate Cloud Engineer certification](https://cloud.google.com/learn/certification/cloud-engineer) — always confirm section weightings against the current Google Cloud exam guide.
This guide covers exam Section 4 using the RAD platform foundation modules. Security is where the modules shine as a lab: every deployment creates dedicated least-privilege service accounts (`Services_GCP` plus the platform's IAM layer), `App_GKE` uses Workload Identity, `Services_GCP` can stand up Workload Identity Federation, and secrets live exclusively in Secret Manager. Deploy the **Serverless application** profile plus the **Operations & security add-ons** profile (IAP, audit logging) from the [Lab Map](ACE_Certification_Guide.md).
---
## 4.1 Managing Identity and Access Management (IAM)
> ⏱ ~60 min · 💰 no additional cost (audit logging adds log volume) · ⚙️ Requires: any deployed profile; `enable_audit_logging = true` for the audit-log lab
**Why the exam cares** — IAM questions test the policy model (principal + role + resource, inherited down the hierarchy), the three role types (basic, predefined, custom) and when each is appropriate, and reading/troubleshooting effective access. The recurring decision criterion: prefer predefined roles on groups; never hand out `roles/owner`/`roles/editor` in production; basic roles are pre-IAM legacy.
**How RAD implements it** — The modules are a worked example of least privilege:
- `Services_GCP` creates `cloudbuild-sa-{prefix}`, `clouddeploy-sa-{prefix}`, `cloudrun-sa-{prefix}`, `nfs-sa-{prefix}`, and `gke-sa-{prefix}`, each granted only the predefined roles its job needs — no basic roles anywhere.
- The platform's IAM layer narrows further: the runtime service account gets `roles/secretmanager.secretAccessor` *per secret* and `roles/storage.objectAdmin` *per bucket* (resource-level bindings, not project-level), and Cloud Build gets `roles/iam.serviceAccountUser` only on the identity it must deploy as.
- `enable_audit_logging` (default `false`, available on `Services_GCP` and both app modules) enables Data Access audit logs (`ADMIN_READ`/`DATA_READ`/`DATA_WRITE`) for `allServices` plus explicit Secret Manager and KMS configs — the mechanism for answering "who did what".
- `support_users` (default `[]`) is the human-principal entry point: emails become monitoring notification targets; bind your operators as groups where possible.
**Try it**
1. Dump and read the project IAM policy the way the exam expects:
```bash
gcloud projects get-iam-policy $GOOGLE_CLOUD_PROJECT \
--flatten="bindings[].members" \
--filter="bindings.members:serviceAccount" \
--format="table(bindings.members, bindings.role)" | sort
```
Confirm the module SAs hold only narrow predefined roles.
2. See a *resource-level* binding (a concept many candidates miss):
```bash
gcloud secrets get-iam-policy
gcloud storage buckets get-iam-policy gs://
```
The runtime SA appears here, not in the project policy — least privilege in action.
3. Explore role definitions: `gcloud iam roles describe roles/secretmanager.secretAccessor` — note it contains essentially one permission (`secretmanager.versions.access`). Compare with `gcloud iam roles describe roles/editor` to see why basic roles are discouraged.
4. With audit logging enabled, change any IAM binding in the console, then find it:
```bash
gcloud logging read 'protoPayload.methodName="SetIamPolicy"' --limit=5 \
--format="table(timestamp, protoPayload.authenticationInfo.principalEmail)"
```
5. You know it worked when steps 2–4 show per-resource bindings, single-permission predefined roles, and your own email on the `SetIamPolicy` entry.
**Check yourself**
Q1: A developer needs to view Cloud Run services and read their logs — nothing else. Which roles, and why not roles/viewer?
A: `roles/run.viewer` plus `roles/logging.viewer` — predefined roles scoped to exactly the needed services. `roles/viewer` (a basic role) grants read access across nearly *every* service in the project, violating least privilege and exposing data (e.g. listing secrets, reading buckets' metadata) the developer has no business seeing.
Q2: A service account has roles/secretmanager.secretAccessor on secret app-db-password only, but the exam scenario says it "can't list secrets in the console". Is something wrong?
A: No — `secretAccessor` permits *reading versions* of that one secret, not listing secrets (that needs `secretmanager.secrets.list`, in roles like `roles/secretmanager.viewer` at project level). Resource-level grants don't confer project-level browse access; this asymmetry is intended and frequently tested.
Q3: Access granted at the folder level — can a project-level admin in a child project remove it?
A: No. IAM policies are inherited downward and the *effective* policy is the union of all levels; a child resource cannot revoke or restrict a grant made on its ancestor. You'd need to change the folder-level binding (or use IAM deny policies / conditions, managed above the project).
**Beyond the modules** — Not implemented: custom role creation, IAM Conditions, Policy Troubleshooter, and org-level policy administration. For the exam: create a throwaway custom role (`gcloud iam roles create labRole --project=$GOOGLE_CLOUD_PROJECT --permissions=run.services.list`), run **IAM & Admin > Policy Troubleshooter** against a principal/resource/permission triple, and review IAM role recommendations in **IAM** (Active Assist flags over-granted bindings based on 90-day usage).
**⚠️ Exam trap** — Removing a user from IAM does not invalidate already-issued access tokens (up to ~1 hour) and does not touch resource-level bindings you may have forgotten — checking *both* project and resource policies is the complete answer.
---
## 4.2 Managing service accounts
> ⏱ ~75 min · 💰 no additional cost · ⚙️ Requires: Serverless or Kubernetes application profile; `enable_iap = true` with authorized users for the IAP lab
**Why the exam cares** — Service accounts are the workload identity story: creating dedicated SAs instead of using defaults, attaching them to compute, avoiding exported JSON keys (Workload Identity / Workload Identity Federation / impersonation instead), and protecting application credentials. The exam's consistent theme: *keys are a last resort*.
**How RAD implements it** —
*Dedicated runtime identities:* the Cloud Run service runs as its tenant-scoped `cloudrun-sa-*`, never the default Compute Engine service account. On GKE, `App_GKE` implements Workload Identity end-to-end: a Kubernetes ServiceAccount annotated `iam.gke.io/gcp-service-account`, and a `roles/iam.workloadIdentityUser` binding to `serviceAccount:{project}.svc.id.goog[namespace/ksa]` — pods get short-lived Google credentials with no key file anywhere.
*Keyless CI/CD:* `Services_GCP`'s `enable_workload_identity_federation` (default `false`) creates pool `wif-pool` with a provider per `wif_provider_type` (default `"github"`; also `gitlab` or `generic` OIDC) and binds the pool's principals (`roles/iam.workloadIdentityUser`) to the Cloud Build, Cloud Deploy, and Cloud Run SAs — external CI authenticates by exchanging its OIDC token, no exported keys.
*Impersonation:* the platform itself runs as `resource_creator_identity`, and `impersonation_service_account` (default `""`) makes the modules' shell scripts call GCP APIs as a target SA — the same `--impersonate-service-account` pattern the exam tests for humans.
*Secrets:* `secret_environment_variables` maps env var names to Secret Manager secrets resolved at runtime (a secret-reference env source on Cloud Run; the Secret Manager CSI driver on GKE). The DB password is generated randomly (`database_password_length` default `32`), stored only in Secret Manager, and `enable_auto_password_rotation` (default `false`) deploys an Eventarc-triggered rotation job doing a dual-version, zero-downtime rotation (`rotation_propagation_delay_sec` default `90`). The plain `secret_rotation_period` (default `"2592000s"`) only publishes rotation *notifications* — it does not rotate anything by itself.
*Identity-gated access:* `enable_iap` (default `false`) turns on IAP. On Cloud Run, the v2 service enables IAP (BETA launch stage) and the module grants `roles/run.invoker` to the IAP service agent and `roles/iap.httpsResourceAccessor` to `iap_authorized_users`/`iap_authorized_groups`. On GKE, IAP additionally requires `iap_oauth_client_id`, `iap_oauth_client_secret`, `iap_support_email`, and at least one authorized principal — all enforced by plan-time validations.
**Try it**
1. Confirm the workload runs as a dedicated SA, not the default:
```bash
gcloud run services describe --region=us-central1 \
--format="value(spec.template.spec.serviceAccountName)"
```
2. On GKE, verify Workload Identity from inside a pod:
```bash
kubectl get serviceaccount -n -o yaml | grep gcp-service-account
kubectl run wi-test -n --rm -it --image=google/cloud-sdk:slim \
--overrides='{"spec":{"serviceAccountName":""}}' \
-- gcloud auth list
```
The active account is the Google SA — no key was mounted.
3. Practice impersonation (grant yourself `roles/iam.serviceAccountTokenCreator` on the SA first):
```bash
gcloud storage ls --impersonate-service-account=cloudrun-sa-@$GOOGLE_CLOUD_PROJECT.iam.gserviceaccount.com
```
4. Inspect secret handling: `gcloud secrets versions list ` and, after enabling `enable_auto_password_rotation`, watch a new version appear while the previous is disabled (dual-version rotation).
5. Enable IAP with `iap_authorized_users = ["user:you@example.com"]`, redeploy, then open the service URL in an incognito window — you are pushed through Google sign-in, and a non-listed account gets a 403. You know it worked when your account passes and others don't.
**Check yourself**
Q1: A GKE pod must read a GCS bucket. A teammate suggests mounting a service account JSON key as a Kubernetes Secret. What is the exam-correct alternative and why?
A: Workload Identity — bind the pod's KSA to a Google SA with `roles/storage.objectViewer` (the `roles/iam.workloadIdentityUser` pattern used by `App_GKE`). JSON keys never expire, can be exfiltrated by anyone who can read the namespace's secrets, and require manual rotation; Workload Identity issues short-lived tokens automatically with full audit attribution.
Q2: GitHub Actions needs to deploy to Cloud Run. Options: download a key for the Cloud Build SA, or use Workload Identity Federation. Compare.
A: WIF (the module's `wif-pool` + GitHub OIDC provider) lets the workflow exchange its GitHub-issued OIDC token for short-lived GCP credentials — nothing stored in repo secrets, automatically scoped and auditable. A downloaded key is a long-lived bearer credential sitting in GitHub secrets; if leaked it works until manually destroyed. The exam answer is WIF (or impersonation) over keys, essentially always.
Q3: With IAP enabled on Cloud Run, a user authenticates successfully with their Google account but still gets a 403. What two grants must both exist?
A: The *user* needs `roles/iap.httpsResourceAccessor` (via `iap_authorized_users`/`iap_authorized_groups`), and the *IAP service agent* needs `roles/run.invoker` on the service so it can forward authenticated requests. Authentication (who you are) passing while authorization (what you may access) fails is exactly this split — the module creates both bindings for you.
**Beyond the modules** — Not implemented: service account key creation/rotation workflows (deliberately — the modules avoid keys entirely), short-lived token minting (`gcloud auth print-access-token --impersonate-service-account=...`, `gcloud auth print-identity-token`), disabling/undeleting service accounts, and cross-project SA usage. Practice in a scratch project: `gcloud iam service-accounts create`, `gcloud iam service-accounts keys create` (then delete it and explain why), and `gcloud iam service-accounts add-iam-policy-binding --member=user:you@... --role=roles/iam.serviceAccountTokenCreator` to wire impersonation. Also review the default Compute Engine SA (`PROJECT_NUMBER-compute@developer.gserviceaccount.com`) and why attaching it with Editor-scope access is the canonical anti-pattern.
**⚠️ Exam trap** — `roles/iam.serviceAccountUser` (attach/run *as* the SA) and `roles/iam.serviceAccountTokenCreator` (mint tokens to *impersonate* it) are different roles; questions often hinge on which one a deployer or impersonator actually needs. The modules grant `serviceAccountUser` to Cloud Build precisely so it can deploy services that run as the runtime SA.
---
# Professional Cloud Architect (PCA) Certification Lab Map
The Professional Cloud Architect certification validates your ability to design, plan, and manage secure, scalable, highly available cloud solutions — and to justify the trade-offs behind every design choice. The RAD platform's four foundation modules give you a live laboratory for exactly those trade-offs: `Services_GCP` (the shared platform layer — VPC, Cloud SQL, Redis, Filestore, GKE, CMEK, VPC-SC), `App_CloudRun` and `App_GKE` (two deployment engines for the *same* containerized workload, embodying the serverless-vs-orchestrated decision the PCA exam returns to again and again), and `App_Common` (shared layers implementing discovery, secrets, IAM, storage, and CI/CD patterns). Every toggle in your deployment portal is a design decision you can deploy, inspect in the GCP console, and reverse.
## How to use this guide
- Deploy one of the profiles below through your deployment portal, then work through the matching section guide(s).
- Each section guide pairs "why the exam cares" decision criteria with the exact variables that implement the concept, hands-on steps, and self-check questions.
- Use the coverage legend honestly: 📘 topics (hybrid connectivity, migration planning, Vertex AI, org hierarchy) must be studied outside the platform — the "Beyond the modules" blocks tell you what and where.
- **Case studies (📘):** the PCA exam includes scenario questions built on official case studies such as EHR Healthcare, Helicopter Racing League, Mountkirk Games, and TerramEarth. The modules are an excellent rehearsal ground: read a case study's requirements, then write down which portal variables would satisfy each one (e.g. EHR Healthcare's encryption and audit demands map to `enable_cmek`, `enable_audit_logging`, and `enable_vpc_sc`; Mountkirk Games' global, autoscaled, container-based platform maps to GKE Autopilot with a global Gateway and Cloud Armor). Where a requirement has *no* matching variable — hybrid Interconnect for TerramEarth, multi-region Spanner for Mountkirk — you have found a study gap.
**Coverage legend**
| Symbol | Meaning |
|---|---|
| ✅ | Fully demonstrated — deploy it, see it, modify it in the RAD platform |
| 🟡 | Partially demonstrated — the modules touch the concept; supplement with docs |
| 📘 | Concept-only — not implemented by the modules; study pointers provided |
## Deployment profiles
### Profile: Lean baseline
*Purpose:* the lowest-cost architecture — zonal database, scale-to-zero serverless, self-managed NFS VM — your reference point for every cost/availability trade-off.
*Modules:* Services_GCP, then App_CloudRun.
| Variable | Value |
|---|---|
| `create_postgres` | `true` (default) |
| `postgres_database_availability_type` | `ZONAL` (default) |
| `create_network_filesystem` | `true` (default — e2-small NFS/Redis VM) |
| `min_instance_count` | `0` (default, App_CloudRun) |
| `max_instance_count` | `1` (default, App_CloudRun) |
*Estimated incremental cost:* low — the zonal `db-custom-1-3840` Cloud SQL instance and the e2-small NFS VM dominate; Cloud Run scales to zero.
### Profile: Resilient data tier
*Purpose:* upgrade the baseline to high availability so you can compare ZONAL vs REGIONAL Cloud SQL, BASIC vs STANDARD_HA Redis, and VM-based NFS vs managed Filestore side by side.
*Modules:* Services_GCP (update in place), App_CloudRun unchanged.
| Variable | Value |
|---|---|
| `postgres_database_availability_type` | `REGIONAL` |
| `create_postgres_read_replica` | `true` |
| `create_redis` | `true` |
| `redis_tier` | `STANDARD_HA` |
| `redis_persistence_mode` | `RDB` |
| `create_filestore_nfs` | `true` |
| `filestore_tier` | `BASIC_HDD` (default) |
*Estimated incremental cost:* high — REGIONAL Cloud SQL roughly doubles instance cost, the read replica adds another instance, STANDARD_HA Redis doubles Redis cost, and Filestore bills a minimum 1024 GB.
### Profile: GKE architecture
*Purpose:* deploy the same workload on GKE Autopilot to exercise the Cloud Run vs GKE decision, Kubernetes governance (quotas, PDBs, NetworkPolicy), and Gateway API exposure.
*Modules:* Services_GCP (update), then App_GKE.
| Variable | Value |
|---|---|
| `create_google_kubernetes_engine` | `true` (Services_GCP) |
| `gke_cluster_mode` | `AUTOPILOT` (default) |
| `enable_resource_quota` | `true` (App_GKE) |
| `enable_network_segmentation` | `true` (App_GKE) |
| `enable_pod_disruption_budget` | `true` (default, App_GKE) |
| `stateful_pvc_enabled` | `true`, with `stateful_pvc_size = "10Gi"` and a mount path |
*Estimated incremental cost:* moderate — Autopilot bills per pod resource request plus a cluster management fee; the stateful PVC adds a small persistent disk.
### Profile: Security and delivery
*Purpose:* layer in defense-in-depth (CMEK, Binary Authorization, VPC-SC dry run, audit logs) and a full CI/CD pipeline with progressive delivery — the backbone for Sections 3, 4, and 6.
*Modules:* Services_GCP (update), App_CloudRun (update).
| Variable | Value |
|---|---|
| `enable_cmek` | `true` (Services_GCP) |
| `enable_binary_authorization` | `true`, `binauthz_evaluation_mode = "REQUIRE_ATTESTATION"` (Services_GCP) |
| `enable_vpc_sc` | `true`, `vpc_sc_dry_run = true` (Services_GCP; needs org + `admin_ip_ranges`) |
| `enable_audit_logging` | `true` (Services_GCP) |
| `enable_cloud_armor` | `true` (`application_domains` optional on App_CloudRun) |
| `enable_iap` | `true`, plus `iap_authorized_users` (App_CloudRun) |
| `enable_cicd_trigger` | `true`, plus `github_repository_url` (App_CloudRun) |
| `enable_cloud_deploy` | `true` (App_CloudRun) |
| `enable_auto_password_rotation` | `true` (App_CloudRun) |
*Estimated incremental cost:* moderate — KMS keys, the global load balancer forwarding rule, and audit-log storage are the main drivers; VPC-SC and Binary Authorization are free.
## Section 1: Designing and planning a cloud solution architecture (~25% of the exam)
The heart of the PCA exam: choosing architectures that satisfy business and technical requirements. The modules embody the canonical trade-offs — serverless vs orchestrated compute, zonal vs regional databases, managed vs self-managed file storage — but business analysis, migration planning, and futures thinking live outside any Terraform module.
| Exam topic | Coverage | Where in RAD | Guide |
|---|---|---|---|
| 1.1 Business requirements (cost, security, success measures) | 🟡 | `min_instance_count`, `create_billing_budget`, `enable_iap`, `support_users` | [Section 1 guide](PCA_Section_1_Exploration_Guide.md#11-designing-a-cloud-solution-infrastructure-that-meets-business-requirements) |
| 1.2 Technical requirements (HA, scalability, reliability) | ✅ | `postgres_database_availability_type`, `redis_tier`, `create_postgres_read_replica`, HPA/PDB in App_GKE | [Section 1 guide](PCA_Section_1_Exploration_Guide.md#12-designing-a-cloud-solution-infrastructure-that-meets-technical-requirements) |
| 1.3 Network, storage, and compute design | ✅ | VPC + Cloud NAT + private services access, Filestore vs self-managed NFS, App_CloudRun vs App_GKE | [Section 1 guide](PCA_Section_1_Exploration_Guide.md#13-designing-network-storage-and-compute-resources) |
| 1.4 Creating a migration plan | 📘 | nearest: `enable_backup_import` data import jobs | [Section 1 guide](PCA_Section_1_Exploration_Guide.md#14-creating-a-migration-plan) |
| 1.5 Envisioning future solution improvements | 📘 | nearest: layered module architecture, discovery-vs-inline pattern | [Section 1 guide](PCA_Section_1_Exploration_Guide.md#15-envisioning-future-solution-improvements) |
## Section 2: Managing and provisioning a cloud solution infrastructure (~17.5% of the exam)
Provisioning is what the modules do for a living: a custom-mode VPC with Cloud NAT and private services access, four database engines, three flavors of file/object storage, and two container platforms — all declaratively. Hybrid topologies and the two Vertex AI subsections are study-only.
| Exam topic | Coverage | Where in RAD | Guide |
|---|---|---|---|
| 2.1 Configuring network topologies | 🟡 | `availability_regions`, `subnet_cidr_range`, Cloud NAT + private services access; no hybrid/Shared VPC | [Section 2 guide](PCA_Section_2_Exploration_Guide.md#21-configuring-network-topologies) |
| 2.2 Configuring individual storage systems | ✅ | `storage_buckets`, `backup_schedule`, `create_filestore_nfs`, Cloud SQL PITR | [Section 2 guide](PCA_Section_2_Exploration_Guide.md#22-configuring-individual-storage-systems) |
| 2.3 Configuring compute systems | ✅ | `gke_cluster_mode`, `gke_autoscaling_profile`, `container_resources`, `execution_environment` | [Section 2 guide](PCA_Section_2_Exploration_Guide.md#23-configuring-compute-systems) |
| 2.4 Leveraging Vertex AI for end-to-end ML workflows | 📘 | not implemented | [Section 2 guide](PCA_Section_2_Exploration_Guide.md#24-leveraging-vertex-ai-for-end-to-end-ml-workflows) |
| 2.5 Configuring prebuilt solutions or APIs with Vertex AI | 📘 | nearest: `secret_environment_variables` for API keys | [Section 2 guide](PCA_Section_2_Exploration_Guide.md#25-configuring-prebuilt-solutions-or-apis-with-vertex-ai) |
## Section 3: Designing for security and compliance (~17.5% of the exam)
The Security and delivery profile turns on most of what this section tests: dedicated least-privilege service accounts, CMEK with automatic rotation, Binary Authorization attestation, VPC Service Controls in dry-run mode, IAP zero-trust access, and comprehensive audit logging. Organization hierarchy and regulatory frameworks remain study topics.
| Exam topic | Coverage | Where in RAD | Guide |
|---|---|---|---|
| 3.1 Security — IAM, secrets, encryption, supply chain, perimeters | ✅ | `enable_cmek`, `enable_binary_authorization`, `enable_vpc_sc`, `enable_iap`, the platform's secrets and IAM layers | [Section 3 guide](PCA_Section_3_Exploration_Guide.md#31-designing-for-security) |
| 3.1 Security — resource hierarchy, org policies | 📘 | not implemented | [Section 3 guide](PCA_Section_3_Exploration_Guide.md#31-designing-for-security) |
| 3.1 Security — Workload Identity Federation (keyless CI) | ✅ | `enable_workload_identity_federation`, `wif_provider_type` (Services_GCP) | [Section 3 guide](PCA_Section_3_Exploration_Guide.md#31-designing-for-security) |
| 3.2 Compliance — auditability, ITAR/HIPAA-style controls | 🟡 | `enable_audit_logging`, `enable_security_command_center`, `vpc_sc_dry_run` | [Section 3 guide](PCA_Section_3_Exploration_Guide.md#32-designing-for-compliance) |
## Section 4: Analyzing and optimizing technical and business processes (~15% of the exam)
CI/CD and release governance are fully demonstrable: a GitHub-triggered Cloud Build pipeline, Kaniko image builds into Artifact Registry, optional Binary Authorization attestation, and a Cloud Deploy pipeline whose default `prod` stage requires manual approval. SRE culture, post-mortems, and stakeholder management are people topics — study them separately.
| Exam topic | Coverage | Where in RAD | Guide |
|---|---|---|---|
| 4.1 Technical processes — SDLC, CI/CD, testing | 🟡 | `enable_cicd_trigger`, `cloud_deploy_stages`, `traffic_split` | [Section 4 guide](PCA_Section_4_Exploration_Guide.md#41-analyzing-and-defining-technical-processes) |
| 4.2 Business processes — change management, decision-making | 🟡 | `require_approval` gates in `cloud_deploy_stages`; cost guardrails via `create_billing_budget` | [Section 4 guide](PCA_Section_4_Exploration_Guide.md#42-analyzing-and-defining-business-processes) |
## Section 5: Managing implementation (~12.5% of the exam)
The platform *is* an implementation-management exhibit: a four-tier IaC architecture that development teams consume through a portal, with Artifact Registry hygiene policies and guardrail validations baked in. Raw SDK fluency (`gcloud`, client libraries, emulators) requires hands-on practice beyond the portal.
| Exam topic | Coverage | Where in RAD | Guide |
|---|---|---|---|
| 5.1 Advising development and operation teams | 🟡 | layered module architecture, `max_images_to_retain`, plan-time validations | [Section 5 guide](PCA_Section_5_Exploration_Guide.md#51-advising-development-and-operation-teams) |
| 5.2 Interacting with Google Cloud programmatically | 🟡 | OpenTofu workflow, `gcloud`-based provisioners and discovery scripts | [Section 5 guide](PCA_Section_5_Exploration_Guide.md#52-interacting-with-google-cloud-programmatically) |
## Section 6: Ensuring solution and operations excellence (~12.5% of the exam)
Day-2 operations: every deployment ships a monitoring dashboard and email alert channels; Cloud SQL and the NFS VM get CPU/memory/disk alerts; releases can be canaried with `traffic_split` and promoted through Cloud Deploy. Publicly reachable deployments also get a synthetic uptime check and alert policy via `uptime_check_config` (provisioned by the platform's monitoring layer); support processes and chaos engineering are concept-only.
| Exam topic | Coverage | Where in RAD | Guide |
|---|---|---|---|
| 6.1 Operational excellence pillar (Well-Architected Framework) | 🟡 | automation throughout; auto-healing NFS MIG, plan-time CMEK key recovery | [Section 6 guide](PCA_Section_6_Exploration_Guide.md#61-operational-excellence-pillar-well-architected-framework) |
| 6.2 Familiarity with Google Cloud Observability solutions | ✅ | `support_users`, `alert_policies`, `uptime_check_config`, the platform monitoring layer | [Section 6 guide](PCA_Section_6_Exploration_Guide.md#62-familiarity-with-google-cloud-observability-solutions) |
| 6.3 Deployment and release management | ✅ | `traffic_split`, `cloud_deploy_stages`, `max_revisions_to_retain` | [Section 6 guide](PCA_Section_6_Exploration_Guide.md#63-deployment-and-release-management) |
| 6.4 Assisting with the support of deployed solutions | 📘 | nearest: `support_users` notification channels | [Section 6 guide](PCA_Section_6_Exploration_Guide.md#64-assisting-with-the-support-of-deployed-solutions) |
| 6.5 Evaluating quality control measures | 🟡 | `enable_vulnerability_scanning`, Binary Authorization attestation step, the App_GKE plan-time validation suite | [Section 6 guide](PCA_Section_6_Exploration_Guide.md#65-evaluating-quality-control-measures) |
| 6.6 Ensuring the reliability of solutions in production | 🟡 | PDBs, topology spread, auto-healing NFS MIG, Redis production-tier guardrail | [Section 6 guide](PCA_Section_6_Exploration_Guide.md#66-ensuring-the-reliability-of-solutions-in-production) |
---
*Application wrapper modules (Django, WordPress, and others) exist on the platform but are out of scope for these guides — everything here is demonstrated with the four foundation modules alone.*
---
# PCA Certification Preparation Guide: Section 1 — Designing and planning a cloud solution architecture (~25% of the exam)
 > 📚 **Official exam guide:** [Professional Cloud Architect certification](https://cloud.google.com/learn/certification/cloud-architect) — always confirm section weightings against the current Google Cloud exam guide.
This is the heaviest-weighted PCA section, and it is about *choices*: which compute platform, which availability tier, which storage type — and why. All four foundation modules are exercised here. Deploy the **Lean baseline** profile from the [Lab Map](PCA_Certification_Guide.md) first, then apply the **Resilient data tier** and **GKE architecture** profiles as you reach 1.2 and 1.3, so you can compare the cheap architecture and the resilient one in the same project.
---
## 1.1 Designing a cloud solution infrastructure that meets business requirements
> ⏱ ~60 min · 💰 low — baseline profile only · ⚙️ Requires: Lean baseline profile
**Why the exam cares** — PCA scenarios open with business constraints, not technical ones: "minimize cost," "the security team requires zero-trust access," "leadership needs spend visibility." You are tested on translating those into platform decisions — scale-to-zero vs warm capacity, identity-based access vs network-based access, budgets and alerts as financial guardrails — and on recognizing which requirement drives which knob.
**How RAD implements it**
| Business requirement | Variable (default) | Module |
|---|---|---|
| Minimize idle cost | `min_instance_count` (default `0`) — Cloud Run scales to zero | App_CloudRun |
| Cap maximum spend on compute | `max_instance_count` (default `1`) | App_CloudRun |
| CPU billing trade-off | `cpu_always_allocated` (default `false` — request-based billing) — set `true` to keep CPU allocated between requests for in-process background work | App_CloudRun |
| Financial guardrails | `create_billing_budget` (default `false`), `budget_amount` (default `100`), `budget_alert_thresholds` (default `[0.5, 0.9, 1.0]`) | Services_GCP |
| Zero-trust access for internal apps | `enable_iap` (default `false`) + `iap_authorized_users` / `iap_authorized_groups` | App_CloudRun |
| Stakeholder visibility | `support_users` — becomes Cloud Monitoring email notification channels | App_CloudRun / App_GKE |
Cost-relevant platform choices also live in Services_GCP: the default database is a single zonal `db-custom-1-3840` PostgreSQL 17 instance (`postgres_tier`), and the default shared filesystem is a single `e2-small` VM (`create_network_filesystem`, default `true`) rather than managed Filestore — a deliberate cost-over-resilience default you will invert in 1.2.
**Try it**
1. Deploy the Lean baseline profile. In **Console > Cloud Run**, open your service and confirm "Min instances: 0" on the service details.
2. Watch the instance count fall to zero after an idle period on the service's **Metrics** tab, then send a request and observe the cold start.
3. Verify the scaling bounds from the CLI:
```bash
gcloud run services describe \
--region=us-central1 \
--format="yaml(spec.template.scaling)"
```
4. Set `create_billing_budget = true` on the Services_GCP deployment and inspect **Console > Billing > Budgets & alerts**.
5. You know it worked when the Metrics tab shows the instance count touching zero and a budget with 50%/90%/100% thresholds exists.
**Check yourself**
Q1: A startup runs an internal admin tool used a few hours per day and wants the lowest possible bill without exposing it to the internet. Which two settings from this platform meet both requirements?
A: `min_instance_count = 0` (scale-to-zero eliminates idle compute cost) and `enable_iap = true` with an authorized-users list (identity-based zero-trust access instead of a VPN or IP allowlist). IAP authenticates every request at Google's edge before it reaches the service, so no always-on network infrastructure is needed.
Q2: Finance wants to be warned before, not after, the monthly cloud budget is exhausted. What do you configure?
A: A billing budget with multiple alert thresholds — here `budget_alert_thresholds = [0.5, 0.9, 1.0]` notifies at 50% and 90% of `budget_amount`, before the 100% mark. Budgets alert but do not stop spending; pair them with `max_instance_count` caps if hard limits matter.
**Beyond the modules** — The exam also tests business analysis the modules cannot show: defining KPIs and success measures, CapEx-vs-OpEx framing, total cost of ownership, and build/buy/modify/deprecate workload disposition. Study the Google Cloud pricing calculator, "Cloud Billing reports" docs, and the Architecture Framework's cost optimization pillar. Try `gcloud billing accounts list` and explore **Billing > Reports** grouped by SKU in a scratch project.
**⚠️ Exam trap** — Budgets never *stop* spending; they only notify. If a scenario demands spend *enforcement*, the answer involves quotas, instance caps, or programmatic budget-response automation — not the budget alone.
---
## 1.2 Designing a cloud solution infrastructure that meets technical requirements
> ⏱ ~90 min · 💰 high — REGIONAL Cloud SQL roughly doubles instance cost; HA Redis and a read replica add more · ⚙️ Requires: Resilient data tier profile (+ GKE architecture profile for the HPA/PDB steps)
**Why the exam cares** — High availability, scalability, and reliability requirements ("99.95% uptime," "survive a zone failure," "handle 10× Black Friday traffic") each map to a specific mechanism with a specific cost. The exam expects you to know that zonal→regional Cloud SQL buys automatic zone failover, that read replicas buy read throughput but *not* HA, and that BASIC-tier Redis offers no replication at all.
**How RAD implements it**
| Requirement | Mechanism | Variable (default) |
|---|---|---|
| Database survives zone failure | Cloud SQL REGIONAL = synchronous standby in a second zone, automatic failover | `postgres_database_availability_type` (default `ZONAL`) |
| Read scale-out | Read replicas — always ZONAL in this module | `create_postgres_read_replica` (default `false`), `postgres_read_replica_count` (default `1`) |
| Point-in-time recovery | PITR with 7-day transaction log retention, 7 retained daily backups starting 04:00 UTC | always on for PostgreSQL |
| Cache survives instance failure | Memorystore `STANDARD_HA` = replica + automatic failover | `redis_tier` (default `BASIC`) |
| Cache survives restart | RDB snapshots or AOF | `redis_persistence_mode` (default `DISABLED`) |
| App scales with traffic (GKE) | HPA targeting 70% CPU / 80% memory utilization — created only when `max_instance_count` > 1 and `enable_vertical_pod_autoscaling = false` | `min_instance_count` (default `1`), `max_instance_count` (default `3`) in App_GKE |
| Voluntary-disruption protection | PodDisruptionBudget, skipped when `max_instance_count = 1` | `enable_pod_disruption_budget` (default `true`), `pdb_min_available` (default `"1"`) |
A guardrail worth studying: the platform's Redis layer carries two plan-time preconditions — one **blocks `redis_tier = "BASIC"` when `resource_labels.environment = "production"`**, and a second **blocks `redis_persistence_mode = "DISABLED"` on a production `STANDARD_HA` instance**, so production caches must enable `RDB` or `AOF`. That is the exam's "BASIC tier is not production-grade" lesson — and "cached state must survive failover" — encoded as validations.
**Try it**
1. Apply the Resilient data tier profile. In **Console > SQL**, open the instance — the overview shows high availability (regional) and a failover option.
2. Confirm from the CLI and find the standby zone:
```bash
gcloud sql instances describe \
--format="value(settings.availabilityType, gceZone, secondaryGceZone)"
```
3. In **Console > Memorystore > Redis**, verify the instance tier shows Standard.
4. On the GKE profile, inspect the autoscaler:
```bash
kubectl get hpa -n -o wide
```
5. You know it worked when `availabilityType` returns `REGIONAL` with a populated `secondaryGceZone`, and `kubectl get hpa` shows utilization targets of 70% (CPU) and 80% (memory).
**Check yourself**
Q1: An e-commerce database must survive a zone outage with no manual intervention, and the reporting team's heavy queries are slowing checkout. What two changes do you make?
A: Set the instance to REGIONAL availability (synchronous standby plus automatic failover handles the zone outage) and add a read replica, pointing the reporting workload at it (offloads reads). Neither substitutes for the other: replication to a read replica is asynchronous with no automatic failover, and a REGIONAL standby serves no read traffic.
Q2: A session cache on BASIC-tier Memorystore loses all data during maintenance, breaking user logins. Cheapest fix that survives both maintenance and instance failure?
A: Move to `STANDARD_HA`, which adds a replica and automatic failover — exactly what the module's production guardrail enforces. Persistence (`RDB`/`AOF`) additionally protects against full restarts. BASIC tier has no replica, so any failure event means a cold cache.
Q3: Why does the module skip creating a PodDisruptionBudget when `max_instance_count = 1`?
A: A PDB with `minAvailable: 1` on a single-replica workload would make the one pod unevictable, blocking node drains and GKE upgrades indefinitely. PDBs only make sense when spare replicas can keep serving during voluntary disruption — a validation in App_GKE also requires `pdb_min_available` to be less than `max_instance_count` (percentages exempt).
**⚠️ Exam trap** — Backups ≠ PITR ≠ HA. Backups recover to a snapshot time, PITR replays transaction logs to any moment within retention, and REGIONAL HA prevents the outage in the first place. A scenario asking to "recover the database to 14:32 yesterday" needs PITR; "no downtime during zone failure" needs REGIONAL; neither solves the other.
---
## 1.3 Designing network, storage, and compute resources
> ⏱ ~90 min · 💰 moderate — Filestore's 1024 GB minimum and the GKE cluster are the drivers · ⚙️ Requires: GKE architecture profile, optionally `create_filestore_nfs = true`
**Why the exam cares** — This is the product-selection subsection: VPC layout and private access patterns, file vs object vs block vs relational storage, and the serverless-vs-Kubernetes compute decision. The exam rewards knowing the *decision criteria* — POSIX semantics demand file storage, per-pod persistent state demands a StatefulSet, operational simplicity favors Cloud Run.
**How RAD implements it**
*Network*: a custom-mode VPC (subnets are not auto-created) with one subnet per entry in `availability_regions` (default `["us-central1"]`) sized by `subnet_cidr_range` (default `["10.0.0.0/24"]`); a Cloud Router and Cloud NAT per region (covering all subnets and IP ranges) so private workloads get outbound-only internet; and private services access (a global VPC-peering address range plus a service networking connection) carrying Cloud SQL and Memorystore traffic privately — the PostgreSQL instance has no public IP and uses encrypted-only SSL connections. GKE clusters are VPC-native (alias-IP), with pod/service secondary ranges derived per cluster from `gke_pod_base_cidr` (default `10.64.0.0/10`) and `gke_service_base_cidr` (default `10.8.0.0/16`).
*Storage* — the module set is a storage-selection matrix:
| Need | Service | Variable (default) |
|---|---|---|
| Relational, transactional | Cloud SQL PostgreSQL/MySQL, AlloyDB | `create_postgres` (default `true`), `create_mysql` (`false`), `enable_alloydb` (`false`) |
| Document / NoSQL | Firestore (Native mode, Enterprise edition) | `create_firestore` (default `false`) |
| Shared POSIX filesystem, managed | Filestore (`BASIC_HDD`/`BASIC_SSD`/`ENTERPRISE`) | `create_filestore_nfs` (default `false`), `filestore_capacity_gb` (default `1024`) |
| Shared POSIX filesystem, cheap | Self-managed NFS on an `e2-small` MIG with a stateful pd-ssd data disk, auto-healing, daily snapshots | `create_network_filesystem` (default `true`), `network_filesystem_capacity` (default `10` GB) |
| Object storage | GCS buckets with versioning, lifecycle rules, CMEK | `storage_buckets` list in App_CloudRun / App_GKE |
| In-memory cache | Memorystore Redis | `create_redis` (default `false`) |
| Per-pod block storage | StatefulSet PVCs (GKE only) | `stateful_pvc_enabled`, `stateful_pvc_size` |
The Filestore-vs-NFS-VM pair is a textbook managed-vs-self-managed trade-off: Filestore costs more (1 TiB minimum on BASIC tiers) but removes patching, healing, and snapshot management; the VM is cheap but is a single zonal instance whose resilience is only MIG auto-healing and daily disk snapshots. The platform's NFS-discovery layer prefers Filestore when both exist.
*Compute* — the same App_Common wiring deploys to either engine. Cloud Run: request-driven, `execution_environment` default `gen2` (required — and validated — for NFS and GCS Fuse mounts), `timeout_seconds` default `300`, no per-instance persistent volumes. GKE: `workload_type` (default `null`) auto-resolves — `stateful_pvc_enabled = true` selects a StatefulSet, otherwise a Deployment; setting `workload_type = "Deployment"` *alongside* `stateful_pvc_enabled = true` fails at plan time because Deployments do not honor per-replica volume claim templates.
**Try it**
1. In **Console > VPC network > VPC networks**, open the platform VPC; note custom subnet mode and the GKE subnet's two secondary ranges.
2. List the private services access allocation:
```bash
gcloud compute addresses list --global --filter="purpose=VPC_PEERING"
gcloud services vpc-peerings list --network=
```
3. Deploy App_GKE with `stateful_pvc_enabled = true`, `stateful_pvc_size = "10Gi"`, and a `stateful_pvc_mount_path`; leave `workload_type` unset. Then:
```bash
kubectl get statefulset,pvc -n
```
4. Now set `workload_type = "Deployment"` while keeping `stateful_pvc_enabled = true` and run a plan — read the validation error, then revert.
5. You know it worked when a StatefulSet with a bound PVC exists, and the deliberate misconfiguration was rejected at plan time, not at runtime.
**Check yourself**
Q1: A legacy CMS needs a shared writable filesystem across six replicas, with a strict SLA and no ops staff to babysit a file server. Which option here, and why not the default?
A: Filestore (`create_filestore_nfs = true`) — a managed service with no VM to patch or heal. The default self-managed NFS VM is far cheaper but is a single zonal `e2-small` whose recovery depends on MIG auto-healing and daily snapshots; "no ops staff + strict SLA" rules it out.
Q2: Why does Cloud Run gen2 matter for this platform's NFS support?
A: NFS and GCS Fuse volume mounts require Cloud Run's gen2 execution environment (full Linux kernel compatibility); gen1 does not support them. The module encodes this as a plan-time validation: `enable_nfs = true` with `execution_environment = "gen1"` is rejected before anything deploys.
Q3: A team must run a container with one persistent volume per replica and stable network identities. Cloud Run or GKE, and which workload type?
A: GKE with a StatefulSet — per-replica PVCs (`volumeClaimTemplates`) and stable pod identities are StatefulSet features. Cloud Run instances are ephemeral and share-nothing; its volume options (Cloud SQL socket, NFS, GCS Fuse) are shared, not per-instance block storage.
**Beyond the modules** — Not implemented here: Shared VPC host/service projects, VPC Network Peering between VPCs, Cloud DNS, internal load balancers, Spanner, Bigtable, and BigQuery. For the exam, be able to place each: Spanner for globally consistent relational scale, Bigtable for high-throughput wide-column time series, BigQuery for analytics. Read "Choose a storage option" and "Compare Google Cloud database services" in the official docs.
**⚠️ Exam trap** — "NoSQL" is not one answer. Firestore (the only NoSQL engine deployable here) suits document data with mobile/web sync; Bigtable suits petabyte time series; Memorystore is a cache, not a system of record — especially with persistence `DISABLED`, the default.
---
## 1.4 Creating a migration plan
> ⏱ ~30 min reading + a short lab on the import jobs · 💰 no additional cost · ⚙️ Requires: default deployment
**Why the exam cares** — Migration scenarios test sequencing (assess → plan → migrate → optimize), choosing rehost/replatform/refactor per workload, and data-transfer mechanics: online vs offline, downtime windows, dependency order.
**How RAD implements it** — The foundation modules deploy greenfield infrastructure; there is no migration tooling. The nearest adjacent capability is the data-import path in App_CloudRun/App_GKE: `enable_backup_import` (default `false`) with `backup_source` (`gcs` or `gdrive`), `backup_file`, and `backup_format` runs a containerized job that restores an existing database dump into the new Cloud SQL instance — a miniature "migrate the data, then cut over" exercise. Notice the real plan-time constraint: `backup_format = "auto"` is rejected when `backup_source = "gdrive"`.
**Try it**
1. Export a small PostgreSQL dump from any existing system and upload it to a GCS bucket.
2. Redeploy with `enable_backup_import = true`, `backup_source = "gcs"`, and the `backup_file` path; watch the import job in **Console > Cloud Run > Jobs**.
3. Verify activity on the target instance:
```bash
gcloud sql operations list --instance= --limit=5
```
4. You know it worked when the import job execution succeeds and your tables exist in the application database.
**Check yourself**
Q1: A company must move a 400 TB on-premises archive to GCS over a 100 Mbps link within a month. Which transfer approach?
A: Transfer Appliance (offline hardware). At 100 Mbps, 400 TB takes roughly a year online — far beyond the window. Storage Transfer Service or `gcloud storage` suits online transfers only when bandwidth × time covers the volume.
Q2: In a phased migration, which workloads move first?
A: Rehost (lift-and-shift) stateless, low-dependency workloads first for quick wins; refactor strategically valuable apps where cloud-native gains justify the effort; defer tightly coupled legacy systems until dependencies are mapped. The exam rewards "assess and map dependencies before moving anything."
**Beyond the modules** — Study Migration Center (discovery and assessment), Migrate to Virtual Machines, Database Migration Service (continuous replication into Cloud SQL with minimal downtime), and Storage Transfer Service vs Transfer Appliance selection. Also review the network prerequisites for migration — HA VPN and Cloud Interconnect — none of which the modules provision. Walk the **Migration Center** console flow in a scratch project.
---
## 1.5 Envisioning future solution improvements
> ⏱ ~30 min reading · 💰 no additional cost · ⚙️ Requires: default deployment
**Why the exam cares** — Architects design for change: new regions, new compliance regimes, replacing components without rework. The exam probes whether your design has seams — abstraction layers, loose coupling, declarative definitions — that let it evolve.
**How RAD implements it** — Not a deployable feature, but the repository itself is the exhibit. Two patterns are worth internalizing as exam-ready talking points. First, the **layered module architecture** (Platform → Foundation → Application): swapping Cloud Run for GKE is a one-layer change because both foundation engines consume the same shared configuration. Second, the **discovery-vs-inline pattern**: App_CloudRun and App_GKE probe for Services_GCP-managed resources (subnets carrying the description `managed-by=services-gcp`, labeled Artifact Registry repos) and provision inline equivalents only when the platform layer is absent — with `require_services_gcp_module` (default `true`) able to enforce platform presence. That is "design for evolving deployment topologies" in working code.
**Try it**
1. Note that the platform discovers shared subnets by the `managed-by=services-gcp` description filter.
2. Reproduce the discovery query the module runs:
```bash
gcloud compute networks subnets list \
--filter="description~managed-by=services-gcp" \
--format="table(name,network,region,description)"
```
3. You know it worked when the subnets your Services_GCP deployment created appear — the same signal a future App_GKE deployment would use to attach to them.
**Check yourself**
Q1: A platform team wants application teams to deploy onto shared infrastructure when it exists, but self-provision in isolated sandboxes when it does not. What architectural pattern supports this?
A: Discovery with inline fallback — probe for tagged/labeled shared resources at plan time and provision local equivalents only when absent, exactly as App_CloudRun does for VPC, SQL, NFS, and Artifact Registry. A policy flag (`require_services_gcp_module`) converts the fallback into a hard requirement for production.
**Beyond the modules** — Study the evolution mechanisms the modules do not show: event-driven decoupling with Pub/Sub and Eventarc, strangler-fig migration off monoliths, API versioning behind API Gateway/Apigee, and tracking Google Cloud release notes ("What's new") as ongoing architectural input.
---
# PCA Certification Preparation Guide: Section 2 — Managing and provisioning a cloud solution infrastructure (~17.5% of the exam)
 > 📚 **Official exam guide:** [Professional Cloud Architect certification](https://cloud.google.com/learn/certification/cloud-architect) — always confirm section weightings against the current Google Cloud exam guide.
This section tests whether you can actually stand infrastructure up — network topology, storage configuration, compute provisioning — and the two Vertex AI subsections added to the current exam guide. The modules exercised are `Services_GCP` (network, databases, GKE) and the two deployment engines. Deploy the **Lean baseline** profile from the [Lab Map](PCA_Certification_Guide.md), then enable GKE (**GKE architecture** profile) before 2.3. Subsections 2.4 and 2.5 are study-only.
---
## 2.1 Configuring network topologies
> ⏱ ~45 min · 💰 low — Cloud NAT and a static IP are minor costs · ⚙️ Requires: default Services_GCP deployment
**Why the exam cares** — Topology questions hinge on traffic direction and trust: how do private workloads reach the internet (NAT, egress-only), how do managed services get private connectivity (private services access), and how is east-west traffic constrained (firewall rules, tags). The exam then extends this to hybrid and multi-VPC designs, which you must study separately.
**How RAD implements it** — Here is how the platform implements it:
| Topology element | Implementation |
|---|---|
| Custom-mode VPC | one subnet per region in `availability_regions` (default `["us-central1"]`), CIDRs from `subnet_cidr_range` (default `["10.0.0.0/24"]`) |
| Outbound-only internet | a Cloud Router and Cloud NAT per region, covering all subnets and IP ranges |
| Private access to managed services | a global VPC-peering address plus a service networking connection (used by Cloud SQL and Memorystore private IP) |
| Health-check ingress | firewall `fw-allow-lb-hc` allowing `130.211.0.0/22` and `35.191.0.0/16` |
| Admin SSH without public IPs | firewall `fw-allow-iap-ssh` allowing `35.235.240.0/20` on tcp:22 (IAP TCP forwarding range) |
| Tag-based segmentation | tags `nfsserver`/`redisserver` open tcp 111/2049/6379 + udp 2049 only to tagged VMs; `httpserver`/`webserver` open 80/443/8080/8443 |
On the application side, App_CloudRun uses **Direct VPC egress** (a network interface on the subnet — no Serverless VPC Access connector), with `vpc_egress_setting` (default `PRIVATE_RANGES_ONLY`, or `ALL_TRAFFIC` to force everything through the VPC and NAT). App_GKE can add Kubernetes NetworkPolicies via `enable_network_segmentation` (default `false`) — covered in Section 3.
**Try it**
1. In **Console > VPC network > VPC networks**, open the platform VPC and review subnets; then **Console > Network services > Cloud NAT** for the NAT gateway.
2. List the firewall rules and map each to a trust decision:
```bash
gcloud compute firewall-rules list \
--filter="network=" \
--format="table(name,direction,sourceRanges.list(),allowed[].map().firewall_rule().list(),targetTags.list())"
```
3. In **Console > Cloud Run**, open your service's **Networking** tab and confirm the VPC egress setting.
4. You know it worked when you can explain every rule's source range — Google LB health checks, the IAP range, or intra-VPC — and the Cloud SQL instance shows only a private IP.
**Check yourself**
Q1: VMs in a private subnet must download OS packages but must never accept inbound internet connections. Which component, and why not external IPs?
A: Cloud NAT — it provides source NAT for egress with no inbound path, and removes the per-VM external IP attack surface. External IPs would work for egress but expose every VM to inbound scanning and violate the requirement.
Q2: Why does Cloud SQL need a "private services access" peering range instead of just living in your subnet?
A: Cloud SQL instances run in a Google-managed producer VPC, not yours. Private services access allocates an IP range from your VPC and peers it to the producer network, so the instance gets an RFC-1918 address reachable from your subnets — which is why this module can disable the public IP entirely and keep the database off the public internet.
Q3: An auditor asks how admins SSH to the NFS VM with no public IP and no VPN. What is the answer in this topology?
A: IAP TCP forwarding — the `fw-allow-iap-ssh` rule admits tcp:22 only from Google's IAP range `35.235.240.0/20`, and admins use `gcloud compute ssh --tunnel-through-iap`. Identity is verified by IAP before any packet reaches the VM.
**Beyond the modules** — Not implemented: Shared VPC, VPC peering between customer VPCs, Cloud VPN / Cloud Interconnect (hybrid), Network Connectivity Center, Cloud DNS, VPC flow logs, and hierarchical firewall policies. These are heavily examined — study "Choosing a Network Connectivity product" (Dedicated vs Partner Interconnect vs HA VPN decision tree, 99.99% SLA requires HA VPN or redundant Interconnect attachments), and Shared VPC host/service project IAM. In a scratch project, try `gcloud compute networks subnets update --enable-flow-logs`.
**⚠️ Exam trap** — Private Google Access, private services access, and Private Service Connect are three different things. This module uses private *services* access (VPC peering to managed-service producers). Don't pick PSC endpoints when the scenario describes Cloud SQL private IP via an allocated peering range.
---
## 2.2 Configuring individual storage systems
> ⏱ ~60 min · 💰 low–moderate — bucket storage is cheap; Filestore adds ~1 TiB minimum if enabled · ⚙️ Requires: App_CloudRun with `create_cloud_storage = true` and a `storage_buckets` entry
**Why the exam cares** — Storage configuration questions are about durability and cost mechanics: lifecycle transitions between storage classes, object versioning vs backups, retention for compliance, and database backup/PITR settings. You should be able to configure each and predict its cost behavior.
**How RAD implements it**
*Object storage* — the `storage_buckets` list (available on both App_CloudRun and App_GKE) provisions GCS buckets through the platform's object-storage layer. Each entry supports `storage_class` (default `"STANDARD"`), `versioning_enabled` (default `false`), `lifecycle_rules` (age, newer-version counts, storage-class transitions), CORS, `public_access_prevention` (default `"enforced"`), and `uniform_bucket_level_access`. The platform also sets a zero-retention soft-delete policy so destroys are not blocked, empties buckets at destroy time, and applies a lifecycle delete rule on the backup bucket driven by `backup_retention_days` (default `7`).
*Database protection* — PostgreSQL gets 7 retained daily automated backups (04:00 UTC) plus PITR with 7-day log retention; disks are PD_SSD with autoresize. Application-level dumps are separate: a Cloud Scheduler job (`backup_schedule`, default `"0 2 * * *"`) triggers a containerized export job that writes dumps to the backup bucket.
*File storage* — Filestore (`create_filestore_nfs`, `filestore_tier` default `BASIC_HDD`, share name `share`, no-root-squash) vs the self-managed NFS VM with daily pd-ssd snapshots and 7-day snapshot retention.
**Try it**
1. Deploy with a bucket entry such as `{ name_suffix = "media", versioning_enabled = true, lifecycle_rules = [...] }` including a transition to `NEARLINE` after 30 days.
2. In **Console > Cloud Storage > Buckets**, open the bucket's **Lifecycle** tab and verify the rule; check **Protection** for versioning and public access prevention.
3. Confirm from the CLI:
```bash
gcloud storage buckets describe gs:// \
--format="yaml(lifecycle,versioning,publicAccessPrevention)"
```
4. In **Console > Cloud Scheduler**, find the backup schedule; trigger it manually ("Force run") and watch the export job in **Cloud Run > Jobs**, then verify the dump file landed in the backup bucket.
5. You know it worked when the lifecycle rule shows in the describe output and a fresh dump object exists after the forced run.
**Check yourself**
Q1: Compliance requires keeping uploaded documents for 90 days in fast storage, then cheap storage for 7 years, then deletion — with no application changes. How?
A: Object Lifecycle Management on the bucket: a SetStorageClass transition (e.g. to COLDLINE/ARCHIVE) at age 90 days and a Delete action at ~2,645 days. Lifecycle rules run server-side, so the application never changes. If regulators require *immutability*, add a retention policy with Bucket Lock — lifecycle alone does not prevent deletion.
Q2: The team enables object versioning "as a backup" but the bucket bill triples in a month. What happened and what fixes it?
A: Every overwrite/delete keeps a noncurrent version billed at full storage rates. Add lifecycle rules keyed on `num_newer_versions` (or noncurrent age) to prune old versions — exactly what `lifecycle_rules` in the `storage_buckets` entry expresses. Versioning protects against accidental deletion; it is not a managed backup with retention built in.
**⚠️ Exam trap** — The scheduled SQL-dump job and Cloud SQL automated backups are different layers: automated backups + PITR restore the *instance*; dumps in GCS are portable, survive instance deletion, and can seed migrations. A scenario about "restore after the instance was deleted" needs the export, not PITR.
---
## 2.3 Configuring compute systems
> ⏱ ~75 min · 💰 moderate — the GKE cluster fee and node/pod resources dominate · ⚙️ Requires: GKE architecture profile; try `gke_cluster_mode = "STANDARD"` in a scratch project if budget allows
**Why the exam cares** — Provisioning questions test the configuration surface of each compute platform: Autopilot vs Standard GKE (who manages nodes, how billing works), machine/resource sizing, autoscaling profiles, and serverless runtime settings. The exam loves "which mode/setting reduces ops burden vs grants control."
**How RAD implements it**
*GKE*: `create_google_kubernetes_engine` (default `false`) provisions 1–10 clusters (`gke_cluster_count`, default `1`). `gke_cluster_mode` (default `"AUTOPILOT"`) is the headline trade-off: Autopilot is fully managed per-pod billing with node auto-provisioning; `"STANDARD"` removes the default pool and creates an explicit node pool with `gke_node_machine_type` (default `e2-standard-4`), autoscaling `gke_node_min_count` (default `1`) to `gke_node_max_count` (default `5`), `gke_node_disk_type` (default `pd-balanced`), and Shielded nodes (secure boot + integrity monitoring). Both modes share: Dataplane V2, VPC-native IP allocation, the standard Gateway API channel, vertical pod autoscaling, managed Prometheus, the `REGULAR` release channel (fixed), cost allocation, and `gke_autoscaling_profile` (default `BALANCED`, or `OPTIMIZE_UTILIZATION` for aggressive scale-down). Note these clusters DO use `private_cluster_config { enable_private_nodes = true }` (nodes get no external IPs — required because RAD-managed projects deny `compute.vmExternalIpAccess`) with a dedicated `master_ipv4_cidr_block` from `gke_master_base_cidr`; only `enable_private_endpoint` stays `false`, so the control plane is still reachable on its public endpoint for CI/CD.
*Cloud Run*: `container_resources` (defaults `cpu_limit = "1000m"`, `memory_limit = "512Mi"`), startup CPU boost always on, `execution_environment` (default `gen2`), `timeout_seconds` (default `300`), session affinity enabled, and startup/liveness probes via `startup_probe_config` / `health_check_config`.
*Workload provisioning on GKE*: the same `container_resources` shape, Cloud SQL Auth Proxy sidecar injected when `enable_cloudsql_volume = true` (default) and a database exists, and CronJobs via the `cron_jobs` list.
**Try it**
1. In **Console > Kubernetes Engine > Clusters**, open the cluster — note "Mode: Autopilot", the release channel, and the enabled features list.
2. Compare via CLI:
```bash
gcloud container clusters describe \
--location=us-central1 \
--format="value(autopilot.enabled, releaseChannel.channel, autoscaling.autoscalingProfile)"
```
3. Change `gke_autoscaling_profile` to `OPTIMIZE_UTILIZATION` in the portal and re-apply; re-run the describe to see the profile change.
4. On Cloud Run, raise `container_resources.memory_limit` to `1Gi` and observe a new revision roll out in **Console > Cloud Run > Revisions**.
5. You know it worked when the describe output reflects each portal change without you touching a node, VM, or YAML file.
**Check yourself**
Q1: A team with no Kubernetes operations experience needs GKE for its API ecosystem but must not manage nodes, upgrades, or bin-packing. Which mode and why?
A: Autopilot (`gke_cluster_mode = "AUTOPILOT"`, the default here). Google manages nodes, repairs, and upgrades; billing is per pod resource request, so right-sizing requests is the only capacity task left. Standard mode is for workloads needing specific machine types, GPUs/local SSDs, or scheduling control — the module's own variable description calls out latency-sensitive gRPC workloads as the Standard-mode use case.
Q2: On Autopilot, what is the cost lever equivalent to "choosing a smaller machine type" on Standard?
A: Pod resource *requests* (`container_resources`) — Autopilot bills what pods request, not nodes. Over-requested CPU/memory is pure waste; VPA (enabled at the cluster level, and exposed per-workload via `enable_vertical_pod_autoscaling` in App_GKE) right-sizes requests from observed usage. `gke_autoscaling_profile = "OPTIMIZE_UTILIZATION"` additionally tightens scale-down.
Q3: When would you accept Standard mode's extra operational burden in this platform?
A: When workloads need explicit node control: a specific machine series (`gke_node_machine_type`), disk types, or scheduling behavior Autopilot constrains. The module then provisions a single explicit node pool with autoscaling 1–5 nodes and Shielded VM protections — operational burden traded for hardware control.
**⚠️ Exam trap** — Autopilot ≠ "no capacity planning." You still set requests/limits, and HPA/quota math still applies — App_GKE's `quota_memory_requests`-style values must use binary suffixes (`"4Gi"`), because a bare `"4"` is parsed by Kubernetes as 4 *bytes* and blocks all scheduling.
---
## 2.4 Leveraging Vertex AI for end-to-end ML workflows
> ⏱ ~study only · 💰 no platform cost · ⚙️ Requires: nothing deployable
**Why the exam cares** — The current PCA guide tests Vertex AI workflow architecture: pipelines for orchestration, feature consistency between training and serving, and choosing infrastructure (GPUs/TPUs, on-demand vs reserved) for training and inference.
**How RAD implements it** — Not implemented by the foundation modules. The closest adjacency is architectural: a trained model served as a container would deploy on these modules like any other workload (Cloud Run for spiky low-ops inference, GKE for GPU-backed or high-throughput serving).
**Beyond the modules** — Study Vertex AI Pipelines (Kubeflow Pipelines / TFX as pipeline definitions), Vertex AI Feature Store (online vs batch serving, preventing training-serving skew), BigQuery as the training data source and BigQuery ML for in-warehouse models, and accelerator selection (GPU vs TPU, on-demand vs reservations). In a scratch project, run the Vertex AI "Hello custom training" quickstart and `gcloud ai custom-jobs list` to see the job lifecycle.
**Check yourself**
Q1: A model performs well offline but degrades in production; investigation shows features are computed differently at serving time. Which Vertex AI component addresses this?
A: Vertex AI Feature Store — it centralizes feature definitions and serves the same feature values for training (batch) and prediction (online), eliminating training-serving skew caused by duplicated feature logic.
---
## 2.5 Configuring prebuilt solutions or APIs with Vertex AI
> ⏱ ~study only + 20 min secret-handling lab · 💰 no platform cost · ⚙️ Requires: default App_CloudRun deployment
**Why the exam cares** — You must select the right pre-trained API per use case (Vision, Video Intelligence, Speech-to-Text/Text-to-Speech, Dialogflow, Vertex AI Search, Gemini models via Model Garden) versus training a custom model — and integrate them *securely*.
**How RAD implements it** — The AI APIs themselves are not provisioned, but the secure-integration pattern is fully demonstrated: `secret_environment_variables` injects credentials into Cloud Run via Secret Manager references (never plaintext env vars), and App_GKE materializes secrets through the GKE Secret Manager CSI add-on (`SecretProviderClass` + secret sync). An application calling Gemini or Vision would receive its API key exactly this way.
**Try it**
1. Add a dummy secret to `secret_environment_variables` and redeploy.
2. In **Console > Cloud Run > (service) > Revisions > Containers**, confirm the variable shows as a secret reference, not a value; then:
```bash
gcloud run services describe --region=us-central1 \
--format="yaml(spec.template.containers[0].env)"
```
3. You know it worked when the env entry shows `valueSource.secretKeyRef` rather than a literal value.
**Check yourself**
Q1: A product needs OCR on scanned invoices and a conversational support agent. Which pre-trained APIs, and when would you switch to custom training?
A: Cloud Vision API (OCR/document text detection) and Dialogflow CX (conversational agents). Switch to custom training (Vertex AI) only when the pre-trained model's quality on your domain data is insufficient — e.g. specialized invoice layouts needing Document AI custom processors or fine-tuned models. Pre-trained first is the exam's default posture.
**Beyond the modules** — Study the official API categories (Vision, Imagen, Video Intelligence, Speech, Dialogflow, Vertex AI Search), Model Garden deployment options, and grounding/RAG patterns with Vertex AI Search. Try `gcloud ml vision detect-text ` in a scratch project for a two-minute taste of a pre-trained API.
---
# PCA Certification Preparation Guide: Section 3 — Designing for security and compliance (~17.5% of the exam)
 Security design is where the RAD modules are at their densest: dedicated service accounts everywhere, secrets that never touch Terraform state, CMEK with automatic rotation and even automatic key *recovery*, Binary Authorization, VPC Service Controls with a deliberately staged dry-run rollout, and zero-trust access via IAP. Deploy the **Security and delivery** profile from the [Lab Map](PCA_Certification_Guide.md) on top of a baseline deployment. Modules exercised: `Services_GCP`, `App_CloudRun` (or `App_GKE`), and the `App_Common` security layers (secrets, IAM, CMEK, and VPC-SC).
---
## 3.1 Designing for security
> ⏱ ~2–3 h · 💰 moderate — KMS keys and the Cloud Armor load balancer; Binary Authorization and VPC-SC are free · ⚙️ Requires: Security and delivery profile (VPC-SC additionally needs the project in a GCP organization and non-empty `admin_ip_ranges`)
**Why the exam cares** — PCA security questions are layered-defense design: who can act (IAM, separation of duties), how data is protected (encryption at rest/in transit, CMEK control), what can run (supply-chain integrity), where data can flow (perimeters, network segmentation), and who can reach the app (zero-trust access). The exam tests choosing the right layer for a requirement — e.g. data-exfiltration prevention is VPC-SC, not firewall rules.
**How RAD implements it**
*Identity and least privilege.* Services_GCP creates dedicated service accounts per duty — `cloudrun-sa-{prefix}`, `cloudbuild-sa-{prefix}`, `clouddeploy-sa-{prefix}`, `gke-sa-{prefix}`, `nfs-sa-{prefix}` — never the default compute SA. The platform's IAM layer grants resource-scoped bindings: `roles/secretmanager.secretAccessor` *per secret* and `roles/storage.objectAdmin` *per bucket*, plus `roles/iam.serviceAccountUser` for controlled impersonation by the build SA. On GKE, Workload Identity binds a per-namespace KSA to the GCP SA via `roles/iam.workloadIdentityUser` — no key files anywhere.
*Secrets.* The platform's secrets layer generates the 32-character database password and stores it in Secret Manager; the GitHub token is written with `gcloud secrets versions add` precisely so it never enters deployment state. `secret_rotation_period` (default `2592000s` = 30 days) and `enable_auto_password_rotation` (default `false`) drive a dual-version, zero-downtime rotation flow: an Eventarc-triggered dispatcher runs a rotator job that executes `ALTER USER`, adds the new secret version, and disables the old one only after a propagation delay.
*Encryption.* `enable_cmek` (default `false`) creates a keyring with separate keys for Cloud SQL, Artifact Registry, and GCS, rotating every `cmek_key_rotation_period` (default `7776000s` = 90 days), and grants `roles/cloudkms.cryptoKeyEncrypterDecrypter` to each service agent. A plan-time recovery step in the platform's object-storage layer detects key versions scheduled for destruction or disabled and restores them before any encrypted resource is provisioned — operational self-healing for the classic "someone scheduled the key for destruction" incident.
*Supply chain.* `enable_binary_authorization` (default `false`) with `binauthz_evaluation_mode` (default `ALWAYS_ALLOW`; set `REQUIRE_ATTESTATION` to enforce) creates a KMS RSA-2048 signing key, a Container Analysis note and attestor, and an additive policy that blocks and audit-logs non-conforming images. GKE clusters enforce the project's singleton Binary Authorization policy when enabled. `enable_vulnerability_scanning` turns on Artifact Registry scanning.
*Perimeters.* `enable_vpc_sc` (default `false`, `vpc_sc_dry_run` default `true`) builds a perimeter restricting ~15 services with four access levels (VPC CIDRs, `admin_ip_ranges`, the IAP SA, CI/CD SAs). The organization ID is resolved from the project (with an explicit `organization_id` variable override available in App_CloudRun/App_GKE — needed when the project sits under a *folder*, where auto-discovery returns nothing), and a permission probe checks the caller's Access Context Manager rights, skipping with a warning instead of failing the apply.
*Edge and runtime.* `enable_iap` grants `roles/run.invoker` to the IAP service agent and `roles/iap.httpsResourceAccessor` to `iap_authorized_users`/`iap_authorized_groups` (validation requires at least one). `enable_cloud_armor` deploys OWASP preconfigured WAF rules (sqli/xss/lfi/rce, v33-stable), Adaptive Protection, and a 500 req/min/IP rate limit with a 300 s ban. `application_domains` is optional — the module derives a `nip.io` managed certificate when it is empty. On GKE, `enable_network_segmentation` (default `false`) creates default-deny-shaped NetworkPolicies on Dataplane V2: ingress only from the same namespace plus Google LB health-check and IAP ranges; egress only to DNS, HTTPS (including the restricted/private googleapis ranges `199.36.153.4/30` and `199.36.153.8/30`), Cloud SQL on 3307, the metadata server, and NFS when enabled.
**Try it**
1. In **Console > IAM & Admin > Service Accounts**, list the five platform SAs; pick one and inspect its bindings:
```bash
gcloud projects get-iam-policy \
--flatten="bindings[].members" \
--filter="bindings.members:cloudrun-sa-" \
--format="table(bindings.role)"
```
2. In **Console > Security > Secret Manager**, open the database password secret — confirm versions exist but values are never shown in plan output or the portal.
3. Enable `REQUIRE_ATTESTATION`, then attempt to deploy an unsigned image and watch the denial in **Console > Logging > Logs Explorer** (filter on Binary Authorization audit events).
4. With VPC-SC enabled in dry-run, review the perimeter:
```bash
gcloud access-context-manager perimeters list --policy= \
--format="table(name,title,spec.restrictedServices.list():label=DRY_RUN_SERVICES)"
```
5. On GKE with segmentation enabled: `kubectl describe networkpolicy -n ` and trace each rule to a trust decision.
6. You know it worked when the unsigned image is blocked, the perimeter shows in dry-run (`spec` populated, not `status`), and every IAM binding you find is scoped to a specific resource or duty.
**Check yourself**
Q1: A regulator requires that your company control — and be able to revoke — the encryption keys protecting customer data, with rotation at least quarterly. Which platform settings satisfy this, and what is the operational risk the module mitigates?
A: `enable_cmek = true` with the default `cmek_key_rotation_period = "7776000s"` (90 days) gives customer-managed keys with quarterly rotation; disabling/destroying the key revokes access to the data. The operational risk is self-inflicted denial of service — a key version scheduled for destruction bricks every encrypted bucket and repo — which the platform's plan-time key-recovery step mitigates by restoring versions that were scheduled for destruction or disabled.
Q2: A security team wants to guarantee that only images built by the official CI pipeline run in production. Which control, and what mode?
A: Binary Authorization with `binauthz_evaluation_mode = "REQUIRE_ATTESTATION"` — the CI pipeline signs (attests) each image digest with the KMS key, and the policy blocks unattested images at deploy time while audit-logging the decision. Vulnerability scanning alone only *reports*; IAM alone controls who deploys, not *what* is deployed.
Q3: Why is `vpc_sc_dry_run = true` the default, and what is the rollout sequence the exam (and this module's variable description) expects?
A: An enforced perimeter with wrong access levels instantly breaks CI/CD, deployments, and admin access — VPC-SC denials are hard failures at the API layer. Correct sequence: deploy in dry-run, monitor audit logs for would-be violations for days, add missing IPs/SAs to access levels, then flip `vpc_sc_dry_run = false`. Dry-run logs violations without blocking.
**Beyond the modules** — Two examined areas are absent. (1) **Resource hierarchy and organization policies**: folders, inheritance, constraints like `iam.disableServiceAccountKeyCreation` — study "Organization Policy Service" and try `gcloud resource-manager org-policies list` in an org-attached project. (2) **Hierarchical firewall policies and Cloud NGFW** — the modules use classic VPC firewall rules only. (Workload Identity Federation, formerly absent, is now live: `enable_workload_identity_federation` in Services_GCP creates pool `wif-pool` with a GitHub Actions / GitLab CI / generic OIDC provider per `wif_provider_type` — a working keyless-CI lab.)
**⚠️ Exam trap** — IAP and Cloud Armor answer different questions: IAP authenticates *identities* (who are you?); Cloud Armor filters *traffic* (is this request malicious?). "Only employees may access the app" → IAP; "block SQL injection and DDoS" → Cloud Armor. Scenarios often need both, but never one as a substitute for the other.
---
## 3.2 Designing for compliance
> ⏱ ~60 min · 💰 low–moderate — Data Access audit logs can grow log storage costs · ⚙️ Requires: `enable_audit_logging = true`; SCC steps need `enable_security_command_center = true` (org-level roles required for notifications)
**Why the exam cares** — Compliance questions test evidence and control mapping: which logs prove who did what (Admin Activity vs Data Access), how findings are surfaced and routed, and how regional/regulatory constraints (HIPAA, PCI-DSS, data residency) shape architecture.
**How RAD implements it**
*Audit trail.* `enable_audit_logging` (default `false`) configures `allServices` audit logs for `ADMIN_READ`, `DATA_READ`, and `DATA_WRITE` — Admin Activity (`ADMIN_WRITE`) is always on and free, but Data Access logs must be explicitly opted in, which is exactly what the platform does, plus explicit per-service configs for Secret Manager and Cloud KMS so secret and key access is provably logged.
*Findings and posture.* `enable_security_command_center` (default `false`) plus `enable_scc_notifications` route findings to a Pub/Sub topic (`scc-{prefix}-findings`). The notification config is gated by an org-permission probe — if the deploying SA lacks org-level SCC roles, the feature is skipped with a warning rather than failing the apply. GKE clusters additionally enable security posture management (mode `BASIC`, vulnerability mode `VULNERABILITY_BASIC`).
*Exfiltration and residency controls.* VPC-SC (3.1) is also the compliance answer for data-boundary requirements; region placement is controlled by `availability_regions`.
**Try it**
1. Enable `enable_audit_logging = true`, then read or write a secret version and find the access event:
```bash
gcloud logging read \
'logName:"cloudaudit.googleapis.com%2Fdata_access" AND protoPayload.serviceName="secretmanager.googleapis.com"' \
--limit=5 --format="table(timestamp, protoPayload.methodName, protoPayload.authenticationInfo.principalEmail)"
```
2. In **Console > IAM & Admin > Audit Logs**, verify Data Read/Write are enabled for "All services" with per-service rows for Secret Manager and KMS.
3. If SCC is active, browse **Console > Security > Security Command Center > Findings** and check for the `scc-{prefix}-findings` topic in **Pub/Sub**.
4. You know it worked when the log query returns the principal email and method for your secret access — audit evidence on demand.
**Check yourself**
Q1: An auditor asks for proof of every read of patient-data secrets in the last 30 days. Default project logging cannot provide it — why, and what does this platform change?
A: Reads are Data Access (`DATA_READ`) events, which Google disables by default for cost reasons; only Admin Activity is always on. `enable_audit_logging = true` opts all services into `ADMIN_READ`/`DATA_READ`/`DATA_WRITE`, with explicit Secret Manager coverage — making the read trail queryable in Logs Explorer (and exportable to BigQuery for long retention).
Q2: Why does the SCC notification feature "silently skip with a warning" instead of failing, and what design principle is that?
A: SCC notification configs require org-level permissions the deploying service account may not hold in every tenant project. The permission probe degrades gracefully — partial security posture rather than a failed platform deployment. The principle: separate *mechanism availability* from *privilege availability*, and never let an optional control block the critical path. Know for the exam that full SCC management is organization-scoped.
**Beyond the modules** — Not covered: Assured Workloads (regulated regions/personnel controls), Access Transparency (logs of *Google* personnel access), org-policy-based data residency (`gcp.resourceLocations`), DLP/Sensitive Data Protection for PII discovery and masking, and formal compliance mappings (HIPAA BAA, PCI-DSS responsibility splits). Study the "Compliance resource center" and run a DLP inspection template against a sample bucket in a scratch project.
**⚠️ Exam trap** — Admin Activity logs are free, always on, and immutable; Data Access logs are opt-in, high-volume, and billable (BigQuery and some services differ). A scenario about "who *changed* the firewall" needs no configuration at all; "who *read* the data" needs Data Access logs enabled *before* the incident — you cannot enable them retroactively.
---
# PCA Certification Preparation Guide: Section 4 — Analyzing and optimizing technical and business processes (~15% of the exam)
 > 📚 **Official exam guide:** [Professional Cloud Architect certification](https://cloud.google.com/learn/certification/cloud-architect) — always confirm section weightings against the current Google Cloud exam guide.
This section is about *process* architecture: software delivery lifecycle, testing and release strategy, and the organizational controls (approvals, cost governance, decision-making) wrapped around them. The deployable half lives in `App_CloudRun`'s CI/CD surface and the platform's Cloud Deploy layer; the people half — SRE culture, stakeholder management, post-mortems — must be studied from the SRE books and Architecture Framework. Deploy the **Security and delivery** profile from the [Lab Map](PCA_Certification_Guide.md) with `enable_cicd_trigger = true` and `enable_cloud_deploy = true`.
---
## 4.1 Analyzing and defining technical processes
> ⏱ ~90 min · 💰 low — Cloud Build minutes and Artifact Registry storage · ⚙️ Requires: Security and delivery profile + a GitHub repository (`github_repository_url`, token or App installation)
**Why the exam cares** — The exam tests SDLC design choices: where builds happen, how artifacts gain provenance, how releases progress through environments, and how risk is contained per stage (canary percentages, approval gates, rollback paths). Expect questions distinguishing CI (build/test/integrate) from CD (release/promote) and asking which Google tool owns which step.
**How RAD implements it**
| SDLC stage | Implementation | Variables (defaults) |
|---|---|---|
| Source trigger | Cloud Build GitHub trigger on push | `enable_cicd_trigger` (default `false`), `cicd_trigger_config.branch_pattern` (default `"^main$"`, plus included/ignored file filters) |
| Build | Kaniko executor `v1.23.2` builds in-cluster-less (no Docker daemon) and pushes to Artifact Registry tagged `latest`, the app version, and `COMMIT_SHA` | `enable_cicd_trigger` |
| Provenance | optional `gcloud beta container binauthz attestations sign-and-create` step signs the `COMMIT_SHA` digest with the KMS attestor key | `enable_binary_authorization` |
| Deploy (simple) | `gcloud run services update` to the new image | default path |
| Deploy (progressive) | Cloud Deploy pipeline with per-stage targets and skaffold configs in GCS | `enable_cloud_deploy` (default `false`), `cloud_deploy_stages` — default `dev` → `staging` → `prod` where **`prod` has `require_approval = true`** |
| Canary / blue-green | Cloud Run revision traffic splitting; entries must sum to exactly 100 (validated) | `traffic_split` (default `[]` = all traffic to latest) |
| Artifact hygiene | AR cleanup policies | `max_images_to_retain` (default `7`), `delete_untagged_images` (default `true`), `image_retention_days` (default `30`) |
Two details to internalize as exam material: builds tag every image with the immutable `COMMIT_SHA` (the digest the attestation signs — `latest` is never the deployment contract), and the default pipeline encodes the governance asymmetry the exam expects: pre-production promotes freely, production requires a human.
**Try it**
1. Push a commit to the configured branch and watch **Console > Cloud Build > History** — identify the Kaniko build step and (if enabled) the attestation step.
2. Inspect the resulting tags:
```bash
gcloud artifacts docker images list \
-docker.pkg.dev/// \
--include-tags --limit=5
```
3. With Cloud Deploy enabled, open **Console > Cloud Deploy > Delivery pipelines**, promote the release from `dev` to `staging`, then observe that `prod` waits in "Needs approval".
4. Configure a canary: set `traffic_split` to 90% LATEST / 10% a previous revision (with a `tag = "canary"`), apply, and verify:
```bash
gcloud run services describe --region=us-central1 \
--format="yaml(status.traffic)"
```
5. You know it worked when the prod stage is blocked pending approval and `status.traffic` shows the 90/10 split with the tagged canary URL.
**Check yourself**
Q1: A team wants new releases validated on 5% of production traffic with instant rollback. Which mechanism here, and what is the rollback action?
A: Cloud Run `traffic_split` — e.g. 95% to the stable revision, 5% to the new one (optionally with a stable `tag` URL for targeted testing). Rollback is a traffic reassignment to the previous revision, not a redeploy, because Cloud Run retains prior revisions (`max_revisions_to_retain`, default `7`). This is the serverless analogue of canary deployments the exam describes.
Q2: Why does the pipeline sign the image's COMMIT_SHA tag rather than `latest`?
A: Attestations bind to an immutable digest. `latest` is a moving pointer — signing it would attest "whatever this tag points to," defeating supply-chain integrity. The Binary Authorization policy verifies the digest being deployed carries a valid signature from the attestor, which only holds for the specific built artifact.
Q3: Where is the CI/CD boundary in this platform's pipeline?
A: CI = Cloud Build (trigger → Kaniko build → push to Artifact Registry → attest): producing a verified artifact. CD = Cloud Deploy (release → dev → staging → approval → prod): promoting that artifact through environments. The exam expects you to assign testing/build failures to CI and promotion/approval/rollout strategy to CD.
**Beyond the modules** — The exam also covers testing strategy (unit vs integration vs load; the pipeline here runs no test step — adding one is a good exercise), post-mortem/root-cause culture, and troubleshooting tooling (Cloud Profiler, Cloud Trace). Study the DORA metrics (deployment frequency, lead time, change-failure rate, MTTR) and the "Application deployment and testing strategies" architecture doc — rolling vs blue-green vs canary trade-offs are recurring exam material.
**⚠️ Exam trap** — Don't conflate Cloud Build triggers with Cloud Deploy. A scenario about "build on every merge" is Cloud Build; "promote the same artifact through dev/staging/prod with approvals" is Cloud Deploy. Rebuilding the image per environment (instead of promoting one artifact) is the anti-pattern the exam wants you to reject.
---
## 4.2 Analyzing and defining business processes
> ⏱ ~45 min · 💰 no additional cost · ⚙️ Requires: Cloud Deploy enabled (Security and delivery profile)
**Why the exam cares** — Architects operate change-management and governance processes, not just infrastructure: enforced approvals for regulated environments, cost accountability, skills-based platform choices (a team that cannot run Kubernetes should not be handed Kubernetes), and data-driven decision frameworks like SRE error budgets.
**How RAD implements it** — The deployable artifacts here are governance encoded as configuration. The default `cloud_deploy_stages` makes production promotion a human decision (`require_approval = true` on `prod`) — an auditable change-management gate satisfying separation-of-duties expectations, with `auto_promote` available per stage where velocity matters more. Cost accountability comes from `create_billing_budget` + `budget_alert_thresholds` (Section 1.1) and from GKE cost allocation (enabled on every cluster, supporting namespace-level cost breakdown in billing). And the platform's *existence* demonstrates a skills-readiness decision: the portal lets a team choose Cloud Run (low Kubernetes skill requirement) or GKE (full orchestration) for the same application — the choice itself is the business-process artifact.
**Try it**
1. Create a release and promote it to the `prod` stage; in **Console > Cloud Deploy > Delivery pipelines > (pipeline) > Releases**, click into the pending rollout and use **Approve** (or reject it).
2. Review the audit trail of that approval:
```bash
gcloud deploy rollouts list \
--delivery-pipeline= --release= \
--region=us-central1 \
--format="table(name,state,approvalState,deployStartTime)"
```
3. You know it worked when the rollout shows `approvalState: APPROVED` with a timestamp — evidence a change-advisory process can consume.
**Check yourself**
Q1: A regulated insurer requires documented sign-off before production changes, but wants zero friction in lower environments. How is this expressed in this platform — and in exam terms, what process is being implemented?
A: `cloud_deploy_stages` with `require_approval = false` (optionally `auto_promote = true`) on dev/staging and `require_approval = true` on prod — exactly the module default. This implements change management with separation of duties: the deployer and the production approver are distinct, and Cloud Deploy records both, producing the audit evidence (SOC 2-style change control) the scenario demands.
Q2: Leadership must choose between Cloud Run and GKE for a new product; the team has strong app developers and no platform engineers. What does the exam expect you to weigh?
A: Team skills readiness is a first-class architectural input. With no Kubernetes operations capability, Cloud Run's managed model (no clusters, quotas, PDBs, upgrades) reduces operational risk even if GKE offers more control; choosing GKE would require hiring or training (a cost and timeline factor). The exam consistently rewards matching platform complexity to organizational capability, not maximal flexibility.
**Beyond the modules** — Study what no module can show: SRE error budgets as a decision mechanism (feature velocity vs reliability), SLI/SLO definition with stakeholders, incident communication, and translating technical metrics into business KPIs. The free Google SRE book chapters "Embracing Risk" and "Service Level Objectives" are the canonical exam preparation here.
**⚠️ Exam trap** — An approval gate is change *management*, not change *validation*. If the scenario asks how to catch bad releases automatically, the answer is canary analysis/testing in the pipeline — a human approval button does not verify correctness, it assigns accountability.
---
# PCA Certification Preparation Guide: Section 5 — Managing implementation (~12.5% of the exam)
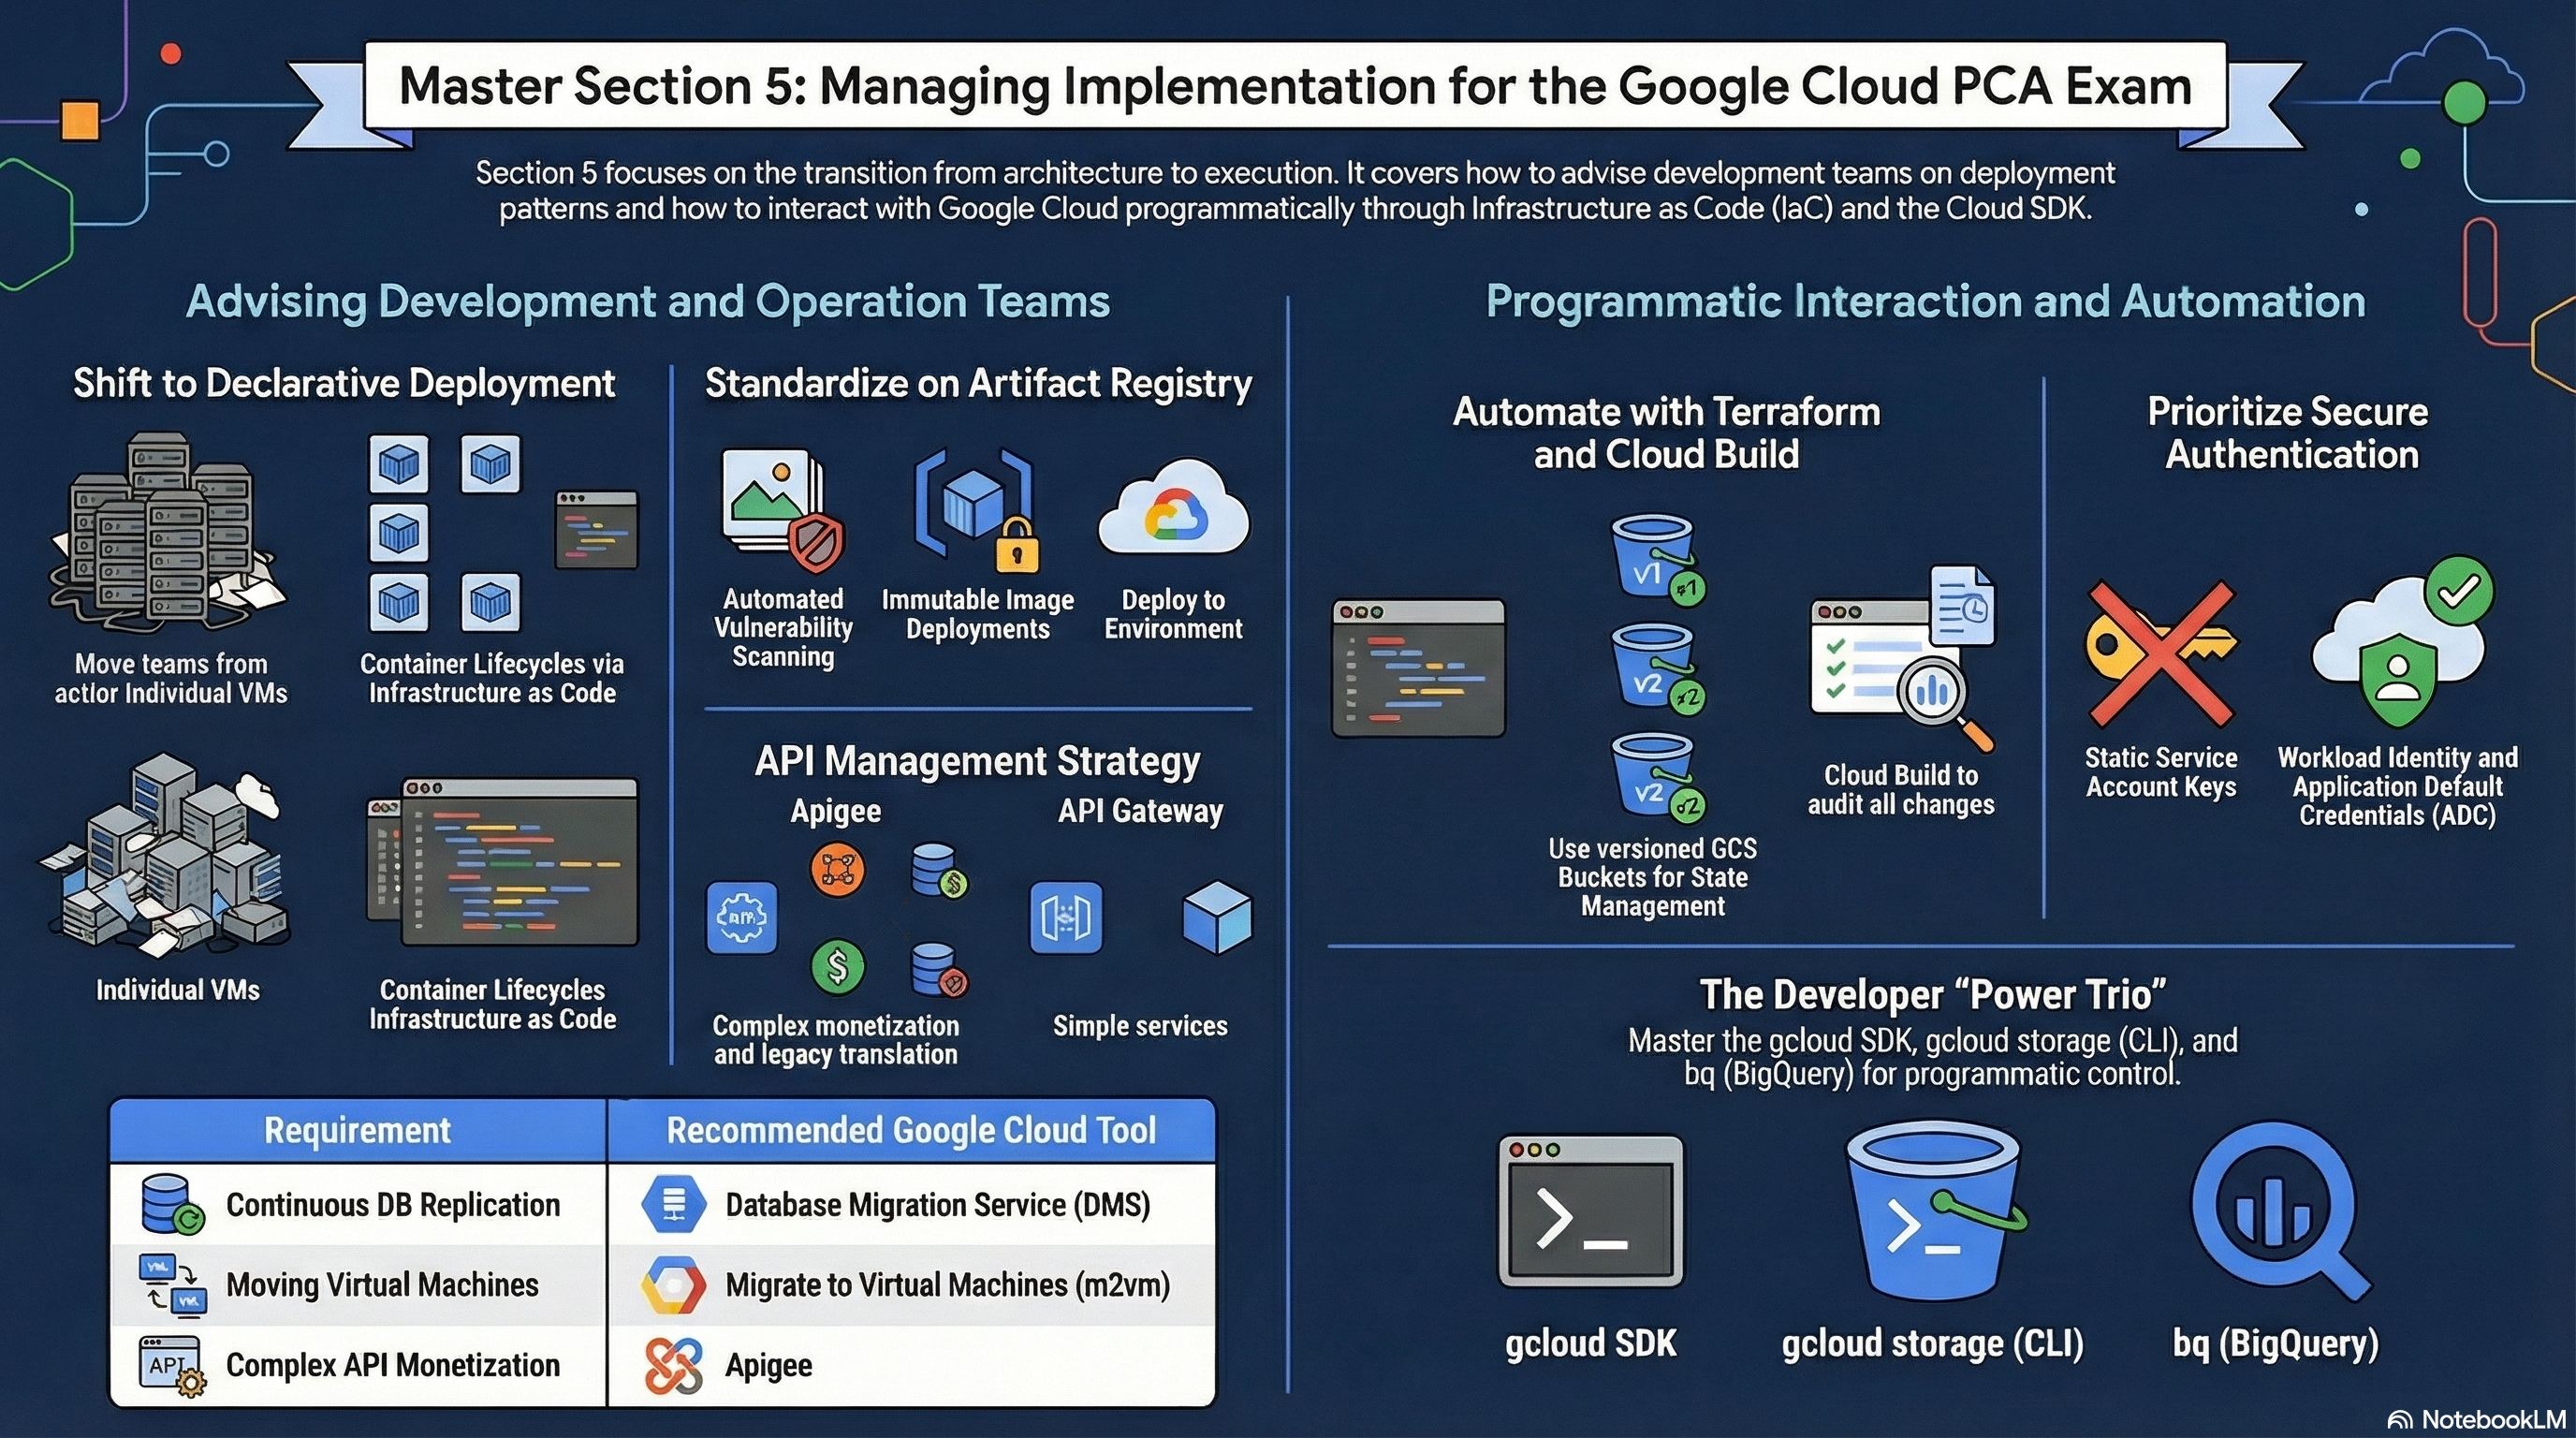 > 📚 **Official exam guide:** [Professional Cloud Architect certification](https://cloud.google.com/learn/certification/cloud-architect) — always confirm section weightings against the current Google Cloud exam guide.
Managing implementation means making other teams successful: providing paved paths, guardrails, and programmatic access patterns. The RAD platform is itself the exhibit — a four-tier Terraform/OpenTofu architecture that development teams consume through a portal, with validations that fail bad configurations at plan time and registry hygiene baked in. Deploy any profile from the [Lab Map](PCA_Certification_Guide.md); the **Security and delivery** profile makes the most artifacts visible. Modules exercised: all four, with emphasis on the platform's shared scripts and plan-time validations.
---
## 5.1 Advising development and operation teams
> ⏱ ~60 min · 💰 no additional cost · ⚙️ Requires: any deployed profile
**Why the exam cares** — Architects are advisors: they codify standards so teams cannot easily do the wrong thing, choose API-management and testing approaches, and set artifact and dependency policies. Exam scenarios ask what guidance or guardrail prevents a described failure.
**How RAD implements it** — Three advisory patterns are observable in the code:
*Paved path with guardrails.* The foundation modules expose a curated variable surface and reject misconfigurations at plan time — App_GKE carries 32 preconditions (min ≤ max instances, IAP completeness, PVC requirements, CDN/Armor prerequisites, name-length limits ≤ 55 chars, `gateway_backend_stage` must exist). Teams get expressive power; the platform team gets enforced invariants. This is "advising through tooling," and it is how the exam expects standards to scale beyond documentation.
*Artifact policy.* Artifact Registry is auto-discovered or created (`shared-repo-{prefix}`), with cleanup policies — `max_images_to_retain` (default `7`), `delete_untagged_images` (default `true`), `image_retention_days` (default `30`) — and optional CMEK (`enable_artifact_registry_cmek`) and vulnerability scanning. Third-party dependencies are not pulled from the internet at runtime: required images (e.g. the Cloud SQL Auth Proxy) are copied into AR using Crane with **digest comparison** — an existing tag is overwritten when its digest no longer matches the source, so a stale or tampered mirror is never silently used.
*Operational defaults.* Database client tooling ships as a purpose-built image, initialization jobs are first-class (`initialization_jobs` with `depends_on_jobs` ordering), and revision/image pruning keeps environments tidy without team effort.
**Try it**
1. Review five of App_GKE's plan-time preconditions; for each, write the production incident it prevents.
2. Deliberately violate one in the portal (e.g. `min_instance_count = 5`, `max_instance_count = 2`) and observe the plan-time error — the message names the variables and the fix.
3. Inspect the artifact policy in effect:
```bash
gcloud artifacts repositories describe \
--location= \
--format="yaml(cleanupPolicies,vulnerabilityScanningConfig)"
```
4. You know it worked when the bad configuration never reached an apply, and the repository shows cleanup policies a developer never had to write.
**Check yourself**
Q1: Development teams keep deploying containers that pull a third-party sidecar from Docker Hub at runtime, causing outages during registry rate-limiting. What do you advise, and what subtlety makes a naive mirror dangerous?
A: Mirror required third-party images into your own Artifact Registry and deploy only from there — as this platform does for the Cloud SQL Auth Proxy. The subtlety: a tag can silently drift upstream, so the mirror must compare digests (as this platform does with Crane) rather than assume "tag exists = up to date"; otherwise you pin to a stale or wrong image forever.
Q2: A platform team's written standards are ignored. What does this repository demonstrate as the scalable alternative?
A: Encode standards as plan-time validations and curated module variables — the standard becomes impossible to violate rather than merely documented. Misconfigurations fail with actionable error messages before any resource is created, which is cheaper than failing in production and faster than review-based enforcement.
**Beyond the modules** — Study what advising covers beyond IaC guardrails: API management selection (Apigee for monetization/analytics/legacy mediation vs API Gateway for lightweight serverless fronting), testing frameworks (unit/integration/load and where each runs in CI), Database Migration Service for advising on data moves, and Service Catalog for curated solution distribution. Try creating an API Gateway in a scratch project to feel the difference from Apigee's scope.
**⚠️ Exam trap** — "Store images in Container Registry" is a stale answer: Container Registry is deprecated in favor of Artifact Registry, which adds per-repository IAM, cleanup policies, CMEK, and scanning — the features this platform depends on.
---
## 5.2 Interacting with Google Cloud programmatically
> ⏱ ~60 min · 💰 no additional cost · ⚙️ Requires: any deployed profile + Cloud Shell or a workstation with `gcloud`
**Why the exam cares** — The exam tests fluency across the programmatic surface: declarative IaC vs imperative CLI, when each is appropriate, and how authentication works without key files. Expect "which command/approach" questions.
**How RAD implements it** — The portal compiles your variable choices and runs the OpenTofu lifecycle (`tofu init → plan → apply`) for you — every deployment you have done in these guides was a programmatic interaction. The modules also demonstrate the *boundary* of declarative IaC: where the provider has gaps, they shell out to `gcloud` deliberately — e.g. GKE add-ons are enabled via `gcloud container clusters update --enable-secret-manager`, Cloud Run jobs are executed with `gcloud run jobs execute --wait`, and discovery runs `gcloud compute networks subnets list --filter=...` inside external data scripts. Service-account impersonation (`--impersonate-service-account`, and the `impersonation_service_account` variable) is used throughout instead of key files.
**Try it**
1. Trigger a deployment from the portal — behind the scenes it runs the read-only half of the lifecycle (init → validate → plan) before any apply, rejecting invalid configurations at plan time.
2. Cross-check the declared state against live state imperatively:
```bash
gcloud run services list --region=us-central1
gcloud sql instances list
gcloud container clusters list
```
3. Note where the platform deliberately steps outside declarative IaC: discovery is fed by `gcloud ... --format=json` calls (e.g. subnet discovery), and add-ons are toggled with imperative `gcloud` commands where the provider has gaps.
4. You know it worked when the plan shows no unexpected diff (declarative truth) and the `gcloud` listings match it (imperative observation).
**Check yourself**
Q1: An operator "quickly fixed" a service's memory limit with `gcloud run services update`. What happens on the next platform deployment, and what does the exam call this?
A: Configuration drift — the next `tofu apply` reverts the manual change to the declared value (or surfaces it as a diff at plan time). The exam expects drift to be resolved by changing the declaration (the portal variable), never by repeated imperative patching; IaC is the source of truth.
Q2: A CI system needs to call GCP APIs as a privileged service account without storing a JSON key. Which patterns does this platform use?
A: Service-account impersonation — callers with `roles/iam.serviceAccountUser`/token-creator rights act as the target SA via `--impersonate-service-account`, receiving short-lived tokens (the modules pass `impersonation_service_account` into provider auth and gcloud calls). On GKE, Workload Identity binds Kubernetes service accounts to GCP SAs the same keyless way. Long-lived JSON keys are the anti-answer.
**Beyond the modules** — The exam's programmatic surface is wider: Cloud Shell and Cloud Code, `gcloud storage` (the modern `gsutil` replacement), `bq` for BigQuery, client libraries (Python/Java/Node) with Application Default Credentials resolution order, local emulators (Pub/Sub, Firestore, Spanner, Bigtable), and API quota/retry behavior (exponential backoff on `429`/`5xx`). Practice in Cloud Shell: `gcloud config list`, `gcloud auth application-default login`, and one client-library quickstart end to end.
**⚠️ Exam trap** — `gcloud auth login` (your user) and Application Default Credentials (`gcloud auth application-default login`, what client libraries see) are separate credential stores. A script that works in your terminal but fails with "could not find default credentials" inside code is the classic symptom — and a recurring exam distractor.
---
# PCA Certification Preparation Guide: Section 6 — Ensuring solution and operations excellence (~12.5% of the exam)
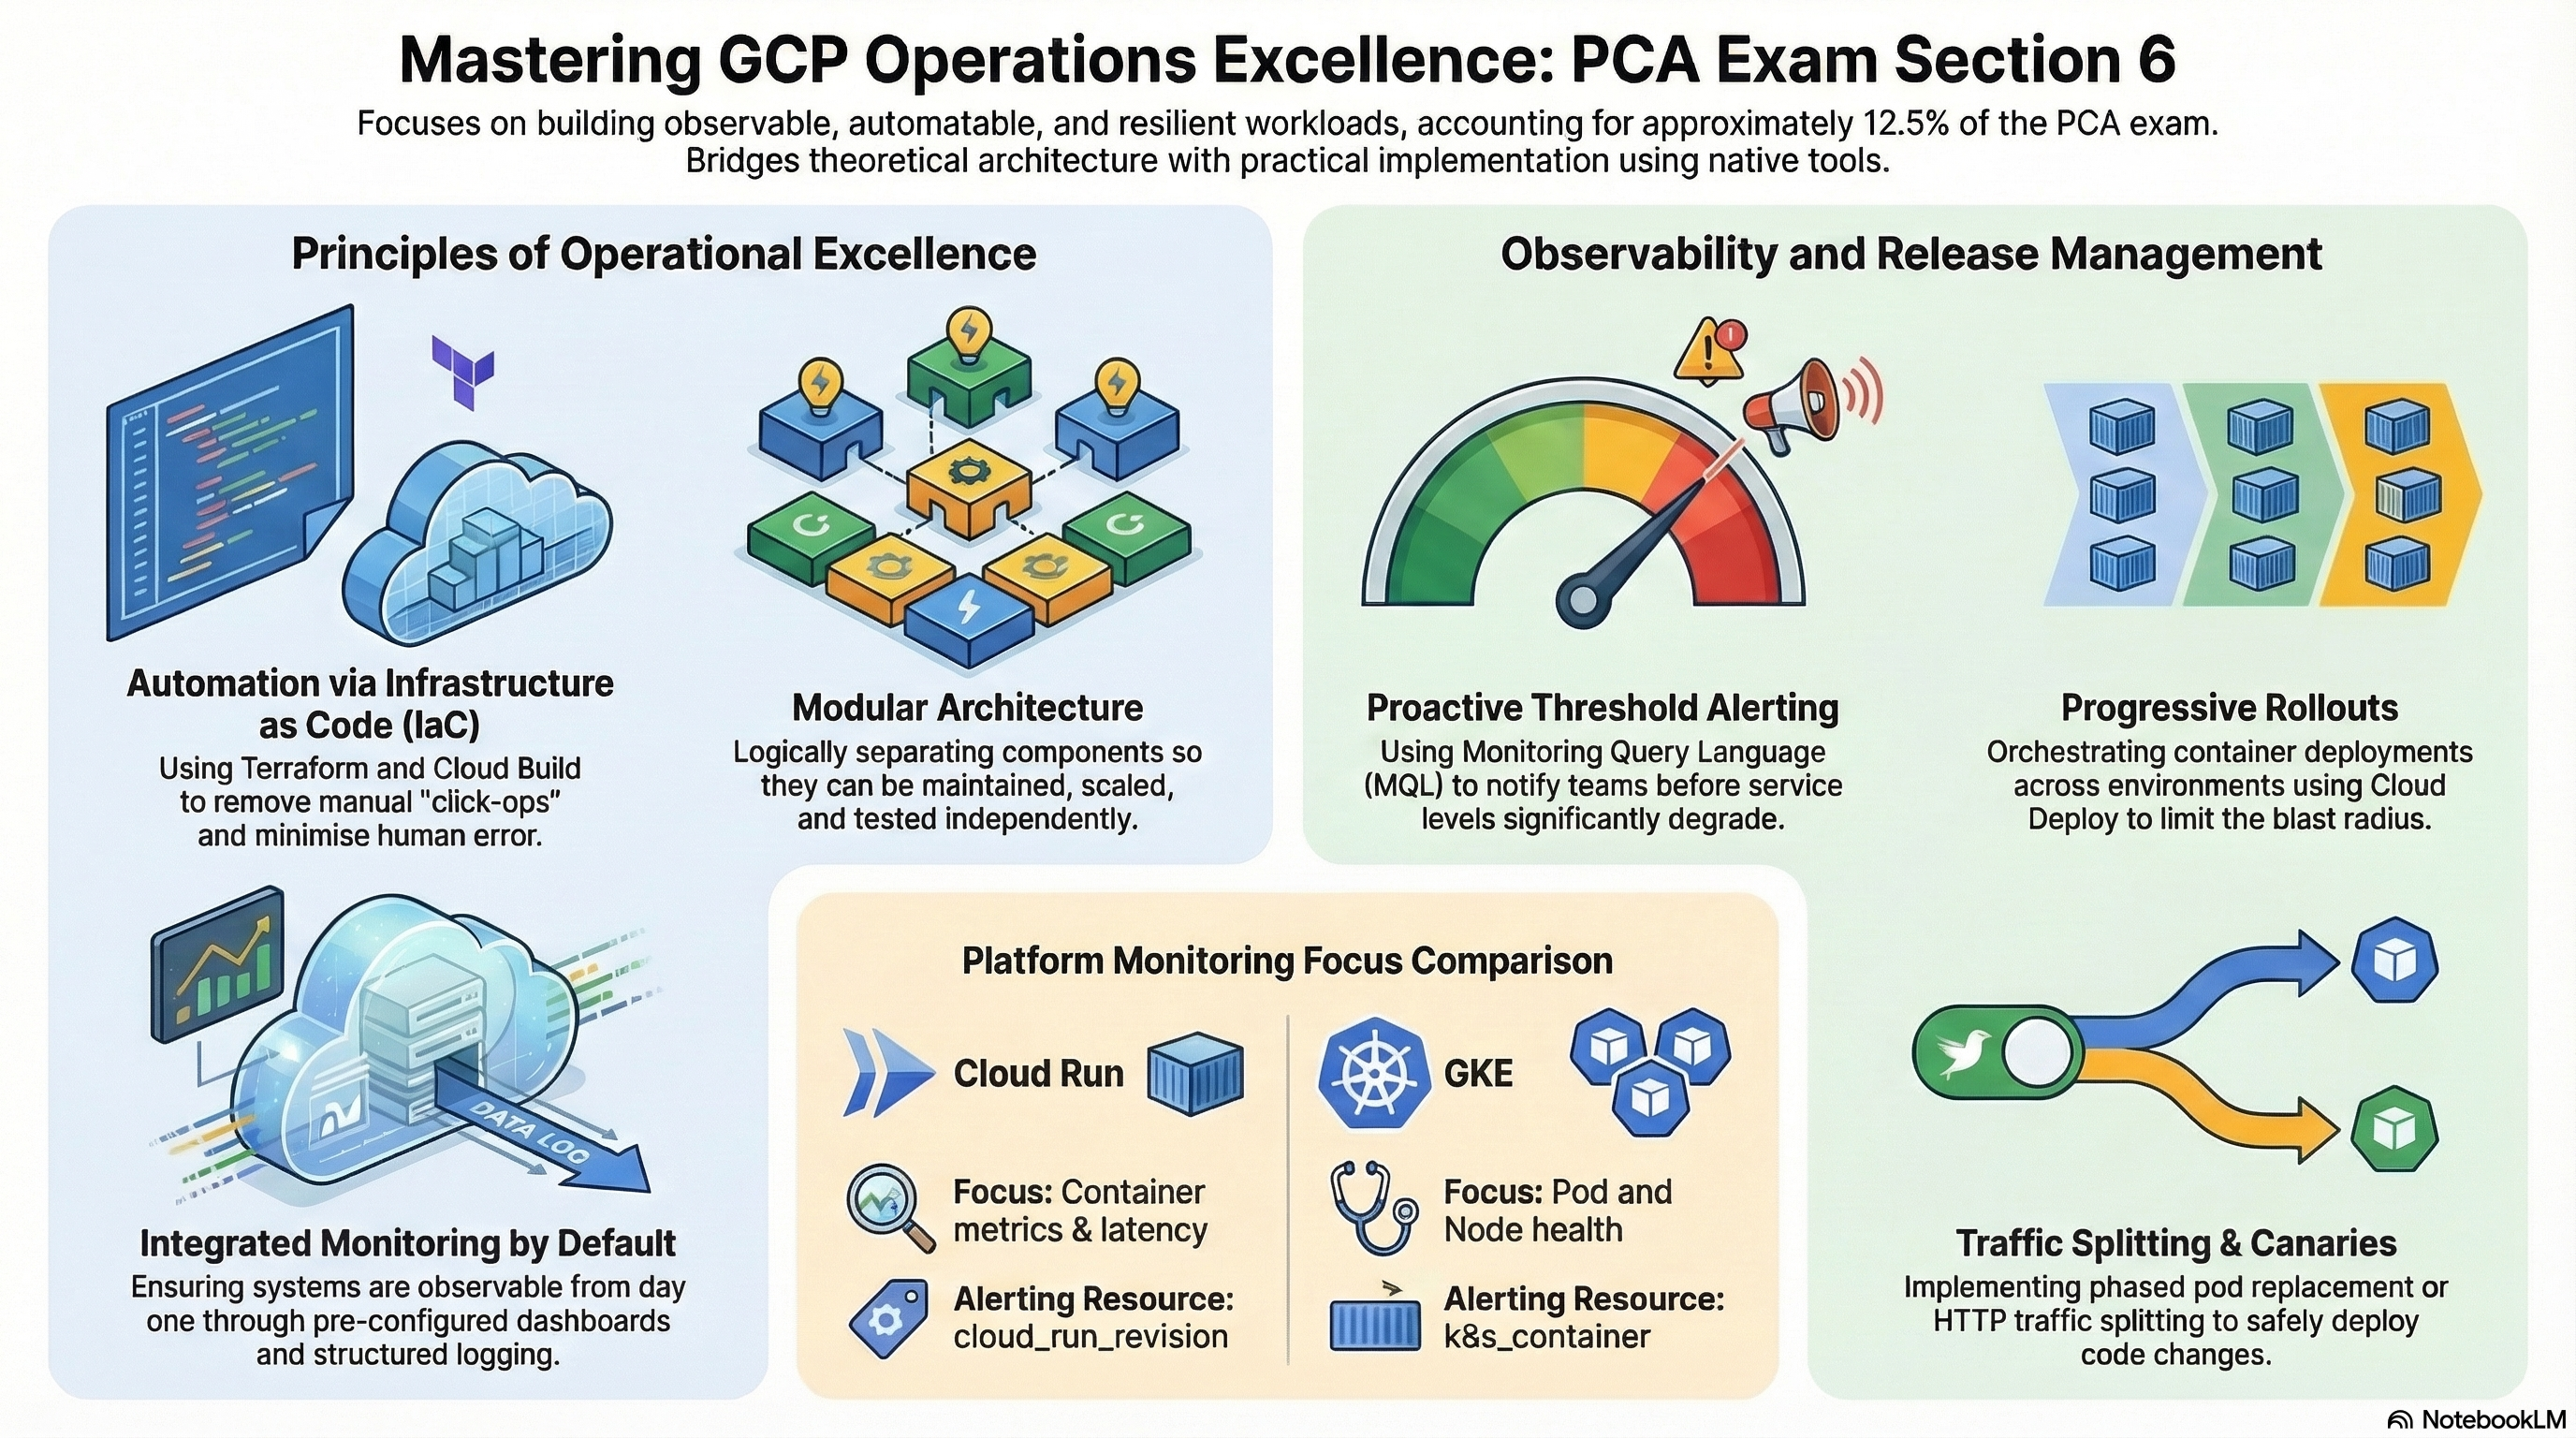 > 📚 **Official exam guide:** [Professional Cloud Architect certification](https://cloud.google.com/learn/certification/cloud-architect) — always confirm section weightings against the current Google Cloud exam guide.
Day-2 operations: observing systems, releasing safely, controlling quality, and keeping production reliable. Every RAD deployment ships with a dashboard and alerting wired to your email, and publicly reachable deployments add a synthetic uptime check (see 6.2) — so most of this section is observable on the **Lean baseline** profile from the [Lab Map](PCA_Certification_Guide.md); add the **Security and delivery** profile for release management (6.3) and the **GKE architecture** profile for the reliability mechanics in 6.6. Modules exercised: all four, with emphasis on the monitoring layers of `Services_GCP` and `App_CloudRun`, plus the platform's shared monitoring and dashboard layers.
---
## 6.1 Operational excellence pillar (Well-Architected Framework)
> ⏱ ~30 min reading + console review · 💰 no additional cost · ⚙️ Requires: default deployment
**Why the exam cares** — The Architecture Framework's operational excellence pillar — automate everything, make changes safely, prepare for failure, continuously improve — frames many scenario answers. The exam rewards recognizing operational toil and replacing it with automation.
**How RAD implements it** — The pillar is visible as a set of automations that remove human toil: the NFS VM is a managed instance group with TCP health checks and auto-healing plus daily disk snapshots (no pager for a hung file server); the platform restores disabled or destruction-scheduled CMEK key versions at *plan* time (self-healing before the failure manifests); orphaned Cloud Run jobs and old revisions are cleaned automatically; secret rotation is event-driven and zero-downtime; and the entire platform is declaratively reproducible, so environment rebuilds are an apply, not a runbook.
**Try it**
1. Pick three automations above (the auto-healing NFS instance group, the plan-time CMEK key recovery, and Cloud Run revision/job pruning), and write down the manual runbook each replaces.
2. Observe one in action — list the snapshot schedule protecting the NFS data disk:
```bash
gcloud compute resource-policies list --format="table(name,snapshotSchedulePolicy.schedule.dailySchedule)"
```
3. You know it worked when you can name, for each automation, the incident class it prevents rather than reacts to.
**Check yourself**
Q1: A team's runbook says "if the file server stops responding, SSH in and restart nfsd; if the disk is corrupted, restore last night's copy." What does this platform replace that with?
A: A managed instance group with TCP health checks (ports 2049/6379) and auto-healing — an unresponsive instance is automatically recreated with its stateful data disk reattached — plus a daily snapshot schedule with 7-day retention for the corruption case. The runbook becomes infrastructure; the exam calls this eliminating toil through automation.
**Beyond the modules** — Read the official "Google Cloud Architecture Framework: Operational excellence" pillar end to end — its principles (automate deployments, manage incidents, plan for DR) are quoted nearly verbatim in exam options. The framework's sustainability and performance pillars are also fair game and have no module analogue.
---
## 6.2 Familiarity with Google Cloud Observability solutions
> ⏱ ~60 min · 💰 low — log/metric volume only · ⚙️ Requires: default deployment with `support_users` populated
**Why the exam cares** — You must know the observability stack's division of labor — Monitoring (metrics, alerts, uptime checks, dashboards), Logging (Logs Explorer, log-based metrics, sinks), Trace/Profiler (latency and code-level analysis) — and design alerting that pages on symptoms with actionable thresholds.
**How RAD implements it**
| Capability | Implementation | Variables (defaults) |
|---|---|---|
| Notification channels | email channels per address | `support_users` (App modules), `configure_email_notification` + `notification_alert_emails` (Services_GCP) |
| Infrastructure alerts | Cloud SQL CPU/memory/disk and NFS-VM CPU/memory/instance-down policies provisioned by the platform | `alert_cpu_threshold` / `alert_memory_threshold` / `alert_disk_threshold` (all default `80`) |
| Application alerts | per-service policies filtered to the Cloud Run service | `alert_policies` list — `metric_type`, `comparison`, `threshold_value`, `duration_seconds`, `aggregation_period` (default `"60s"`) |
| Synthetic monitoring | `-uptime-check` (HTTP GET from multiple global probe regions) plus a `-uptime-check-alert` policy on `monitoring.googleapis.com/uptime_check/check_passed`, created by the platform's monitoring layer when the endpoint is publicly reachable; `uptime_check_names` outputs the real check name | `uptime_check_config` (default `{ enabled = false, path = "/" }`; `check_interval` default `"60s"`, `timeout` default `"10s"`) |
| Dashboards | per-deployment dashboard provisioned by the platform | App_CloudRun / App_GKE |
| GKE telemetry | system + workload logging, managed Prometheus | fixed defaults in Services_GCP |
**Try it**
1. In **Console > Monitoring > Alerting**, identify the platform policies (Cloud SQL CPU/memory/disk, NFS health) and your service's policies; open one and trace metric → threshold → channel.
2. Add a custom policy via the portal, e.g. `{ name = "high-latency", metric_type = "run.googleapis.com/request_latencies", comparison = "COMPARISON_GT", threshold_value = 1000, duration_seconds = 300 }`, and re-apply.
3. In **Console > Monitoring > Uptime checks**, open the module-created `-uptime-check` and watch the probe results arriving from multiple regions, then query recent application errors:
```bash
gcloud logging read \
'resource.type="cloud_run_revision" AND severity>=ERROR' \
--limit=10 --format="table(timestamp,severity,textPayload)"
```
4. You know it worked when your custom policy appears in Alerting wired to the `support_users` email channel, and the module-created uptime check shows passing probes from multiple regions.
**Check yourself**
Q1: Users report the app is down, but no alert fired — CPU and memory were normal. What monitoring gap exists in the default deployment, and what is the right kind of alert to close it?
A: A synthetic uptime check probing the endpoint from outside (the modules create one via `uptime_check_config` for publicly reachable deployments — internal-only deployments get none, so this gap appears whenever ingress is locked down). Resource metrics are *cause-based* and can look healthy while the user experience is broken (bad deploy, LB misconfig, dead dependency); an external probe is *symptom-based* — it measures what users experience, which SRE practice (and the exam) says to page on.
Q2: The DB team wants warning before the database degrades. Which three platform thresholds apply, and what tuning trade-off should you explain?
A: `alert_cpu_threshold`, `alert_memory_threshold`, `alert_disk_threshold` (each default `80`%) on the Cloud SQL instance. Lower thresholds buy lead time but raise false-positive load (alert fatigue); higher thresholds reduce noise but shrink reaction time. Durations (`duration_seconds`) suppress transient spikes — alert design is a precision/recall trade-off, not a single right number.
**Beyond the modules** — Not wired up: log sinks/exports to BigQuery, log-based metrics, SLO monitoring with burn-rate alerts, Cloud Trace, and Cloud Profiler. Practice creating a log-based metric and an SLO on a Cloud Run service in the Monitoring console — SLO/error-budget questions are frequent.
**⚠️ Exam trap** — Uptime checks need an externally reachable endpoint. If a scenario locks ingress down (e.g. internal-only), a public uptime check fails by design — the answer is private uptime checks or internal synthetic probes, not "the service is down." RAD encodes this: the foundation modules skip uptime check creation entirely when the deployment is not publicly reachable.
---
## 6.3 Deployment and release management
> ⏱ ~60 min · 💰 low · ⚙️ Requires: Security and delivery profile (Cloud Deploy + CI/CD)
**Why the exam cares** — Release management questions test rollout strategies (rolling, blue-green, canary), rollback speed, and environment promotion discipline — including keeping the data layer (schemas, secrets) compatible across a rollout.
**How RAD implements it** — Cloud Run retains prior revisions and prunes them to `max_revisions_to_retain` (default `7`), so rollback is re-pointing traffic, with `traffic_split` providing canary and blue-green percentages (validated to sum to 100). Cloud Deploy (`cloud_deploy_stages`, default `dev`/`staging`/`prod` with approval on `prod`) promotes one artifact through environments. On GKE, Deployments use rolling updates, StatefulSets use `stateful_update_strategy` (default `RollingUpdate`), and Cloud Deploy stages map to per-stage services selected by `gateway_backend_stage` (default `"dev"`) behind the Gateway. The data layer is covered too: secret rotation is dual-version (new version added, old disabled only after `rotation_propagation_delay_sec`, default `90`) so a rollout never races its credentials.
**Try it**
1. Deploy a new application version, then roll back without rebuilding:
```bash
gcloud run services update-traffic \
--region=us-central1 \
--to-revisions==100
```
2. Confirm in **Console > Cloud Run > Revisions** that traffic moved and the old revision still exists (pruning keeps 7).
3. On GKE, watch a rolling update: change the image/version in the portal and run `kubectl rollout status deployment/ -n `.
4. You know it worked when rollback took seconds (traffic shift) rather than minutes (rebuild + redeploy).
**Check yourself**
Q1: Why does revision pruning matter to release management — isn't keeping every revision safer?
A: Unbounded revisions accumulate cost (container images, config clutter) and make the rollback target ambiguous. Retaining a bounded window (7 here) keeps fast rollback to any recent version while forcing older states to be reproduced from source control — the artifact of record — rather than from stale runtime objects.
Q2: During a credential rotation mid-rollout, old pods still hold the previous password. Why doesn't this platform's rotation break them?
A: Rotation is dual-version: the rotator adds the *new* secret version and changes the database password, but disables the *old* version only after a propagation delay, so both credentials briefly remain valid while revisions/pods converge. Single-version rotation (overwrite-then-pray) is the outage pattern the exam wants you to avoid.
**⚠️ Exam trap** — Blue-green and canary differ in cost and blast radius: blue-green doubles capacity for an instant full cutover; canary exposes a small percentage gradually. `traffic_split` implements both shapes on Cloud Run — pick per the scenario's tolerance for risk vs spend.
---
## 6.4 Assisting with the support of deployed solutions
> ⏱ ~20 min reading · 💰 no additional cost · ⚙️ Requires: default deployment
**Why the exam cares** — Architects design the support model: who is notified, with what evidence, and when to escalate to Google Cloud Customer Care (Standard/Enhanced/Premium plans, TAM engagement for P1s).
**How RAD implements it** — Largely not implemented; the nearest adjacent capability is the notification plumbing: `support_users` feeds Cloud Monitoring email channels (one per address, via the platform's monitoring layer), so the on-call audience is part of the deployment definition, and every alert in 6.2 carries the metric evidence a support case needs.
**Try it**
1. Add a second address to `support_users` and re-apply; verify the new channel in **Console > Monitoring > Alerting > Notification channels**:
```bash
gcloud beta monitoring channels list --format="table(displayName,type,labels.email_address)"
```
2. You know it worked when the channel list matches the variable.
**Check yourself**
Q1: A customer running mission-critical production workloads asks which Google Cloud support plan they need for a 15-minute P1 response and a named technical contact. What do you recommend?
A: Premium Support — it provides the fastest P1 response SLO and Technical Account Manager engagement. Enhanced suits production workloads with less aggressive response needs; Standard is for non-critical workloads. Plan selection is an architectural recommendation, not an afterthought, in exam scenarios.
**Beyond the modules** — Study the Cloud Customer Care tiers and case-priority definitions (P1–P4), escalation paths, and how to package diagnostic evidence (logs, traces, monitoring snapshots). Browse **Console > Support** in any project to see the case workflow.
---
## 6.5 Evaluating quality control measures
> ⏱ ~45 min · 💰 low · ⚙️ Requires: `enable_vulnerability_scanning = true` (Services_GCP) and the Security and delivery profile
**Why the exam cares** — Quality control spans the delivery chain: static checks before apply, image scanning before deploy, admission enforcement at deploy, and posture monitoring after. The exam asks which control catches which defect class, and where in the pipeline it belongs.
**How RAD implements it** — The platform layers four quality gates. *Plan time*: `tofu validate` plus the modules' preconditions (32 in App_GKE alone) reject invalid configurations before any API call. *Build time*: `enable_vulnerability_scanning` enables Artifact Registry scanning (`enablement_config = INHERITED`), surfacing CVEs per image digest. *Deploy time*: Binary Authorization (`REQUIRE_ATTESTATION`) admits only pipeline-signed digests. *Run time*: GKE clusters enable `security_posture_config` (mode `BASIC`, `VULNERABILITY_BASIC`) for workload posture findings.
**Try it**
1. Push an intentionally dated base image through the pipeline, then review findings in **Console > Artifact Registry > (repo) > (image)** under Vulnerabilities, or:
```bash
gcloud artifacts docker images list \
-docker.pkg.dev/// \
--show-occurrences --occurrence-filter='kind="VULNERABILITY"'
```
2. Map each defect class to its gate: bad variable → plan precondition; CVE → AR scan; unsigned image → Binary Authorization; risky workload config → security posture.
3. You know it worked when the scan lists CVEs with severities for your image, and you can state which gate would have caught each of the three other defect classes.
**Check yourself**
Q1: Scanning found a critical CVE, yet the image deployed anyway. Why, and what closes the gap?
A: Scanning is *detective*, not *preventive* — it reports findings but blocks nothing. Closing the gap requires an enforcement point: Binary Authorization with an attestation granted only after a passing scan (e.g. the CI step attests only when no critical CVEs are present). The exam regularly contrasts visibility controls with enforcement controls.
Q2: Which is cheaper to catch: a malformed memory quota at plan time or at pod-scheduling time — and how does this platform decide?
A: Plan time. App_GKE validates that quota memory values carry binary unit suffixes (`"4Gi"`) precisely because a bare number is interpreted by Kubernetes as bytes and silently blocks *all* pod scheduling — a confusing runtime outage converted into an immediate, named plan error. Shifting defect detection left is the quality-control principle being tested.
**Beyond the modules** — Not present: automated test suites in CI (unit/integration), SAST/dependency scanning steps, Web Security Scanner, and policy-as-code on infrastructure plans (e.g. OPA/terraform-compliance). Study "Container scanning overview" and "Web Security Scanner" docs, and try adding a test step to a Cloud Build YAML in a scratch repo.
---
## 6.6 Ensuring the reliability of solutions in production
> ⏱ ~75 min · 💰 moderate — needs the GKE profile with ≥2 replicas · ⚙️ Requires: GKE architecture profile (`max_instance_count ≥ 2`), `enable_topology_spread = true`
**Why the exam cares** — Reliability engineering is mechanism selection: protect capacity during voluntary disruptions (PDBs), spread replicas across failure domains, gate traffic on health (probes), auto-heal infrastructure, and enforce production-grade tiers. The exam gives a failure narrative and asks which mechanism was missing.
**How RAD implements it**
| Failure mode | Mechanism | Variables (defaults) |
|---|---|---|
| Upgrade/drain evicts too many pods | PodDisruptionBudget | `enable_pod_disruption_budget` (default `true`), `pdb_min_available` (default `"1"`), skipped when `max_instance_count = 1` |
| All replicas land in one zone | topology spread across zone + hostname | `enable_topology_spread` (default `false`), `topology_spread_strict` |
| Traffic hits a booting container | startup probe (10 s delay/10 s period) and liveness probe (15 s delay/30 s period), HTTP or TCP | `startup_probe_config`, `health_check_config` (both engines) |
| NFS VM hangs | MIG auto-healing on TCP 2049/6379 health checks (300 s initial delay), PROACTIVE/REPLACE updates | `create_network_filesystem` (default `true`) |
| Production on a non-replicated cache | plan-time guardrail blocks `redis_tier = "BASIC"` when `resource_labels.environment = "production"` | Services_GCP |
| Demand exceeds capacity | HPA 70% CPU / 80% memory (GKE), instance scaling (Cloud Run) | `min_instance_count` / `max_instance_count` |
**Try it**
1. With ≥2 replicas, verify the PDB and then simulate a voluntary disruption:
```bash
kubectl get pdb -n
kubectl get pods -n -o wide # note the nodes
kubectl drain --ignore-daemonsets --delete-emptydir-data --dry-run=server
```
2. Enable `enable_topology_spread = true`, re-apply, and confirm pods land in different zones (`kubectl get pods -o wide` — compare node zones).
3. Break the liveness path deliberately (point `health_check_config.path` at a non-existent route in a test deployment) and watch pods restart in **Console > Kubernetes Engine > Workloads**.
4. You know it worked when the drain respects `minAvailable`, replicas span zones, and the bad health path produces restarts instead of silent traffic blackholing.
**Check yourself**
Q1: During a GKE node upgrade, a 3-replica service briefly dropped to zero healthy pods. Which two mechanisms from this platform were missing?
A: A PodDisruptionBudget (`minAvailable: 1` would have forced the drain to keep one pod serving) and topology spread (replicas concentrated on one node/zone all evict together). Defaults here provide the PDB automatically once `max_instance_count > 1`; spread must be opted into via `enable_topology_spread`.
Q2: A slow-starting JVM app gets killed in a restart loop on GKE. Which probe setting is wrong, and why are there two probes at all?
A: The startup probe window is too short — it must cover worst-case boot time before the liveness probe takes over. Startup probes answer "has it finished booting?" (failure = keep waiting, within limits); liveness probes answer "is it still healthy?" (failure = restart). Tuning liveness to tolerate slow boots instead of using a startup probe weakens failure detection for the entire pod lifetime.
Q3: Leadership asks for "five nines" on the self-managed NFS option. What honest answer does this architecture support?
A: It cannot deliver that: the NFS server is a single zonal VM — auto-healing and daily snapshots reduce MTTR but recovery still takes minutes, and a zone outage takes the share down. For higher availability you change architecture, not tuning: managed Filestore (or, beyond this platform, a regional/Enterprise file tier). Recognizing when an SLO requires an architectural change is core PCA material.
**Beyond the modules** — Not demonstrated: chaos engineering (fault injection), load testing at scale, multi-region failover with global traffic management, and formal SLO/error-budget operations. Study the SRE workbook's "Implementing SLOs," and practice a load test (e.g. `hey` or the distributed load-testing reference architecture) against a scratch deployment while watching the HPA respond.
**⚠️ Exam trap** — A PDB protects only against *voluntary* disruptions (drains, upgrades, autoscaler consolidation). Node crashes and zone outages ignore it entirely — those require replica count, topology spread, and multi-zone/multi-region design. "We had a PDB, why did the zone outage hurt us?" is exactly the confusion the exam probes.
---
# Professional Cloud Developer (PCD) Certification Lab Map
The Professional Cloud Developer certification validates your ability to design, build, test, deploy, and integrate scalable applications on Google Cloud — with a strong emphasis on Cloud Run, GKE, Cloud Build, Artifact Registry, Cloud Deploy, runtime secrets, service authentication, and observability. The RAD platform's four foundation modules (`Services_GCP`, `App_CloudRun`, `App_GKE`, `App_Common`) give you a live lab for exactly these skills: `Services_GCP` provisions the shared platform (VPC, Cloud SQL, Redis, GKE Autopilot, Artifact Registry, Binary Authorization, Workload Identity Federation), `App_CloudRun` and `App_GKE` are full-featured deployment engines for Cloud Run v2 services and Kubernetes workloads, and `App_Common` supplies the shared submodules they both use (secrets and rotation, Cloud Build container builds, Cloud Deploy pipelines, IAM, storage, monitoring). Application wrapper modules (Django, Wordpress, etc.) exist on the platform but everything in these guides uses the foundation modules directly.
## How to use this guide
- Deploy one of the profiles below through your deployment portal, then work through the matching section exploration guide.
- Every section guide pairs portal variables with the GCP console views and `gcloud`/`kubectl` commands the exam expects you to know.
- Use the coverage legend to plan study time: 🟡 and 📘 topics include a "Beyond the modules" block telling you what to practice outside the platform.
- PCD is a *developer* exam: when working through the labs, always ask "what would my application code see?" — the env vars, the secret refs, the socket paths, the tokens.
**Coverage legend**
| Symbol | Meaning |
|---|---|
| ✅ | Fully demonstrated — deploy it, see it, modify it in the RAD platform |
| 🟡 | Partially demonstrated — the modules touch the concept; supplement with docs |
| 📘 | Concept-only — not implemented by the modules; study pointers provided |
## Deployment profiles
### Profile: Serverless baseline
*Purpose:* a default Cloud Run v2 service with database, probes, and runtime secrets — the workhorse for Sections 1, 3.1, and 4.
*Modules:* `Services_GCP` (defaults), then `App_CloudRun`.
| Variable | Value |
|---|---|
| `create_postgres` (Services_GCP) | `true` (default) |
| `deploy_application` | `true` (default) |
| `min_instance_count` | `0` (default — scale to zero) |
| `max_instance_count` | `3` (raise from default `1` to observe scale-out) |
| `database_type` | `"POSTGRES"` (default) |
| `startup_probe_config` / `health_check_config` | defaults (HTTP `/healthz`) |
*Estimated incremental cost:* low — Cloud Run scales to zero; the dominant costs are the `db-custom-1-3840` Cloud SQL instance and the `e2-small` NFS VM that `Services_GCP` creates by default.
### Profile: Delivery pipeline
*Purpose:* GitHub-triggered Cloud Build (Kaniko) → Artifact Registry → Cloud Deploy progressive delivery with Binary Authorization attestation. Sections 2 and 3.1.
*Modules:* `Services_GCP` + `App_CloudRun`.
| Variable | Value |
|---|---|
| `enable_cicd_trigger` | `true` |
| `github_repository_url` | your repo URL |
| `enable_cloud_deploy` | `true` |
| `cicd_enable_cloud_deploy` | `true` |
| `cloud_deploy_stages` | default (`dev`, `staging`, `prod` with `require_approval = true` on prod) |
| `enable_binary_authorization` (both modules) | `true` |
| `binauthz_evaluation_mode` | `"REQUIRE_ATTESTATION"` |
| `enable_vulnerability_scanning` (Services_GCP) | `true` |
| `enable_workload_identity_federation` (Services_GCP) | `true` |
*Estimated incremental cost:* low/moderate — three per-stage Cloud Run services (all can scale to zero) plus Cloud Build minutes per push.
### Profile: Kubernetes lab
*Purpose:* GKE Autopilot deployment with Workload Identity, HPA, namespace governance, and the Secret Manager CSI add-on. Sections 1.1, 3.2, and 4.2.
*Modules:* `Services_GCP` with GKE enabled, then `App_GKE`.
| Variable | Value |
|---|---|
| `create_google_kubernetes_engine` (Services_GCP) | `true` |
| `gke_cluster_mode` (Services_GCP) | `"AUTOPILOT"` (default) |
| `min_instance_count` / `max_instance_count` (App_GKE) | `1` / `3` (defaults) |
| `enable_resource_quota` (App_GKE) | `true` |
| `enable_network_segmentation` (App_GKE) | `true` |
| `enable_pod_disruption_budget` (App_GKE) | `true` (default) |
*Estimated incremental cost:* moderate — Autopilot bills per pod resource request plus the cluster management fee; the default 1000m/512Mi pod is the dominant driver.
### Profile: Hardened edge
*Purpose:* IAP authentication, Cloud Armor WAF + global HTTPS load balancer, automatic secret rotation, and Memorystore caching. Sections 1.1, 1.2, and 4.1.
*Modules:* `Services_GCP` with Redis, then `App_CloudRun`.
| Variable | Value |
|---|---|
| `create_redis` (Services_GCP) | `true` |
| `redis_tier` (Services_GCP) | `"BASIC"` (default) |
| `enable_iap` | `true` (plus `iap_authorized_users`) |
| `enable_cloud_armor` | `true` (`application_domains` optional — a `nip.io` cert is derived when unset) |
| `application_domains` | a domain you control |
| `enable_auto_password_rotation` | `true` |
| `secret_rotation_period` | `"2592000s"` (default, 30 days) |
*Estimated incremental cost:* moderate — the global external Application Load Balancer forwarding rule and the 1 GB Memorystore instance bill continuously even when the Cloud Run service is idle. IAP alone (without Cloud Armor) adds no LB cost.
## Section 1: Designing highly scalable, available, and reliable cloud-native applications (~36% of the exam)
The largest section. The modules demonstrate platform selection (Cloud Run vs GKE), scaling behavior, revision-based traffic splitting, runtime secrets, IAP, Binary Authorization, and storage selection. API management products and application messaging are study-only.
| Exam topic | Coverage | Where in RAD | Guide |
|---|---|---|---|
| 1.1 Platform choice, scaling, cold starts | ✅ | `min_instance_count`, `max_instance_count`, `cpu_always_allocated`, `execution_environment` | [Section 1 guide](PCD_Section_1_Exploration_Guide.md#11-designing-high-performing-applications-and-apis) |
| 1.1 Traffic splitting, canary, rollback | ✅ | `traffic_split`, `max_revisions_to_retain` (App_CloudRun) | [Section 1 guide](PCD_Section_1_Exploration_Guide.md#11-designing-high-performing-applications-and-apis) |
| 1.1 Caching, CDN, session affinity | 🟡 | `create_redis`, `enable_redis`, `enable_cdn`; session affinity hardcoded on | [Section 1 guide](PCD_Section_1_Exploration_Guide.md#11-designing-high-performing-applications-and-apis) |
| 1.1 REST/gRPC APIs, API management, async messaging | 🟡 | `container_protocol = "h2c"` enables end-to-end HTTP/2 (gRPC-ready) on Cloud Run and `appProtocol kubernetes.io/h2c` on the GKE Service; API management and messaging are study-only | [Section 1 guide](PCD_Section_1_Exploration_Guide.md#11-designing-high-performing-applications-and-apis) |
| 1.2 Secrets at runtime + rotation | ✅ | `secret_environment_variables`, `enable_auto_password_rotation`, `secret_rotation_period` | [Section 1 guide](PCD_Section_1_Exploration_Guide.md#12-designing-secure-applications) |
| 1.2 End-user auth (IAP), supply-chain security | ✅ | `enable_iap`, `enable_binary_authorization`, `enable_vulnerability_scanning` | [Section 1 guide](PCD_Section_1_Exploration_Guide.md#12-designing-secure-applications) |
| 1.2 CMEK, audit logs, network segmentation | 🟡 | `enable_cmek`, `enable_audit_logging`, `enable_network_segmentation` | [Section 1 guide](PCD_Section_1_Exploration_Guide.md#12-designing-secure-applications) |
| 1.3 Relational/object/cache storage selection | ✅ | `create_postgres`, `create_mysql`, `storage_buckets`, `create_redis`, `enable_alloydb` | [Section 1 guide](PCD_Section_1_Exploration_Guide.md#13-storing-and-accessing-data) |
| 1.3 Firestore, Spanner, Bigtable, BigQuery, signed URLs | 📘 | `create_firestore` provisions the DB only — SDK usage is study-only | [Section 1 guide](PCD_Section_1_Exploration_Guide.md#13-storing-and-accessing-data) |
## Section 2: Building and testing applications (~23% of the exam)
The build pipeline is the strongest coverage in the repo: every deployment runs real Cloud Build jobs (Kaniko or Docker), pushes to Artifact Registry with cleanup policies, and can sign images for Binary Authorization. Local tooling and emulators are study-only.
| Exam topic | Coverage | Where in RAD | Guide |
|---|---|---|---|
| 2.1 Local dev environment, emulators, Cloud Code/Shell/Workstations | 📘 | nearest: per-tenant isolated deployments via `tenant_id` | [Section 2 guide](PCD_Section_2_Exploration_Guide.md#21-setting-up-your-development-environment) |
| 2.2 Cloud Build container builds | ✅ | `container_image_source = "custom"`, `container_build_config` | [Section 2 guide](PCD_Section_2_Exploration_Guide.md#22-building) |
| 2.2 Artifact Registry, image lifecycle, mirroring | ✅ | `max_images_to_retain`, `image_retention_days`, `delete_untagged_images`, Crane digest-aware mirroring | [Section 2 guide](PCD_Section_2_Exploration_Guide.md#22-building) |
| 2.2 CI triggers, Kaniko, attestation | ✅ | `enable_cicd_trigger`, `cicd_trigger_config`, Kaniko v1.23.2, pipeline image signing | [Section 2 guide](PCD_Section_2_Exploration_Guide.md#22-building) |
| 2.3 Unit/integration testing in CI | 🟡 | generated build pipeline is extensible; no test step ships by default | [Section 2 guide](PCD_Section_2_Exploration_Guide.md#23-testing) |
## Section 3: Deploying applications (~20% of the exam)
Both deployment targets are fully implemented. `App_CloudRun` covers revisions, scaling, probes, volumes, jobs, and Cloud Deploy promotion; `App_GKE` covers Deployments/StatefulSets, HPA/VPA, probes, quotas, PDBs, and the Gateway API.
| Exam topic | Coverage | Where in RAD | Guide |
|---|---|---|---|
| 3.1 Cloud Run service configuration (scaling, CPU, gen2, timeout) | ✅ | `min/max_instance_count`, `cpu_always_allocated`, `execution_environment`, `timeout_seconds` | [Section 3 guide](PCD_Section_3_Exploration_Guide.md#31-deploying-applications-to-cloud-run) |
| 3.1 Revisions, traffic management, rollback | ✅ | `traffic_split`, `max_revisions_to_retain` | [Section 3 guide](PCD_Section_3_Exploration_Guide.md#31-deploying-applications-to-cloud-run) |
| 3.1 Cloud Deploy progressive delivery | ✅ | `enable_cloud_deploy`, `cloud_deploy_stages`, `cicd_enable_cloud_deploy` | [Section 3 guide](PCD_Section_3_Exploration_Guide.md#31-deploying-applications-to-cloud-run) |
| 3.1 Cloud Run jobs (migrations, init) | ✅ | `initialization_jobs`, `cron_jobs` | [Section 3 guide](PCD_Section_3_Exploration_Guide.md#31-deploying-applications-to-cloud-run) |
| 3.2 GKE workloads, resources, probes | ✅ | `workload_type`, `container_resources`, `startup_probe_config`, `health_check_config` | [Section 3 guide](PCD_Section_3_Exploration_Guide.md#32-deploying-containers-to-gke) |
| 3.2 HPA/VPA, quotas, PDBs, exposure | ✅ | `min/max_instance_count`, `enable_vertical_pod_autoscaling`, `enable_resource_quota`, `enable_custom_domain` | [Section 3 guide](PCD_Section_3_Exploration_Guide.md#32-deploying-containers-to-gke) |
## Section 4: Integrating applications with Google Cloud services (~21% of the exam)
Database connectivity (Cloud SQL Auth Proxy on both platforms), runtime configuration injection, Workload Identity, and alerting are demonstrated live. Client-library coding, tracing, and profiling are study-only.
| Exam topic | Coverage | Where in RAD | Guide |
|---|---|---|---|
| 4.1 Cloud SQL connectivity (sockets, sidecar proxy) | ✅ | `enable_cloudsql_volume`, `cloudsql_volume_mount_path`, GKE proxy sidecar | [Section 4 guide](PCD_Section_4_Exploration_Guide.md#41-integrating-applications-with-data-and-storage-services) |
| 4.1 Storage integration (GCS Fuse, NFS, Redis) | ✅ | `gcs_volumes`, `enable_nfs`, `enable_redis` | [Section 4 guide](PCD_Section_4_Exploration_Guide.md#41-integrating-applications-with-data-and-storage-services) |
| 4.1 Pub/Sub & Firestore application code | 📘 | only rotation/SCC topics exist — no app messaging | [Section 4 guide](PCD_Section_4_Exploration_Guide.md#41-integrating-applications-with-data-and-storage-services) |
| 4.2 Service accounts, ADC, Workload Identity | ✅ | per-app SAs, KSA annotation `iam.gke.io/gcp-service-account`, `additional_cloudrun_sa_roles` | [Section 4 guide](PCD_Section_4_Exploration_Guide.md#42-consuming-google-cloud-apis) |
| 4.2 Workload Identity Federation (keyless CI) | ✅ | `enable_workload_identity_federation`, `wif_provider_type` | [Section 4 guide](PCD_Section_4_Exploration_Guide.md#42-consuming-google-cloud-apis) |
| 4.2 Service-to-service auth (ID tokens) | 🟡 | `roles/run.invoker` bindings (IAP agent, allUsers); calling code is study-only | [Section 4 guide](PCD_Section_4_Exploration_Guide.md#42-consuming-google-cloud-apis) |
| 4.3 Logging, metrics, alerting, dashboards | ✅ | `support_users`, `alert_policies` (the platform's monitoring and dashboard layers) | [Section 4 guide](PCD_Section_4_Exploration_Guide.md#43-troubleshooting-and-observability) |
| 4.3 Uptime checks | ✅ | `uptime_check_config` creates a `-uptime-check` + alert policy on publicly reachable endpoints | [Section 4 guide](PCD_Section_4_Exploration_Guide.md#43-troubleshooting-and-observability) |
| 4.3 Trace, Profiler, Error Reporting | 📘 | not implemented — study-only | [Section 4 guide](PCD_Section_4_Exploration_Guide.md#43-troubleshooting-and-observability) |
---
# PCD Certification Preparation Guide: Section 1 — Designing highly scalable, available, and reliable cloud-native applications (~36% of the exam)
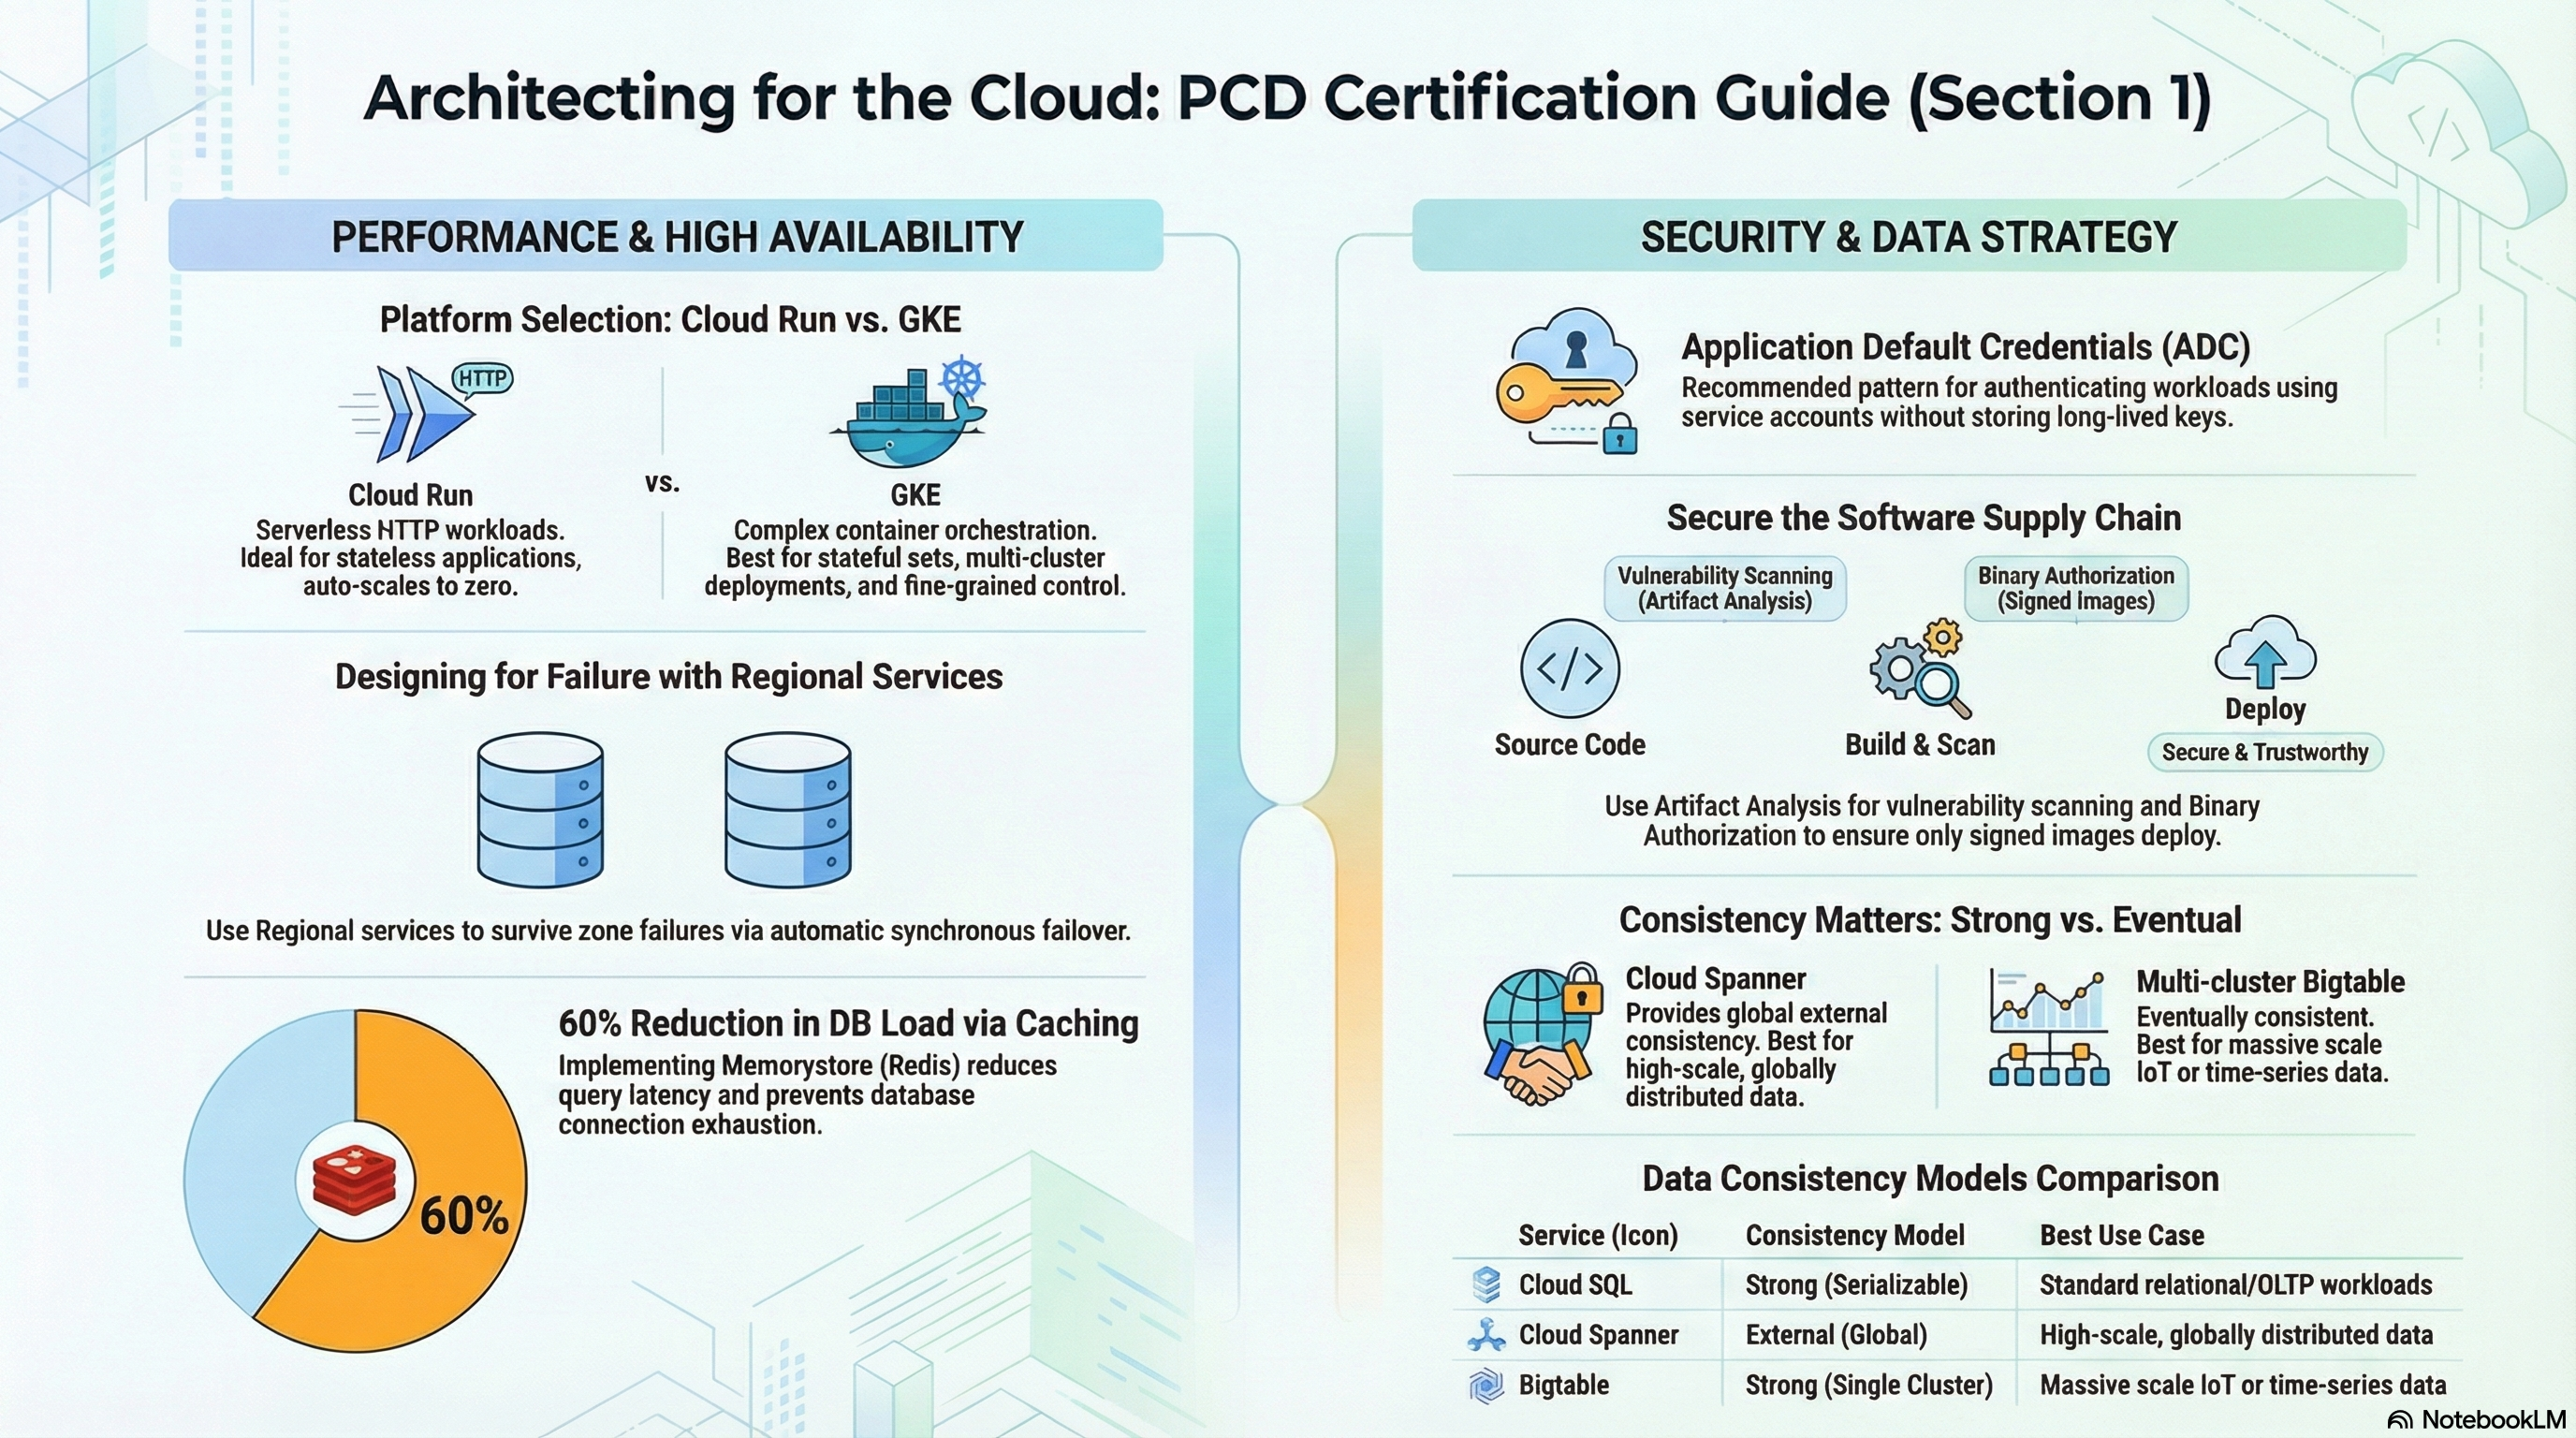 This guide covers the largest PCD exam section using the RAD platform foundation modules. You will exercise `App_CloudRun` (Cloud Run v2 service design), `App_GKE` (Kubernetes workload design), and `Services_GCP` (the shared database, cache, and security infrastructure). Deploy the **Serverless baseline** profile from the [Lab Map](PCD_Certification_Guide.md) before starting; add the **Hardened edge** profile for 1.1 (caching/CDN) and 1.2 (IAP, rotation).
---
## 1.1 Designing high-performing applications and APIs
> ⏱ ~90 min · 💰 low (scale-to-zero defaults); Memorystore and the global LB bill continuously if enabled · ⚙️ Requires: Serverless baseline; Hardened edge for CDN/Redis steps
**Why the exam cares** — PCD scenarios constantly ask you to pick between Cloud Run and GKE, and to tune the chosen platform: when does `min_instances > 0` beat accepting cold starts, when is CPU throttling between requests acceptable, how do you canary a new revision without redeploying, and where does a cache or CDN belong in the request path. The decision criteria are cost vs latency vs operational control: Cloud Run for stateless request/response workloads with bursty traffic, GKE for workloads needing sidecars you control, StatefulSets, or fine-grained pod networking.
**How RAD implements it** — Both foundation modules expose the same scaling vocabulary with platform-appropriate defaults:
| Variable | App_CloudRun default | App_GKE default | What it controls |
|---|---|---|---|
| `min_instance_count` | `0` (scale to zero) | `1` | scaling floor / HPA `minReplicas` |
| `max_instance_count` | `1` | `3` | scaling ceiling / HPA `maxReplicas` |
| `container_resources` | `cpu_limit = "1000m"`, `memory_limit = "512Mi"` | same | per-instance/pod resources |
| `timeout_seconds` | `300` (0–3600) | `300` | request / LB backend timeout |
Cloud Run-specific performance levers:
- `cpu_always_allocated` (default `false`, i.e. request-based billing) — set `true` to keep CPU allocated between requests (schedulers, queue workers, WebSocket servers). Startup CPU boost is always on, and session affinity is always on for the service. NOTE: line 59 of the same file ("keep `cpu_always_allocated = true`") is phrased as an override and stays correct only if reworded from "keep" to "set".
- `execution_environment` (default `"gen2"`) — plan-time validations require gen2 for NFS (`enable_nfs`) and GCS Fuse (`gcs_volumes`) mounts.
- `traffic_split` (default `[]` = 100% to latest) takes a list of `{ type, revision, percent, tag }` entries where `type` is `TRAFFIC_TARGET_ALLOCATION_TYPE_LATEST` or `TRAFFIC_TARGET_ALLOCATION_TYPE_REVISION`; validation enforces that percents sum to exactly 100. The optional `tag` gives a revision a stable preview URL.
- `max_revisions_to_retain` (default `7`) prunes old revisions automatically; revisions serving traffic are never deleted.
- Request concurrency per instance is **not** exposed — the service uses the Cloud Run default (80 concurrent requests per instance).
- `container_protocol` (default `"http1"`) sets the named port on the Cloud Run service: `"h2c"` switches Cloud Run to end-to-end HTTP/2 cleartext — required for gRPC services (gRPC is built on HTTP/2) and useful for streaming/large-payload workloads. The container must serve cleartext HTTP/2 on the container port. On GKE the same variable advertises `appProtocol kubernetes.io/h2c` on the Service port so Gateway/Ingress backends speak HTTP/2 to the pods.
On GKE, the platform creates a HorizontalPodAutoscaler only when `max_instance_count > 1` **and** `enable_vertical_pod_autoscaling = false`, targeting 70% CPU and 80% memory utilization.
Caching: `Services_GCP` provisions Memorystore with `create_redis` (default `false`), `redis_tier` (default `BASIC` vs `STANDARD_HA`), `redis_memory_size_gb` (default `1`), AUTH enabled. On the app side, `enable_redis` (App_CloudRun default `true`) injects `REDIS_HOST`/`REDIS_PORT` (and `REDIS_URL` when derivable) env vars — set `redis_host` to the Memorystore IP, otherwise the module falls back to the shared NFS VM's Redis. CDN: `enable_cdn` (default `false`) forces the service behind a global external Application Load Balancer (ingress is auto-overridden to `internal-and-cloud-load-balancing`).
**Try it**
1. In the portal, set `max_instance_count = 3` and redeploy. In **Console > Cloud Run > your service > Revisions**, note a new revision was created — configuration changes always create revisions.
2. Deploy a trivial change (e.g., a new `environment_variables` entry), then set `traffic_split` to send 10% to the new revision:
```bash
gcloud run revisions list --service= --region=us-central1
gcloud run services update-traffic --region=us-central1 \
--to-revisions==90,=10
gcloud run services describe --region=us-central1 \
--format="yaml(status.traffic)"
```
(Doing it via the `traffic_split` variable keeps Terraform state authoritative; the CLI is what the exam tests.)
3. Flip `cpu_always_allocated = false`, apply, and inspect the revision: **Console > Cloud Run > service > Revisions > Containers tab** shows "CPU is only allocated during request processing".
4. Generate load (`hey` or a loop of `curl`) and watch **Cloud Run > service > Metrics > Container instance count** climb toward 3 and fall back to 0.
5. You know it worked when the traffic chart on the Revisions tab shows the 90/10 split and instance count returns to zero after load stops.
**Check yourself**
Q1: A latency-sensitive API on Cloud Run shows 4-second p99 spikes after idle periods. Which two settings fix this, and what is the cost trade-off?
A: Set `min_instance_count >= 1` to keep a warm instance (eliminates cold starts, bills the idle instance continuously) and keep `cpu_always_allocated = true` so background initialization isn't throttled between requests. The trade-off is paying for instance time even with zero traffic — the opposite of the scale-to-zero default.
Q2: You must roll out a risky change to 5% of users with instant rollback. How do you do it on Cloud Run without a load balancer?
A: Deploy the change as a new revision and use revision-based traffic splitting (`traffic_split` / `gcloud run services update-traffic`) to send 5% to it, optionally with a `tag` for a direct test URL. Rollback is routing 100% back to the previous revision — no rebuild or redeploy, because revisions are immutable.
Q3: When would you choose App_GKE over App_CloudRun for the same container?
A: When the workload needs stable per-pod storage (StatefulSet via `stateful_pvc_enabled`), Kubernetes-native controls (NetworkPolicy, ResourceQuota, PDB, topology spread), long-lived non-HTTP protocols, or sidecars you define yourself. Cloud Run wins for bursty stateless HTTP because of scale-to-zero and per-request billing.
**Beyond the modules** — The exam also tests API design and async patterns the modules don't implement: REST versioning and OpenAPI specs behind **API Gateway** or **Apigee** (try `gcloud api-gateway gateways list` in a scratch project), gRPC application code (the platform side is covered — `container_protocol = "h2c"` is the module equivalent of `gcloud run deploy --use-http2` — but writing the gRPC service/client is study-only), **Pub/Sub** publish/subscribe and push-vs-pull decisions, **Cloud Tasks** for rate-limited dispatch, **Workflows** for multi-step orchestration, and **Eventarc** triggers (the modules use Eventarc only internally for secret rotation). Also study Cloud Run concurrency tuning (`--concurrency`) since the modules pin the default of 80.
**⚠️ Exam trap** — "Min instances = 0" plus "CPU always allocated" is a contradiction candidates miss: with `min_instance_count = 0` you still pay full instance time while instances exist if CPU is always allocated. Scale-to-zero only saves money between requests if instances actually terminate.
---
## 1.2 Designing secure applications
> ⏱ ~75 min · 💰 low (Secret Manager pennies; KMS keys ~$0.06/key/month; IAP free) · ⚙️ Requires: Hardened edge profile (`enable_iap`, `enable_auto_password_rotation`); add `enable_binary_authorization` on both modules
**Why the exam cares** — PCD security questions are about *where credentials live and who can call what*: secrets must reach code at runtime (never baked into images or state), end-user authentication should happen before traffic reaches the app (IAP), and only provably-built images should run (Binary Authorization). You're expected to know which mechanism solves which problem, not to administer the org.
**How RAD implements it** —
*Secrets at runtime.* `secret_environment_variables` (map of env var name → Secret Manager secret name) is rendered on the Cloud Run service as a secret reference pinned to the `latest` version — the plaintext never enters Terraform state or the image. The database password is auto-generated (`database_password_length`, default 32 in App_CloudRun) and stored in Secret Manager by the platform's secrets layer. On GKE, secrets arrive through the Secret Manager add-on: the platform creates a `SecretProviderClass` (provider `gke`) that syncs Secret Manager secrets into a Kubernetes Secret which pods consume via `secretKeyRef` — the add-on itself (`secret-manager+secret-sync-v1`) is enabled on the cluster via gcloud.
*Rotation.* `secret_rotation_period` (default `"2592000s"` = 30 days) configures the Secret Manager rotation notification. On its own it only publishes to Pub/Sub; `enable_auto_password_rotation` (default `false`) closes the loop: an Eventarc trigger fires a dispatcher Cloud Run service which runs a rotator Cloud Run job. The rotation logic is dual-version and zero-downtime: `ALTER USER` first, add the new secret version, wait `rotation_propagation_delay_sec` (default `90`), then *disable* (not destroy) the old version so `latest` is unambiguous and rollback stays possible.
*IAP.* `enable_iap` (default `false`) turns on IAP for the Cloud Run v2 service (launch stage BETA). A plan-time validation requires at least one entry in `iap_authorized_users` or `iap_authorized_groups`; the platform grants `roles/run.invoker` to the IAP service agent and `roles/iap.httpsResourceAccessor` to your principals. Without IAP, public services get an `allUsers` → `roles/run.invoker` binding. On GKE, IAP additionally requires `iap_oauth_client_id`, `iap_oauth_client_secret`, and `iap_support_email`.
*Supply chain.* `enable_binary_authorization` with `binauthz_evaluation_mode` (default `"ALWAYS_ALLOW"`, options include `REQUIRE_ATTESTATION` and `ALWAYS_DENY`) creates a KMS-backed attestor; the CI pipeline signs images (see Section 2). `enable_vulnerability_scanning` (Services_GCP, default `false`) turns on Artifact Analysis scanning for the shared repository.
*Edge protection.* `enable_cloud_armor` (default `false`) deploys a WAF policy (`{service}-waf-policy`) with preconfigured OWASP rules (SQLi/XSS/LFI/RCE), Adaptive Protection, and a 500 req/min/IP rate limit behind a global HTTPS LB. **`application_domains` is optional** — with none set, the module derives a zero-config `.nip.io` Google-managed certificate so the LB always has a hostname. The live constraint runs the *other* way: `enable_cdn = true` requires `enable_cloud_armor = true`, because the CDN attaches to the load balancer Cloud Armor provisions. Hardening extras: `enable_cmek` (Services_GCP, default `false`) for customer-managed keys with `cmek_key_rotation_period` default `7776000s` (90 days), `enable_audit_logging` (default `false`) for DATA_READ/DATA_WRITE audit logs, and `enable_network_segmentation` (App_GKE, default `false`) for namespace-scoped NetworkPolicies.
**Try it**
1. Add a custom secret: create `MY_API_KEY` in **Console > Security > Secret Manager**, then set `secret_environment_variables = { MY_API_KEY = "" }` and redeploy. Verify in **Cloud Run > service > Revisions > Variables & Secrets** that it shows "Secret reference", not a value.
2. Enable rotation (`enable_auto_password_rotation = true`) and inspect the moving parts:
```bash
gcloud secrets list --filter="name~rotation OR name~password"
gcloud secrets versions list
gcloud eventarc triggers list --location=us-central1
gcloud run jobs list --region=us-central1 # look for the rotator job
```
3. Enable IAP with your user in `iap_authorized_users`, then prove the boundary:
```bash
curl -s -o /dev/null -w "%{http_code}\n" https:/// # 302/403 anonymous
curl -s -o /dev/null -w "%{http_code}\n" \
-H "Authorization: Bearer $(gcloud auth print-identity-token)" https:///
```
4. You know it worked when the secret version list shows a new ENABLED version and a DISABLED prior version after a rotation fires, and anonymous requests stop returning 200 once IAP is on.
**Check yourself**
Q1: Your app reads DB_PASSWORD from an env var sourced from Secret Manager with version "latest". A rotation writes a new version while 20 instances are running. What happens, and how does the RAD design avoid an outage?
A: Running instances keep the value they resolved at startup — env-var secret references resolve when the instance starts, not per request. The rotator avoids breakage by being dual-version: the database accepts the new password (`ALTER USER`) before the new secret version is published, the old secret version is only disabled after a propagation delay, and the workload is restarted so new instances pick up "latest". An exam answer should mention that env-var secrets require a new revision/restart to refresh.
Q2: A team must guarantee only images built by their CI pipeline run in production. Which two RAD variables implement this, and what happens to a hand-pushed image?
A: `enable_binary_authorization = true` plus `binauthz_evaluation_mode = "REQUIRE_ATTESTATION"`. The CI pipeline signs each image with the KMS-backed attestor after building; a locally built image pushed straight to Artifact Registry has no attestation, so admission is denied at deploy time (enforcement is block-and-audit-log).
Q3: You enable `enable_cloud_armor = true` without setting `application_domains`. What happens?
A: It deploys successfully. The module auto-provisions a zero-config `.nip.io` Google-managed SSL certificate (`security.tf`, `use_nip_io` / `nip_io_cert`), so the Global HTTPS Load Balancer always has a hostname to bind to. A domain is optional, not required.
The validation that once required a domain here was **removed** — `App_CloudRun/validation.tf` keeps it only as comment 19, "(removed) Cloud Armor no longer requires a custom domain."
The constraint that *does* exist runs the other way: **`enable_cdn = true` requires `enable_cloud_armor = true`** (precondition 26). Cloud CDN attaches to the Global HTTPS Load Balancer that Cloud Armor provisions; without it there is no backend to attach the CDN to.
**Beyond the modules** — Study Identity Platform (end-user/CIAM auth — the modules only do IAP for Google identities), OAuth 2.0/OIDC token flows and the difference between access tokens and ID tokens, signed URLs vs IAM for object access, and Web Security Scanner. VPC Service Controls exist in the modules (`enable_vpc_sc`, dry-run by default, with graceful permission-probe skips) but perimeter design questions go deeper — read the VPC-SC ingress/egress rules documentation.
**⚠️ Exam trap** — `secret_rotation_period` alone rotates nothing. It only schedules a Pub/Sub *notification*. Something must consume that notification and write a new version — in RAD that's `enable_auto_password_rotation`; on the exam it's "a rotation function/job you implement".
---
## 1.3 Storing and accessing data
> ⏱ ~60 min · 💰 moderate — Cloud SQL `db-custom-1-3840` is the dominant baseline cost; REGIONAL roughly doubles it; Filestore `BASIC_HDD` 1 TiB is significant · ⚙️ Requires: Serverless baseline (Postgres is on by default)
**Why the exam cares** — Storage-selection questions give you data shape, consistency, and scale requirements and expect the right product: relational OLTP → Cloud SQL/AlloyDB, documents with mobile sync → Firestore, petabyte wide-column/time-series → Bigtable, global relational → Spanner, blobs → Cloud Storage, hot ephemeral → Memorystore. PCD adds the developer angle: how does code *connect* to each (covered in 4.1), and what consistency does it observe.
**How RAD implements it** — `Services_GCP` provisions the menu; the app modules consume it:
| Variable (Services_GCP) | Default | What you get |
|---|---|---|
| `create_postgres` | `true` | Cloud SQL Postgres (`postgres_database_version` default `POSTGRES_17`), private IP only, SSL `ENCRYPTED_ONLY`, PITR with 7-day log retention, 7 daily backups |
| `postgres_database_availability_type` | `ZONAL` | set `REGIONAL` for an HA standby with automatic failover |
| `create_postgres_read_replica` | `false` | read replica(s) (`postgres_read_replica_count` default `1`) for read scaling |
| `create_mysql` | `false` | MySQL (`MYSQL_8_4`), binlog-based recovery (no PITR config) |
| `enable_alloydb` | `false` | AlloyDB cluster + primary; `enable_alloydb_read_pool` adds a read pool |
| `create_firestore` | `false` | Firestore Native (Enterprise edition) database — provisioning only |
| `create_redis` | `false` | Memorystore Redis; persistence `redis_persistence_mode` default `DISABLED` |
| `create_filestore_nfs` | `false` | Filestore (`filestore_tier` default `BASIC_HDD`, `filestore_capacity_gb` default `1024`) |
| `create_network_filesystem` | `true` | self-managed e2-small NFS+Redis VM with stateful disk and daily snapshots |
Object storage lives in the app modules: `storage_buckets` (a list of bucket definitions handled by the platform's object-storage layer) creates GCS buckets with versioning, lifecycle rules (age, newer-version counts, storage-class transitions), CORS, per-bucket `public_access_prevention`, and least-privilege IAM (`roles/storage.objectAdmin` granted per bucket to the app SA). `gcs_volumes` mounts buckets into the container via GCS Fuse (gen2 required), so code can use plain filesystem calls.
Consistency facts to anchor: Cloud SQL is strongly consistent on the primary; read replicas lag asynchronously. The RAD Postgres instance enables PITR (restore to a timestamp) *in addition to* daily backups — these are different exam answers. Redis `BASIC` tier has no replication and loses data on restart unless RDB/AOF persistence is enabled; the module even enforces at plan time that a production STANDARD_HA instance must not have persistence `DISABLED`.
**Try it**
1. Inspect the database the baseline profile created:
```bash
gcloud sql instances describe \
--format="yaml(settings.availabilityType, settings.backupConfiguration, ipAddresses)"
```
Confirm `availabilityType: ZONAL`, `pointInTimeRecoveryEnabled: true`, and that there is no public IP.
2. Set `postgres_database_availability_type = "REGIONAL"` in the portal and re-apply; the describe output now shows a secondary zone. (This restarts the instance — do it in a lab window.)
3. Add a bucket via `storage_buckets` with a lifecycle rule, then verify:
```bash
gcloud storage buckets describe gs:// \
--format="yaml(lifecycle_config, versioning, public_access_prevention)"
```
4. You know it worked when the bucket shows your lifecycle rule and `versioning: enabled`, and the SQL instance reports REGIONAL with a failover replica zone.
**Check yourself**
Q1: An app needs to survive a zone outage with zero data loss on its relational store. Daily backups are already enabled. What change is required and why aren't backups enough?
A: Set `postgres_database_availability_type = "REGIONAL"` — synchronous replication to a standby in another zone gives automatic failover with no data loss. Backups (and even PITR) are recovery mechanisms with restore time and potential data loss back to the last transaction logs; they don't provide availability.
Q2: A product catalog is read 50:1 vs writes and the Cloud SQL primary is CPU-saturated. Rank the RAD options.
A: First add Memorystore caching (`create_redis = true` + app-side `enable_redis`) — it removes repeated reads entirely and is cheapest. Second, `create_postgres_read_replica = true` to offload remaining reads (code must route reads to the replica and tolerate replication lag). Vertical scaling (`postgres_tier`) is the fallback because it has a ceiling and scales cost linearly.
Q3: Why might a developer choose `gcs_volumes` (GCS Fuse) over the Cloud Storage client library?
A: Fuse lets unmodified code use filesystem semantics (good for legacy apps, ML model files, static assets at startup) at the cost of object-storage performance characteristics and POSIX edge cases. The client library is the right answer for high-throughput object I/O, signed URLs, and metadata operations. Fuse requires `execution_environment = "gen2"` on Cloud Run — validated at plan time.
**Beyond the modules** — Spanner (interleaved tables, avoiding hotspotting primary keys), Bigtable (row-key design, single-index model, eventual consistency across replicated clusters), BigQuery write paths (Storage Write API vs batch loads), and signed URL generation (`blob.generate_signed_url`, requires `roles/iam.serviceAccountTokenCreator` or a key) are all absent from the modules and all examined. The Firestore database can be created here (`create_firestore = true`) but SDK usage — documents, composite indexes, real-time listeners, transactions — must be practiced with the client libraries or the emulator.
**⚠️ Exam trap** — Backups ≠ PITR. Daily backups restore to a snapshot moment; PITR replays transaction logs to an arbitrary timestamp. The RAD Postgres instance has both; the RAD MySQL instance relies on binary logging and has no PITR configuration — a distinction the exam loves.
---
# PCD Certification Preparation Guide: Section 2 — Building and testing applications (~23% of the exam)
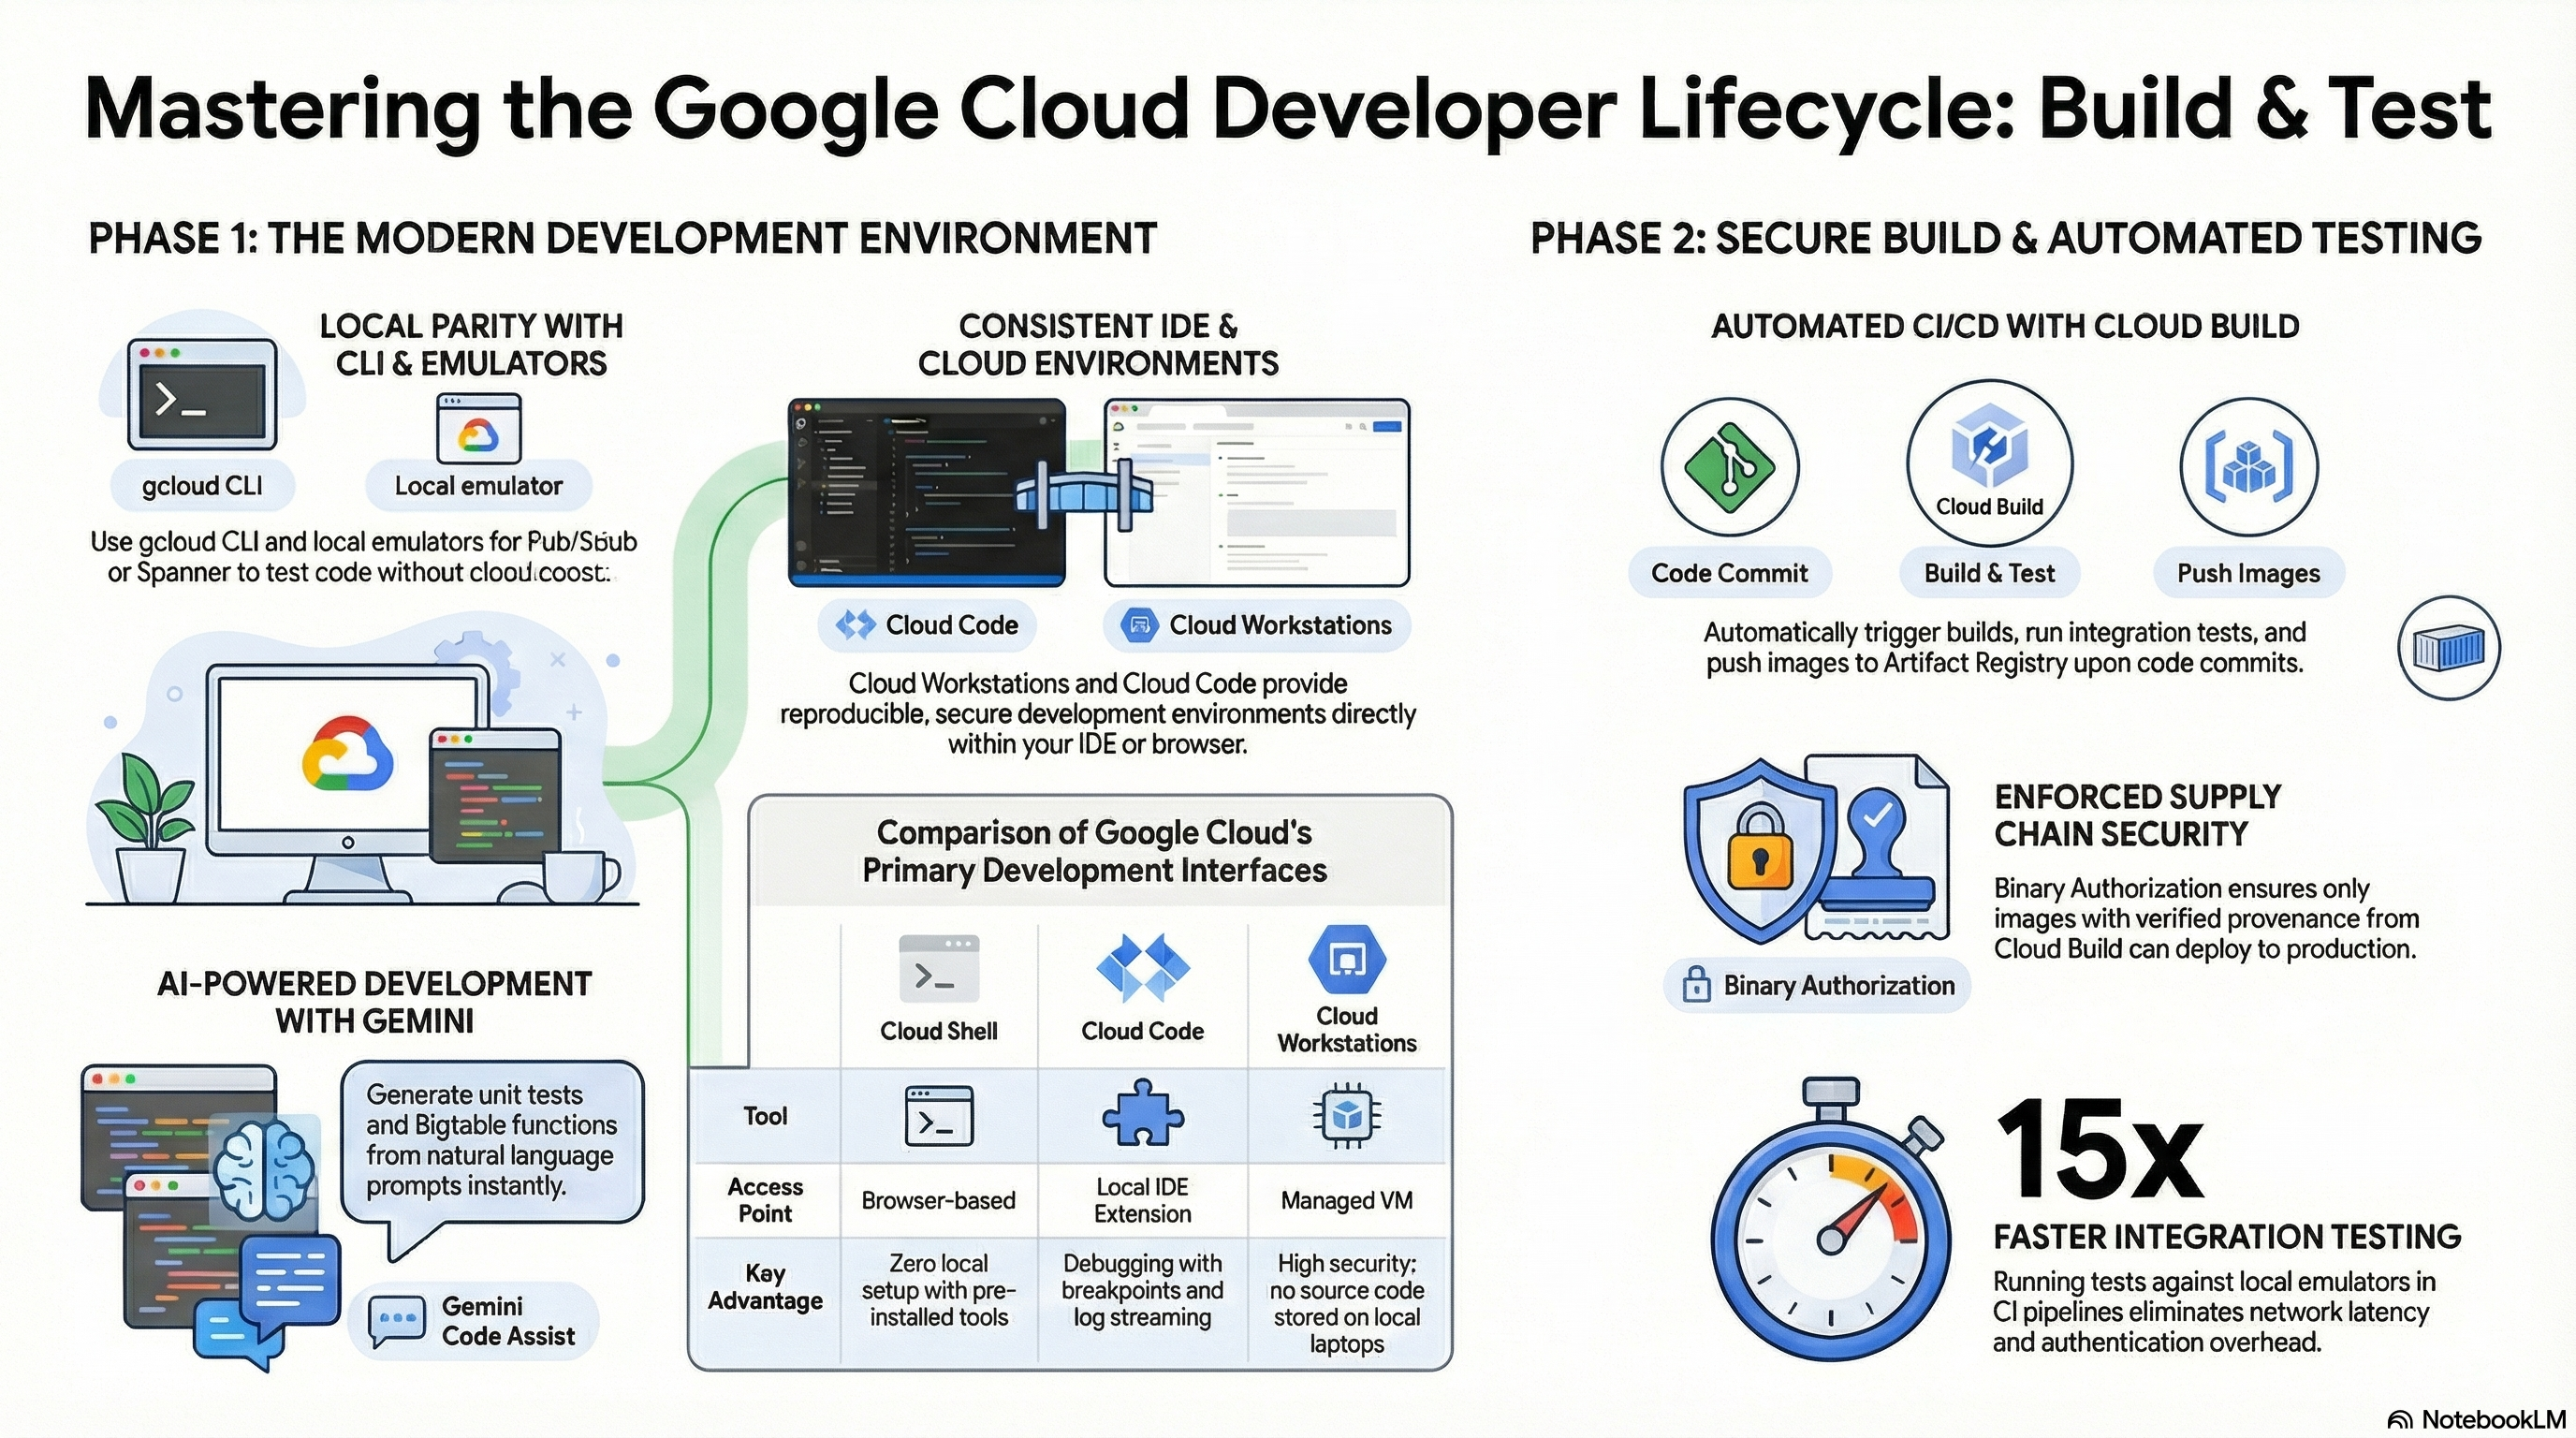 > 📚 **Official exam guide:** [Professional Cloud Developer certification](https://cloud.google.com/learn/certification/cloud-developer) — always confirm section weightings against the current Google Cloud exam guide.
This section maps to the RAD platform's build machinery: the platform's Cloud Build container builds, the Cloud Build CI trigger (present in both App_CloudRun and App_GKE), Artifact Registry management, and image mirroring. Deploy the **Delivery pipeline** profile from the [Lab Map](PCD_Certification_Guide.md). Local development tooling (2.1) and test authoring (2.3) are mostly study-only — honest pointers are given.
---
## 2.1 Setting up your development environment
> ⏱ ~45 min (mostly outside the platform) · 💰 no additional cost · ⚙️ Requires: any deployed profile + a workstation or Cloud Shell
**Why the exam cares** — The exam tests whether you know the developer toolchain: `gcloud` auth flows (user credentials vs Application Default Credentials), local emulators for unit testing without cloud cost, Cloud Code/Cloud Shell/Cloud Workstations trade-offs, and how to reproduce a cloud environment locally (e.g., Cloud SQL Auth Proxy on your laptop).
**How RAD implements it** — Not directly: the foundation modules run server-side and assume the portal performs the deploy. The nearest adjacent capabilities are real and useful, though:
- **Isolated per-developer environments.** `tenant_id` feeds the deterministic naming scheme (`app<8-hex-hash>`), so each developer can deploy a complete, non-colliding copy of the same application into a shared project — the cloud-native answer to "works on my machine".
- **Database tooling image.** The platform builds a psql/mysql client image into Artifact Registry, which the modules' jobs use; you can run the same image locally for parity.
- **Local DB access pattern.** Cloud SQL has private IP only, so the local equivalent of the deployed setup is running the Cloud SQL Auth Proxy yourself from a machine with VPC access (or via IAP tunneling) — the same binary the GKE module runs as a sidecar.
**Try it**
1. Deploy a second copy of `App_CloudRun` with a different `tenant_id` and confirm both stacks coexist:
```bash
gcloud run services list --region=us-central1
gcloud sql databases list --instance=
```
2. Set up ADC locally the way the exam expects developer machines to authenticate:
```bash
gcloud auth application-default login
gcloud config set project
```
3. Start a Pub/Sub emulator and point a test at it (no RAD involvement — this is the exam skill):
```bash
gcloud beta emulators pubsub start --project=test-project &
export PUBSUB_EMULATOR_HOST=localhost:8085
```
4. You know it worked when `gcloud run services list` shows two services with different tenant suffixes, and your local client library calls hit the emulator (no credentials needed).
**Check yourself**
Q1: A developer's laptop code calls `storage.Client()` and gets a 403 in the office but works on Cloud Run. Why, and what's the fix?
A: On Cloud Run the client library resolves Application Default Credentials from the metadata server (the service's service account). Locally there are no ambient credentials until the developer runs `gcloud auth application-default login` (or sets `GOOGLE_APPLICATION_CREDENTIALS` — discouraged because key files are long-lived). The fix is establishing local ADC; the code itself shouldn't change.
Q2: Your CI unit tests must exercise Pub/Sub and Firestore logic without network access or cost. What do you use?
A: The local emulators (`gcloud beta emulators pubsub start`, the Firestore emulator) with the `PUBSUB_EMULATOR_HOST` / `FIRESTORE_EMULATOR_HOST` environment variables set so client libraries transparently target them. Emulators need no credentials, which is exactly what hermetic CI wants.
**Beyond the modules** — Study Cloud Code (IDE deploy/debug for Cloud Run and GKE, including a local Cloud Run emulator), Cloud Shell (ephemeral, pre-authenticated, 5 GB persistent home), and Cloud Workstations (managed, persistent, IAP-fronted dev VMs for regulated teams) — know which to recommend for a given constraint. Also practice `gcloud run deploy --source .` (Buildpacks-based source deploy) since the RAD pipeline always builds an explicit container instead.
**⚠️ Exam trap** — `gcloud auth login` and `gcloud auth application-default login` are different credentials: the first authorizes the `gcloud` CLI, the second writes the ADC file client libraries read. Tests that pass for CLI commands but 401 in code usually mean the second was skipped.
---
## 2.2 Building
> ⏱ ~75 min · 💰 low — Cloud Build per-minute billing plus Artifact Registry storage · ⚙️ Requires: Delivery pipeline profile (`enable_cicd_trigger = true`, `github_repository_url` set)
**Why the exam cares** — PCD expects fluency in the container supply chain: building images in Cloud Build (and why a daemonless builder like Kaniko or Buildpacks beats `docker build` in CI), tagging strategy (mutable `latest` vs immutable commit-SHA tags), Artifact Registry storage and cleanup, and attaching provenance (attestations) so Binary Authorization can gate deploys.
**How RAD implements it** — Two distinct build paths, both real Cloud Build:
1. **Terraform-driven build** (every deploy with `container_image_source = "custom"`, the default): the platform renders a build config and runs `gcloud builds submit`. Kaniko builds with layer caching (`--cache=true`, `--cache-ttl=24h`) and pushes three tags: the app version, `latest`, and the commit SHA. Rebuilds are *hash-triggered*: the platform hashes the build context files, the Dockerfile (or inline `dockerfile_content`), and `build_args`, so an unchanged source tree never rebuilds.
2. **Git-driven CI trigger** (`enable_cicd_trigger`, default `false`): the platform creates a Cloud Build trigger bound to `github_repository_url`, filtered by `cicd_trigger_config` (`branch_pattern` default `"^main$"`, plus `included_files`/`ignored_files`/`substitutions`). The generated pipeline runs Kaniko `v1.23.2`, optionally signs the image (`gcloud beta container binauthz attestations sign-and-create` against the `pipeline-attestor` using the `binauthz-signer` KMS key in `{project}-binauthz-keyring`), then either runs `gcloud run services update --image=...:$COMMIT_SHA` directly or creates a Cloud Deploy release (Section 3.1).
Registry management: the module discovers the `Services_GCP` shared repository or creates one, and applies cleanup policies — `max_images_to_retain` (default `7`), `delete_untagged_images` (default `true`), `image_retention_days` (default `30`), scoped to this deployment's package names. `enable_image_mirroring` (default `true`) copies external base images into Artifact Registry using Crane digest comparison, comparing source/target SHA256 digests and only copying (or overwriting a stale tag) when digests differ — protecting you from registry rate limits and tag drift. `enable_vulnerability_scanning` (Services_GCP) makes Artifact Analysis scan everything pushed.
**Try it**
1. Push a commit to the configured branch and watch the trigger fire: **Console > Cloud Build > History**, open the build, and identify the Kaniko step and (if Binary Authorization is on) the attestation step.
```bash
gcloud builds list --limit=5
gcloud builds log
```
2. Inspect the resulting tags and scan results:
```bash
gcloud artifacts docker images list \
us-central1-docker.pkg.dev// --include-tags
gcloud artifacts docker images describe \
us-central1-docker.pkg.dev///:latest \
--show-package-vulnerability
```
3. Verify the attestation exists for the new digest:
```bash
gcloud container binauthz attestations list \
--attestor=pipeline-attestor --attestor-project=
```
4. Re-apply the deployment *without* changing source and confirm no new Cloud Build job runs (the build's content hash was unchanged).
5. You know it worked when the image shows three tags (version, `latest`, commit SHA), vulnerabilities are listed, and an attestation references the new digest.
**Check yourself**
Q1: Why does the pipeline deploy by commit-SHA tag rather than `latest`, even though `latest` is also pushed?
A: `latest` is mutable — it points to whatever was pushed most recently, so a deployment referencing it is not reproducible and rollbacks are ambiguous. The commit SHA tag is effectively immutable and ties the running revision to exact source provenance, which is also what the Binary Authorization attestation signs (the digest). `latest` is kept only as a developer convenience.
Q2: A build fails with Docker daemon errors inside Cloud Build. The RAD pipeline never hits this — why?
A: It uses Kaniko, which builds OCI images entirely in userspace from the Dockerfile without a Docker daemon — the standard answer for daemonless, cacheable container builds in CI. (Buildpacks are the other daemonless exam answer, used by `gcloud run deploy --source`.)
Q3: Artifact Registry storage costs are growing without bound in a busy repo. Which three RAD controls address it?
A: `delete_untagged_images = true` removes dangling layers, `image_retention_days = 30` ages out old images, and `max_images_to_retain = 7` keeps the most recent N regardless of age (a keep-guard, not a deleter). Together they implement the recommended AR cleanup-policy pattern: delete-by-age plus keep-most-recent.
**Beyond the modules** — The exam also covers Buildpacks/source deploys, build provenance and SLSA levels (Cloud Build generates SLSA provenance viewable under a build's **Security insights** tab), private pools, and build substitutions/secrets in a Cloud Build config (try `gcloud builds submit --substitutions=_FOO=bar` in a scratch repo). The RAD trigger supports GitHub only (token or App installation) — know that Cloud Build also connects GitLab and Bitbucket repos.
**⚠️ Exam trap** — Pushing an image to Artifact Registry does *not* deploy it. The pipeline's explicit `gcloud run services update` (or Cloud Deploy release) step is what changes the running revision — a missing deploy step is a classic "build succeeded, app unchanged" troubleshooting scenario.
---
## 2.3 Testing
> ⏱ ~45 min · 💰 low (extra Cloud Build minutes) · ⚙️ Requires: Delivery pipeline profile + write access to the app repository
**Why the exam cares** — Tests must run *inside* the pipeline so a failure blocks promotion: unit tests early (cheap, hermetic, emulator-backed), integration tests against real or staged services after build, and smoke tests after deploy to a non-prod stage. The exam tests where each belongs and what a failing step does to the pipeline.
**How RAD implements it** — Honestly: the generated pipelines contain **no test step by default** — the CI flow is build → (optional attestation) → deploy/release. The hooks for adding tests are real, though:
- The Cloud Build trigger executes the generated build config; steps run sequentially and any non-zero exit fails the build, so a test step inserted between Kaniko and the deploy step gates deployment exactly as the exam describes.
- `cicd_trigger_config.branch_pattern` (default `"^main$"`) controls which pushes build at all; `included_files`/`ignored_files` keep doc-only commits from burning build minutes.
- The foundation modules themselves ship native OpenTofu/Terraform tests exercising the plan-time validations — a useful example of testing infrastructure code, which occasionally appears on the exam as "shift-left for IaC".
- Cloud Deploy stages (Section 3.1) provide the post-deploy verification surface: promote to `dev`, run smoke tests against the per-stage service URL, then promote.
**Try it**
1. In your application repo, add a test step to the build config between the build and deploy steps, e.g.:
```yaml
- name: 'python:3.12-slim'
entrypoint: 'bash'
args: ['-c', 'pip install -r requirements.txt && pytest -q']
```
2. Push a commit with a deliberately failing test and observe: **Console > Cloud Build > History** shows the red step, and the deploy step never runs.
```bash
gcloud builds list --filter="status=FAILURE" --limit=3
```
3. Confirm the Cloud Run service still runs the previous image:
```bash
gcloud run services describe --region=us-central1 \
--format="value(spec.template.spec.containers[0].image)"
```
4. You know it worked when the failed build leaves the deployed image untouched and the deploy step is skipped.
**Check yourself**
Q1: Integration tests need a real Postgres but must not touch production data. How would you structure this with the RAD stack?
A: Deploy a separate tenant (`tenant_id = "ci"`) so the pipeline gets its own isolated Cloud SQL database and service, run integration tests against that stage from a Cloud Build step, and tear down or reuse it per run. Unit tests stay on emulators/mocks; only the integration layer touches the real (isolated) database.
Q2: Where do smoke tests belong in a Cloud Deploy pipeline, and what stops a bad release from reaching prod?
A: After the rollout to a non-prod target (dev/staging) — run them against that stage's URL, and gate `prod` with `require_approval = true` (the RAD default) so a human (or an automated verification you wire in) confirms before promotion. A failed rollout or withheld approval keeps the release from advancing.
**Beyond the modules** — Practice writing emulator-backed unit tests (Pub/Sub, Firestore, Spanner emulators), Cloud Build test reporting, and load testing against Cloud Run revisions (e.g., `hey`/`k6` against a tagged canary URL). Cloud Deploy *verify* (post-deploy verification jobs declared in the Skaffold config) is the managed version of step 2's smoke-test idea and worth reading about — the RAD Cloud Deploy configs use hooks for IAM and jobs, not verification.
**⚠️ Exam trap** — Cloud Build steps share the `/workspace` volume but are otherwise isolated containers; a test step can't reach a server started in a previous step unless you background it within the *same* step or use the `docker` network. "Why can't step 4 see the service step 3 started?" is a recurring question shape.
---
# PCD Certification Preparation Guide: Section 3 — Deploying applications (~20% of the exam)
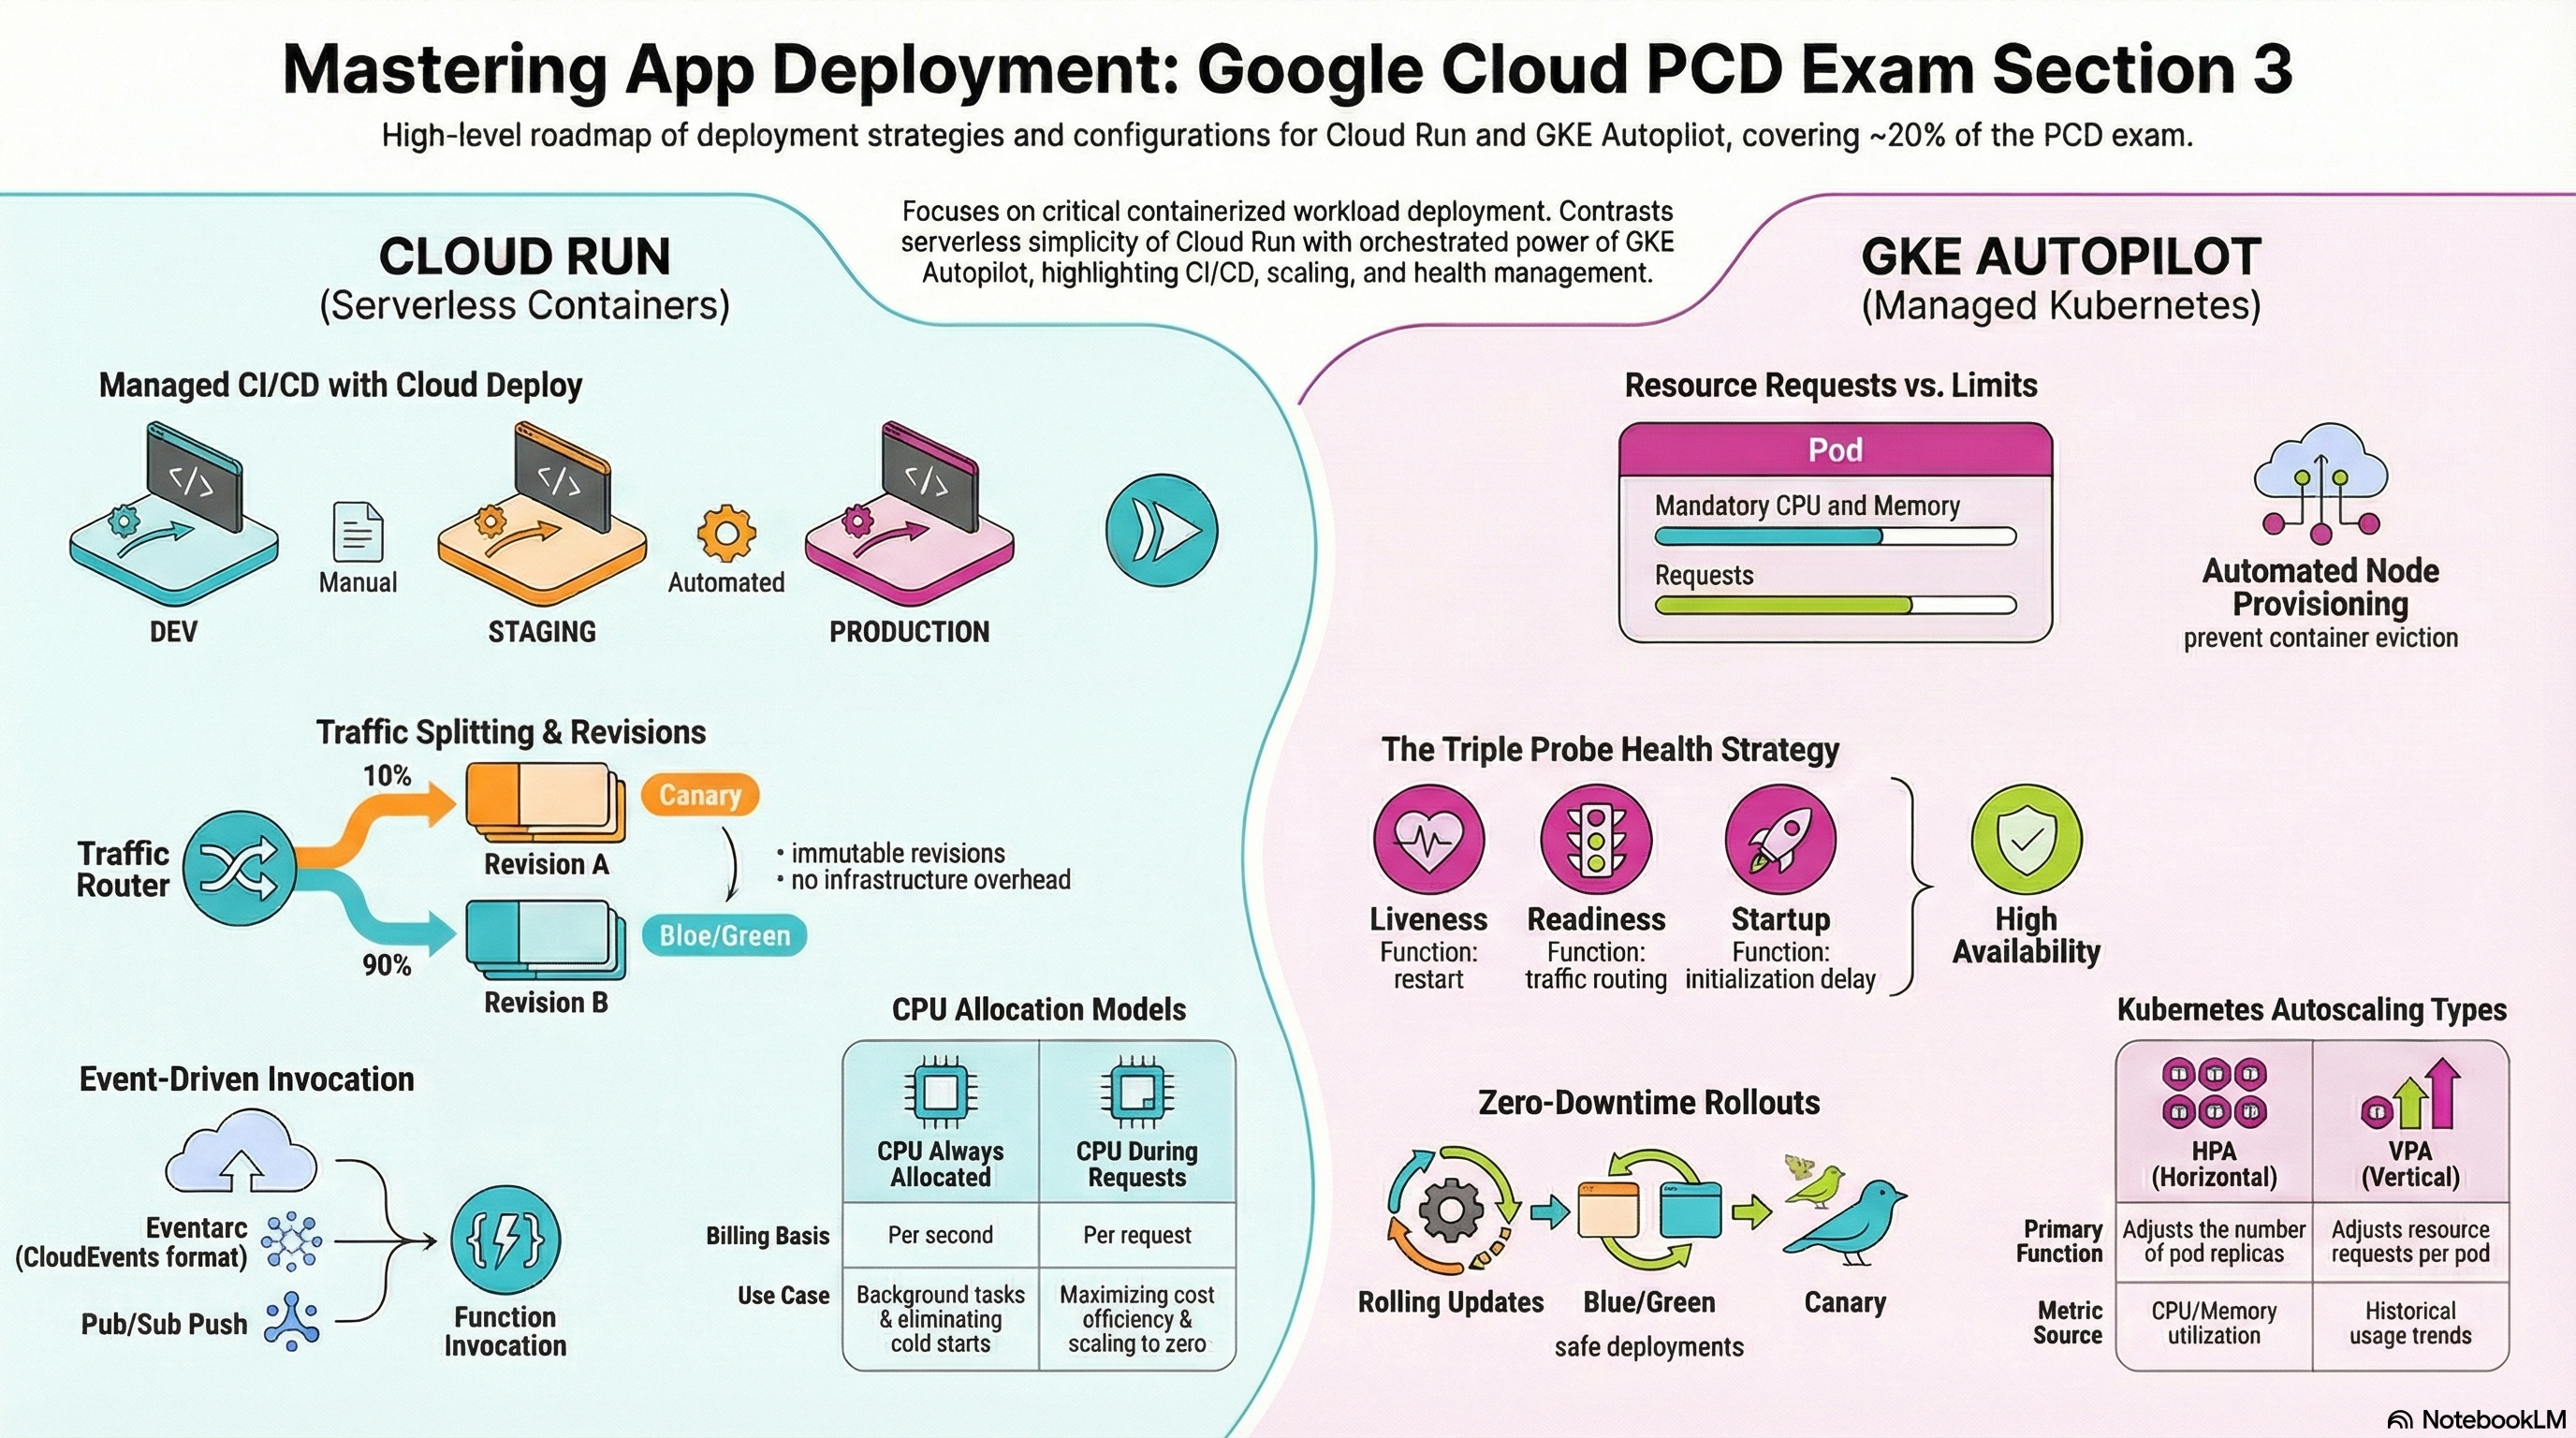 > 📚 **Official exam guide:** [Professional Cloud Developer certification](https://cloud.google.com/learn/certification/cloud-developer) — always confirm section weightings against the current Google Cloud exam guide.
This section is where the RAD foundation modules shine: `App_CloudRun` deploys a fully configured Cloud Run v2 service (scaling, probes, volumes, traffic management, jobs, optional Cloud Deploy pipeline) and `App_GKE` deploys the equivalent Kubernetes workload on GKE Autopilot (Deployment/StatefulSet, HPA, probes, quotas, Gateway API). Deploy the **Serverless baseline** and **Delivery pipeline** profiles for 3.1, and the **Kubernetes lab** profile for 3.2 (see the [Lab Map](PCD_Certification_Guide.md)).
---
## 3.1 Deploying applications to Cloud Run
> ⏱ ~90 min · 💰 low — per-stage services scale to zero; Cloud Deploy itself is free (you pay for the Cloud Build it runs) · ⚙️ Requires: Serverless baseline; Delivery pipeline profile for the Cloud Deploy steps
**Why the exam cares** — Cloud Run questions probe the service resource model: every deploy creates an immutable *revision*; traffic is routed across revisions by percentage and tag; scaling, CPU allocation, execution environment, and probes are revision properties. Progressive delivery questions then layer Cloud Deploy on top: releases, targets, promotion, and approval gates. You should be able to predict what a given configuration does to cold starts, cost, and rollback time.
**How RAD implements it** — App_CloudRun builds the Cloud Run v2 service from portal variables:
| Concern | Variables (defaults) |
|---|---|
| Lifecycle | `deploy_application` (`true`) — `false` provisions infra only |
| Image | `container_image_source` (`"custom"` = Cloud Build; `"prebuilt"` = use `container_image` as-is), `enable_image_mirroring` (`true`) |
| Scaling | `min_instance_count` (`0`), `max_instance_count` (`1`); plan-time check min ≤ max |
| Runtime | `container_port` (`8080`), `container_resources` (`1000m`/`512Mi`), `timeout_seconds` (`300`), `execution_environment` (`"gen2"`), `cpu_always_allocated` (`false`), `startup_cpu_boost` hardcoded on |
| Probes | `startup_probe_config` (enabled, HTTP `/healthz`, delay 10s, period 10s, failure threshold 10) and `health_check_config` → liveness probe (enabled, HTTP `/healthz`, delay 15s, period 30s, failure threshold 3); both support TCP |
| Volumes | Cloud SQL socket (`enable_cloudsql_volume` `true`, mount `cloudsql_volume_mount_path` `/cloudsql`), NFS (`enable_nfs` `true`, `nfs_mount_path` `/mnt/nfs`), GCS Fuse (`gcs_volumes`) — NFS and Fuse require gen2 (validated) |
| Traffic | `traffic_split` (default all-to-latest), revision `tag` for preview URLs, `max_revisions_to_retain` (`7`) |
| Networking | `ingress_settings` (`"all"`), Direct VPC egress with `vpc_egress_setting` (`"PRIVATE_RANGES_ONLY"`) — no Serverless VPC Access connector is used |
| Jobs | `initialization_jobs` (Cloud Run v2 Jobs with `depends_on_jobs` ordering, `execute_on_apply`, NFS/GCS mounts); `cron_jobs` |
Progressive delivery: `enable_cloud_deploy` (default `false`) creates a Cloud Deploy delivery pipeline — **setting it without `enable_cicd_trigger = true` is rejected at plan time** by a precondition in App_CloudRun (the pipeline would never receive a release without a CI trigger). `cloud_deploy_stages` defaults to `dev` → `staging` → `prod` with `require_approval = true` on prod and `auto_promote = false` everywhere (per-stage `auto_promote` creates a Cloud Deploy automation). Each stage gets its own Cloud Run service named `-`; only the prod stage inherits your `ingress_settings` (non-prod stages stay `"all"` so their `*.run.app` URLs work). Skaffold configs live in a GCS bucket named `{project}-{8-char-md5}-cd-configs`; skaffold post-deploy hooks grant `allUsers` invoker on public stages and execute initialization jobs with `gcloud run jobs execute --wait`. With `cicd_enable_cloud_deploy = true`, the Cloud Build trigger ends with `gcloud deploy releases create` instead of `gcloud run services update`.
**Try it**
1. Deploy the baseline, then list revisions and confirm probe wiring:
```bash
gcloud run services describe --region=us-central1 \
--format="yaml(spec.template.spec.containers[0].startupProbe, spec.template.spec.containers[0].livenessProbe)"
```
2. With the Delivery pipeline profile, push a commit and follow the release:
```bash
gcloud deploy releases list --delivery-pipeline= --region=us-central1
gcloud deploy rollouts list --delivery-pipeline= \
--release= --region=us-central1
```
3. Promote to staging, then approve prod (it is gated by default):
```bash
gcloud deploy releases promote --release= \
--delivery-pipeline= --region=us-central1
gcloud deploy rollouts approve --release= \
--delivery-pipeline= --region=us-central1
```
Watch **Console > Cloud Deploy > Delivery pipelines** render the stage graph as each rollout completes.
4. Inspect the per-stage services: `gcloud run services list --region=us-central1` shows `-dev`, `-staging`, `-prod`.
5. You know it worked when the prod rollout sits in "Pending approval" until you approve it, and the prod service serves the new image afterward.
**Check yourself**
Q1: A release passed dev and staging but the prod rollout is stuck. No errors anywhere. What's the most likely cause in the default RAD pipeline?
A: The prod stage has `require_approval = true` by default — the rollout is waiting in `PENDING_APPROVAL` for `gcloud deploy rollouts approve` (or a console approval). This is the intended manual gate, not a failure; the exam phrases this as "deployment requires manager sign-off before production".
Q2: You set `enable_cloud_deploy = true` without `enable_cicd_trigger = true` and the plan fails with a precondition error. Why does the module insist on the trigger?
A: Cloud Deploy releases are only created by the CI/CD pipeline; a delivery pipeline with nothing to create releases is meaningless, so the module rejects the combination at plan time instead of provisioning a dead pipeline. Generalized exam lesson: progressive delivery sits *downstream* of CI — Cloud Deploy consumes artifacts, it doesn't build them.
Q3: How do you give QA a URL for an unreleased revision without sending it any production traffic?
A: Add a `traffic_split` entry for the revision with `percent = 0` and a `tag` (e.g., `"qa"`). Cloud Run exposes a stable tagged URL (`https://qa----.run.app`) that routes directly to that revision while the main URL keeps serving the stable split.
**Beyond the modules** — The exam also expects Cloud Run *event-driven* invocation (Eventarc triggers delivering CloudEvents, Pub/Sub push subscriptions authenticating with OIDC tokens and `roles/run.invoker`) — the modules only use Eventarc internally for secret rotation. Also study canary/automated rollback strategies in Cloud Deploy (canary deployment strategy with traffic percentages per phase) — the RAD pipeline uses the standard strategy with manual promotion. Try `gcloud deploy rollouts retry` and `gcloud run services update-traffic --to-latest` in a scratch project.
**⚠️ Exam trap** — The startup probe and the liveness probe fail differently: a failing *startup* probe means the instance never receives traffic and Cloud Run keeps retrying/replacing instances (deploys appear to hang); a failing *liveness* probe restarts a previously healthy container. "New revision stuck at 0% serving" is almost always the startup probe (wrong `path` or port), not liveness.
---
## 3.2 Deploying containers to GKE
> ⏱ ~90 min · 💰 moderate — Autopilot bills summed pod resource *requests* plus a cluster fee; the quota/PDB/probe exercises add nothing · ⚙️ Requires: Kubernetes lab profile (`create_google_kubernetes_engine = true` in Services_GCP, then App_GKE)
**Why the exam cares** — GKE questions test the Kubernetes resource model through a Google lens: requests vs limits (and how Autopilot bills them), Deployment vs StatefulSet selection, HPA vs VPA, probe semantics, disruption budgets, and modern exposure via the Gateway API. Autopilot specifics matter: you size pods, not nodes.
**How RAD implements it** — `Services_GCP` provisions the cluster: `gke_cluster_mode` default `"AUTOPILOT"`, Dataplane V2, VPC-native (alias-IP) pod/service secondary ranges, Workload Identity (`{project}.svc.id.goog`), the standard Gateway API channel, release channel `REGULAR`, and the Secret Manager add-on. `App_GKE` then deploys into it (discovering the cluster via `gke_cluster_selection_mode`, or provisioning an inline Autopilot cluster when the platform module is absent):
- **Workload type.** `workload_type` (default `null`) auto-resolves: `stateful_pvc_enabled = true` → StatefulSet (with required `stateful_pvc_size` and `stateful_pvc_mount_path`, `stateful_pod_management_policy` default `OrderedReady`, `stateful_update_strategy` default `RollingUpdate`); otherwise Deployment. Explicitly setting `workload_type = "Deployment"` together with `stateful_pvc_enabled = true` fails at plan time.
- **Autoscaling.** The HPA is created only when `max_instance_count > 1` (default `3`) **and** `enable_vertical_pod_autoscaling = false` (its default); it targets 70% CPU and 80% memory utilization. Turning VPA on therefore replaces horizontal scaling with request right-sizing — they are mutually exclusive here because both would act on the same CPU/memory signals.
- **Probes.** `startup_probe_config` (enabled, HTTP `/healthz`, delay 10s, period 10s, failure threshold 3) and `health_check_config` → liveness probe (delay 15s, period 30s, failure threshold 3). **No readiness probe is configured** — the module relies on the startup probe to gate first traffic; be ready to explain on the exam why a dedicated readiness probe still matters for temporarily-overloaded pods.
- **Sidecar.** When a database exists and `enable_cloudsql_volume = true`, a `cloud-sql-proxy` sidecar (image mirrored into Artifact Registry) runs with `--private-ip` and a preStop hook calling `/quitquitquit` for graceful shutdown.
- **Namespace governance.** `enable_resource_quota` (default `false`) creates a ResourceQuota — `quota_cpu_requests`/`quota_cpu_limits` default `"4"`, `quota_memory_requests` default `"4Gi"`, `quota_memory_limits` default `"8Gi"` (binary unit suffix is *validated*: a bare `"4"` would be read as 4 bytes by Kubernetes and block all scheduling), `quota_max_pods` `"20"`. `enable_pod_disruption_budget` (default `true`) creates a PDB with `pdb_min_available` default `"1"`, skipped when `max_instance_count = 1` and validated to be < `max_instance_count`. `enable_network_segmentation` (default `false`) adds NetworkPolicies (requires Dataplane V2). `enable_topology_spread` spreads pods across zones/hosts.
- **Exposure.** The Service is `service_type` default `"LoadBalancer"`, `service_port` `80` → `container_port` `8080`, `session_affinity` default `"ClientIP"`. `enable_custom_domain` (default `false`) switches to the Gateway API: a `Gateway` with `gatewayClassName: gke-l7-global-external-managed`, an `HTTPRoute` (plus a `ReferenceGrant` for cross-namespace backends), Certificate Manager Google-managed certs for `application_domains`, and a reserved global static IP (`reserve_static_ip` default `true`). Cloud Armor and CDN attach via `GCPBackendPolicy`.
**Try it**
1. Get credentials and inspect what the module deployed (the namespace is auto-generated from `application_name` + `tenant_id` unless `namespace_name` is set):
```bash
gcloud container clusters get-credentials --region=us-central1
kubectl get ns
kubectl -n get deploy,hpa,pdb,resourcequota,svc
```
2. Confirm probe and sidecar wiring, and watch a rolling update:
```bash
kubectl -n get deploy -o yaml | grep -A6 -E "startupProbe|livenessProbe|cloud-sql-proxy"
kubectl -n rollout status deploy/
kubectl -n rollout history deploy/
```
3. Trigger the HPA: run a load generator against the Service IP and watch replicas climb toward `max_instance_count`:
```bash
kubectl -n get hpa -w
```
4. Set `enable_resource_quota = true` with `quota_max_pods = "2"` while `max_instance_count = 3`, generate load, and observe pods blocked by the quota in `kubectl -n get events --sort-by=.lastTimestamp`.
5. You know it worked when the HPA shows `cpu: %/70%` scaling events and the quota event reads `exceeded quota` when the cap is hit.
**Check yourself**
Q1: On Autopilot, a team sets limits of 4 CPU/8Gi "to be safe" while actual usage is 200m/300Mi. What is the cost effect and the fix?
A: Autopilot bills the pod's resource *requests* (and defaults requests from limits when unset), so over-declaring inflates cost ~20× regardless of usage. Fix: set realistic `container_resources` requests (`cpu_request`/`mem_request`) below the limits, or enable `enable_vertical_pod_autoscaling = true` and let VPA right-size requests — accepting that the module then drops the HPA.
Q2: A maintenance event evicts pods and the app briefly serves 0 replicas. Which RAD default should have prevented this, and when does it silently not apply?
A: The PodDisruptionBudget (`enable_pod_disruption_budget = true`, `pdb_min_available = "1"`) makes voluntary evictions keep at least one pod running. It is intentionally skipped when `max_instance_count = 1` — a PDB of minAvailable 1 on a single-replica workload would block node upgrades entirely. Single-replica workloads therefore have no disruption protection by design.
Q3: You need stable per-pod volumes and ordered startup for a clustered datastore. What do you set, and what happens if you also force `workload_type = "Deployment"`?
A: Set `stateful_pvc_enabled = true` with `stateful_pvc_size` and `stateful_pvc_mount_path` — the workload auto-resolves to a StatefulSet with `OrderedReady` pod management. Forcing `workload_type = "Deployment"` alongside it fails at plan time, because Deployments share volumes and have no stable identity — the validation encodes the exam's own decision rule.
**Beyond the modules** — Study `maxSurge`/`maxUnavailable` tuning on rolling updates and blue/green via label-switching Services (the module always uses default RollingUpdate parameters), GKE Standard node-pool management (`gcloud container node-pools create`), and fine-grained canary traffic on GKE (requires a mesh or Gateway API traffic splitting across two Services — the module's HTTPRoute targets a single backend, selectable per Cloud Deploy stage via `gateway_backend_stage`, default `"dev"`). Also know `kubectl rollout undo` for instant Deployment rollback.
**⚠️ Exam trap** — Requests vs limits on Autopilot: scheduling, quota accounting (`quota_*_requests`), and *billing* all key off requests, while OOM kills key off memory limits. "Reduce the limit" does not reduce Autopilot cost if the request stays high — and a memory limit below actual usage turns a working pod into a CrashLoopBackOff.
---
# PCD Certification Preparation Guide: Section 4 — Integrating applications with Google Cloud services (~21% of the exam)
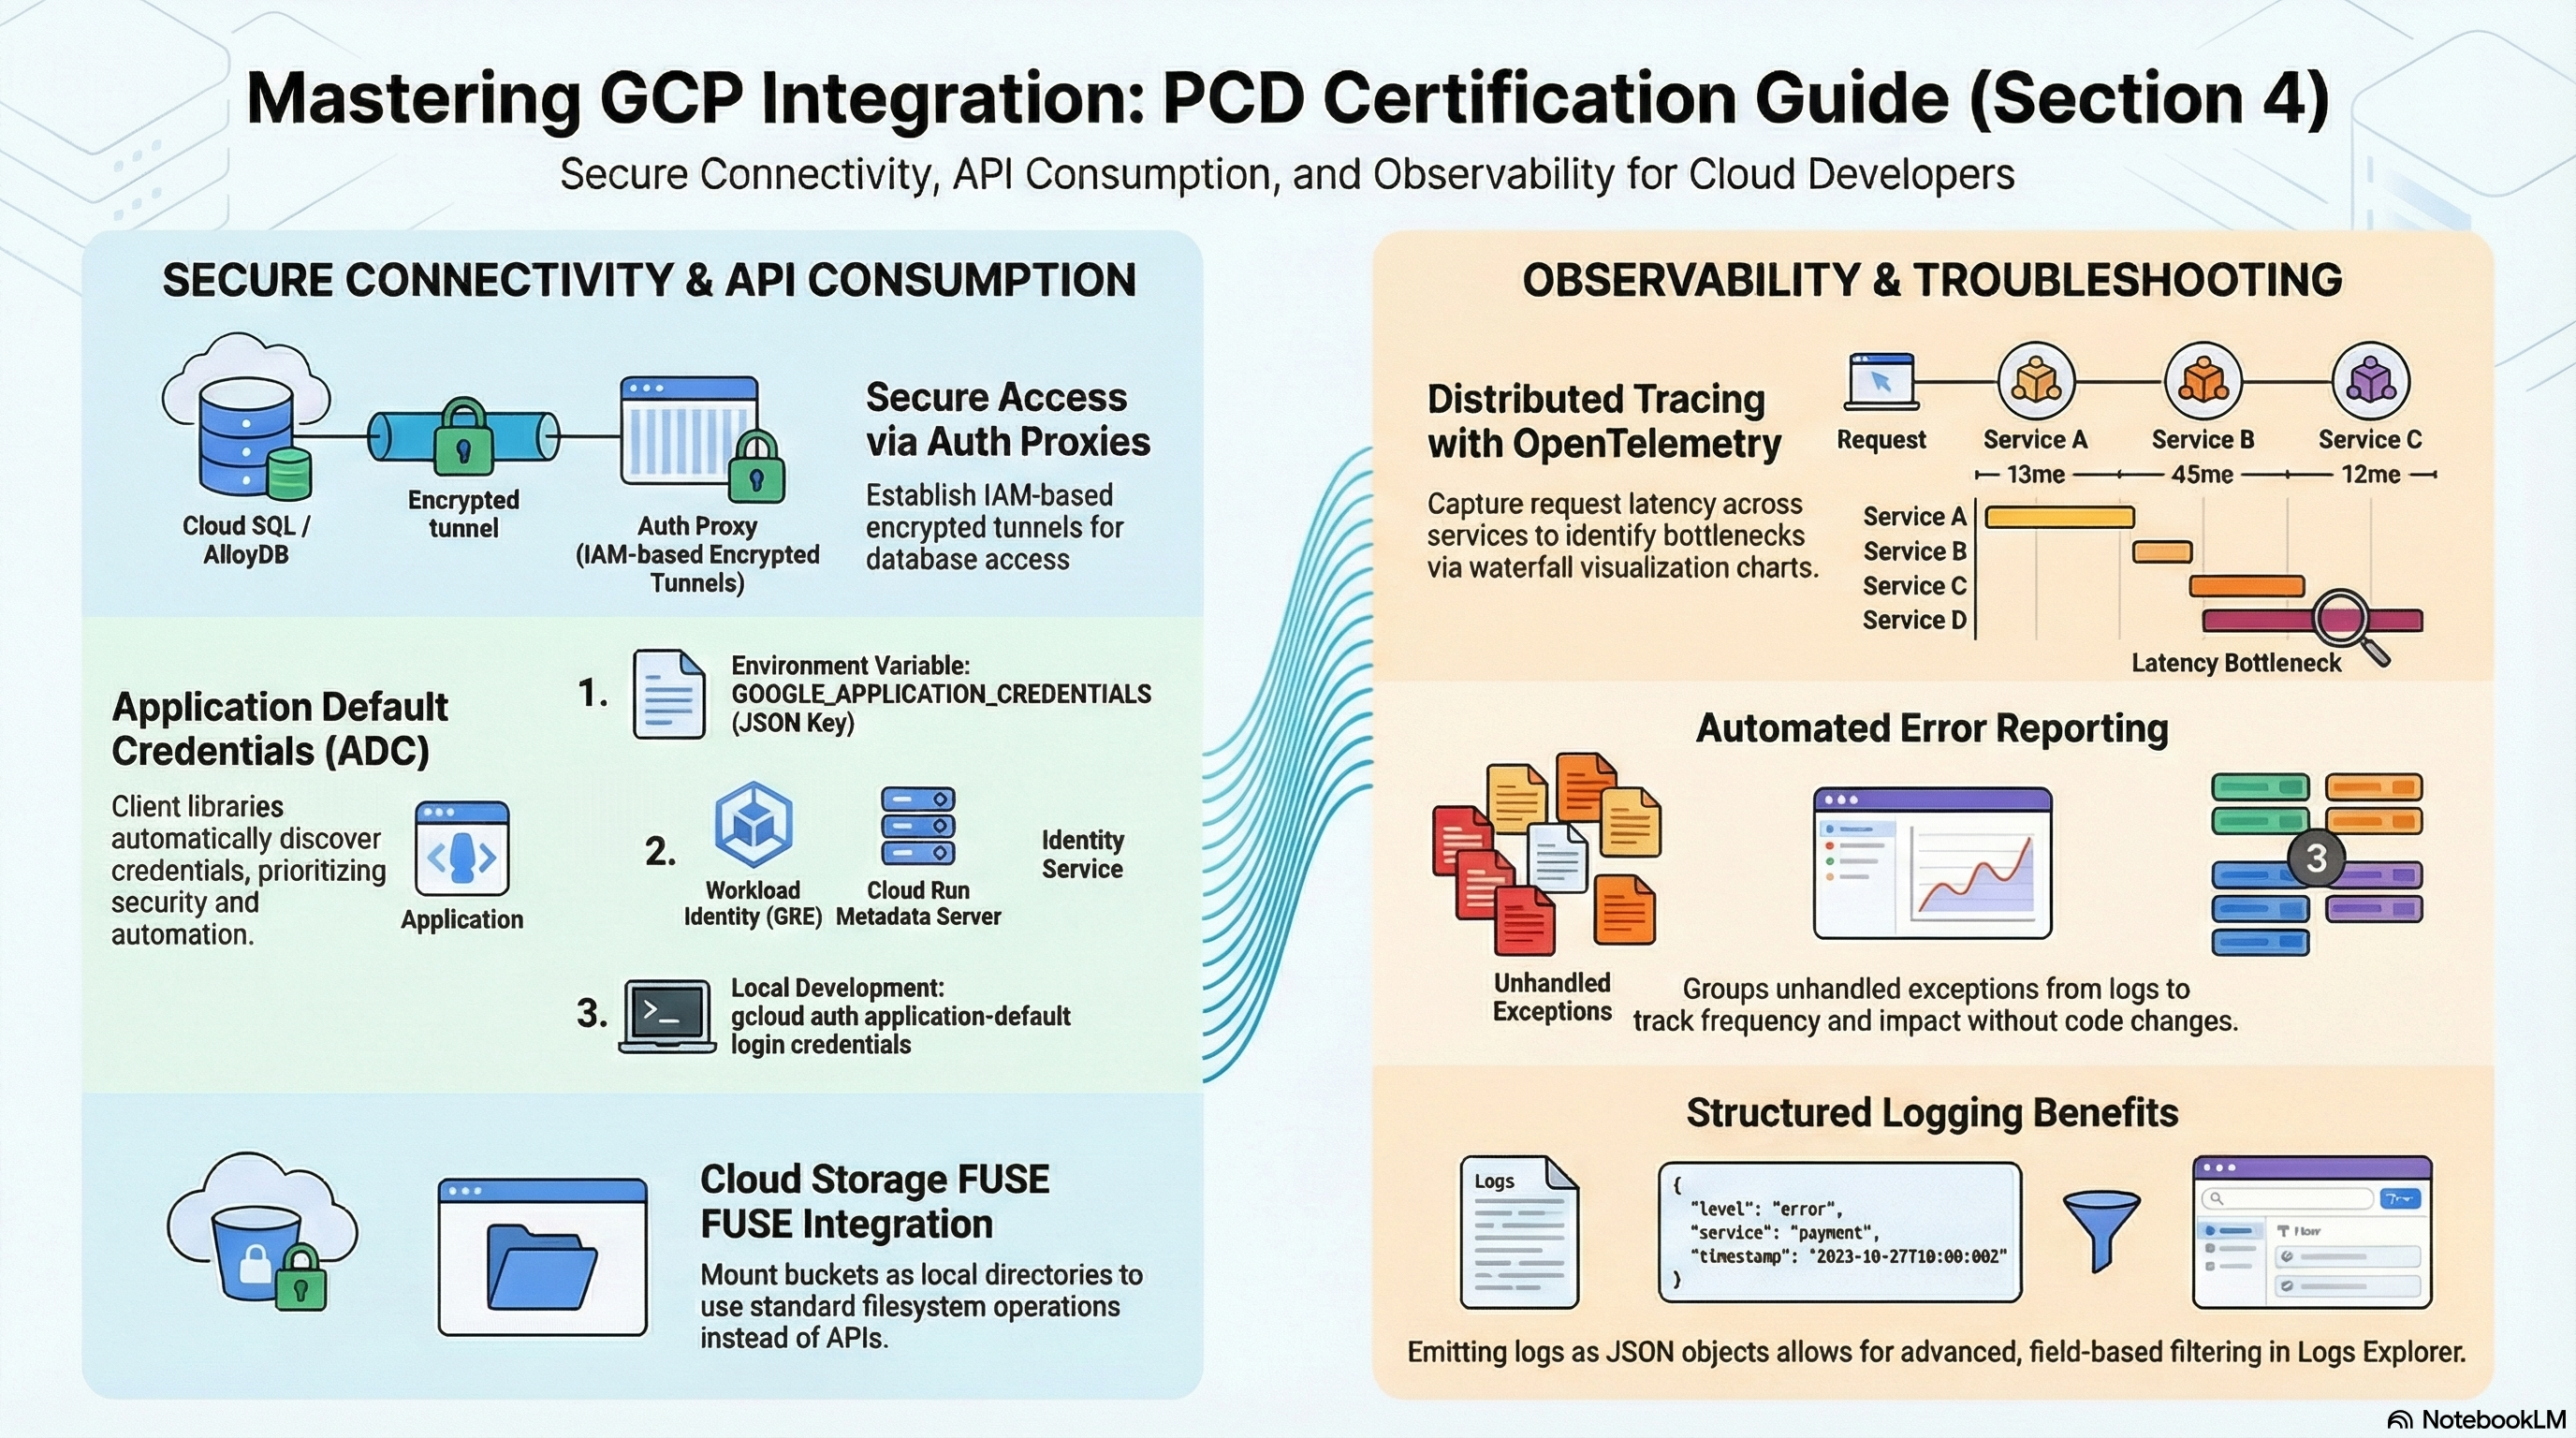 > 📚 **Official exam guide:** [Professional Cloud Developer certification](https://cloud.google.com/learn/certification/cloud-developer) — always confirm section weightings against the current Google Cloud exam guide.
This section uses the integration surfaces the foundation modules wire up for you: database connectivity and runtime configuration (App_CloudRun's Cloud Run service and the GKE proxy sidecar), identity (the GKE service-account wiring, Workload Identity Federation in `Services_GCP`, and the platform's IAM layer), and monitoring (the platform's monitoring and dashboard layers). Deploy the **Serverless baseline** profile; add the **Kubernetes lab** profile for the Workload Identity exercises (see the [Lab Map](PCD_Certification_Guide.md)).
---
## 4.1 Integrating applications with data and storage services
> ⏱ ~60 min · 💰 no additional cost over the deployed profile · ⚙️ Requires: Serverless baseline (Postgres + Cloud SQL volume are on by default)
**Why the exam cares** — Integration questions are concrete: what connection string does the code use, where does the password come from, which IAM role does the service account need, and what happens at scale (connection limits, proxy behavior). The Cloud SQL Auth Proxy pattern — IAM-authenticated, TLS-encrypted, no IP allowlists — is the canonical answer, and you should know both its Cloud Run form (managed socket volume) and its GKE form (sidecar container).
**How RAD implements it** —
*Database connectivity.* On Cloud Run, `enable_cloudsql_volume` (default `true`) attaches the managed Cloud SQL volume mounted at `cloudsql_volume_mount_path` (default `/cloudsql`); the app connects via the Unix socket `/cloudsql/::`. On GKE, the same flag injects a `cloud-sql-proxy` sidecar (image mirrored into Artifact Registry, started with `--private-ip`, graceful preStop via `/quitquitquit`) and the app connects to localhost. Disable the flag to connect over private IP directly — the module then sets `DB_HOST` to the instance's private address.
*Runtime configuration injection.* App_CloudRun assembles env vars the container sees without any code knowing about Terraform: `APP_NAME`, `APP_VERSION`, `DB_NAME`, `DB_USER`, `DB_PORT`, `DB_HOST` (socket path or private IP), `CLOUDRUN_SERVICE_URL`, plus `NFS_SERVER_IP` when NFS is enabled and `REDIS_HOST`/`REDIS_PORT`/`REDIS_URL` when `enable_redis` is on. The password never appears in plaintext: `DB_PASSWORD` arrives as a Secret Manager reference. All the env var *names* are overridable (`db_password_env_var_name`, `db_host_env_var_name`, etc.) so existing application images need no changes.
*Schema and data lifecycle.* `initialization_jobs` (default: a `db-init` job running a database-init script on `postgres:15-alpine` with `execute_on_apply = true`) handles migrations/seeding with `depends_on_jobs` ordering. `enable_backup_import` restores a dump from GCS or Google Drive (`backup_source`, `backup_file`, `backup_format`); `enable_postgres_extensions`/`enable_mysql_plugins` install database extensions; `enable_custom_sql_scripts` runs arbitrary SQL from a bucket. `Services_GCP` additionally offers `enable_cloudsql_iam_auth` (default `false`), which sets the IAM-auth database flag (`cloudsql.iam_authentication` on PostgreSQL, `cloudsql_iam_authentication` on MySQL) and grants `roles/cloudsql.instanceUser` — the passwordless IAM database authentication the exam mentions.
*File and object integration.* `gcs_volumes` mounts buckets via GCS Fuse (filesystem semantics; gen2 only), `enable_nfs` (default `true`) mounts the shared NFS export at `/mnt/nfs` for multi-instance shared writes, and `storage_buckets` provisions buckets with per-bucket `roles/storage.objectAdmin` for the app SA — the client-library path.
**Try it**
1. See exactly what your code sees:
```bash
gcloud run services describe --region=us-central1 \
--format="yaml(spec.template.spec.containers[0].env, spec.template.spec.containers[0].volumeMounts)"
```
Identify `DB_HOST` (a `/cloudsql/...` path), the `DB_PASSWORD` secret reference, and the volume mounts.
2. Verify the IAM that makes the proxy work — the service account needs `roles/cloudsql.client`:
```bash
gcloud projects get-iam-policy \
--flatten="bindings[].members" \
--filter="bindings.members~cloudrun-sa" \
--format="table(bindings.role)"
```
3. Watch the default initialization job run and read its logs:
```bash
gcloud run jobs executions list --job= --region=us-central1
gcloud logging read 'resource.type="cloud_run_job"' --limit=20
```
4. On the GKE profile, confirm the sidecar: `kubectl -n get pod -o jsonpath='{.spec.containers[*].name}'` should list your app and `cloud-sql-proxy`.
5. You know it worked when the app container resolves `DB_HOST` to the socket path, the db-init execution shows `Succeeded`, and the GKE pod runs two containers.
**Check yourself**
Q1: Cloud Run scaled to 50 instances and Postgres started rejecting connections. The instance has the module default flags. What happened and what are the fixes?
A: Each instance holds its own pool; 50 instances × even a small pool exceeds the default `max_connections=200` flag set on the RAD Postgres instance. Fixes in exam order: cap `max_instance_count`, shrink the per-instance pool, raise `max_connections` (costs memory), or introduce server-side pooling. The Auth Proxy authenticates and encrypts — it does not pool for you.
Q2: Why does the platform run schema migrations as a Cloud Run *job* instead of at service startup?
A: A service can scale to N concurrent instances — running migrations in the entrypoint races N copies against each other and slows cold starts. A job (`initialization_jobs` with `execute_on_apply`) runs exactly `task_count` tasks once, can be ordered with `depends_on_jobs`, retried independently (`max_retries`), and keeps the serving path fast. This separation of "run-once" from "serve" is a standard PCD design answer.
Q3: An app needs shared writable storage across all Cloud Run instances. Compare the two RAD options.
A: `enable_nfs` mounts a real POSIX filesystem (Filestore or the platform NFS VM) — correct for apps needing file locking/rename semantics, but it's a single capacity/throughput point. `gcs_volumes` (GCS Fuse) backs the mount with an object store — effectively unlimited and cheaper, but writes are object uploads (no partial writes/locking). Both require `execution_environment = "gen2"`.
**Beyond the modules** — The modules create no application messaging or document-store code paths: practice the **Pub/Sub** client libraries (publish with attributes, pull vs push subscriptions, ack deadlines, dead-letter topics), **Firestore** SDK usage (documents, queries needing composite indexes, real-time listeners, transactions), and **Cloud Storage** client-library patterns including signed URLs for direct browser upload/download. The only Pub/Sub in the platform is internal (secret-rotation and SCC topics) — useful to inspect (`gcloud pubsub topics list`) but not an application pattern.
**⚠️ Exam trap** — The Cloud SQL Auth Proxy replaces *network* allowlisting and TLS cert management, not database authentication: code still presents a DB user and password (unless IAM database authentication is enabled). "We added the proxy, why do we still need the password?" distinguishes `roles/cloudsql.client` (connect) from `roles/cloudsql.instanceUser` + IAM auth (login).
---
## 4.2 Consuming Google Cloud APIs
> ⏱ ~60 min · 💰 no additional cost · ⚙️ Requires: Serverless baseline; Kubernetes lab profile for Workload Identity; `enable_workload_identity_federation = true` in Services_GCP for the WIF steps
**Why the exam cares** — Every PCD scenario about calling Google APIs reduces to identity: code should use Application Default Credentials backed by the runtime's service account — never JSON key files. You must know how ADC resolves on Cloud Run (metadata server), on GKE (Workload Identity), on developer machines (`gcloud auth application-default login`), and outside Google Cloud entirely (Workload Identity Federation). The second axis is authorization: least-privilege roles on the *resource* (a specific secret, a specific bucket), not the project.
**How RAD implements it** —
*Dedicated service accounts.* `Services_GCP` creates `cloudrun-sa-{prefix}`, `cloudbuild-sa-{prefix}`, `clouddeploy-sa-{prefix}`, `gke-sa-{prefix}`, and `nfs-sa-{prefix}` — nothing runs as the default compute SA. The platform's IAM layer applies resource-level least privilege: `roles/secretmanager.secretAccessor` granted *per secret*, `roles/storage.objectAdmin` *per bucket*, and `roles/iam.serviceAccountUser` for the impersonation chains the deployer needs. When your app needs more (say Firestore), `additional_cloudrun_sa_roles` extends the Cloud Run SA's role list declaratively.
*Workload Identity on GKE.* App_GKE creates a Kubernetes ServiceAccount per namespace annotated `iam.gke.io/gcp-service-account: ` and binds `roles/iam.workloadIdentityUser` to `serviceAccount:{project}.svc.id.goog[/]`. Pods using that KSA get GSA-backed tokens from the metadata server — ADC works with zero key files, identical in code to Cloud Run.
*Workload Identity Federation.* `Services_GCP` (`enable_workload_identity_federation`, default `false`) creates pool `wif-pool` with a provider chosen by `wif_provider_type` (default `"github"` → provider `github-actions`; also `gitlab` → `gitlab-ci`, or `generic` for any OIDC issuer). All pool identities (`principalSet://.../*`) may impersonate the Cloud Build, Cloud Deploy, and Cloud Run service accounts via `roles/iam.workloadIdentityUser` — keyless CI from external systems, the exam's recommended replacement for exported keys.
*Service-to-service authorization.* Cloud Run access is IAM on `roles/run.invoker`: public services get an `allUsers` binding; IAP services instead grant the IAP service agent invoker rights and your principals `roles/iap.httpsResourceAccessor`. Calling a non-public service from another service means minting an *ID token* for the caller's SA — the modules establish the IAM shape; the token-fetching code is yours to learn.
**Try it**
1. Prove the runtime identity from inside the deployed service (no SDK required — this is what ADC does under the hood):
```bash
# from your workstation, against the metadata-backed identity:
gcloud run services describe --region=us-central1 \
--format="value(spec.template.spec.serviceAccountName)"
```
2. On GKE, inspect the Workload Identity wiring:
```bash
kubectl -n get sa -o yaml | grep -B2 "iam.gke.io/gcp-service-account"
gcloud iam service-accounts get-iam-policy \
--format="table(bindings.role, bindings.members)"
```
You should see the `roles/iam.workloadIdentityUser` binding for `serviceAccount:.svc.id.goog[/]`.
3. Inspect the WIF pool and provider, then test invoker enforcement:
```bash
gcloud iam workload-identity-pools providers list \
--workload-identity-pool=wif-pool --location=global
gcloud run services get-iam-policy --region=us-central1
curl -s -o /dev/null -w "%{http_code}\n" \
-H "Authorization: Bearer $(gcloud auth print-identity-token)" https:///
```
4. You know it worked when the KSA annotation matches the GSA whose policy contains the workloadIdentityUser binding, and the authenticated curl returns 200 where an anonymous one is rejected (on a non-public service).
**Check yourself**
Q1: Service A on Cloud Run must call private Service B. Which role, on what, for whom — and which token type does A send?
A: Grant A's service account `roles/run.invoker` *on Service B* (resource-level, not project-level). A fetches an **ID token** with audience = B's URL (from the metadata server, e.g. via the client library or `fetch_id_token`) and sends it as a Bearer header. An OAuth *access* token is the wrong answer — Cloud Run's IAM check validates identity tokens.
Q2: GitHub Actions needs to push images and create Cloud Deploy releases without a downloaded key. Which RAD configuration is the textbook setup?
A: `enable_workload_identity_federation = true` with `wif_provider_type = "github"`. The workflow exchanges its GitHub OIDC token through pool `wif-pool` / provider `github-actions` and impersonates `cloudbuild-sa-*`/`clouddeploy-sa-*` (the module binds `roles/iam.workloadIdentityUser` for the pool). No long-lived credential exists anywhere; note the module's wildcard `principalSet` is deliberately broad — production answers scope to `attribute.repository`.
Q3: A pod's Google API calls run as the node's identity instead of the app's GSA. What's missing?
A: One of the three Workload Identity legs: the cluster's workload pool, the KSA annotation `iam.gke.io/gcp-service-account`, or the `roles/iam.workloadIdentityUser` binding on the GSA for `{project}.svc.id.goog[ns/ksa]` — or the pod spec isn't using the annotated KSA (`serviceAccountName`). The RAD module wires all three; on the exam, the missing IAM binding is the most common culprit.
**Beyond the modules** — Practice the client-library mechanics the modules can't show: automatic retries with exponential backoff (built into the libraries for 429/503), pagination iterators, field masks, and choosing gRPC vs REST transports. Also study API enablement failures (`SERVICE_DISABLED` 403s — the platform pre-enables its APIs, a fresh project does not) and quota errors (`RESOURCE_EXHAUSTED` 429 → backoff or quota increase, not retry-storms).
**⚠️ Exam trap** — Access tokens vs ID tokens: `gcloud auth print-access-token` authorizes Google *API* calls; `gcloud auth print-identity-token` authenticates you *to a service* (Cloud Run invoker, IAP). Swapping them produces 401s that look like missing IAM but aren't.
---
## 4.3 Troubleshooting and observability
> ⏱ ~60 min · 💰 low — alerting/dashboards are free at this scale; log storage grows if you enable DATA_READ audit logs · ⚙️ Requires: any deployed profile; set `support_users` to receive notifications
**Why the exam cares** — PCD troubleshooting questions hand you a symptom (5xx spike, latency regression, crash loop) and expect you to pick the right tool in the right order: Logs Explorer with resource-type filters, metrics and alerting, dashboards, then code-level tools (Trace, Profiler, Error Reporting). Structured logging and instrumentation are developer responsibilities the exam tests directly.
**How RAD implements it** — Containers log to stdout/stderr and Cloud Run/GKE forward to Cloud Logging automatically — nothing to configure. The modules add the alerting layer via the platform's monitoring layer:
- `support_users` creates email notification channels; monitoring resources are only created when `support_users`, `alert_policies`, or an enabled uptime config exists.
- Built-in alerts: CPU utilization > 0.9 and memory utilization > 0.9 (P99-aligned over 60s), filtered to your specific service (`resource.labels.service_name` on Cloud Run; the GKE module passes Kubernetes-scoped filters).
- `alert_policies` adds custom policies declaratively: each entry is `{ name, metric_type, comparison, threshold_value, duration_seconds, aggregation_period }` and the module scopes the filter to the deployed service — e.g. `run.googleapis.com/request_latencies` with `COMPARISON_GT` and `threshold_value = 1000`.
- The platform provisions a per-deployment Cloud Monitoring dashboard (separate Cloud Run and GKE layouts).
- `uptime_check_config` (default `{ enabled = false, path = "/" }` — set `enabled = true` to provision one; `check_interval` default `"60s"`, `timeout` default `"10s"`) provisions a real Cloud Monitoring uptime check named `-uptime-check` (HTTP GET from multiple global regions) plus a `-uptime-check-alert` policy on `monitoring.googleapis.com/uptime_check/check_passed` (fires after 300s of failure, notifies the `support_users` channels). Creation is gated at plan time on public reachability — Cloud Run probes the first `application_domains` entry, else the nip.io LB host, else the run.app URL when `ingress_settings = "all"`; GKE probes the custom domain via the Gateway (HTTPS:443) or the LoadBalancer Service ingress IP over HTTP on `service_port`. Internal-only deployments get no check, and `uptime_check_names` outputs the created check's name.
**Try it**
1. Generate some traffic and read the logs the developer way:
```bash
gcloud logging read \
'resource.type="cloud_run_revision" AND resource.labels.service_name="" AND severity>=WARNING' \
--limit=20 --format="value(timestamp, severity, textPayload)"
```
In **Console > Logging > Logs Explorer**, repeat with the query builder and note that JSON log lines become filterable `jsonPayload.*` fields — emit structured logs from your app to get this for free.
2. Add a latency alert via the portal: `alert_policies = [{ name = "p-latency", metric_type = "run.googleapis.com/request_latencies", comparison = "COMPARISON_GT", threshold_value = 1000, duration_seconds = 300 }]`, apply, then verify:
```bash
gcloud alpha monitoring policies list --format="table(displayName, enabled)"
gcloud monitoring dashboards list --format="value(displayName)"
```
3. Inspect the module-created uptime check (publicly reachable deployments only) and confirm the probed host matches your domain or LB:
```bash
gcloud monitoring uptime list-configs --format="table(displayName, httpCheck.path, period)"
gcloud monitoring uptime describe -uptime-check
```
4. Force an error (e.g., temporarily point `health_check_config.path` at a nonexistent path) and watch the liveness restarts in **Cloud Run > service > Logs** and the CPU/memory charts on the module-created dashboard.
5. You know it worked when the alert policy appears with your email channel attached, and the module-created uptime check shows green from multiple regions in **Monitoring > Uptime checks**.
**Check yourself**
Q1: Users report intermittent 503s but your application logs show nothing at those timestamps. Where do you look next on Cloud Run?
A: The *request* logs and platform metrics, not app logs: filter `resource.type="cloud_run_revision" AND httpRequest.status=503` — 503s with no app log usually mean the request never reached your code (instance startup failures, exceeded `max_instance_count` under load, or request timeout/probe failures). Correlate with `container/instance_count` and startup-probe failures; raising `max_instance_count` or fixing the startup probe is the usual fix.
Q2: An alert should fire when error rate exceeds 5% for 5 minutes, notifying the on-call list. Map this to RAD variables.
A: Put the on-call addresses in `support_users` (creates the notification channels) and add an `alert_policies` entry on `run.googleapis.com/request_count` filtered to 5xx — though for a *ratio*, the honest answer is that the module's single-metric threshold policies can't express it; you'd build a ratio-based condition (MQL/PromQL) directly in Cloud Monitoring. Knowing when declarative simple thresholds stop being enough is itself exam-relevant.
Q3: Checkout takes 4s; the database team swears their queries are fast. Which tool proves where the time goes across your two Cloud Run services?
A: Cloud Trace with distributed trace context propagation — instrument both services with OpenTelemetry (Cloud Trace exporter), propagate the `traceparent` header on the service-to-service call, and read the waterfall to see which span (handler, downstream call, DB query) owns the latency. Logs and metrics aggregate; only tracing shows the per-request breakdown.
**Beyond the modules** — Nothing in the modules instruments application code: study OpenTelemetry setup and trace propagation (Cloud Trace), continuous profiling (`google-cloud-profiler`, flame graphs, <1% overhead — safe in prod), Error Reporting's automatic stack-trace grouping (works from stdout logs for major runtimes), and log-based metrics for alerting on log patterns. Also try Cloud Run's built-in SLO monitoring (**Cloud Run > service > SLOs**) — none of this is provisioned by the platform.
**⚠️ Exam trap** — Don't assume an input variable means a provisioned resource — always verify in the source (earlier platform releases accepted `uptime_check_config` without creating any check; today it provisions one, but only for publicly reachable endpoints). On the exam the analogous trap is assuming Cloud Run "has" tracing/profiling because the agent *could* run — Trace gets automatic spans for inbound requests, but cross-service propagation and custom spans require you to instrument the code.
---
# Professional Cloud Database Engineer (PCDE) Certification Lab Map
> 📚 **Official exam guide:** [Professional Cloud Database Engineer certification](https://cloud.google.com/learn/certification/cloud-database-engineer) — always confirm section weightings against the current Google Cloud exam guide.
The Professional Cloud Database Engineer certification validates your ability to design, manage, migrate, and deploy scalable, highly available database solutions on Google Cloud. The RAD foundation modules — `Services_GCP`, `App_CloudRun`, `App_GKE`, and `App_Common` — serve as a live lab for the bulk of this exam: `Services_GCP` provisions Cloud SQL (PostgreSQL and MySQL), AlloyDB, Firestore Enterprise, and Memorystore Redis behind a private VPC, while `App_CloudRun` and `App_GKE` demonstrate how real applications connect, authenticate, back up, monitor, and rotate credentials against those databases — all driven by infrastructure-as-code, which is itself the exam's "automate database instance provisioning" objective made concrete.
> **Abbreviation note:** in this repository **PDE** refers to the Professional Cloud **DevOps** Engineer guides. This certification — Professional Cloud **Database** Engineer — uses the abbreviation **PCDE** throughout.
## How to use this guide
- Deploy one of the profiles below through your deployment portal, then work through the matching section guide while the infrastructure is live.
- Each section guide pairs a portal change with what to observe in the GCP console and a real `gcloud`/`psql`/`kubectl` command.
- Use the coverage legend to know which exam topics must be studied outside the platform — Spanner, Bigtable, BigQuery, and Database Migration Service are *not* implemented by these modules, and the section guides say so plainly.
- Destroy or scale down expensive profiles (REGIONAL Cloud SQL, AlloyDB) when you finish a study session.
**Coverage legend**
| Symbol | Meaning |
|---|---|
| ✅ | Fully demonstrated — deploy it, see it, modify it in the RAD platform |
| 🟡 | Partially demonstrated — the modules touch the concept; supplement with docs |
| 📘 | Concept-only — not implemented by the modules; study pointers provided |
## Deployment profiles
### Profile: relational-baseline
*Purpose:* The minimum-cost lab — a zonal private-IP PostgreSQL instance plus a Cloud Run application that connects to it through the Cloud SQL connector volume.
*Modules:* `Services_GCP` + `App_CloudRun`.
| Variable | Value |
|---|---|
| `create_postgres` | `true` (default) |
| `postgres_database_availability_type` | `ZONAL` (default) |
| `postgres_tier` | `db-custom-1-3840` (default) |
| `database_type` (App_CloudRun) | `POSTGRES` (default) |
| `enable_cloudsql_volume` (App_CloudRun) | `true` (default) |
*Estimated incremental cost:* low — one 1-vCPU Cloud SQL Enterprise instance with a 10 GB PD_SSD disk is the dominant cost.
### Profile: ha-production
*Purpose:* Section 1.2 and Section 4 — REGIONAL high availability, a cross-region read replica, CMEK, IAM database authentication, and database alerting.
*Modules:* `Services_GCP` (redeploy/update the baseline).
| Variable | Value |
|---|---|
| `availability_regions` | `["us-central1", "us-east1"]` |
| `subnet_cidr_range` | one CIDR per region, e.g. `["10.0.0.0/24", "10.0.1.0/24"]` |
| `postgres_database_availability_type` | `REGIONAL` |
| `create_postgres_read_replica` | `true` |
| `postgres_read_replica_count` | `1` |
| `enable_cloudsql_iam_auth` | `true` |
| `enable_cmek` | `true` |
| `configure_email_notification` | `true` |
| `notification_alert_emails` | `["you@example.com"]` |
*Estimated incremental cost:* moderate-to-high — REGIONAL roughly doubles the primary's instance cost, and each read replica bills like another primary-sized instance.
### Profile: multi-engine
*Purpose:* Section 1.4 and Section 2 — run PostgreSQL, MySQL, Memorystore Redis, and Firestore Enterprise (MongoDB-compatible) side by side to compare engines.
*Modules:* `Services_GCP`.
| Variable | Value |
|---|---|
| `create_postgres` | `true` (default) |
| `create_mysql` | `true` |
| `create_redis` | `true` |
| `redis_tier` | `STANDARD_HA` |
| `redis_persistence_mode` | `RDB` |
| `create_firestore` | `true` |
*Estimated incremental cost:* moderate — a second Cloud SQL instance plus a STANDARD_HA Redis instance (~2× BASIC); Firestore Enterprise bills per operation and is negligible at lab scale.
### Profile: alloydb-ai
*Purpose:* Sections 1.1, 1.4, and 2.4 — an AlloyDB cluster with a primary and a horizontally scalable read pool, for analytics/vector-workload study.
*Modules:* `Services_GCP`.
| Variable | Value |
|---|---|
| `enable_alloydb` | `true` |
| `alloydb_cpu_count` | `2` (default; allowed: 2, 4, 8, 16, 32, 64) |
| `enable_alloydb_read_pool` | `true` |
| `alloydb_read_pool_node_count` | `1` (default; 1–20) |
*Estimated incremental cost:* high — AlloyDB has no shared-core tier; the 2-vCPU primary plus each read-pool node is the dominant cost. Tear down after each session.
### Profile: app-dataops
*Purpose:* Sections 2.3, 2.5, and 3.1 — scheduled database exports, one-time backup imports, automated password rotation, and database users managed by initialization jobs.
*Modules:* `App_CloudRun` (or `App_GKE`) on top of relational-baseline.
| Variable | Value |
|---|---|
| `database_type` | `POSTGRES` (default) |
| `backup_schedule` | `"0 2 * * *"` (default) |
| `backup_retention_days` | `7` (default) |
| `enable_backup_import` | `true` (after staging a file; see Section 3 guide) |
| `backup_source` / `backup_file` / `backup_format` | `gcs` / `backup.sql` / `sql` |
| `enable_auto_password_rotation` | `true` |
| `secret_rotation_period` | `"2592000s"` (default, 30 days) |
*Estimated incremental cost:* low — Cloud Run jobs, Cloud Scheduler, and Secret Manager versions cost cents; the backup GCS bucket is lifecycle-pruned.
## Section 1: Design innovative, scalable, and highly available cloud database solutions (~32% of the exam)
The heaviest section. `Services_GCP` is the star: every design decision the exam tests — machine tier, zonal vs regional availability, private connectivity, encryption, engine selection — is a variable you can flip and observe.
| Exam topic | Coverage | Where in RAD | Guide |
|---|---|---|---|
| 1.1 Database capacity and usage planning | ✅ | `postgres_tier`, `alloydb_cpu_count`, `redis_memory_size_gb`, disk autoresize | [Section 1 guide](PCDE_Section_1_Exploration_Guide.md#11-analyze-relevant-variables-to-perform-database-capacity-and-usage-planning) |
| 1.2 HA and DR options | ✅ | `postgres_database_availability_type`, `create_postgres_read_replica`, PITR/backup settings, `sql_maintenance_window_day`/`_hour` + `sql_maintenance_update_track` | [Section 1 guide](PCDE_Section_1_Exploration_Guide.md#12-evaluate-database-high-availability-and-disaster-recovery-options-given-the-requirements) |
| 1.3 Application connectivity, encryption, auditing | ✅ | private IP via PSA, `ssl_mode`, `enable_cmek`, `enable_cloudsql_volume`, Auth Proxy sidecar (App_GKE), `enable_audit_logging` (session poolers 📘) | [Section 1 guide](PCDE_Section_1_Exploration_Guide.md#13-determine-how-applications-will-connect-to-the-database) |
| 1.4 Evaluating database solutions (SQL/NoSQL/vector, managed vs unmanaged, gen-AI) | 🟡 | Cloud SQL vs AlloyDB vs Firestore Enterprise (MongoDB compat) vs Redis vs self-managed Redis VM; Spanner/Bigtable/BigQuery 📘 | [Section 1 guide](PCDE_Section_1_Exploration_Guide.md#14-evaluate-appropriate-database-solutions-on-google-cloud) |
## Section 2: Manage a solution that can span multiple database technologies (~25% of the exam)
Day-2 operations: users and IAM, monitoring, backup/recovery, scaling, and automation. The application modules (`App_CloudRun`/`App_GKE`) carry most of this section — db-init jobs, export schedulers, rotation pipelines, and alert policies.
| Exam topic | Coverage | Where in RAD | Guide |
|---|---|---|---|
| 2.1 Connectivity and access management (IAM, database users) | ✅ | `enable_cloudsql_iam_auth`, `roles/cloudsql.instanceUser` grants, the db-init user-creation script, per-secret IAM | [Section 2 guide](PCDE_Section_2_Exploration_Guide.md#21-determine-database-connectivity-and-access-management-considerations) |
| 2.2 Monitoring and troubleshooting | ✅ | Cloud SQL CPU/memory/disk alert policies (Services_GCP), `alert_policies` + `uptime_check_config` in App modules, `enable_query_insights` (Services_GCP); slow-query analysis 📘 | [Section 2 guide](PCDE_Section_2_Exploration_Guide.md#22-configure-database-monitoring-and-troubleshooting-options) |
| 2.3 Backup and recovery (RTO/RPO/PITR, retention) | ✅ | managed backup configuration, PITR + 7-day log retention, export/import jobs, `backup_retention_days` | [Section 2 guide](PCDE_Section_2_Exploration_Guide.md#23-design-database-backup-and-recovery-solutions) |
| 2.4 Cost and performance optimization | ✅ | scale up (`postgres_tier`, `alloydb_cpu_count`) vs out (`postgres_read_replica_count`, `alloydb_read_pool_node_count`), `postgres_database_flags`; query optimization 📘 | [Section 2 guide](PCDE_Section_2_Exploration_Guide.md#24-optimize-database-cost-and-performance) |
| 2.5 Automating common database tasks | ✅ | Cloud Scheduler export job, `db-export` CronJob (GKE), the password-rotation pipeline, scheduled maintenance via `sql_maintenance_window_*`; managed upgrades 📘 | [Section 2 guide](PCDE_Section_2_Exploration_Guide.md#25-automate-common-database-tasks) |
## Section 3: Migrate data solutions (~23% of the exam)
The modules implement the export/import (extended-outage) migration path end to end, but Database Migration Service, Datastream, and continuous replication from external sources are concept-only — budget real study time here.
| Exam topic | Coverage | Where in RAD | Guide |
|---|---|---|---|
| 3.1 Design and implement data migration and replication | 🟡 | `enable_backup_import` + `backup_source` (gcs/gdrive) import jobs, scheduled logical export jobs, `enable_custom_sql_scripts`; DMS / Datastream / zero-downtime migration / reverse replication 📘 | [Section 3 guide](PCDE_Section_3_Exploration_Guide.md#31-design-and-implement-data-migration-and-replication) |
## Section 4: Deploy scalable and highly available databases in Google Cloud (~20% of the exam)
This section is the repository's home turf: "automate database instance provisioning" is literally what these infrastructure-as-code modules do. Deploy the ha-production profile and practice failover, replica scaling, and HA monitoring against real instances.
| Exam topic | Coverage | Where in RAD | Guide |
|---|---|---|---|
| 4.1 Implement scalable and highly available databases (provision HA, test HA/DR, read replicas, automated provisioning, monitoring) | ✅ | `postgres_database_availability_type = REGIONAL`, `postgres_read_replica_count`, `gcloud sql instances failover`, the infrastructure-as-code modules themselves, the Cloud SQL alert policies (cross-region promotion workflow 🟡) | [Section 4 guide](PCDE_Section_4_Exploration_Guide.md#41-apply-concepts-to-implement-scalable-and-highly-available-databases-in-google-cloud) |
---
# PCDE Certification Preparation Guide: Section 1 — Design innovative, scalable, and highly available cloud database solutions (~32% of the exam)
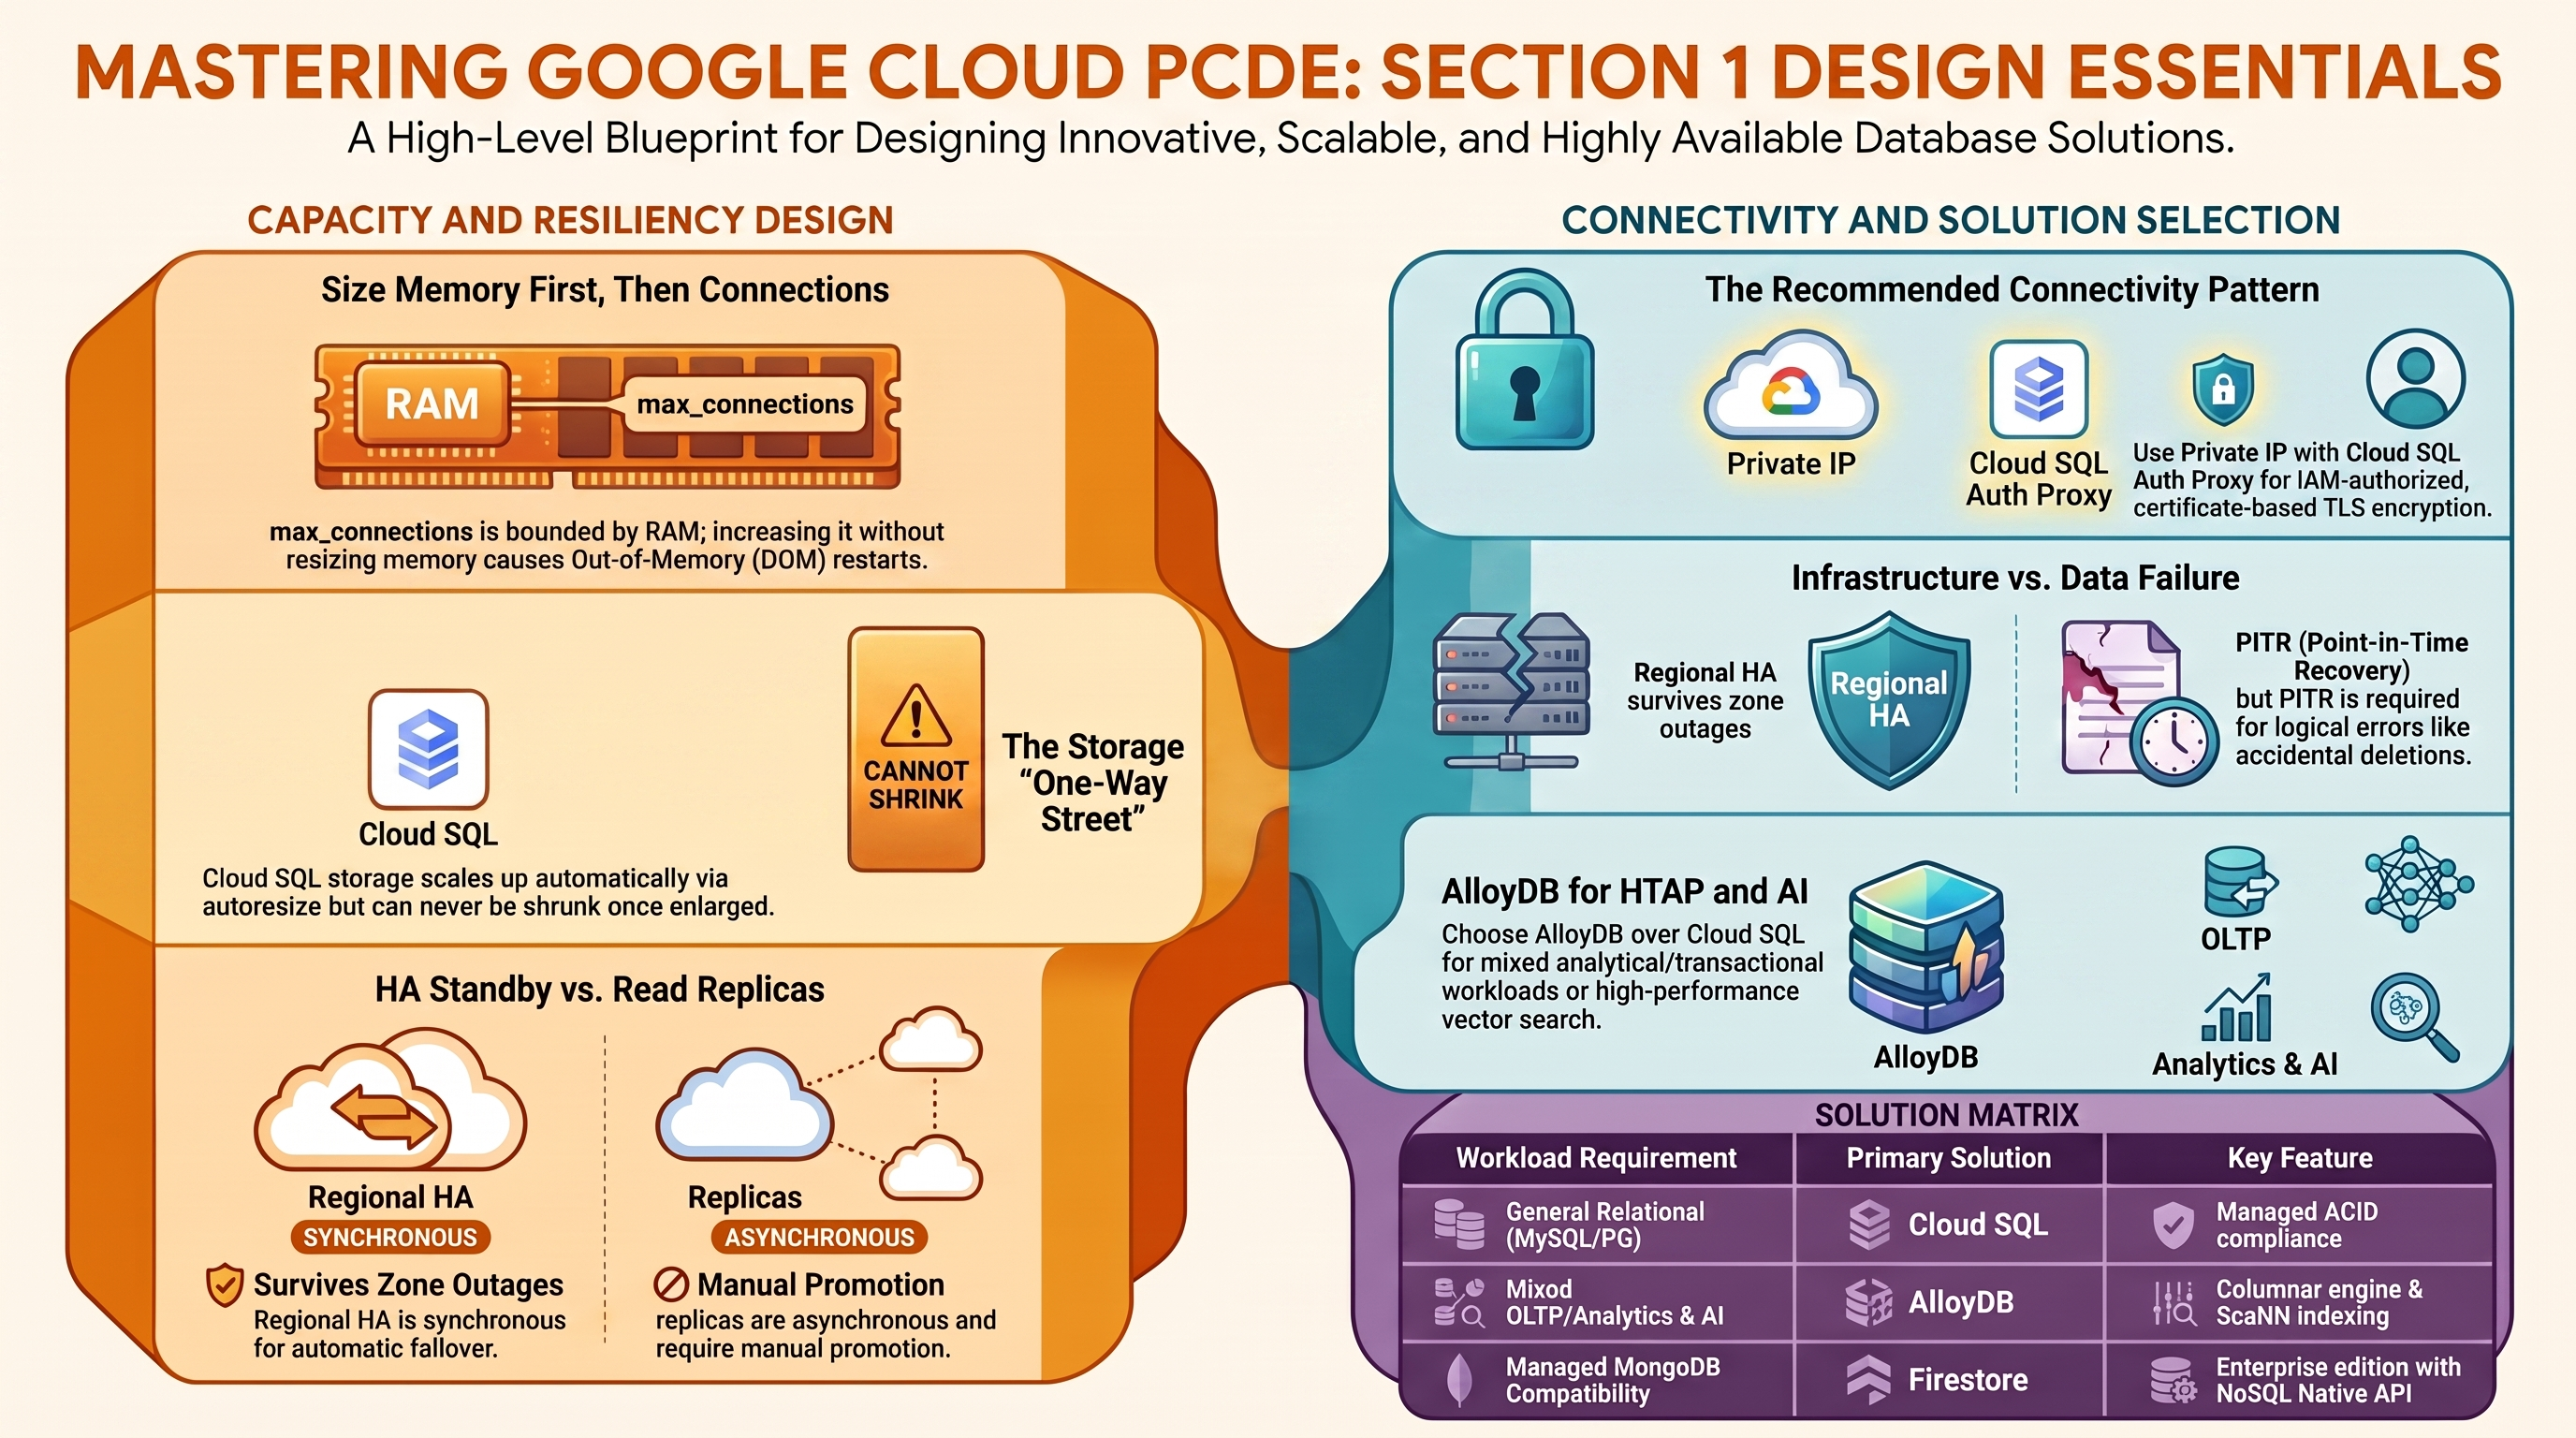 > 📚 **Official exam guide:** [Professional Cloud Database Engineer certification](https://cloud.google.com/learn/certification/cloud-database-engineer) — always confirm section weightings against the current Google Cloud exam guide.
This guide covers Section 1 of the Professional Cloud Database Engineer (PCDE) exam — the largest section, weighted at roughly a third of the questions. It exercises `Services_GCP` (which provisions Cloud SQL PostgreSQL/MySQL, AlloyDB, Firestore Enterprise, and Memorystore Redis) with supporting connectivity patterns from `App_CloudRun` and `App_GKE`. Before starting, deploy the **relational-baseline** profile from the [PCDE Lab Map](PCDE_Certification_Guide.md); subsections 1.2 and 1.4 additionally use the **ha-production**, **multi-engine**, and **alloydb-ai** profiles.
---
## 1.1 Analyze relevant variables to perform database capacity and usage planning
> ⏱ ~45 min · 💰 no additional cost beyond the relational-baseline profile · ⚙️ Requires: default deployment (`create_postgres = true`)
**Why the exam cares** — Capacity questions test whether you can translate workload metrics (connections, working-set size, IOPS, read/write ratio) into a machine tier and storage configuration, and whether you understand the cost consequences: vCPU/RAM drive instance cost linearly, SSD vs HDD trades IOPS for price, and over-provisioned storage cannot be shrunk. Expect scenarios like "the buffer cache hit ratio is low — add memory or add vCPUs?" where the right answer is the cheaper targeted change.
**How RAD implements it** — Sizing is fully parameterized in `Services_GCP`:
| Variable | Default | What it sizes |
|---|---|---|
| `postgres_tier` / `mysql_tier` | `db-custom-1-3840` | Cloud SQL machine: `db-custom--` — the default is 1 vCPU / 3.75 GB |
| `postgres_database_flags` | `[{ name = "max_connections", value = "200" }]` | Connection capacity, tunable per workload |
| `alloydb_cpu_count` | `2` (validated: 2, 4, 8, 16, 32, 64) | AlloyDB primary *and* read-pool node size |
| `redis_memory_size_gb` | `1` (validated 1–300) | Memorystore working-set capacity |
Storage is deliberately *not* a variable: the PostgreSQL instance is fixed to a PD_SSD disk starting at 10 GB with disk autoresize enabled and no upper limit (unlimited), so the disk grows automatically as data arrives — a managed answer to "size storage for growth". The instance edition is fixed to Enterprise. The same shape applies to MySQL.
**Try it**
1. In your deployment portal, change `postgres_tier` from `db-custom-1-3840` to `db-custom-2-7680` (2 vCPU / 7.5 GB) and apply. This is an in-place `PATCH` that restarts the instance.
2. Observe the change in **Console > SQL > cloudsql-\-postgres > Edit > Machine configuration**, then confirm from the CLI:
```bash
gcloud sql instances describe cloudsql--postgres \
--format="table(settings.tier, settings.dataDiskType, settings.dataDiskSizeGb, settings.storageAutoResize)"
```
3. Check the connection ceiling the flag default gives you:
```bash
gcloud sql instances describe cloudsql--postgres \
--format="value(settings.databaseFlags)"
```
4. You know it worked when the describe output shows the new tier and `storageAutoResize: True` with `PD_SSD`.
**Check yourself**
Q1: A reporting workload on a db-custom-1-3840 instance shows 95% memory utilization and frequent disk reads, but CPU sits at 20%. Which single change in this module addresses it most cost-effectively?
A: Change `postgres_tier` to a custom shape with more RAM (e.g. `db-custom-2-13312`) rather than more vCPUs. Cloud SQL custom tiers let you scale memory to enlarge the buffer cache — which converts disk reads to cache hits — without paying for unused CPU. Adding storage or replicas would not fix a working-set-doesn't-fit-in-RAM problem.
Q2: Why does the module enable disk autoresize instead of provisioning a large disk up front, and what is the one-way street you must remember for the exam?
A: Autoresize means you pay only for storage actually used while never hitting a disk-full outage. The trap: Cloud SQL storage can grow but **never shrink** — once autoresize (or a manual edit) enlarges the disk, the only way back to a smaller disk is to export and import into a new instance.
**Beyond the modules** — The modules always use `PD_SSD`; the exam also tests when HDD storage is acceptable (rarely — archival/low-IOPS only) and how per-GB SSD pricing compares to instance pricing. They also fix the Cloud SQL edition to `ENTERPRISE`; study the Enterprise Plus edition (higher per-instance limits, data cache, near-zero-downtime maintenance) in the "Cloud SQL editions" docs page. Practice estimating with the official pricing calculator and `gcloud sql tiers list`.
**⚠️ Exam trap** — `max_connections` is bounded by instance memory: cranking the flag up without resizing the tier causes per-connection memory pressure and OOM restarts. Size memory first, then connections (or use a pooler — see 1.3).
---
## 1.2 Evaluate database high availability and disaster recovery options given the requirements
> ⏱ ~60 min · 💰 REGIONAL roughly doubles instance cost; each replica adds an instance-sized cost · ⚙️ Requires: ha-production profile
**Why the exam cares** — HA and DR questions hinge on matching the *blast radius* a requirement tolerates to the cheapest topology that survives it: zonal (no failover) → regional/HA (synchronous standby in a second zone, same region) → cross-region read replica (asynchronous, survives region loss but needs promotion). You must also know what each option does and does not protect: REGIONAL HA protects against zone failure, not against a bad `DELETE` — that is what PITR is for (see 2.3).
**How RAD implements it** — In `Services_GCP`:
| Variable | Default | Behavior |
|---|---|---|
| `postgres_database_availability_type` | `ZONAL` | Set `REGIONAL` for an HA primary with an automatic-failover standby |
| `mysql_database_availability_type` | `ZONAL` | Same choice for the MySQL instance |
| `create_postgres_read_replica` / `create_mysql_read_replica` | `false` | Adds read replicas (instance type `READ_REPLICA_INSTANCE`) |
| `postgres_read_replica_count` / `mysql_read_replica_count` | `1` | Replica fan-out |
| `availability_regions` | `["us-central1"]` | List ≥2 regions and replicas are placed in `availability_regions[1]` — a **cross-region** DR replica |
Replica placement follows the region list: when two or more regions are configured, replicas land in the second region; otherwise they stay in the primary region. Replicas are always ZONAL, and each replica's private IP is published to Secret Manager as `cloudsql--postgres-replica-host` so applications can split reads. Backups/PITR (the DR time machine) are hardcoded on the primary — see Section 2.3.
Maintenance windows **are** configured on the Cloud SQL instances: `sql_maintenance_window_day` (1–7, Monday-based, default `7` = Sunday), `sql_maintenance_window_hour` (0–23 UTC, default `3`), and `sql_maintenance_update_track` (`"stable"`/`"canary"`/`"week5"`, default `"stable"`) configure the maintenance window on both the PostgreSQL and MySQL primaries. Memorystore Redis similarly pins maintenance to Sunday 02:00 UTC.
**Try it**
1. Apply the ha-production profile (`postgres_database_availability_type = "REGIONAL"`, `create_postgres_read_replica = true`, `availability_regions = ["us-central1", "us-east1"]`).
2. In **Console > SQL**, the primary now shows "High availability (regional)" and a replica `cloudsql--postgres-replica` appears in us-east1. Verify topology:
```bash
gcloud sql instances list \
--format="table(name, region, gceZone, settings.availabilityType, instanceType)"
```
3. Trigger a manual failover (the exam expects you to know this command — it flips the primary to the standby zone):
```bash
gcloud sql instances failover cloudsql--postgres
```
4. You know it worked when `gcloud sql instances describe cloudsql--postgres --format="value(gceZone)"` reports a different zone than before the failover, and the replica still lists `instanceType: READ_REPLICA_INSTANCE` in the secondary region.
**Check yourself**
Q1: A customer requires the database to survive a complete region outage with an RPO of minutes, but reads/writes during normal operation must stay in one region for latency. Which two module settings deliver this, and what manual step remains in a disaster?
A: `postgres_database_availability_type = "REGIONAL"` (zone-level HA with automatic failover) plus `availability_regions = ["primary", "secondary"]` with `create_postgres_read_replica = true` (asynchronous cross-region replica, RPO = replication lag, usually seconds-to-minutes). In a region loss you must still **promote** the replica (`gcloud sql instances promote-replica`) and repoint applications — cross-region failover is not automatic.
Q2: Why is enabling REGIONAL availability alone insufficient for a "we accidentally dropped a table" recovery requirement?
A: The HA standby is a synchronous copy — the `DROP TABLE` is replicated to it instantly. Logical/operator errors are recovered with point-in-time recovery (enabled in this module with 7 days of transaction logs) or backups, not with HA. HA addresses infrastructure failure; PITR addresses data failure.
Q3: Where would you configure when Cloud SQL applies maintenance, and what does this module do about it?
A: Via the instance's maintenance window (`gcloud sql instances patch --maintenance-window-day=SUN --maintenance-window-hour=2`) and optional deny-maintenance periods. This module sets one declaratively — `sql_maintenance_window_day`/`sql_maintenance_window_hour`/`sql_maintenance_update_track` (defaults: Sunday, 03:00 UTC, `stable`) on both engines. For exam purposes know that HA instances get rolling maintenance on the standby first, and that maintenance notifications can be subscribed to per instance.
**Beyond the modules** — Deny-maintenance periods and maintenance notifications are not configured here (the window itself is — see above): practice `gcloud sql instances patch --deny-maintenance-period-start-date/--deny-maintenance-period-end-date` and the "About maintenance on Cloud SQL instances" docs page. Truly multi-regional *write* topologies (Spanner multi-region configurations, AlloyDB secondary clusters with switchover) are also out of scope for these modules — study "Spanner instance configurations" and "AlloyDB cross-region replication" docs.
**⚠️ Exam trap** — A read replica is **not** an HA standby. The REGIONAL standby is synchronous, invisible (no connection string), and fails over automatically; a replica is asynchronous, readable, and must be promoted manually. Questions that say "automatic failover" point to REGIONAL availability, never to replicas.
---
## 1.3 Determine how applications will connect to the database
> ⏱ ~60 min · 💰 no additional cost · ⚙️ Requires: relational-baseline profile (+ optionally `enable_cmek = true`, `enable_audit_logging = true` on Services_GCP)
**Why the exam cares** — Connectivity questions test the decision between private IP, public IP with authorized networks, and the Cloud SQL Auth Proxy/connectors; how encryption is enforced in transit (SSL modes) and at rest (Google-managed vs CMEK); where credentials live; and how access is audited. The Auth Proxy + private IP + Secret Manager combination demonstrated here is Google's recommended production pattern.
**How RAD implements it** — three layers:
*Network path.* The platform allocates a /16 internal range reserved for VPC peering and establishes a private services access (PSA) connection to the Service Networking service. Every database then attaches privately: PostgreSQL and MySQL disable the public IPv4 address and bind to the VPC's private network and allocated range; AlloyDB attaches to the same VPC; Redis uses the VPC as its authorized network with `redis_connect_mode` (default `DIRECT_PEERING`). There is no public IP on any database.
*In-transit encryption.* PostgreSQL enforces SSL mode `ENCRYPTED_ONLY`; MySQL is relaxed to `ALLOW_UNENCRYPTED_AND_ENCRYPTED` (a deliberate engine-by-engine difference worth noticing).
*Application attach + credentials.* In `App_CloudRun`, `enable_cloudsql_volume` (default `true`) mounts a Cloud SQL volume at `cloudsql_volume_mount_path` (default `/cloudsql`) — the managed Cloud Run Cloud SQL connector exposing a Unix socket per connection name. In `App_GKE`, the same flag injects a **Cloud SQL Auth Proxy sidecar** container running with `--private-ip` and the database port. Passwords are randomly generated and stored only in Secret Manager (e.g. `secret-cloudsql--postgres-root-password`); applications receive them via secret references, never plaintext. Key management: `enable_cmek` (default `false`) encrypts the instances with a customer-managed KMS key (rotation period `cmek_key_rotation_period` default `7776000s`). Auditing: `enable_audit_logging` (default `false`) turns on `ADMIN_READ`/`DATA_READ`/`DATA_WRITE` audit logs for all services, which includes the Cloud SQL Admin API.
**Try it**
1. Confirm the instance has no public address and SSL is enforced:
```bash
gcloud sql instances describe cloudsql--postgres \
--format="yaml(ipAddresses, settings.ipConfiguration.sslMode, settings.ipConfiguration.ipv4Enabled)"
```
2. In **Console > Cloud Run > \ > Revisions > Volumes**, find the `cloudsql` volume bound to the instance connection name. On GKE, `kubectl get pod -n -o jsonpath='{.items[0].spec.containers[*].name}'` lists the `cloud-sql-proxy` sidecar.
3. Connect the way an operator would — fetch the root password from Secret Manager and use psql through a Cloud SQL Auth Proxy (the instance is private-IP, so run this from a VM/workstation with VPC access, or inside a GKE pod):
```bash
export PGPASSWORD=$(gcloud secrets versions access latest \
--secret=secret-cloudsql--postgres-root-password)
./cloud-sql-proxy --private-ip ::cloudsql--postgres &
psql -h 127.0.0.1 -U postgres -d postgres -c "SELECT version();"
```
4. You know it worked when psql returns the PostgreSQL 17 version string and the describe output showed `ipv4Enabled: false` with `sslMode: ENCRYPTED_ONLY`.
**Check yourself**
Q1: An application running outside the VPC (a partner data center) must reach this Cloud SQL instance. The instance is private-IP only. What are the legitimate options?
A: Either extend private connectivity (Cloud VPN/Interconnect into the VPC, since PSA-peered ranges are reachable through the VPC with custom route export — which this platform already enables on the peering), or run the Cloud SQL Auth Proxy somewhere with VPC reachability and let the partner connect to it. Enabling public IP plus authorized networks is possible but contradicts the security posture; the exam favors keeping private IP and fixing the network path.
Q2: Why does the GKE module deploy an Auth Proxy sidecar when the database is already on a private IP it could dial directly?
A: The proxy adds IAM-checked, certificate-based TLS without managing client certificates: every connection is authorized against the pod's (Workload Identity) service account and encrypted end-to-end regardless of driver settings. Direct private-IP connections work, but the proxy gives uniform encryption + IAM enforcement + connection name stability across failovers — the Google-recommended pattern the exam expects.
**Beyond the modules** — **Session poolers are not implemented.** Cloud SQL's built-in *Managed Connection Pooling* and the PgBouncer-in-the-middle pattern are exam topics — study "Managed connection pooling" in the Cloud SQL docs, and know when a pooler (thousands of short-lived serverless connections) beats raising `max_connections`. Per-service data-access *audit policies* narrower than this module's allServices switch, and Private Service Connect endpoints for Cloud SQL (as opposed to PSA peering), are also worth a docs pass.
**⚠️ Exam trap** — The Cloud SQL Auth Proxy *authenticates the connection*; it does **not** log the user into the database. You still need either a database password or IAM database authentication (Section 2.1) for the login itself.
---
## 1.4 Evaluate appropriate database solutions on Google Cloud
> ⏱ ~75 min · 💰 moderate-to-high while multi-engine and alloydb-ai profiles are up — tear down after · ⚙️ Requires: multi-engine + alloydb-ai profiles
**Why the exam cares** — Solution-evaluation questions give you workload adjectives — relational, global, wide-column, document, cache, vector/semantic search, analytical — plus constraints (lift-and-shift compatibility, licensing, ops headcount, compliance) and ask which product fits. The discriminators to internalize: compatibility (Cloud SQL/AlloyDB run real PostgreSQL/MySQL), horizontal write scale (Spanner/Bigtable), document model (Firestore), sub-millisecond cache (Memorystore), analytics (BigQuery), and managed-vs-self-managed cost of ownership.
**How RAD implements it** — the platform lets you stand four genuinely different engines side by side, plus one self-managed contrast:
| Engine | Toggle (default) | What to study on it |
|---|---|---|
| Cloud SQL PostgreSQL 17 | `create_postgres` (`true`) | Managed relational default; structured/transactional |
| Cloud SQL MySQL 8.4 | `create_mysql` (`false`) | Engine choice driven by app compatibility (e.g. WordPress-class apps) |
| AlloyDB for PostgreSQL | `enable_alloydb` (`false`) | PostgreSQL-compatible, built for mixed OLTP/analytics and AI — it provides a columnar engine and pgvector-with-ScaNN support; read pool via `enable_alloydb_read_pool` |
| Firestore Enterprise | `create_firestore` (`false`) | Document/semi-structured NoSQL; the platform creates a named Firestore Native database in the Enterprise edition, then enables MongoDB-compatible data access via the REST API — MongoDB wire compatibility for lift-and-shift document apps |
| Memorystore Redis | `create_redis` (`false`) | In-memory cache/session store; tier and persistence tradeoffs |
| Self-managed Redis + NFS VM | `create_network_filesystem` (`true`) | Redis runs on an e2-small managed instance group you patch, snapshot, and health-check yourself — the "unmanaged" half of the managed-vs-unmanaged comparison |
For the generative-AI angle: AlloyDB is the module's designated vector platform, and on Cloud SQL the application modules can install PostgreSQL extensions (including `vector`) through the extensions job that installs them (`CREATE EXTENSION` as the postgres user — see Section 2.5). Regulatory levers that influence engine *configuration* are also here: `enable_cmek`, `enable_audit_logging`, and `enable_vpc_sc` apply uniformly to whichever engines you enable. Note the platform even encodes a real-world multi-engine ops detail: a 120-second delay between creating the two Cloud SQL instances to avoid Service Networking conflicts.
**Try it**
1. Apply the multi-engine profile, then inventory what one project now runs:
```bash
gcloud sql instances list --format="table(name, databaseVersion, region)"
gcloud redis instances list --region=us-central1
gcloud firestore databases list --format="table(name, type, locationId)"
```
2. Apply the alloydb-ai profile and inspect the cluster:
```bash
gcloud alloydb clusters describe alloydb--cluster --region=us-central1
gcloud alloydb instances list --cluster=alloydb--cluster \
--region=us-central1 --format="table(name, instanceType, machineConfig.cpuCount)"
```
3. In **Console > Firestore > Databases**, open the named database (Enterprise edition does not support `(default)` — the module generates `firestore--db` when `firestore_database_id` is empty) and note the MongoDB compatibility setting.
4. You know it worked when the AlloyDB list shows a `PRIMARY` and a `READ_POOL` instance and Firestore shows edition Enterprise in the chosen location.
**Check yourself**
Q1: A team is migrating a MongoDB application to Google Cloud and wants a managed service without rewriting the data access layer. Which option demonstrated by this platform fits, and what is its limitation?
A: Firestore Enterprise with MongoDB-compatible data access (exactly what the platform provisions). It speaks the MongoDB wire protocol against a fully managed backend. Limitations: it must be a *named* database (no `(default)`), and compatibility covers the common driver surface, not every MongoDB feature — verify feature parity before committing, which is itself an exam-style answer.
Q2: When would you pick AlloyDB over Cloud SQL for PostgreSQL, given both are PostgreSQL-compatible and both appear in this module?
A: When the workload mixes OLTP with heavy analytical reads or vector search: AlloyDB adds a columnar engine, ScaNN-indexed pgvector, scale-out read pools (1–20 nodes here), and higher per-instance performance — at a higher floor cost (minimum 2 vCPU, no shared-core tier, as the `alloydb_cpu_count` validation shows). Pure lightweight CRUD on a budget → Cloud SQL; HTAP/AI or aggressive read scaling → AlloyDB.
Q3: The compliance team mandates customer-managed keys and data-access audit trails for every database. Which two variables satisfy this across all engines in the platform, and what org-level concern remains?
A: `enable_cmek = true` (CMEK on Cloud SQL and AlloyDB via the shared `cloudsql` KMS key) and `enable_audit_logging = true` (DATA_READ/DATA_WRITE audit logs for all services). Remaining concern: organization policy constraints (e.g. `constraints/gcp.restrictNonCmekServices`, location restrictions) are *not* managed by these modules — they live at the org/folder level and the exam expects you to know they override anything a project-level module does.
**Beyond the modules** — Not implemented, and all examinable: **Spanner** (horizontal write scaling, external consistency, multi-region configs), **Bigtable** (wide-column, time-series, single-digit-ms at scale), **BigQuery** (analytics; also *federated queries* to Cloud SQL — study `EXTERNAL_QUERY()` for the "multiple database solutions / federation" subtopic), **Memorystore for Memcached**, and **Vertex AI Vector Search** for embedding retrieval beyond pgvector. Try in a scratch project: `gcloud spanner instances create test --config=regional-us-central1 --nodes=1 --description=test` and a BigQuery federated query via `bq query --use_legacy_sql=false 'SELECT * FROM EXTERNAL_QUERY("", "SELECT 1;")'`. For decision practice, the "Google Cloud database options" decision tree page is the single highest-value read.
**⚠️ Exam trap** — "PostgreSQL-compatible" appears three times in the Google catalog: Cloud SQL (actual PostgreSQL), AlloyDB (PostgreSQL-compatible, Google storage engine), and Spanner's PostgreSQL interface (PostgreSQL *dialect*, not wire-compatible with every driver/extension). Questions that mention existing PostgreSQL extensions or exotic drivers usually eliminate Spanner's PG interface.
---
# PCDE Certification Preparation Guide: Section 2 — Manage a solution that can span multiple database technologies (~25% of the exam)
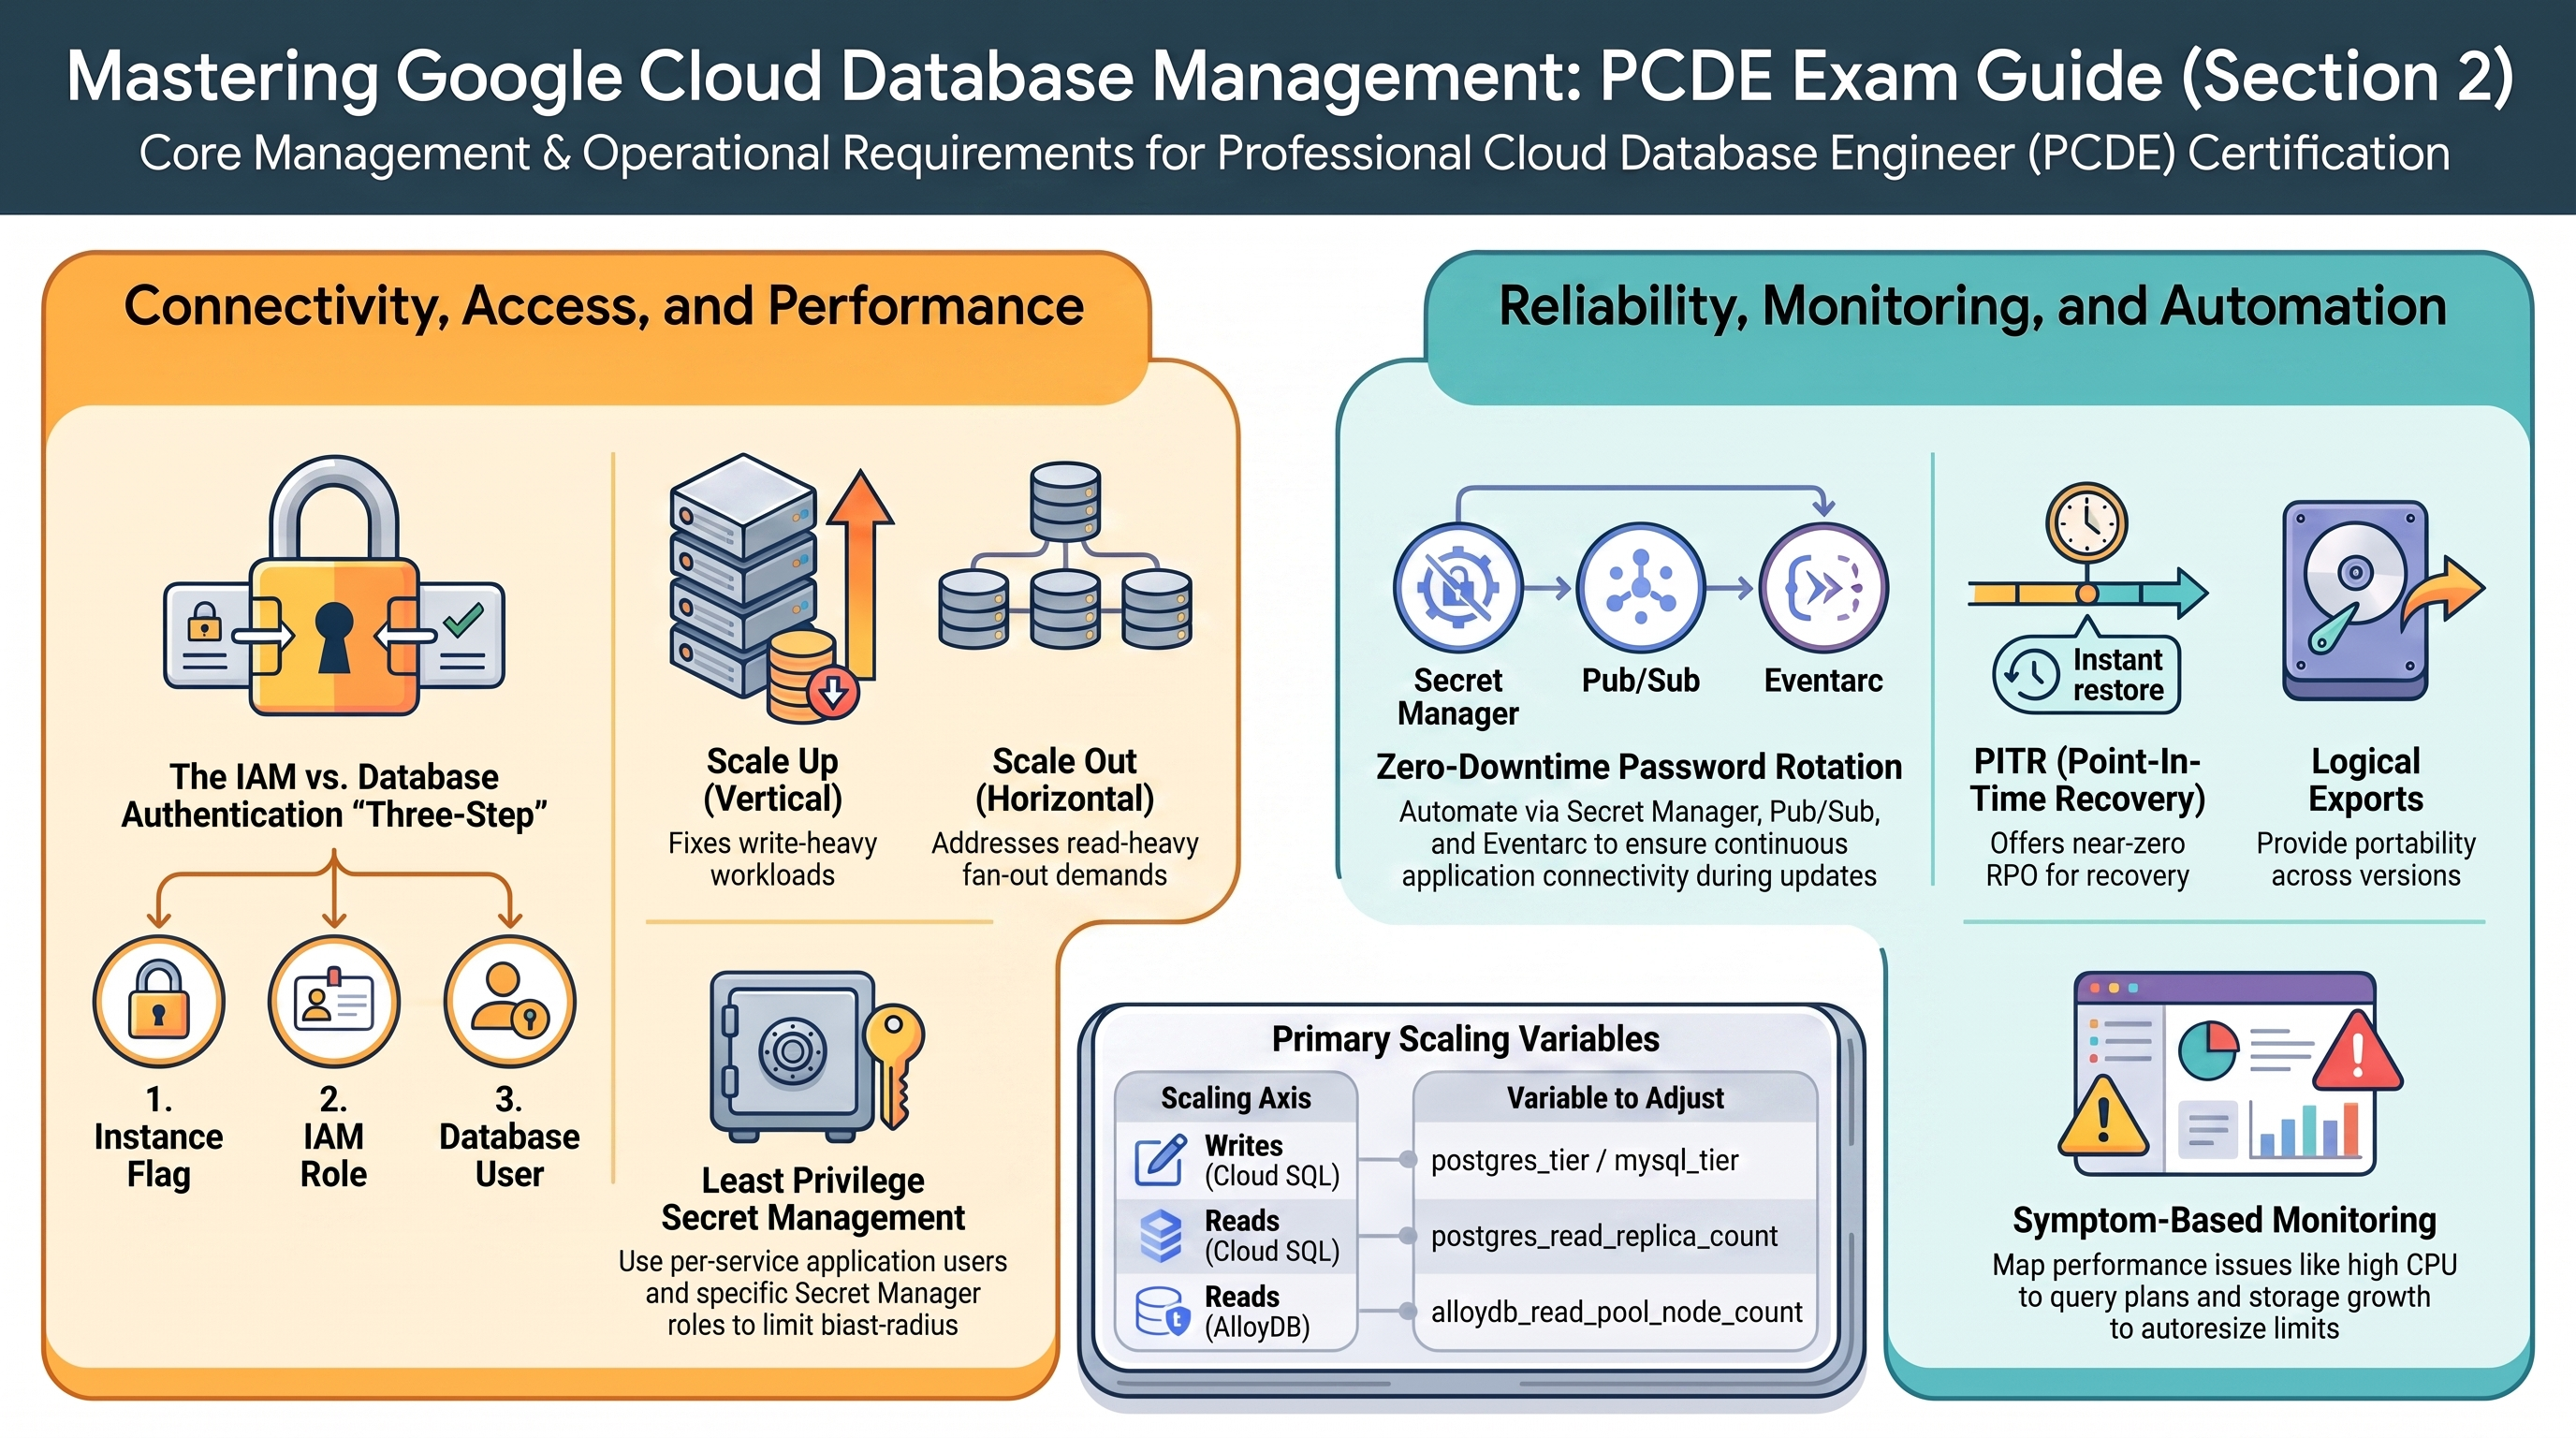 > 📚 **Official exam guide:** [Professional Cloud Database Engineer certification](https://cloud.google.com/learn/certification/cloud-database-engineer) — always confirm section weightings against the current Google Cloud exam guide.
This guide covers Section 2 of the Professional Cloud Database Engineer (PCDE) exam: day-2 management — access control, monitoring, backup/recovery, cost/performance tuning, and task automation. It exercises all four foundation modules: `Services_GCP` (instances, IAM auth, alert policies), `App_CloudRun` and `App_GKE` (database users, export schedulers, rotation jobs), and the `App_Common` submodules and scripts that implement them. Deploy the **relational-baseline** and **app-dataops** profiles from the [PCDE Lab Map](PCDE_Certification_Guide.md) before starting; 2.2 also benefits from the **ha-production** profile's notification settings.
---
## 2.1 Determine database connectivity and access management considerations
> ⏱ ~45 min · 💰 no additional cost · ⚙️ Requires: relational-baseline profile; set `enable_cloudsql_iam_auth = true` on Services_GCP
**Why the exam cares** — The exam separates two layers it loves to conflate in distractors: **IAM** controls who may *reach and administer* the instance (`roles/cloudsql.client`, `roles/cloudsql.instanceUser`, `roles/cloudsql.admin`), while **database users** control what happens *inside* the engine (GRANTs, ownership). IAM database authentication bridges them — short-lived OAuth tokens instead of passwords — and you must know its setup steps and limits.
**How RAD implements it** —
| Mechanism | Where | Detail |
|---|---|---|
| IAM database authentication | Services_GCP | `enable_cloudsql_iam_auth` (default `false`) adds the IAM-auth database flag to the PostgreSQL primary *and* replicas and the MySQL primary, and grants `roles/cloudsql.instanceUser` to the Cloud Run and Cloud Build service accounts |
| Built-in users | Services_GCP | Root password is a 16-char random password, plus an explicit database user resource (`root`@`%` for MySQL — the explicit resource is needed for the MySQL grant model), stored only in Secret Manager (`secret--root-password`) |
| Application users | the db-init job in App_CloudRun / App_GKE | Creates a per-app database user idempotently, creates the database with that user as owner, and applies `GRANT ALL PRIVILEGES ON DATABASE` / `GRANT ALL ON SCHEMA public` (PostgreSQL) or `CREATE USER ''@'%'` + grants (MySQL) |
| App credential | `App_CloudRun`/`App_GKE` `database_password_length` (default `32`, validated 16–64) | Generated password stored as `secret--`; injected via secret references only |
| Secret access IAM | App_Common | Per-secret `roles/secretmanager.secretAccessor` to the runtime SA — least privilege, no project-wide secret access |
Note the engine nuance: the flag *name* differs per engine — PostgreSQL uses `cloudsql.iam_authentication` (dot) while MySQL uses `cloudsql_iam_authentication` (underscore), and the platform sets the underscore form for MySQL. A nice exam-trap nuance: the same feature, two different flag spellings.
**Try it**
1. Set `enable_cloudsql_iam_auth = true` in the portal and apply. Verify the flag and grants:
```bash
gcloud sql instances describe cloudsql--postgres \
--format="value(settings.databaseFlags)"
gcloud projects get-iam-policy \
--flatten="bindings[].members" \
--filter="bindings.role:roles/cloudsql.instanceUser" \
--format="value(bindings.members)"
```
2. Add an IAM database user (the flag alone does not create one — a deliberate two-step the exam tests):
```bash
gcloud sql users create cloudrun-sa-@.iam.gserviceaccount.com \
--instance=cloudsql--postgres --type=cloud_iam_service_account
gcloud sql users list --instance=cloudsql--postgres \
--format="table(name, type)"
```
3. In **Console > SQL > \ > Users**, observe the built-in `postgres`/`root` user, the application user created by the `db-init` job, and your new `CLOUD_IAM_SERVICE_ACCOUNT` user.
4. You know it worked when `gcloud sql users list` shows the IAM principal with type `CLOUD_IAM_SERVICE_ACCOUNT` and the flags output contains `cloudsql.iam_authentication=on`.
**Check yourself**
Q1: After enabling enable_cloudsql_iam_auth, a service account still cannot log in with an IAM token. The flag is on and roles/cloudsql.instanceUser is granted. What is missing?
A: The database user itself. IAM authentication requires three things: the instance flag, the IAM role, *and* a database user of type `CLOUD_IAM_SERVICE_ACCOUNT` (or `CLOUD_IAM_USER`) created on the instance — plus in-database GRANTs on the objects it needs. The module automates the first two; the user creation is the step candidates forget.
Q2: Why does the platform generate a separate 32-character application user per service instead of letting applications connect as root?
A: Least privilege and blast-radius control: the app user owns only its own database (the `db-init` job grants per-database privileges), its password is scoped to one secret with per-secret `secretAccessor` IAM, and it can be rotated (2.5) without touching other tenants. Root credentials in app code is a standard wrong-answer pattern on the exam.
**Beyond the modules** — IAM **group** authentication for Cloud SQL is not exercised here; read "IAM authentication" for both engines. Also study `gcloud sql generate-login-token` and the Auth Proxy `--auto-iam-authn` flag, which together replace passwords entirely.
**⚠️ Exam trap** — `roles/cloudsql.client` lets a principal *connect through* the proxy/connector; `roles/cloudsql.instanceUser` is what IAM *login* requires. Distractors swap them.
---
## 2.2 Configure database monitoring and troubleshooting options
> ⏱ ~45 min · 💰 negligible (alerting/log volume) · ⚙️ Requires: relational-baseline + `configure_email_notification = true`, `notification_alert_emails` set on Services_GCP
**Why the exam cares** — You are expected to map symptoms to signals: high CPU → query plans/missing indexes, high memory → working set/connection count, storage growth → autoresize headroom and log retention, lock waits → contention views (`pg_stat_activity`, `INFORMATION_SCHEMA.INNODB_TRX`), and to wire alerting *before* the incident. Questions also cover Query Insights and audit logs as diagnostic sources, and quota exhaustion (connections, storage) as a failure class.
**How RAD implements it** — `Services_GCP` creates three database alert policies, all filtered to `resource.type = "cloudsql_database"`:
| Policy | Metric | Threshold variable (default) |
|---|---|---|
| `[prefix] Cloud SQL - High CPU Usage` | `cloudsql.googleapis.com/database/cpu/utilization` | `alert_cpu_threshold` (`80`) |
| `[prefix] Cloud SQL - High Memory Usage` | `cloudsql.googleapis.com/database/memory/utilization` | `alert_memory_threshold` (`80`) |
| `[prefix] Cloud SQL - High Disk Usage` | `cloudsql.googleapis.com/database/disk/utilization` | `alert_disk_threshold` (`80`) |
Notifications fan out to email channels built from `configure_email_notification` (default `false`) + `notification_alert_emails`. The application modules add the workload side: `alert_policies` (a list of `{name, metric_type, comparison, threshold_value, duration_seconds, aggregation_period}` objects, default `[]`) in `App_CloudRun`, plus a monitoring dashboard. `uptime_check_config` (default `{ enabled = false, path = "/" }`) creates a `-uptime-check` synthetic probe plus a failure alert policy, once enabled, whenever the application endpoint is publicly reachable — symptom-based monitoring of the database-backed service from outside. On the database itself, `enable_query_insights` (Services_GCP, default `false`) adds an `insights_config` block (query strings recorded up to 1024 chars) to both the PostgreSQL and MySQL primaries, lighting up **Console > SQL > Query insights** with per-query load and plans. For audit-trail troubleshooting, `enable_audit_logging` (Services_GCP, default `false`) records ADMIN_READ/DATA_READ/DATA_WRITE. Slow-query capture is *available* through the flag mechanism — the `postgres_database_flags` variable's own example shows `log_min_duration_statement = 1000` — but no slow-query flag is set by default.
**Try it**
1. Enable email notification in the portal, apply, then confirm the policies exist:
```bash
gcloud alpha monitoring policies list \
--filter='displayName:"Cloud SQL"' --format="table(displayName, enabled)"
```
2. Add a slow-query flag the way a DBA would, via `postgres_database_flags`: append `{ name = "log_min_duration_statement", value = "1000" }` in the portal and apply (this restarts the instance). Then generate a slow query through psql (`SELECT pg_sleep(2);`) and read it back:
```bash
gcloud logging read \
'resource.type="cloudsql_database" AND logName:"postgres.log" AND textPayload:"duration"' \
--limit=5 --freshness=1h
```
3. In **Console > SQL > \ > System insights**, correlate CPU, memory, connections, and disk during your test load. Then set `enable_query_insights = true`, apply, and open **Query insights** on the same instance to see per-query load and captured query text.
4. You know it worked when the three alert policies list as enabled, your `pg_sleep` statement appears in the postgres log with its duration, and Query insights starts charting query load.
**Check yourself**
Q1: Users report intermittent application timeouts. Cloud SQL CPU is at 30%, memory at 50%, but active connections spike to exactly 200 during incidents. What is happening and what are two fixes demonstrated or discussed in this platform?
A: The instance is hitting the `max_connections=200` flag default — a quota/limit problem, not a resource problem; new connections queue or fail. Fixes: raise the flag via `postgres_database_flags` after sizing memory for it, or reduce connection demand with pooling (Cloud SQL managed connection pooling / PgBouncer — a "Beyond the modules" topic from 1.3). Scaling CPU would not help, a classic distractor.
Q2: Which signal tells you an index is missing — and where would you look on a Cloud SQL instance?
A: Sustained high CPU and read IOPS with slow specific queries; confirm with Query Insights (per-query load, plans) or `EXPLAIN ANALYZE` showing sequential scans on large tables. In this lab you'd capture candidates via `log_min_duration_statement`, then `EXPLAIN` them in psql. The fix is `CREATE INDEX`, not a bigger tier — the exam rewards diagnosing before resizing.
**Beyond the modules** — Query Insights' *advanced* features (tagged query attribution via SQL commenter, longer retention) and the `gcloud` equivalent (`gcloud sql instances patch --insights-config-query-insights-enabled`) are worth knowing alongside the module's `enable_query_insights` toggle. Locking diagnosis (`pg_locks`, `pg_stat_activity.wait_event`, MySQL `SHOW ENGINE INNODB STATUS`) and Cloud SQL quotas/limits (connections per tier, 64 TB storage cap) are pure-docs topics here.
**⚠️ Exam trap** — `database/disk/utilization` alerts at 80% can be a non-event on this platform because `disk_autoresize = true` grows the disk first — but autoresize **cannot** help when you hit the storage *quota* or when growth is caused by unpurged WAL/binlogs from a broken replica. Know the difference between "disk almost full" and "disk growing without bound."
---
## 2.3 Design database backup and recovery solutions
> ⏱ ~60 min · 💰 low — backup storage + a small GCS bucket · ⚙️ Requires: relational-baseline + app-dataops profiles
**Why the exam cares** — Backup questions are RTO/RPO arithmetic: automated daily backups give an RPO of up to 24 h; PITR (transaction logs) shrinks RPO to seconds within the log-retention window; exports (`pg_dump`/`mysqldump`) are portable but slow (long RTO) and are the only cross-version/cross-product option. Retention is both a compliance and a cost lever.
**How RAD implements it** — Three independent layers:
*Managed backups + PITR* (Services_GCP): the PostgreSQL primary is fixed to enabled automated backups with point-in-time recovery on, 7 days of transaction-log retention, 7 retained backups (count-based), a 04:00 start time, and the backup location set to the primary region. MySQL keeps 7 daily backups at 04:00 and enables binary logging — the binlog mechanism MySQL PITR relies on — but sets no PITR-specific attribute. AlloyDB gets a weekly automated backup (Sunday 04:00 UTC, a one-hour backup window, quantity-based retention of 7). Redis persistence is opt-in (`redis_persistence_mode`, default `DISABLED`; `RDB` with `redis_rdb_snapshot_period` default `ONE_HOUR`, or `AOF` — STANDARD_HA tier only), but *enforced* for production: a plan-time precondition rejects `DISABLED` persistence on a `STANDARD_HA` instance labeled `environment = "production"`.
*Logical exports* (App_CloudRun, App_GKE): a `db-clients` job image (Debian 12 with `postgresql-client-14`–`17` and the MySQL 8.0 client, built by `App_Common`) runs the export script, which picks a *version-matched* `pg_dump`/`mysqldump` and writes `backup-.tar.gz` to the dedicated GCS backup bucket. Scheduling is `backup_schedule` (default `"0 2 * * *"`); bucket retention is `backup_retention_days` (default `7`) via an object lifecycle delete rule.
*Imports / restore drills*: `enable_backup_import` (default `false`) runs a one-time `-backup-import` job restoring `backup_file` (default `backup.sql`, formats `sql,tar,gz,tgz,tar.gz,zip,auto`) from `backup_source` — `gcs` (the backup bucket) or `gdrive`.
**Try it**
1. List the automated backups Terraform configured, then take an on-demand one:
```bash
gcloud sql backups list --instance=cloudsql--postgres
gcloud sql backups create --instance=cloudsql--postgres \
--description="pre-change safety backup"
```
2. Rehearse PITR the safe way — clone to a *new* instance at a timestamp (UTC, within the 7-day log window):
```bash
gcloud sql instances clone cloudsql--postgres pitr-drill-1 \
--point-in-time "2026-06-10T03:00:00Z"
```
3. Trigger the logical export immediately instead of waiting for 02:00 UTC, then verify the artifact: **Console > Cloud Storage > \**.
```bash
gcloud scheduler jobs run -backup-schedule --location=us-central1
gcloud storage ls gs:///
```
4. You know it worked when the clone instance reaches RUNNABLE with data as of your timestamp and a fresh `backup-.tar.gz` object exists in the bucket.
**Check yourself**
Q1: A developer dropped a table at 14:32. The platform's defaults are in place. What is your recovery path and your data loss?
A: Use PITR: clone the instance to a new instance at 14:31 (`gcloud sql instances clone --point-in-time`), then copy the table back or repoint the app. Data loss ≈ one minute (whatever you choose to discard), because transaction logs are retained 7 days. Restoring last night's 04:00 backup *without* PITR would lose ~10.5 hours — the distractor answer.
Q2: Compliance requires backups to survive a region-wide disaster. Does the module's configuration satisfy this, and what would you change?
A: Not fully: `backup_configuration.location` is set to the primary region, so managed backups live in that region (the GCS export bucket adds a second copy, but also regional by default). To survive region loss you would set a multi-region or different-region backup location, replicate the export bucket (dual/multi-region storage), and/or keep the cross-region read replica from 1.2. The exam expects you to notice backup *location* as part of DR design.
Q3: When is a pg_dump-based export the right recovery/migration tool instead of managed backups?
A: When you need portability: restoring into a different major version, a different product (AlloyDB, self-managed PG), another project/org, or keeping long-term archives independent of the instance's lifecycle (managed backups are deleted with the instance). The cost is RTO — logical restore is far slower than backup restore — and consistency is as-of dump start.
**Beyond the modules** — Cross-project backup restore, `gcloud sql export sql` (the *serverless* managed export to GCS, distinct from this module's job-based `pg_dump`), final backups on instance deletion, and Backup and DR Service for long-horizon retention are docs-only topics. Try `gcloud sql export sql cloudsql--postgres gs:///managed-export.sql --database=postgres` in a scratch project and compare it with the job-based export.
**⚠️ Exam trap** — Backups ≠ PITR. Retained backups (7 here) bound how far *back* you can restore; transaction-log retention (7 days here) bounds how *precisely*. Also: restoring in place overwrites the instance — clone to a new instance for investigations.
---
## 2.4 Optimize database cost and performance
> ⏱ ~45 min · 💰 experiments scale cost up — revert when done · ⚙️ Requires: relational-baseline; ha-production and alloydb-ai for scale-out
**Why the exam cares** — "Scale up or scale out?" is the section's signature question: vertical scaling (bigger tier) fixes CPU/memory-bound *write* workloads but has a ceiling and a restart; horizontal read scaling (replicas/read pools) fixes read-heavy fan-out but does nothing for writes and introduces replication lag. Cost questions test right-sizing, committed-use thinking, and knowing which HA/replica choices double spend.
**How RAD implements it** — every scaling axis is one variable:
| Axis | Variable | Notes |
|---|---|---|
| Scale up (writes) | `postgres_tier` / `mysql_tier` / `alloydb_cpu_count` | In-place patch; brief restart |
| Scale out (reads), Cloud SQL | `create_postgres_read_replica` + `postgres_read_replica_count` (default `1`) | Replica private IPs published as `-host` secrets so apps can route reads; replicas get a fixed `max_connections=30000` flag |
| Scale out (reads), AlloyDB | `enable_alloydb_read_pool` + `alloydb_read_pool_node_count` (1–20) | One endpoint load-balanced across nodes — no per-replica routing needed |
| Engine tuning | `postgres_database_flags` / `mysql_database_flags` / `alloydb_database_flags` | Defaults: `max_connections=200` (PG), `max_connections=200` + `local_infile=off` (MySQL) |
| Cost floor | `ZONAL` default availability, `BASIC` default Redis tier, 10 GB autoresizing disk | The defaults *are* the cost-optimization lesson: HA, replicas, STANDARD_HA Redis, and CMEK are opt-in |
The Redis plan-time preconditions are a governance example: deployments labeled `environment = "production"` are blocked from `BASIC` tier at plan time, and a second precondition blocks `redis_persistence_mode = "DISABLED"` on a production `STANDARD_HA` instance — cheap-but-fragile configurations are disallowed exactly where an SLA exists.
**Try it**
1. With ha-production applied, raise read capacity without touching the primary:
```bash
# portal: postgres_read_replica_count = 2, then verify
gcloud sql instances list --filter="name:replica" \
--format="table(name, region, settings.tier, state)"
```
2. Read the replica endpoint an application would use:
```bash
gcloud secrets versions access latest \
--secret=cloudsql--postgres-replica-host
```
3. Measure replication health before trusting reads — in psql against the **primary**:
```bash
psql -h 127.0.0.1 -U postgres -d postgres \
-c "SELECT client_addr, state, replay_lag FROM pg_stat_replication;"
```
4. You know it worked when both replicas show RUNNABLE and `pg_stat_replication` lists them with small `replay_lag`.
**Check yourself**
Q1: An e-commerce database is write-saturated during flash sales (CPU 95%, all from INSERT/UPDATE). The team proposes adding two read replicas. Why is that wrong, and what is right?
A: Replicas only serve reads — every write is still replayed on the primary *and* on each replica, so write saturation persists (and replicas may lag). The correct first move is vertical: a larger `postgres_tier`. If writes outgrow the largest tier, that is the exam's cue for re-architecture (sharding or Spanner), not more replicas.
Q2: What recurring cost do you take on per unit when you change postgres_read_replica_count from 1 to 3, and what operational cost comes with it?
A: Each replica bills like an instance of the primary's tier (`postgres_tier` is reused in the replica settings) plus its own storage — 3 replicas ≈ 3 extra primaries. Operationally, applications must consume the per-replica `-host` secrets and tolerate asynchronous lag; replicas are not free HA (they are ZONAL and must be promoted manually).
**Beyond the modules** — Query optimization itself (EXPLAIN plans, index design, Query Insights recommendations) has no module surface — practice on the lab instance with `EXPLAIN (ANALYZE, BUFFERS)`. Continuous cost optimization tooling — committed use discounts for Cloud SQL, the Active Assist idle/overprovisioned instance recommenders, per-database billing labels in billing exports — is console/docs work: check **Console > SQL > Recommendations** in any long-lived project.
**⚠️ Exam trap** — Changing the tier restarts the instance (downtime ≈ seconds-to-minutes, or a failover on REGIONAL instances). "Resize during the maintenance window with HA enabled" beats "resize whenever" in scenario answers.
---
## 2.5 Automate common database tasks
> ⏱ ~60 min · 💰 low — jobs, scheduler, secret versions · ⚙️ Requires: app-dataops profile (`enable_auto_password_rotation = true`)
**Why the exam cares** — The exam wants operations expressed as scheduled, auditable automation rather than humans with psql: scheduled exports, credential rotation, post-provision initialization, and SLO-based health monitoring. Knowing *which* GCP primitive schedules what (Cloud Scheduler → Cloud Run jobs; Kubernetes CronJobs; Secret Manager rotation topics → Eventarc) is the testable content.
**How RAD implements it** — four automations, all observable in the console:
1. **Scheduled exports.** Cloud Run path: a Cloud Scheduler job (App_CloudRun) POSTs to the Cloud Run Jobs `:run` API with the runtime SA's OAuth token, on `backup_schedule` (default `"0 2 * * *"`), executing the `-db-export` job. GKE path: a Kubernetes CronJob (App_GKE), name `-db-export`, concurrency policy `Forbid`, history limits 3/3, script delivered via ConfigMap.
2. **Automated password rotation.** `enable_auto_password_rotation` (default `false`) wires Secret Manager's `rotation_period` (`secret_rotation_period`, default `"2592000s"` = 30 days) → Pub/Sub rotation topic → Eventarc trigger (`-pw-rot-trigger`) → a dispatcher Cloud Run service (`-rot-dispatch`) → the `-pw-rotator` job (App_Common). The rotator: generates a new password, runs `ALTER USER`, adds the new secret **version**, waits a propagation delay, then *disables* (not destroys) the old version — dual-version, zero-downtime, rollback-capable.
3. **Initialization & schema tasks.** The `db-init` job creates the database and user on every deploy (idempotent); `enable_custom_sql_scripts` + `custom_sql_scripts_bucket`/`custom_sql_scripts_path` runs `.sql` files from GCS in lexicographic order (optionally as root via `custom_sql_scripts_use_root`); PostgreSQL extension and MySQL plugin install jobs install the configured extensions/plugins — note that in a standalone foundation-module deployment the `enable_postgres_extensions`/`postgres_extensions` variables are validation-only, with the actual lists injected by application wrapper modules.
4. **SLO-adjacent monitoring.** `alert_policies` provides availability and latency alerting on the database-backed service, and `uptime_check_config` adds a `-uptime-check` synthetic probe plus failure alert for publicly reachable endpoints — external SLI data with no manual setup.
5. **Scheduled maintenance.** `sql_maintenance_window_day` (1–7, Monday-based, default `7` = Sunday), `sql_maintenance_window_hour` (0–23 UTC, default `3`), and `sql_maintenance_update_track` (`"stable"`/`"canary"`/`"week5"`, default `"stable"`) pin Cloud SQL maintenance to a predictable low-traffic window on both the PostgreSQL and MySQL primaries — patching becomes a declared, scheduled operation instead of Google-chosen timing.
**Try it**
1. Inspect the rotation plumbing after applying app-dataops: **Console > Security > Secret Manager > secret-\-\ > Rotation**, and:
```bash
gcloud scheduler jobs list --location=us-central1
gcloud run jobs list --region=us-central1 # -db-export, -db-init, -pw-rotator
```
2. Force a rotation rehearsal by executing the rotator job directly, then confirm the version flip:
```bash
gcloud run jobs execute -pw-rotator --region=us-central1 --wait
gcloud secrets versions list secret-cloudsql--postgres- \
--format="table(name, state)"
```
3. Prove the app still authenticates: connect with the *new* latest version via psql (`PGPASSWORD=$(gcloud secrets versions access latest --secret=...) psql -h -U -d -c "SELECT 1;"`).
4. On GKE, run tomorrow's export now:
```bash
kubectl create job --from=cronjob/-db-export manual-export -n
kubectl logs -n job/manual-export -f
```
5. You know it worked when the secret shows a new ENABLED version with the prior one DISABLED, and the export job log ends with an upload to the backup bucket.
**Check yourself**
Q1: During rotation, why does the platform disable the old secret version only after a propagation delay instead of immediately destroying it?
A: Zero-downtime and rollback. Running instances may hold the old password in memory or fetch "latest" mid-rotation; the delay lets the new version propagate before "latest" becomes unambiguous, and disabling (rather than destroying) keeps the old version recoverable for rollback/audit. Destroying immediately risks authentication failures across the fleet — the exam's "what breaks" answer.
Q2: A team needs nightly logical backups of a GKE-hosted database with a guarantee that two exports never run concurrently. Which Kubernetes settings shown in this module deliver that?
A: A CronJob with `schedule` (the module's `backup_schedule`) and `concurrencyPolicy: Forbid` — exactly what the module's db-export CronJob sets — plus bounded history (`successful/failedJobsHistoryLimit = 3`) and `restartPolicy: OnFailure` with a backoff limit so a stuck export cannot pile up.
**Beyond the modules** — Two 2.5 topics have no implementation here: **index maintenance** (`REINDEX`/`pg_repack`, MySQL `OPTIMIZE TABLE` — you could schedule them through `enable_custom_sql_scripts`, but nothing ships) and **managed upgrades** — there is no automation for major version upgrades; study in-place upgrades (`gcloud sql instances patch --database-version=POSTGRES_18` once available, plus the pre-upgrade checks) and Cloud SQL maintenance/patching behavior. Formal SLOs (error budgets, `gcloud monitoring` SLO API) also live outside the modules.
**⚠️ Exam trap** — Secret Manager's `rotation_period` only *publishes a Pub/Sub notification* — nothing rotates unless something consumes it. This platform's Eventarc→dispatcher→job chain is that consumer; an answer that says "enable rotation on the secret and you're done" is wrong.
---
# PCDE Certification Preparation Guide: Section 3 — Migrate data solutions (~23% of the exam)
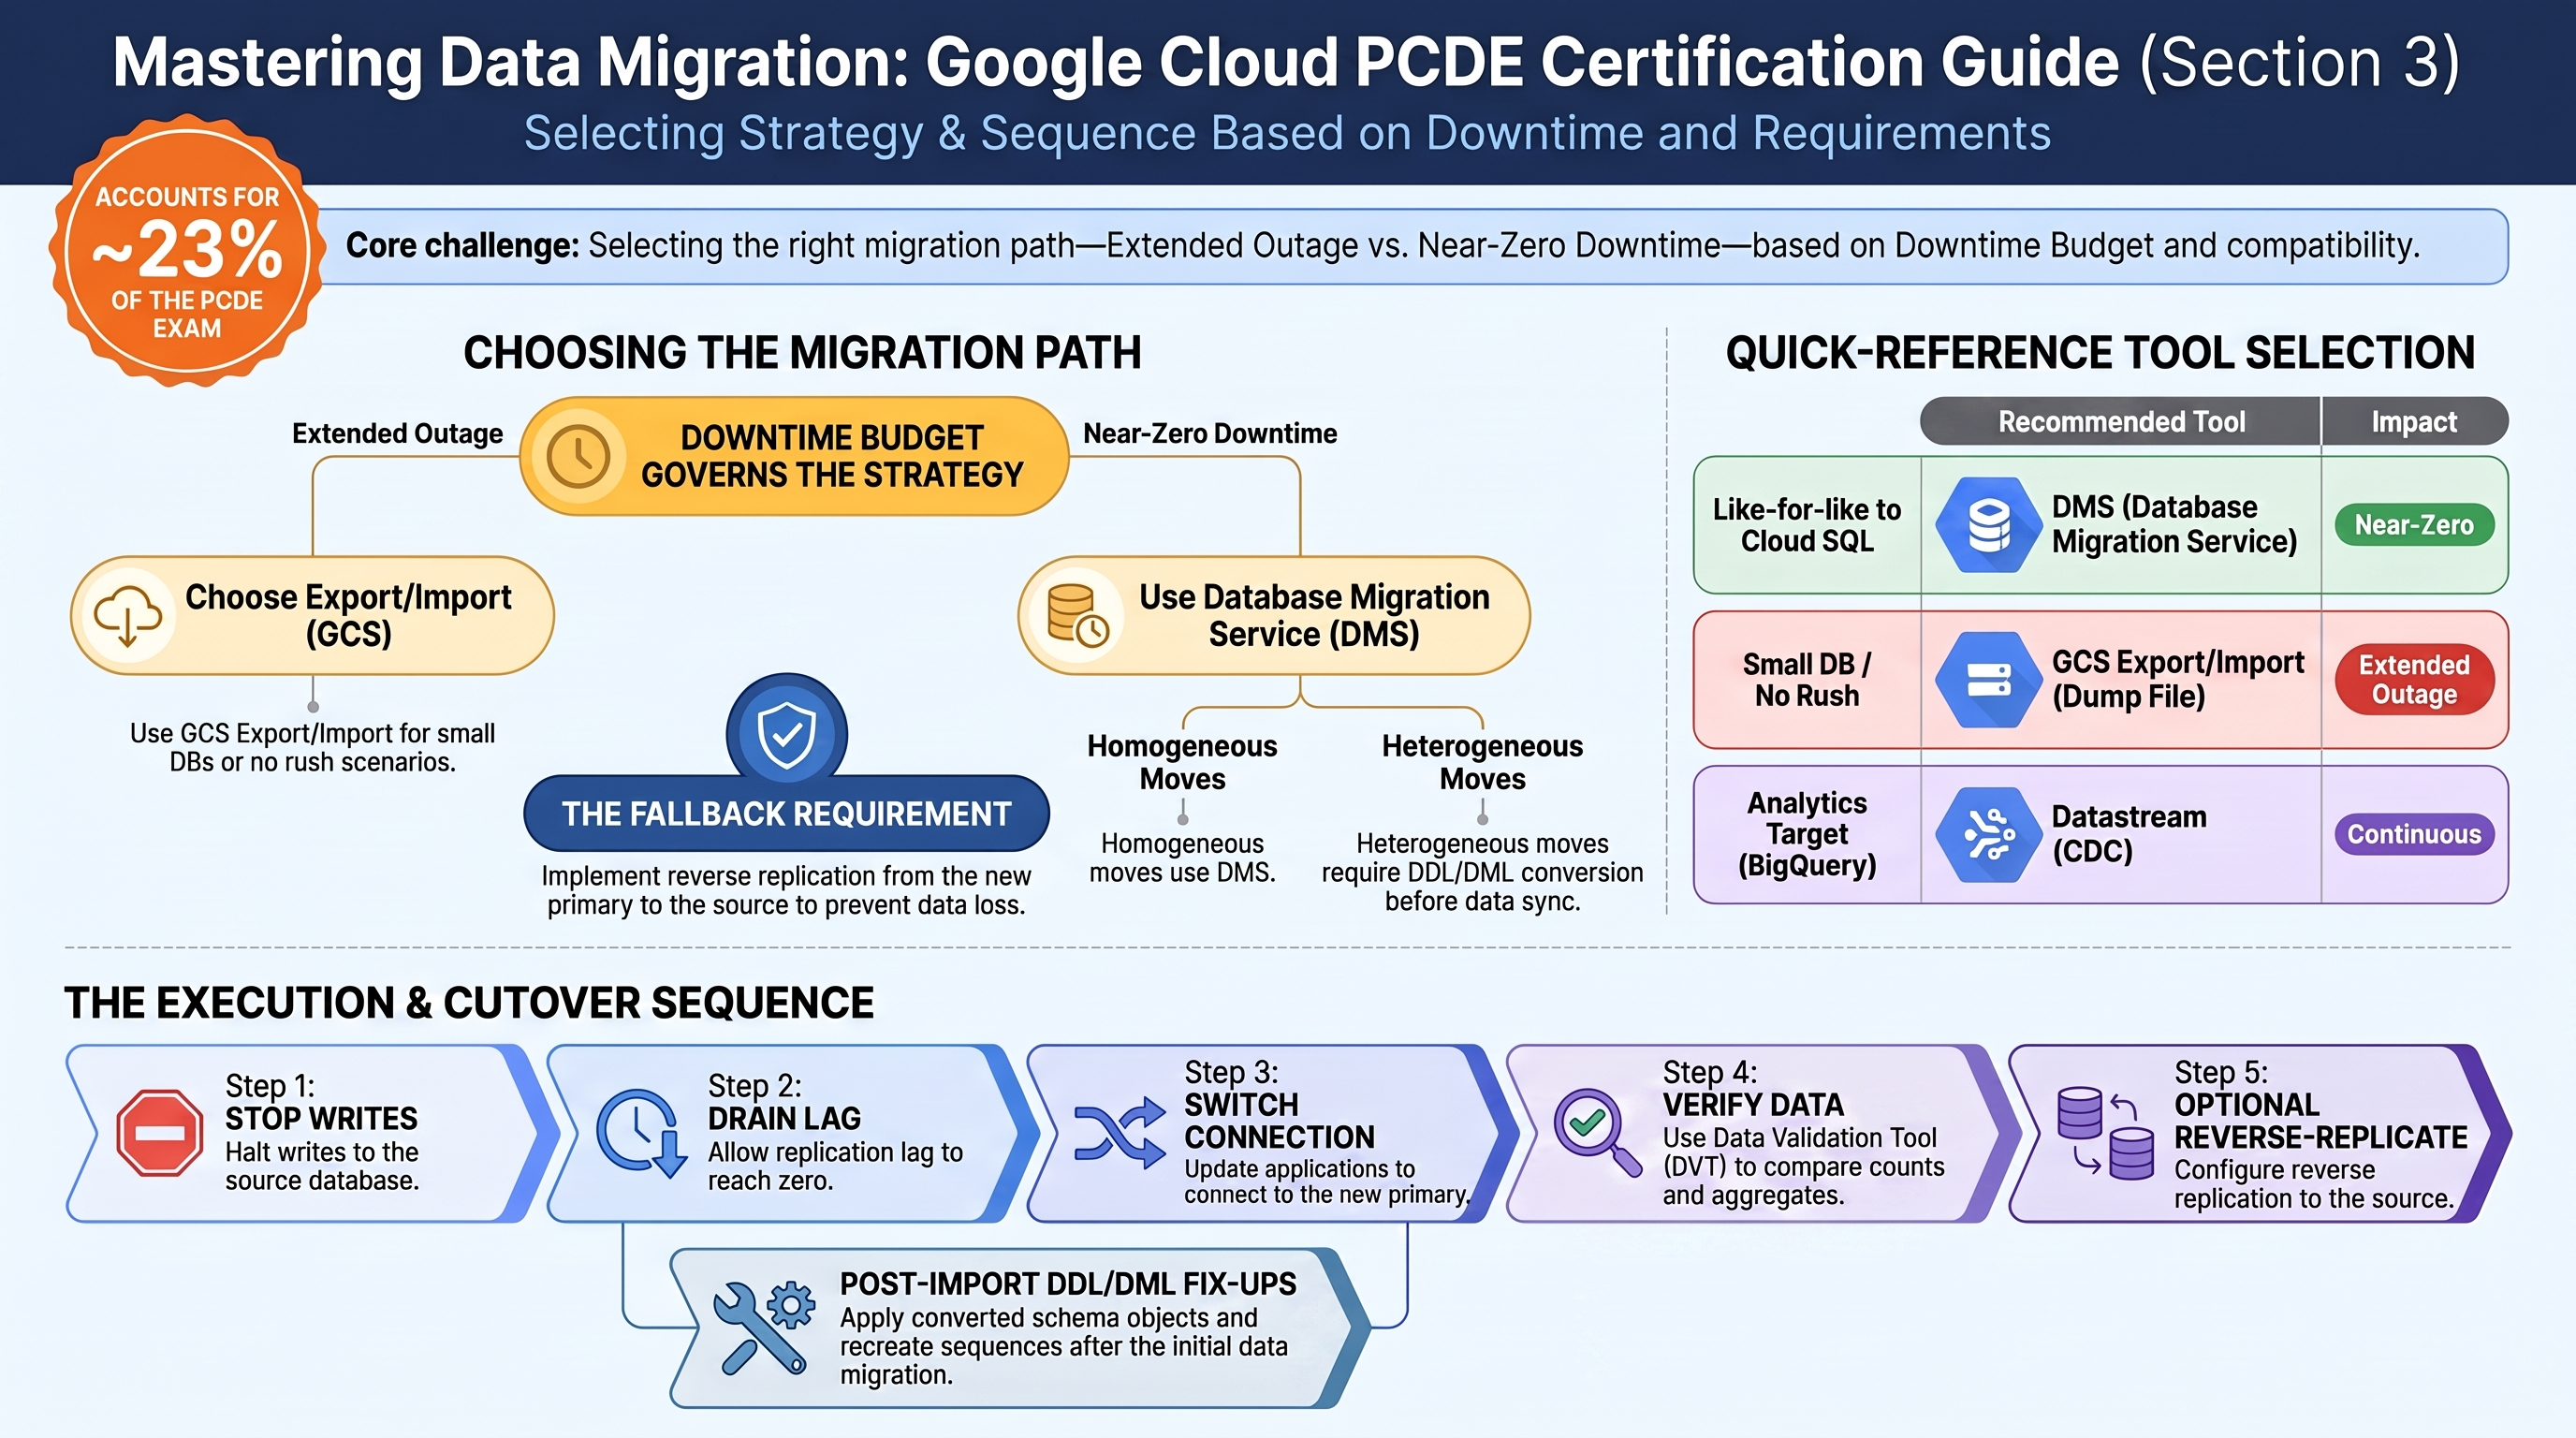 > 📚 **Official exam guide:** [Professional Cloud Database Engineer certification](https://cloud.google.com/learn/certification/cloud-database-engineer) — always confirm section weightings against the current Google Cloud exam guide.
This guide covers Section 3 of the Professional Cloud Database Engineer (PCDE) exam. Be warned up front: this is the section where the RAD foundation modules cover the *least* ground. The modules implement the export/import (extended-outage) migration path end to end — `App_CloudRun`/`App_GKE` backup-import jobs fed from GCS or Google Drive, driven by the `App_Common` scripts — and read replication inside Google Cloud via `Services_GCP`. Database Migration Service, Datastream, zero-downtime cutovers, and reverse replication are concept-only and carry heavy "Beyond the modules" study lists. Deploy the **relational-baseline** and **app-dataops** profiles from the [PCDE Lab Map](PCDE_Certification_Guide.md) before starting.
---
## 3.1 Design and implement data migration and replication
> ⏱ ~90 min (half hands-on, half reading) · 💰 low — one import job + GCS staging · ⚙️ Requires: app-dataops profile with `enable_backup_import = true`
**Why the exam cares** — Migration questions are downtime-budget questions. The decision tree the exam tests: **extended outage acceptable** → one-time export/import (dump file through GCS); **near-zero downtime** → continuous replication (Database Migration Service for homogeneous moves into Cloud SQL/AlloyDB, Datastream/CDC for heterogeneous) with a short cutover; **fallback required** → reverse replication from the new primary back to the source so you can return if the cutover fails. Heterogeneous moves add DDL/DML conversion (schema/type/dialect translation) on top. You must pick the tool *and* sequence the cutover: stop writes → drain replication lag → switch connection strings → verify → (optionally) reverse-replicate.
**How RAD implements it** — the extended-outage path is real and runnable:
| Step of a lift-and-shift | Module implementation |
|---|---|
| Export from source | the export script (App_Common) — version-matched `pg_dump`/`mysqldump` producing `backup-.tar.gz`; for an external source you run the equivalent dump yourself |
| Stage the artifact | The module-provisioned GCS backup bucket (lifecycle-managed by `backup_retention_days`, default `7`), or Google Drive |
| Import into Cloud SQL | `enable_backup_import = true` (default `false`) runs a one-time `-backup-import` job selected by `backup_source` (`gcs`/`gdrive`, default `gcs`), restoring `backup_file` (default `backup.sql`) with `backup_format` (`sql,tar,gz,tgz,tar.gz,zip,auto`) through the Cloud SQL connector volume |
| Post-import fix-ups (DDL/DML adjustments) | `enable_custom_sql_scripts` + `custom_sql_scripts_bucket`/`custom_sql_scripts_path` (+ `custom_sql_scripts_use_root` for privileged DDL) runs `.sql` files in lexicographic order — the place to apply converted schema objects, recreate sequences, or fix collations |
| Replication (inside GCP) | `create_postgres_read_replica` / `create_mysql_read_replica` in `Services_GCP` — Cloud SQL native async replication, the same mechanism a DMS migration uses for its destination sync, observable end to end |
What the modules deliberately do **not** do: connect to an *external* source, run change data capture, or orchestrate a cutover. There is no DMS, Datastream, or external-server replication configuration anywhere in the four modules.
**Try it**
1. Simulate a source database: connect to the lab instance (Auth Proxy + psql as in Section 1.3), create a table with rows, and dump it — or simply let the scheduled export from Section 2.5 produce one. Stage your own file explicitly:
```bash
pg_dump -h 127.0.0.1 -U postgres -d postgres -f /tmp/source-dump.sql
gcloud storage cp /tmp/source-dump.sql gs:///source-dump.sql
```
2. In the portal set `enable_backup_import = true`, `backup_source = "gcs"`, `backup_file = "source-dump.sql"`, `backup_format = "sql"`, and apply. Watch the import job:
```bash
gcloud run jobs executions list --job=-backup-import --region=us-central1
gcloud logging read 'resource.type="cloud_run_job" AND resource.labels.job_name="-backup-import"' \
--limit=50 --freshness=1h
```
3. Verify row counts match the source (the migration engineer's first validation):
```bash
psql -h 127.0.0.1 -U -d -c "SELECT count(*) FROM ;"
```
4. For the replication half, apply ha-production (Section 1.2) and watch `cloudsql--postgres-replica` seed and catch up — `gcloud sql instances describe cloudsql--postgres-replica --format="value(state, replicaConfiguration)"`. This is the same replica machinery DMS drives during a continuous migration.
5. You know it worked when the import execution succeeds and the destination row counts equal the source's.
**Check yourself**
Q1: A 2 TB on-premises PostgreSQL 14 database must move to Cloud SQL with under 5 minutes of downtime. Is the platform's import-job pattern appropriate? What is?
A: No — a dump/restore of 2 TB takes hours, all of it downtime (the pattern is right only when an extended outage is acceptable). Use Database Migration Service: initial snapshot plus continuous CDC replication from the source, let lag drain while the source stays live, then a minutes-long cutover. DMS homogeneous migrations to Cloud SQL are free, which the exam likes to mention.
Q2: After cutover to Cloud SQL, the business demands a fallback path for two weeks. What is the mechanism, and what must remain true at the source?
A: Reverse replication: replicate changes from the new Cloud SQL primary back to the old source (DMS supports configuring the old source as a replica of the migrated instance for PostgreSQL/MySQL, or you maintain logical replication yourself), so the application can be repointed back without data loss. The source must remain schema-compatible and reachable, and no writes may go to it directly during the fallback window — otherwise the two diverge.
Q3: An Oracle-to-PostgreSQL migration stalls because of incompatible PL/SQL and data types. Which class of work is this, and which tools address it?
A: DDL/DML conversion — heterogeneous migrations need schema and code translation, not just data movement. Tools: DMS's Oracle-to-PostgreSQL conversion workspaces (Ora2Pg-based), manual rewrite of stored procedures, plus type-mapping decisions (NUMBER → numeric, DATE → timestamp). In this platform the converted DDL would be applied through the custom-SQL-scripts job; the conversion itself is always engineering work the exam expects you to schedule before data sync.
**Beyond the modules** — Most of Section 3 lives here; budget real study time:
- **Database Migration Service (DMS)**: connection profiles, migration jobs, homogeneous (MySQL/PostgreSQL → Cloud SQL/AlloyDB, free) vs heterogeneous (Oracle/SQL Server → PostgreSQL, conversion workspaces). In a scratch project walk through `gcloud database-migration connection-profiles create postgresql ...` and `gcloud database-migration migration-jobs create ... --type=CONTINUOUS`, even if only to the validation step — the *verify* phase (`gcloud database-migration migration-jobs verify`) is exam-favored.
- **Datastream** for CDC into BigQuery/GCS when the target is analytics rather than a like-for-like database.
- **Cloud SQL external server replication** ("Replicating from an external server" docs): the pre-DMS pattern of making a Cloud SQL instance a replica of an external primary; promotion = cutover (`gcloud sql instances promote-replica`).
- **Zero-downtime sequencing**: dual-write pitfalls, draining lag before cutover, connection-string switching via Secret Manager (this platform's secret-driven `DB_HOST`/host secrets show exactly where you would flip it).
- **Validation tooling**: the open-source Data Validation Tool (DVT) for row/aggregate comparison between source and target.
**⚠️ Exam trap** — "Use the import job / `gcloud sql import sql` for the migration" is the trap answer whenever the scenario states a downtime budget in minutes. Conversely, "set up DMS" is the trap when the scenario says a weekend outage is fine and the database is small — one-time export/import is simpler, cheaper, and exactly what this platform automates.
---
# PCDE Certification Preparation Guide: Section 4 — Deploy scalable and highly available databases in Google Cloud (~20% of the exam)
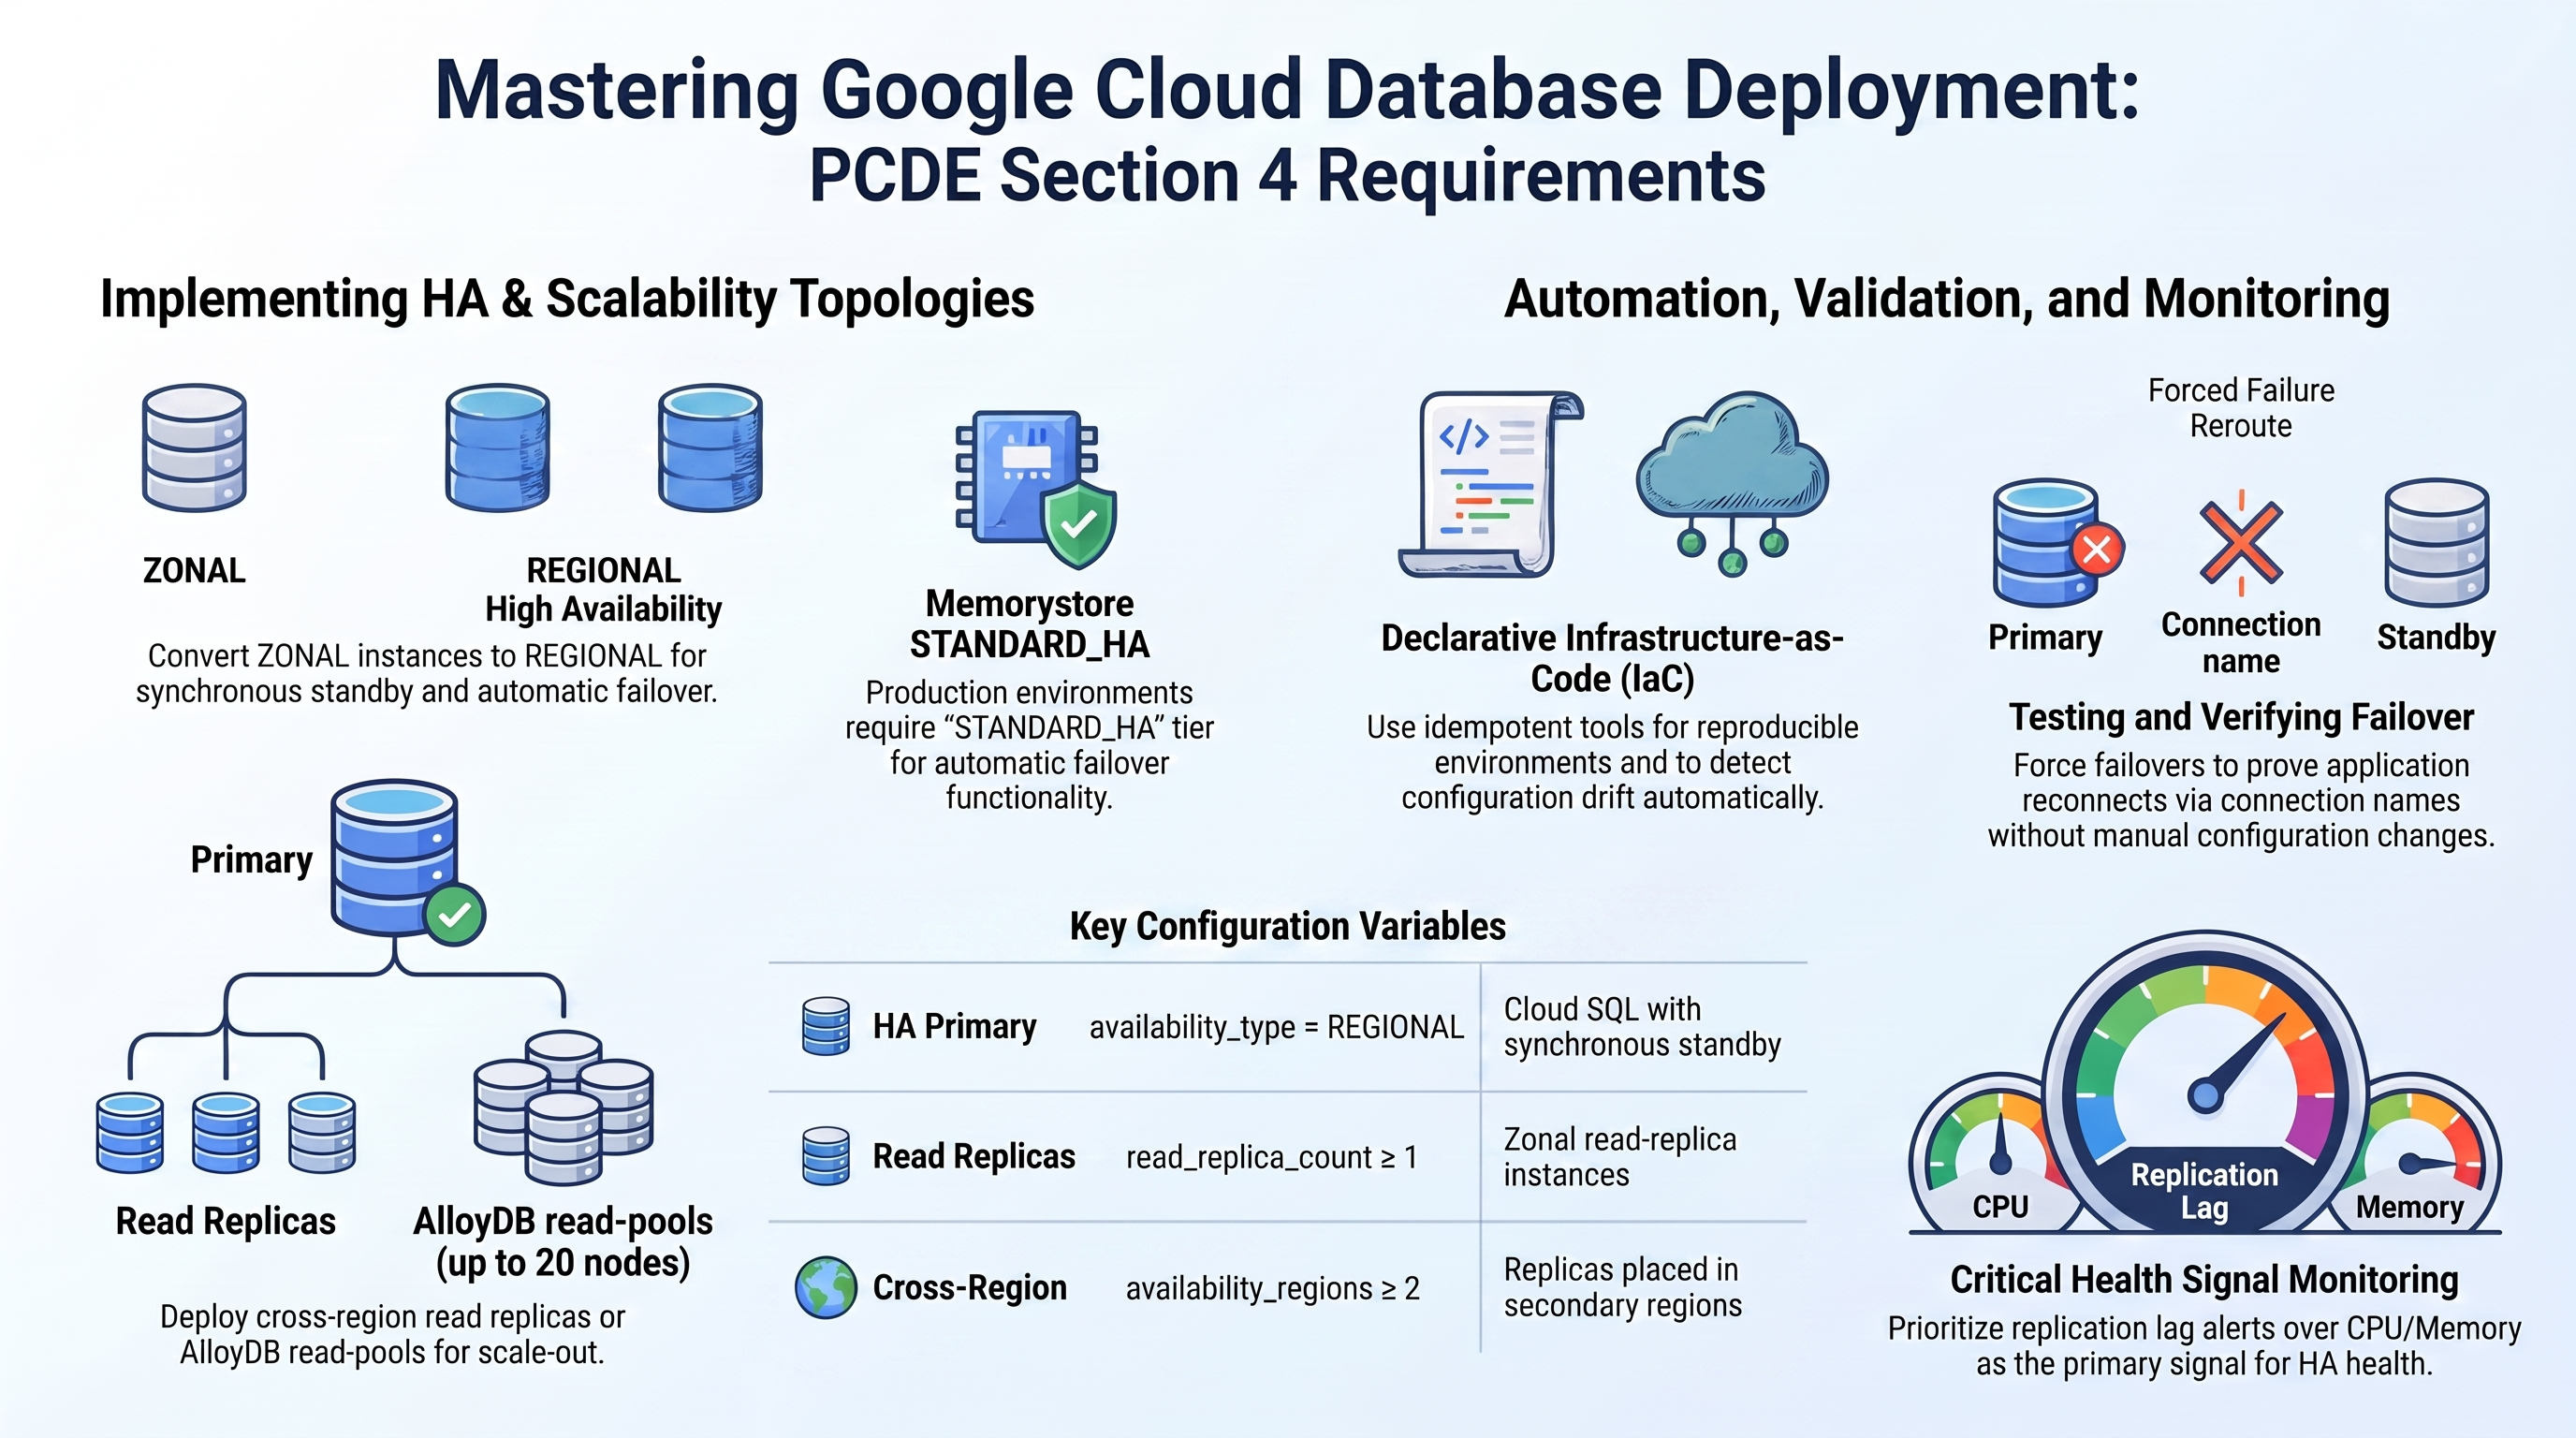 > 📚 **Official exam guide:** [Professional Cloud Database Engineer certification](https://cloud.google.com/learn/certification/cloud-database-engineer) — always confirm section weightings against the current Google Cloud exam guide.
This guide covers Section 4 of the Professional Cloud Database Engineer (PCDE) exam — and it is the section where this repository *is* the answer key. "Automate database instance provisioning" is literally what `Services_GCP` does: every Cloud SQL, AlloyDB, Redis, and Firestore deployment in the platform is declarative infrastructure-as-code applied through your deployment portal or Cloud Build. The HA, replica, and monitoring machinery comes from `Services_GCP`; application failover behavior is observed through `App_CloudRun`/`App_GKE`. Deploy the **ha-production** profile from the [PCDE Lab Map](PCDE_Certification_Guide.md) before starting.
---
## 4.1 Apply concepts to implement scalable and highly available databases in Google Cloud
> ⏱ ~90 min · 💰 moderate-to-high while ha-production is applied (REGIONAL ≈ 2× instance cost; each replica ≈ +1 instance) — revert to ZONAL/no-replica afterwards · ⚙️ Requires: ha-production profile
**Why the exam cares** — Section 1 asked you to *choose* an HA design; Section 4 asks you to *implement and prove* it: provision the HA topology, deploy and scale read replicas, replicate across regions, verify failover actually works (an untested DR plan is the exam's favorite anti-pattern), automate provisioning so environments are reproducible, and monitor the HA signals (replication lag, failover events, instance health) rather than just CPU.
**How RAD implements it** —
*Provisioning HA, declaratively.* The entire topology is variables on `Services_GCP`:
| Capability | Variable (default) | Resulting resource |
|---|---|---|
| HA primary | `postgres_database_availability_type` (`ZONAL`) → `REGIONAL` | A Cloud SQL primary instance with synchronous standby + automatic failover (same for `mysql_database_availability_type`) |
| Read replicas | `create_postgres_read_replica` (`false`), `postgres_read_replica_count` (`1`) | A Cloud SQL read replica instance (type `READ_REPLICA_INSTANCE`), always ZONAL |
| Cross-region placement | `availability_regions` (`["us-central1"]`) | With ≥2 regions, replicas land in the second region; otherwise they stay in the primary region |
| Read-pool scale-out | `enable_alloydb_read_pool` (`false`), `alloydb_read_pool_node_count` (`1`, 1–20) | An AlloyDB read-pool instance (type `READ_POOL`) |
| Cache HA | `redis_tier` (`BASIC`) → `STANDARD_HA` | Memorystore with automatic failover replica; the platform *blocks* BASIC at plan time when `resource_labels.environment = "production"` |
*Automated provisioning.* This is infrastructure-as-code end to end: `tofu init → plan → apply` (run by the platform's create/update pipeline in CI), idempotent re-application, dependency sequencing (instances are gated on the Service Networking connection; a 120 s delay separates the two Cloud SQL instances), and discovery-not-duplication in the app layer (App_Common finds the platform instance by its `managed-by = services-gcp` label; `App_CloudRun` provisions an equivalent inline ZONAL PostgreSQL 17 instance only when none exists). Replica lifecycle is also codified: replicas are rebuilt if the primary is replaced.
*Monitoring for HA databases.* The platform ships CPU/memory/disk alert policies on `resource.type = "cloudsql_database"` wired to email channels (`configure_email_notification`, `notification_alert_emails`); each replica additionally publishes its endpoint as a `-host` secret so consumers fail over reads deliberately. Application-side, `uptime_check_config` (default `{ enabled = false, path = "/" }`) creates a `-uptime-check` synthetic probe plus failure alert once enabled whenever the application endpoint is publicly reachable — ready-made detection of user-visible impact during failover tests (internal-only deployments get none).
**Try it**
1. Apply ha-production and map the fleet:
```bash
gcloud sql instances list \
--format="table(name, region, gceZone, settings.availabilityType, instanceType, state)"
```
Expect the primary as `REGIONAL` in us-central1 and the replica as `READ_REPLICA_INSTANCE` in us-east1.
2. **Test HA** — note the current zone, force a failover, and time it:
```bash
gcloud sql instances describe cloudsql--postgres --format="value(gceZone)"
gcloud sql instances failover cloudsql--postgres
gcloud sql operations list --instance=cloudsql--postgres --limit=3
```
While it runs, hit the application URL (or watch the module-created `-uptime-check` in **Console > Monitoring > Uptime checks**) to observe the brief connection blip — the Cloud SQL connector reconnects to the same connection name without any configuration change.
3. **Scale reads** — raise `postgres_read_replica_count` to `2` in the portal, apply, and confirm the new replica appears in the secondary region; then check replication health from the primary via psql: `SELECT client_addr, state, replay_lag FROM pg_stat_replication;`.
4. **Test DR promotion** (destructive to the replica's replica-status — do it on the second, disposable replica):
```bash
gcloud sql instances promote-replica cloudsql--postgres-replica-1
gcloud sql instances describe cloudsql--postgres-replica-1 \
--format="value(instanceType, settings.availabilityType)"
```
Note what Terraform now thinks: the promoted instance has drifted from the declared state, and the next `tofu plan` will want to reconcile it — promotion is a break-glass action, not a managed workflow in these modules.
5. **Prove reproducibility** — the automation claim of this section: re-run a plan over the unchanged deployment from your deployment portal (the platform runs `tofu plan` for you) and review the proposed changes.
You know it worked when the failover operation completes with the primary in a new zone, the promoted instance reports `CLOUD_SQL_INSTANCE` (no longer a replica), and a fresh `tofu plan` over the *unmodified* configuration shows no unexpected changes (idempotence) — while the post-promotion plan visibly flags the drift.
**Check yourself**
Q1: During a failover test of the REGIONAL instance, the application reconnected automatically without any configuration change. Why — and which connection pattern from this platform made that possible?
A: Cloud SQL HA failover keeps the instance's identity: the connection name and private IP move to the promoted standby. Because the app connects through the Cloud SQL connector volume (Cloud Run) or Auth Proxy sidecar (GKE) addressed by *connection name*, and reads credentials from Secret Manager, nothing client-side referenced the failed zone. Hardcoded zonal IPs are the anti-pattern this design avoids.
Q2: A scenario requires read traffic served in two regions and a documented region-loss runbook. Which variables build the topology, and which two steps remain manual?
A: `availability_regions = ["us-central1", "us-east1"]`, `postgres_database_availability_type = "REGIONAL"`, `create_postgres_read_replica = true`, `postgres_read_replica_count ≥ 1` — replicas are placed in the secondary region and their endpoints published as secrets. Manual in a disaster: promoting the replica (`gcloud sql instances promote-replica`) and repointing applications to the promoted endpoint (e.g. updating the host secret). Cross-region failover is never automatic for Cloud SQL — a recurring exam point.
Q3: Why is Terraform-based provisioning itself an HA control, not just a convenience?
A: Reproducibility is recoverability: the entire database estate (instances, flags, networks, secrets, alerting) can be re-created in another project or region from code with `tofu apply`, and configuration drift is detected by `tofu plan`. Manual console-built instances cannot be rebuilt reliably under incident pressure. The exam frames this as "automate instance provisioning" — IaC plus idempotent re-application is the expected answer.
**Beyond the modules** — Three gaps to study: (1) **managed cross-region promotion workflows** — the modules build the replica but have no promotion/runbook automation; read "Promoting replicas" and "Cross-region replicas for disaster recovery" in the Cloud SQL docs, including how to re-establish replication after promotion; (2) **multi-region write systems** — Spanner multi-region instance configurations and AlloyDB secondary clusters (`gcloud alloydb clusters create-secondary`) with switchover/failover semantics; (3) **replication-lag alerting** — the module alerts on CPU/memory/disk but not on `cloudsql.googleapis.com/database/replication/replica_lag`; practice adding that alert in **Console > Monitoring > Alerting** or via `gcloud alpha monitoring policies create` in a scratch project, since lag is *the* HA health signal for read-replica topologies.
**⚠️ Exam trap** — `gcloud sql instances failover` works only on REGIONAL (HA) instances — running it against a ZONAL instance fails because there is no standby. And promotion is one-way: a promoted replica is a standalone primary; to get a replica back you create a new one and reseed. Distractors that "fail back by demoting" the promoted instance are wrong for Cloud SQL.
---
# Professional Cloud Network Engineer (PCNE) Certification Lab Map
> 📚 **Official exam guide:** [Professional Cloud Network Engineer certification](https://cloud.google.com/learn/certification/cloud-network-engineer) — always confirm section weightings against the current Google Cloud exam guide.
The Professional Cloud Network Engineer certification validates the ability to design, implement, and operate Google Cloud VPC networks, hybrid connectivity, network services (load balancing, CDN, DNS), and network security. The RAD platform's four foundation modules — `Services_GCP` (custom-mode VPC, subnets, firewall rules, Cloud NAT, private services access, GKE VPC-native clusters), `App_CloudRun` (Direct VPC egress, serverless NEGs, global external Application Load Balancer, Cloud Armor, Cloud CDN), `App_GKE` (Gateway API, Kubernetes NetworkPolicy, GCPBackendPolicy), and `App_Common` (network discovery, VPC-SC) — give you a live, modifiable lab for roughly half of this exam. The other half (Interconnect, VPN, BGP, Network Connectivity Center, Cloud DNS, NGFW, Network Intelligence Center) is deliberately *not* implemented by the modules; this guide is honest about those gaps and tells you exactly what to study outside the platform. Expect to lean on the "Beyond the modules" blocks more heavily here than in any other RAD certification guide.
## How to use this guide
- Deploy one of the profiles below through your deployment portal, then work through the matching section exploration guide while the infrastructure is live.
- Use the coverage legend to plan your study time: ✅ topics can be learned hands-on in RAD; 📘 topics need official docs and a scratch project.
- The PCNE exam is scenario-heavy. After each "Try it", ask yourself *why* the modules made each choice (e.g., why a /16 PSA range, why Dataplane V2, why a global external ALB).
**Coverage legend**
| Symbol | Meaning |
|---|---|
| ✅ | Fully demonstrated — deploy it, see it, modify it in the RAD platform |
| 🟡 | Partially demonstrated — the modules touch the concept; supplement with docs |
| 📘 | Concept-only — not implemented by the modules; study pointers provided |
## Deployment profiles
### Profile: VPC Foundation
*Purpose:* Custom-mode VPC, subnets, firewall rules, Cloud Router + Cloud NAT, and private services access — the core of Sections 1, 2, and 6.3.
*Modules:* `Services_GCP`, then `App_CloudRun` on top.
| Variable | Value |
|---|---|
| `availability_regions` | `["us-central1"]` (default) |
| `subnet_cidr_range` | `["10.0.0.0/24"]` (default) |
| `create_postgres` | `true` (default — forces the PSA peering to be exercised) |
| `create_network_filesystem` | `true` (default — tag-based firewall rules + TCP health checks) |
| `vpc_egress_setting` (App_CloudRun) | `PRIVATE_RANGES_ONLY` (default) |
*Estimated incremental cost:* Low — a `db-custom-1-3840` Cloud SQL instance and one e2-small NFS VM dominate; the VPC, NAT gateway, and firewall rules are cents per day.
### Profile: GKE Network Lab
*Purpose:* VPC-native cluster with named secondary ranges, Dataplane V2, Kubernetes NetworkPolicy, and Workload Identity — Sections 1.4, 2.4, and 6.2.
*Modules:* `Services_GCP` (with GKE), then `App_GKE`.
| Variable | Value |
|---|---|
| `create_google_kubernetes_engine` (Services_GCP) | `true` |
| `gke_cluster_mode` | `AUTOPILOT` (default) |
| `gke_cluster_count` | `1` (set `2` + `configure_cloud_service_mesh = true` for the multi-cluster east-west firewall variant) |
| `gke_subnet_base_cidr` / `gke_pod_base_cidr` / `gke_service_base_cidr` | defaults `10.128.0.0/12` / `10.64.0.0/10` / `10.8.0.0/16` |
| `enable_network_segmentation` (App_GKE) | `true` |
| `service_type` (App_GKE) | `LoadBalancer` (default) |
*Estimated incremental cost:* Moderate — Autopilot bills per pod resource request; a second cluster plus Cloud Service Mesh roughly doubles it.
### Profile: Global Edge
*Purpose:* Global external Application Load Balancer, serverless NEG, Cloud Armor WAF, Cloud CDN, Certificate Manager, static global IPs — Sections 3.1, 3.2, 6.1.
*Modules:* `App_CloudRun` (and/or `App_GKE` for the Gateway API equivalent).
| Variable | Value |
|---|---|
| `enable_cloud_armor` | `true` |
| `application_domains` | `["app.example.com"]` (required by App_CloudRun validation when Cloud Armor is on) |
| `enable_cdn` | `true` |
| `admin_ip_ranges` | your office/VPN CIDRs (priority-100 WAF allowlist on both engines; also a VPC-SC access level on App_CloudRun) |
| `enable_custom_domain` (App_GKE) | `true` |
| `reserve_static_ip` (App_GKE) | `true` (default) |
*Estimated incremental cost:* Moderate — forwarding-rule hours, Cloud Armor policy + per-request charges, and CDN cache egress are the drivers.
### Profile: Locked-Down Perimeter
*Purpose:* VPC Service Controls perimeter, restricted Google API egress, all-traffic VPC egress — Sections 2.1 and 6.2/6.3 defense-in-depth.
*Modules:* `Services_GCP` or either app module (all carry the VPC-SC variables).
| Variable | Value |
|---|---|
| `enable_vpc_sc` | `true` |
| `admin_ip_ranges` | non-empty (required, or VPC-SC is skipped with a warning) |
| `vpc_sc_dry_run` | `true` (default — audit before enforcing) |
| `vpc_egress_setting` (App_CloudRun) | `ALL_TRAFFIC` |
| `enable_network_segmentation` (App_GKE) | `true` (includes the `restricted.googleapis.com` 199.36.153.4/30 egress rule) |
*Estimated incremental cost:* Low — VPC-SC and firewall/NetworkPolicy changes are free; the cost is operational (requires an organization and org-level Access Context Manager permission).
## Section 1: Designing and planning a Google Cloud VPC network (~21% of the exam)
The modules demonstrate a complete single-VPC design: custom subnet mode, deterministic CIDR planning, private services access for managed databases, and GKE secondary-range sizing. Network tiers, Shared VPC, hybrid design, and DNS topology are study-only.
| Exam topic | Coverage | Where in RAD | Guide |
|---|---|---|---|
| 1.1 Designing an overall network architecture | 🟡 | `enable_cloud_armor` LB choice, PSA peering, Direct VPC egress; tiers/DNS/quotas 📘 | [Section 1 guide](PCNE_Section_1_Exploration_Guide.md#11-designing-an-overall-network-architecture) |
| 1.2 Designing VPC networks | 🟡 | custom-mode VPC, `subnet_cidr_range`, PSA /16; Shared VPC/NCC/PSC/IPv6/MTU 📘 | [Section 1 guide](PCNE_Section_1_Exploration_Guide.md#12-designing-vpc-networks) |
| 1.3 Designing a resilient and performant hybrid and multi-cloud network | 📘 | Not implemented (Cloud Router exists only as a NAT anchor) | [Section 1 guide](PCNE_Section_1_Exploration_Guide.md#13-designing-a-resilient-and-performant-hybrid-and-multi-cloud-network) |
| 1.4 Designing for Google Kubernetes Engine | ✅ | deterministically computed secondary ranges, Autopilot/Standard, public endpoint | [Section 1 guide](PCNE_Section_1_Exploration_Guide.md#14-designing-for-google-kubernetes-engine) |
## Section 2: Implementing a VPC network (~20% of the exam)
This is the strongest section for hands-on work: every deployment creates (or discovers) a VPC, subnets, firewall rules, a PSA peering with custom-route exchange, and a VPC-SC perimeter if enabled. Shared VPC, policy-based routing, and NCC are study-only.
| Exam topic | Coverage | Where in RAD | Guide |
|---|---|---|---|
| 2.1 Configuring VPCs | ✅ | VPC/subnets/firewall, PSA range, VPC-SC perimeters; Shared VPC 📘 | [Section 2 guide](PCNE_Section_2_Exploration_Guide.md#21-configuring-vpcs) |
| 2.2 Configuring VPC routing | 🟡 | Cloud Router (NAT-only, ASN 64514), peering route import/export; policy-based routing/ILB next hop 📘 | [Section 2 guide](PCNE_Section_2_Exploration_Guide.md#22-configuring-vpc-routing) |
| 2.3 Configuring Network Connectivity Center | 📘 | Not implemented | [Section 2 guide](PCNE_Section_2_Exploration_Guide.md#23-configuring-network-connectivity-center) |
| 2.4 Configuring and maintaining GKE clusters | ✅ | VPC-native + Dataplane V2, Kubernetes NetworkPolicy; private clusters / Cloud DNS for GKE 📘 | [Section 2 guide](PCNE_Section_2_Exploration_Guide.md#24-configuring-and-maintaining-google-kubernetes-engine-clusters) |
## Section 3: Configuring managed network services (~16% of the exam)
Both deployment engines build a global external Application Load Balancer — one from Terraform LB primitives (Cloud Run), one from the GKE Gateway API. Cloud DNS is not implemented at all.
| Exam topic | Coverage | Where in RAD | Guide |
|---|---|---|---|
| 3.1 Configuring load balancing | ✅ | Cloud Run serverless NEG chain; GKE Gateway API; ALB traffic management 📘 | [Section 3 guide](PCNE_Section_3_Exploration_Guide.md#31-configuring-load-balancing) |
| 3.2 Configuring Cloud CDN | 🟡 | `enable_cdn` on the Cloud Run backend service (real); App_GKE flag provisions the Gateway but does not enable CDN | [Section 3 guide](PCNE_Section_3_Exploration_Guide.md#32-configuring-cloud-cdn) |
| 3.3 Configuring Cloud DNS | 📘 | Not implemented (nip.io wildcard DNS used instead) | [Section 3 guide](PCNE_Section_3_Exploration_Guide.md#33-configuring-cloud-dns) |
## Section 4: Configuring and implementing hybrid and multicloud network interconnectivity (~16% of the exam)
Entirely concept-only in RAD. The Cloud Router the modules create carries no BGP sessions — it exists solely to host Cloud NAT. Treat this section as a pure-study block; the guide gives you a structured plan and scratch-project commands.
| Exam topic | Coverage | Where in RAD | Guide |
|---|---|---|---|
| 4.1 Configuring Cloud Interconnect | 📘 | Not implemented | [Section 4 guide](PCNE_Section_4_Exploration_Guide.md#41-configuring-cloud-interconnect) |
| 4.2 Configuring a site-to-site IPSec VPN | 📘 | Not implemented | [Section 4 guide](PCNE_Section_4_Exploration_Guide.md#42-configuring-a-site-to-site-ipsec-vpn) |
| 4.3 Configuring Cloud Router | 🟡 | NAT-only router with ASN 64514; BGP/BFD/custom advertisement 📘 | [Section 4 guide](PCNE_Section_4_Exploration_Guide.md#43-configuring-cloud-router) |
| 4.4 Configuring Network Connectivity Center | 📘 | Not implemented | [Section 4 guide](PCNE_Section_4_Exploration_Guide.md#44-configuring-network-connectivity-center) |
## Section 5: Managing, monitoring, and troubleshooting network operations (~14% of the exam)
The modules enable LB request logging (sample rate 1.0) and rich health-check/auto-healing patterns, but VPC Flow Logs, NAT logging, and firewall logging are *not* enabled — turning them on manually against the deployed VPC is itself a great exercise.
| Exam topic | Coverage | Where in RAD | Guide |
|---|---|---|---|
| 5.1 Logging and monitoring with Google Cloud Observability | 🟡 | LB request logging on the Cloud Run backend; alert policies/uptime checks; flow/NAT/DNS logs 📘 | [Section 5 guide](PCNE_Section_5_Exploration_Guide.md#51-logging-and-monitoring-with-google-cloud-observability) |
| 5.2 Maintaining and troubleshooting connectivity | 🟡 | NFS MIG TCP health checks + auto-healing; VPN/Interconnect troubleshooting 📘 | [Section 5 guide](PCNE_Section_5_Exploration_Guide.md#52-maintaining-and-troubleshooting-connectivity-issues) |
| 5.3 Monitoring, maintaining, and troubleshooting latency and traffic flow | 📘 | Run Network Intelligence Center tools *against* RAD resources | [Section 5 guide](PCNE_Section_5_Exploration_Guide.md#53-monitoring-maintaining-and-troubleshooting-latency-and-traffic-flow) |
## Section 6: Configuring, implementing and managing a cloud network security solution (~13% of the exam)
Cloud Armor is the flagship ✅ here — both engines create a full WAF policy with preconfigured OWASP rules, Adaptive Protection, and rate limiting. Classic VPC firewall rules with tag-based micro-segmentation and Cloud NAT are also live; NGFW policies, Secure Web Proxy, and Packet Mirroring are study-only.
| Exam topic | Coverage | Where in RAD | Guide |
|---|---|---|---|
| 6.1 Implementing and managing Google Cloud Armor | ✅ | both app modules: OWASP v33 rules, Adaptive Protection, rate limiting | [Section 6 guide](PCNE_Section_6_Exploration_Guide.md#61-implementing-and-managing-google-cloud-armor) |
| 6.2 Configuring NGFW policies and VPC firewall rules | 🟡 | Tag-based VPC rules + K8s NetworkPolicy; hierarchical/NGFW tiers 📘 | [Section 6 guide](PCNE_Section_6_Exploration_Guide.md#62-configuring-ngfw-policies-and-vpc-firewall-rules) |
| 6.3 Controlling internet egress traffic with Cloud NAT and Secure Web Proxy | 🟡 | Cloud NAT (`ALL_SUBNETWORKS_ALL_IP_RANGES`, auto IPs); Secure Web Proxy 📘 | [Section 6 guide](PCNE_Section_6_Exploration_Guide.md#63-controlling-internet-egress-traffic-with-cloud-nat-and-secure-web-proxy) |
| 6.4 Implementing a self-managed network virtual appliance and Packet Mirroring | 📘 | Nearest analogue: self-managed NFS VM in a MIG; multi-NIC NVAs / Packet Mirroring 📘 | [Section 6 guide](PCNE_Section_6_Exploration_Guide.md#64-implementing-a-self-managed-network-virtual-appliance-and-packet-mirroring) |
## Suggested study sequence
1. **Week 1 — live lab (✅ topics):** Deploy VPC Foundation, work Sections 2.1–2.2, then 1.1–1.2. Add the GKE Network Lab and complete 1.4 and 2.4 while the cluster is up. These four subsections alone cover most of the hands-on weight of the exam.
2. **Week 2 — edge and security:** Deploy Global Edge; work 3.1, 3.2, 6.1 in one sitting (the LB, CDN, and Cloud Armor objects are the same deployment). Then 6.2 and 6.3 against the VPC Foundation resources, and Locked-Down Perimeter for the VPC-SC walk-through in 2.1.
3. **Week 3 — the 📘 third:** Sections 4 (all), 3.3, 2.3, 5.3, and 6.4 from docs plus the scratch-project commands in each "Beyond the modules" block. Roughly a third of the exam weight lives here; do not let the strength of the live lab tempt you into skipping it. The HA VPN lab in Section 4.2 — using the RAD VPC as one side — is the single highest-value scratch exercise.
4. **Final pass:** Re-run every "Check yourself" question cold. Tear down the lab profiles you no longer need; the GKE Network Lab and Global Edge profiles are the cost drivers.
## Key capabilities for quick reference
| Area | What it demonstrates |
|---|---|
| Services_GCP networking | Custom-mode VPC, subnets, firewall rules, Cloud Router + NAT, PSA peering with custom-route export |
| Services_GCP GKE | VPC-native clusters, deterministic secondary-range planning, Dataplane V2, Gateway API, Standard node pools |
| Services_GCP NFS appliance | Tag-targeted firewall rules, TCP health checks, MIG auto-healing (appliance ops pattern) |
| Services_GCP VPC-SC | VPC-SC perimeter, access levels, dry-run mode, permission probes |
| App_CloudRun edge | Serverless NEG → backend service → URL map → proxies → global IP; Cloud Armor; CDN; cert management |
| App_CloudRun service | Direct VPC egress, inline VPC/NAT/PSA fallback, hash-based CIDR allocation |
| App_GKE edge | Gateway API global external ALB, HTTPRoute, GCPBackendPolicy, Cloud Armor for GKE |
| App_GKE segmentation | Kubernetes NetworkPolicy micro-segmentation incl. restricted/private googleapis VIPs |
| App_Common discovery | Network/subnet/tag discovery contract (`managed-by=services-gcp`) |
---
# PCNE Certification Preparation Guide: Section 1 — Designing and planning a Google Cloud VPC network (~21% of the exam)
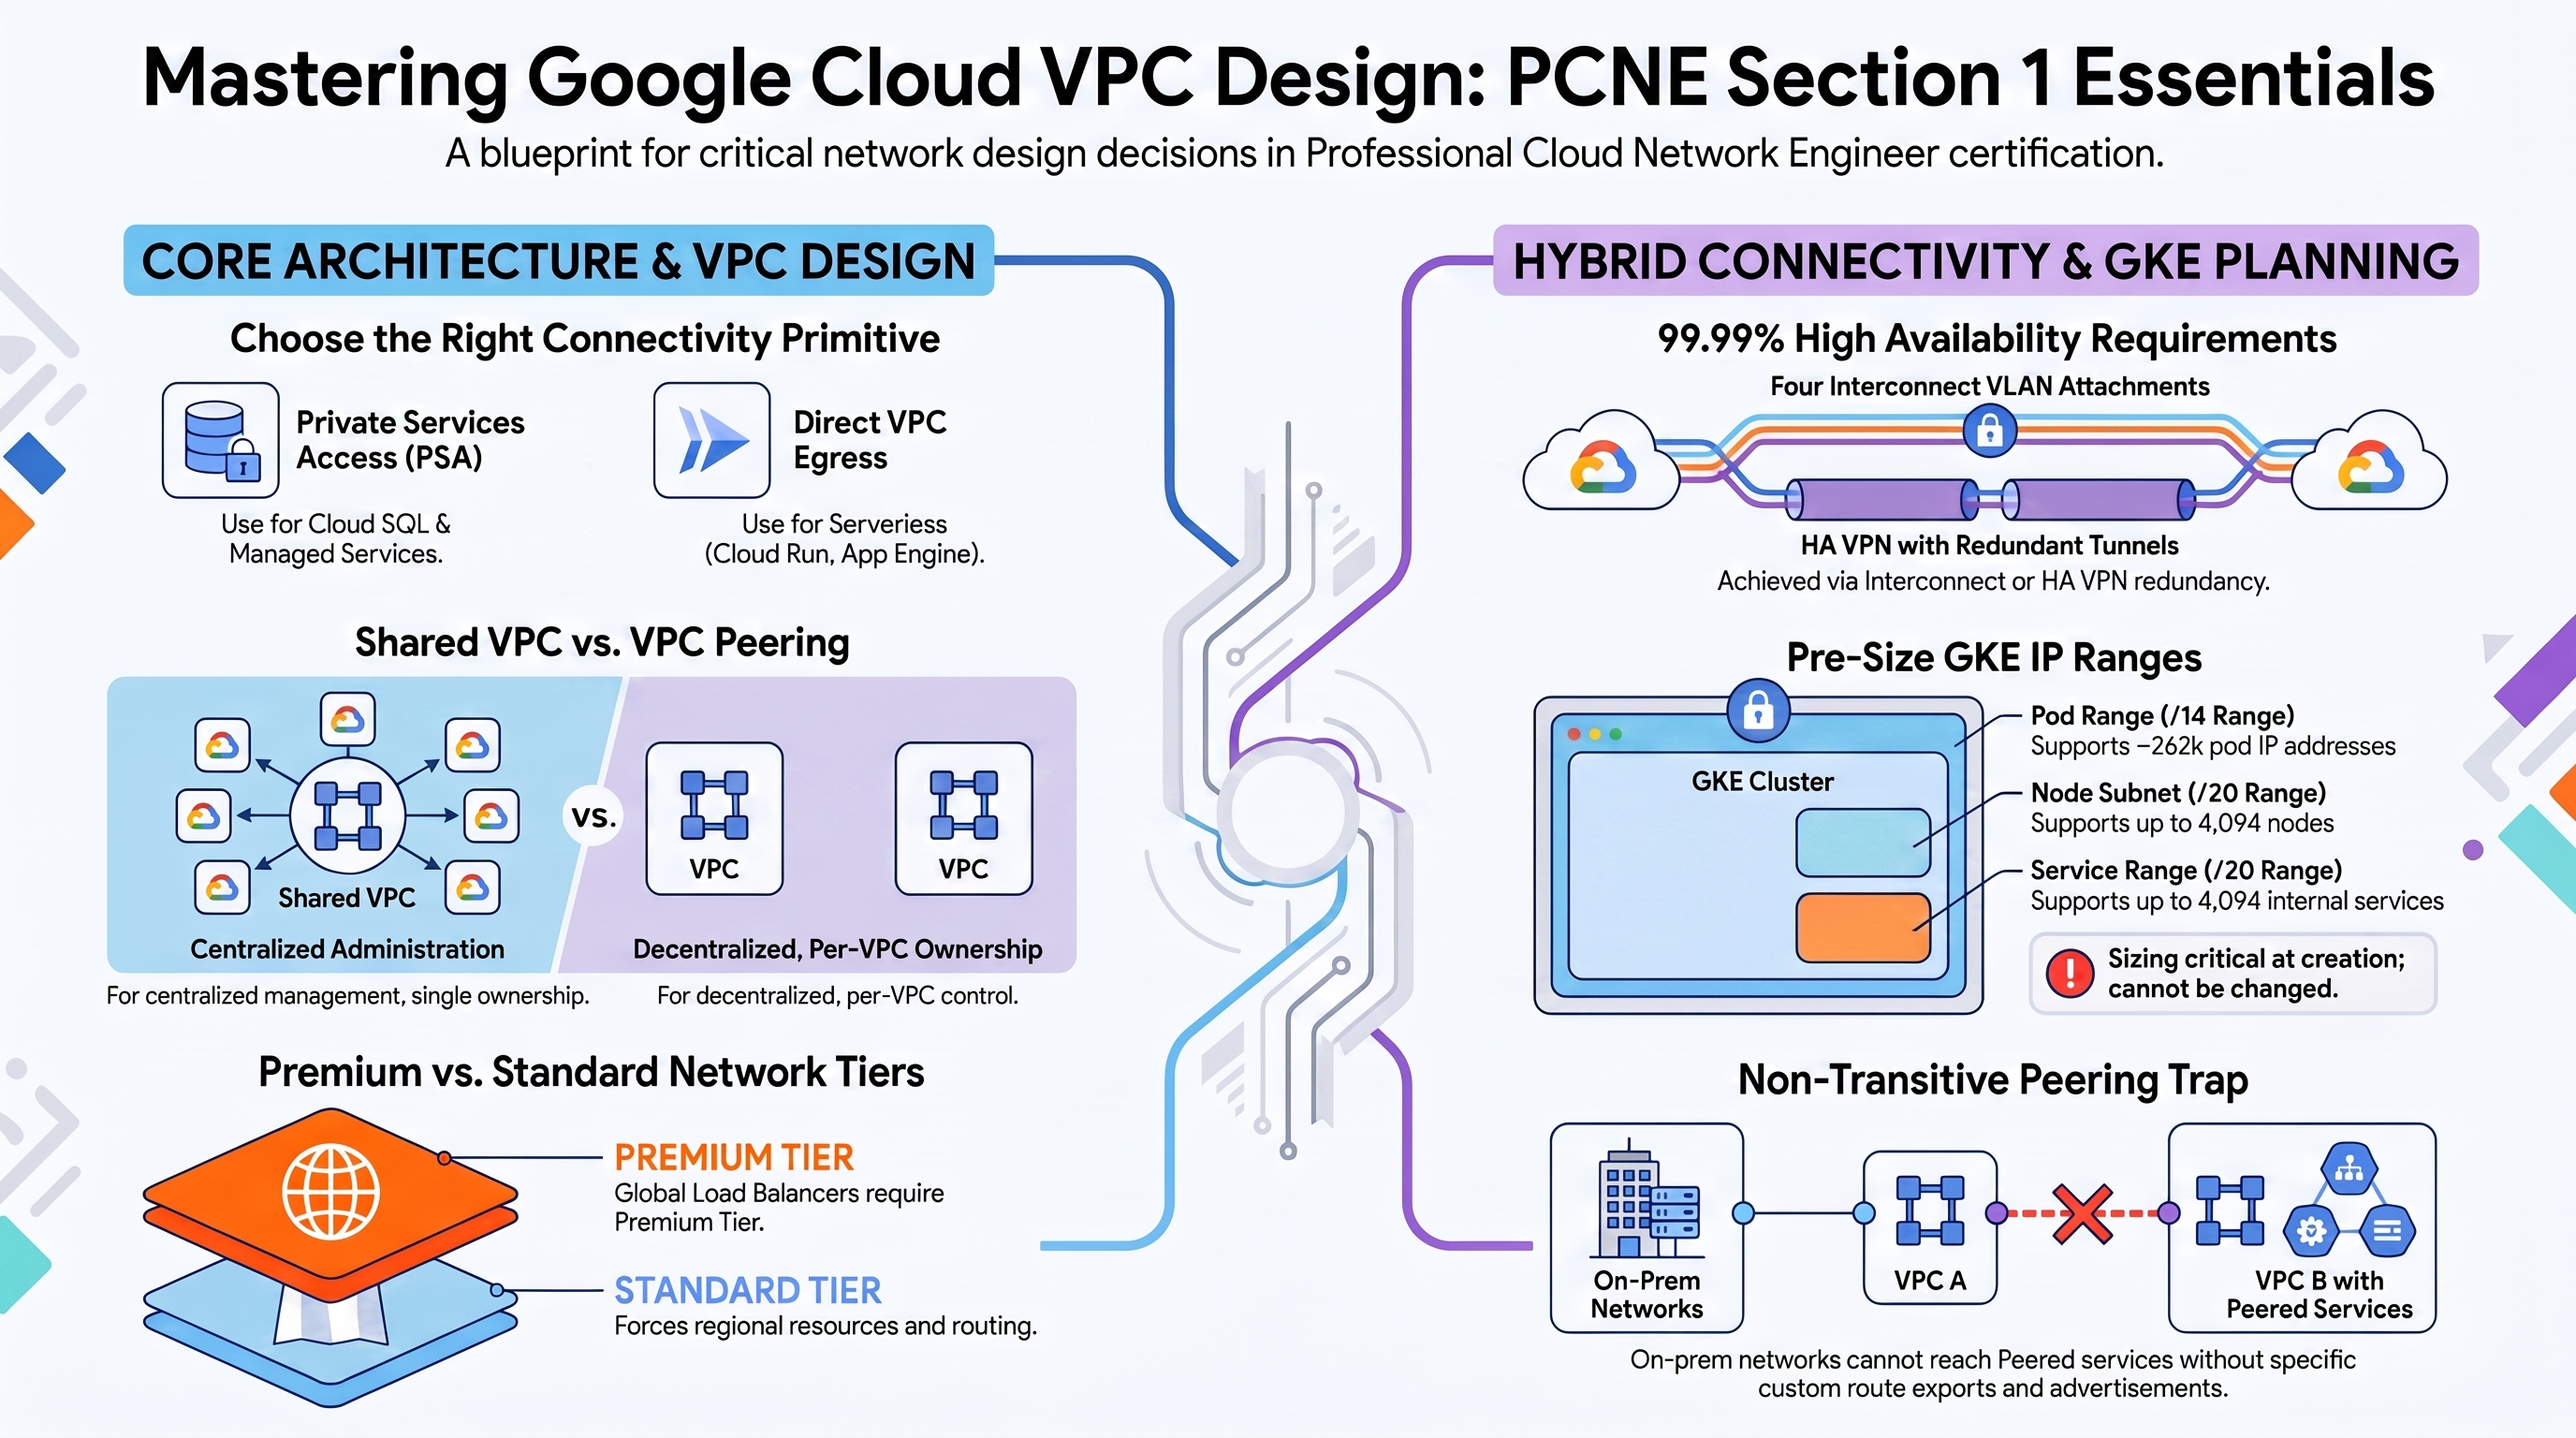 > 📚 **Official exam guide:** [Professional Cloud Network Engineer certification](https://cloud.google.com/learn/certification/cloud-network-engineer) — always confirm section weightings against the current Google Cloud exam guide.
This section tests network *design decisions*: how to size and segment IP space, when to choose Shared VPC vs peering vs Private Service Connect, and how to plan GKE networking before the first cluster exists. Deploy the **VPC Foundation** profile first; add the **GKE Network Lab** profile before working through 1.4. The modules exercised are `Services_GCP` (the network itself) and `App_Common` (how downstream modules discover it).
---
## 1.1 Designing an overall network architecture
> ⏱ ~45 min · 💰 no additional cost beyond the VPC Foundation profile · ⚙️ Requires: default deployment
**Why the exam cares** — Architecture questions test whether you can pick the right *connectivity primitive* for a managed service: private services access (PSA) for Cloud SQL/Memorystore, Private Service Connect (PSC) for producer endpoints, Direct VPC egress or a Serverless VPC Access connector for Cloud Run. They also test load balancer selection (global external Application LB vs regional vs passthrough) and whether your design respects quotas (subnet ranges per VPC, peering route limits).
**How RAD implements it** — The platform makes three deliberate architecture choices you can interrogate:
| Decision | RAD's choice |
|---|---|
| Managed-service connectivity | PSA: a /16 internal range reserved for VPC peering plus a Service Networking connection |
| Serverless-to-VPC connectivity | Cloud Run **Direct VPC egress** (a network interface on a subnet) — no Serverless VPC Access connector anywhere |
| Internet-facing entry point | An external Application Load Balancer with a serverless NEG, created when `enable_cloud_armor` (default `false`) or `enable_cdn` (default `false`) is on |
Memorystore Redis additionally exposes the choice directly: `redis_connect_mode` (default `DIRECT_PEERING`, option `PRIVATE_SERVICE_ACCESS`). Filestore uses `DIRECT_PEERING`.
**Try it**
1. Deploy the VPC Foundation profile. In **Console > VPC network > VPC network peering**, find the `servicenetworking-googleapis-com` peering created by the PSA connection.
2. Inspect the reserved range and the peering from the CLI:
```bash
gcloud compute addresses list --global \
--filter="purpose=VPC_PEERING" \
--format="table(name,address,prefixLength,network)"
gcloud services vpc-peerings list \
--network=$(gcloud compute networks list --filter="name~vpc-network" --format="value(name)" | head -1)
```
3. In **Console > Cloud Run**, open your service > **Networking** tab. Confirm "VPC" shows a network interface on the Services_GCP subnet (Direct VPC egress) rather than a connector.
4. You know it worked when the PSA address shows `prefixLength: 16` and the Cloud SQL instance's private IP (visible in **SQL > instance > Connections**) falls inside that range.
**Check yourself**
Q1: A Cloud Run service must reach a Cloud SQL private IP and an on-prem CIDR via VPN. Direct VPC egress or Serverless VPC Access connector — and what egress setting?
A: Either works for routing into the VPC, but Direct VPC egress (what RAD uses) avoids connector instance cost and gives higher throughput. To reach on-prem, `vpc_egress_setting = "ALL_TRAFFIC"` is not strictly required — `PRIVATE_RANGES_ONLY` (RAD's default) routes RFC 1918 destinations through the VPC, which covers a private on-prem CIDR. `ALL_TRAFFIC` is needed when *public* destinations must also traverse the VPC (e.g., for NAT-based egress IP allowlisting).
Q2: Why does the platform reserve a /16 for private services access instead of a /24?
A: Each service producer (Cloud SQL, Memorystore, Filestore) carves per-region subnets out of the allocated range inside Google's producer VPC. A small allocation can be exhausted as instances, replicas, and regions are added, and growing it later requires updating the reservation. A /16 leaves headroom for every producer the platform might enable.
Q3: Which network tier do the module-created load balancers use?
A: Global external Application Load Balancers with `EXTERNAL_MANAGED` scheme require Premium Tier, which is the project default. The modules never set a `network_tier`, so everything runs Premium. Standard Tier would force regional load balancing and regional forwarding rules — one reason a "global static IP + Standard Tier" design is an exam trap.
**Beyond the modules** — The exam also tests: Premium vs Standard network tiers (study "Network Service Tiers overview"; try `gcloud compute project-info describe --format="value(defaultNetworkTier)"`); DNS resolution topology (Cloud DNS private zones, split horizon — nothing in RAD); IAM roles for network design (`roles/compute.networkAdmin` vs `networkUser` vs `securityAdmin` — only `roles/compute.networkUser` appears, granted to the GKE service account); and quotas/limits (study "VPC resource quotas": subnet ranges per network, secondary ranges per subnet, peering limits). For PSC study "Private Service Connect types" — RAD uses *only* PSA peering, never PSC endpoints, despite the resource name `psconnect_private_ip_alloc`.
**⚠️ Exam trap** — Private services access is implemented with VPC *peering*, so it is non-transitive: an on-prem network connected by VPN cannot reach a Cloud SQL private IP through the consumer VPC unless you export custom routes on the peering and advertise the PSA range from Cloud Router. RAD already enables custom-route export on the PSA peering — know why.
---
## 1.2 Designing VPC networks
> ⏱ ~45 min · 💰 no additional cost · ⚙️ Requires: VPC Foundation profile
**Why the exam cares** — You must choose between standalone VPCs, Shared VPC, and multi-VPC designs joined by peering, NCC, or PSC, then defend an IPAM plan: which CIDRs, how many subnets, global vs regional resources, MTU, and what happens when address space collides.
**How RAD implements it** — One standalone custom-mode VPC per project:
| Variable / behavior | Default |
|---|---|
| VPC `vpc-network-{resource_prefix}` — custom-mode (subnets are not auto-created) | always |
| `availability_regions` — one subnet per listed region | `["us-central1"]` |
| `subnet_cidr_range` — one CIDR per region, validated 1–2 entries | `["10.0.0.0/24"]` |
| Subnet description `managed-by=services-gcp` — the discovery contract used by app modules | always |
The deterministic IPAM pattern is worth studying closely. When no Services_GCP VPC exists, `App_CloudRun` and `App_GKE` provision *inline* VPCs whose subnet CIDR is a deterministic /24 carved out of `192.168.0.0/16` — derived from a SHA-256 of the deployment suffix — so multiple standalone deployments never advertise the same CIDR into the shared PSA peering. The inline GKE path goes further: pod ranges from `10.0.0.0/8` and **service ranges from `100.64.0.0/10`** — RFC 6598 shared address space, a live example of non-RFC 1918 IP planning.
The discovery layer runs `gcloud compute networks subnets list --filter="description~managed-by=services-gcp"` and also harvests network *tags* from existing ingress firewall rules so Cloud Run's VPC interface carries the right tags.
**Try it**
1. In your deployment portal, redeploy Services_GCP with `availability_regions = ["us-central1", "us-west1"]` and `subnet_cidr_range = ["10.0.0.0/24", "10.0.1.0/24"]`.
2. Verify the subnet layout and that the VPC is custom mode:
```bash
gcloud compute networks describe vpc-network- \
--format="value(x_gcloud_subnet_mode,routingConfig.routingMode)"
gcloud compute networks subnets list \
--network=vpc-network- \
--format="table(name,region,ipCidrRange,description)"
```
3. **Console > VPC network > VPC networks** — open the network and note the MTU column (the modules never set it, so it is the default 1460).
4. You know it worked when two subnets appear, one per region, each carrying the `managed-by=services-gcp` description.
**Check yourself**
Q1: Two App_GKE deployments in one project, no Services_GCP. Why is the hashed-CIDR scheme necessary rather than a fixed 192.168.0.0/24 for both?
A: Both inline VPCs peer with the same Service Networking producer via PSA. If two consumer VPCs advertise identical subnet CIDRs, the producer installs a return route for only one of them, silently black-holing reply traffic for the other deployment. Deterministic, hash-distinct /24s guarantee non-overlapping advertisements — the same reason on-prem/cloud IP plans must never overlap.
Q2: A customer needs 40 service projects to share one network with centralized firewall administration. Standalone VPCs with peering, or Shared VPC?
A: Shared VPC. Peering does not scale administratively (full mesh, non-transitive, per-VPC firewall ownership) and has peering-group route limits. Shared VPC keeps subnets, routes, and firewall rules in one host project while service projects attach workloads via `roles/compute.networkUser` on specific subnets. RAD's "one VPC per project" model deliberately avoids this — know both.
**Beyond the modules** — Not implemented and heavily tested: **Shared VPC** (host/service projects, subnet-level IAM — try `gcloud compute shared-vpc enable HOST_PROJECT` in a scratch org), **VPC Network Peering** between your own VPCs (`gcloud compute networks peerings create`, remember non-transitivity and no overlapping CIDRs), **NCC star/mesh** topologies for many-VPC designs, **IPv6** (dual-stack subnets, `--stack-type=IPV4_IPV6`), **BYOIP/PUPI**, **Private NAT** for overlapping ranges, **MTU** decisions (1460 default, 8896 jumbo for intra-VPC and supported Interconnect), and **NVA insertion** with custom/policy-based routes plus internal LB. Study pages: "Shared VPC overview", "VPC Network Peering", "Create and use IPv6", "MTU of a VPC network".
**⚠️ Exam trap** — Subnets are regional; VPCs and their routing tables are global. "Create one subnet per zone" is wrong, and a VM in `us-west1` reaches a `us-central1` subnet with no extra routing. Don't confuse the *dynamic routing mode* (regional vs global, affects only Cloud Router-learned routes) with subnet reach.
---
## 1.3 Designing a resilient and performant hybrid and multi-cloud network
> ⏱ ~60 min study · 💰 no platform cost · ⚙️ Requires: nothing deployed — concept-only
**Why the exam cares** — Choosing between Dedicated Interconnect (10/100 Gbps, your own colo presence), Partner Interconnect (50 Mbps–50 Gbps via a provider), Cross-Cloud Interconnect (to AWS/Azure), and HA VPN (encrypted, internet-transported, 99.99% with two tunnels per interface) is the single most repeated decision pattern on this exam, along with the 99.9% vs 99.99% Interconnect SLA topologies and hybrid DNS forwarding design.
**How RAD implements it** — Not implemented by the foundation modules. The only adjacent artifacts: the Cloud Router (ASN `64514`, no BGP peers — it exists to anchor Cloud NAT), and the PSA peering's custom-route export, which is exactly the knob you would flip so an on-prem network could reach Cloud SQL private IPs over a future VPN/Interconnect.
**Try it**
1. Even without hybrid links, you can inspect the building blocks the modules leave behind:
```bash
gcloud compute routers list --format="table(name,region,network,bgp.asn)"
gcloud compute routers describe vpc-network--nat-gw-us-central1 \
--region=us-central1 --format="yaml(bgp,nats[].name)"
```
2. Note `bgp.asn: 64514` (a private ASN) and that there are no `bgpPeers` and no `interfaces` — contrast with what an HA VPN attachment would add.
3. You know you understand it when you can explain why this router could later host both NAT and VPN BGP sessions on the same network.
**Check yourself**
Q1: An enterprise needs 99.99% SLA connectivity to on-prem with encryption in transit. Which design?
A: HA VPN over Cloud Interconnect (or plain HA VPN if Interconnect isn't justified). The 99.99% Interconnect SLA requires four VLAN attachments across two metros (two edge availability domains each) with global dynamic routing; Interconnect alone is not encrypted, so the exam answer for "encrypted + 99.99%" is HA VPN over Interconnect, or MACsec on supported Interconnect connections.
Q2: On-prem hosts must call Google APIs privately through the Interconnect. What do you configure?
A: Advertise `199.36.153.4/30` (restricted.googleapis.com) or `199.36.153.8/30` (private.googleapis.com) from Cloud Router as a custom route advertisement, create a Cloud DNS private zone for `googleapis.com` mapping `*.googleapis.com` to those VIPs, and make it resolvable on-prem via DNS forwarding/inbound server policy. Note RAD's GKE NetworkPolicy already allowlists exactly those two /30s for pod egress — same VIPs, different enforcement point.
**Beyond the modules** — Study the full 1.3 list deliberately: Dedicated vs Partner vs Cross-Cloud Interconnect ("Cloud Interconnect overview"); HA VPN topologies incl. VPN between two VPCs; regional vs global dynamic routing mode and its effect on which subnets Cloud Router advertises; accessing multiple VPCs from on-prem (per-VPC attachments vs NCC hub); hybrid DNS (forwarding zones, inbound DNS policies, DNS peering, cross-project binding); IP planning across on-prem and cloud (internal ranges, Private NAT for overlap); MTU over hybrid links (1440 typical for VPN, up to 8896 on Interconnect); MACsec. Scratch-project commands worth memorizing: `gcloud compute vpn-gateways create` (HA VPN gives two interfaces automatically), `gcloud compute interconnects attachments partner create`, `gcloud compute routers add-bgp-peer`.
**⚠️ Exam trap** — "Global dynamic routing makes my VPN highly available" — no. Routing mode controls which *subnets* are advertised/learned across regions; HA comes from redundant tunnels/attachments and BGP failover (optionally accelerated with BFD).
---
## 1.4 Designing for Google Kubernetes Engine
> ⏱ ~60 min · 💰 Autopilot cluster cost while deployed · ⚙️ Requires: GKE Network Lab profile
**Why the exam cares** — GKE IP exhaustion is a classic incident: the exam tests sizing the node subnet, pod secondary range, and service secondary range *before* cluster creation, choosing public vs private nodes and control-plane endpoints, and matching node pools to workload needs.
**How RAD implements it** — The platform is a worked example of deterministic multi-cluster IP planning. For cluster *i*, each range is sliced out of a base CIDR using the cluster index:
| Range | Derivation | Cluster 1 result (defaults) |
|---|---|---|
| Node subnet | a /20 spaced 16 apart inside `gke_subnet_base_cidr` (`10.128.0.0/12`) | `10.128.0.0/20` (4,094 nodes) |
| Pod range | a /14 slice of `gke_pod_base_cidr` (`10.64.0.0/10`) | `10.64.0.0/14` (~262k pod IPs) |
| Service range | a /20 slice of `gke_service_base_cidr` (`10.8.0.0/16`) | `10.8.0.0/20` (4,094 services) |
Each subnet carries two **named secondary ranges** (`gke-{prefix}-pods-{i}`, `gke-{prefix}-services-{i}`) — i.e., VPC-native/alias-IP clusters. Other verified design choices: `gke_cluster_mode` default `AUTOPILOT` (or `STANDARD` with an explicit node pool: `gke_node_machine_type` default `e2-standard-4`, autoscaling `gke_node_min_count` 1 to `gke_node_max_count` 5, `pd-balanced` disks, Shielded nodes);release channel `REGULAR`; **private nodes** — `private_cluster_config { enable_private_nodes = true }` plus a control-plane-only `/28` from `gke_master_base_cidr`, required because RAD-managed projects deny `compute.vmExternalIpAccess`; `enable_private_endpoint` is left `false`, so the control-plane endpoint stays public for CI/CD. The inline cluster additionally configures master authorized networks with Google public CIDR access enabled *plus* a `0.0.0.0/0` block so Cloud Build workers can reach the API server.
**Try it**
1. Deploy the GKE Network Lab profile, then map the IP plan end to end:
```bash
gcloud container clusters describe gke-cluster-1- \
--location=us-central1 \
--format="yaml(clusterIpv4Cidr,servicesIpv4Cidr,ipAllocationPolicy,datapathProvider,privateClusterConfig)"
gcloud compute networks subnets describe vpc-network--gke-subnet-1-us-central1 \
--region=us-central1 \
--format="yaml(ipCidrRange,secondaryIpRanges)"
```
2. Confirm `privateClusterConfig.enablePrivateNodes: true` (nodes have no external IPs) and `datapathProvider: ADVANCED_DATAPATH`.
3. In your portal, set `gke_cluster_count = 2` and redeploy: observe cluster 2 receive `10.68.0.0/14` pods and `10.8.16.0/20` services — non-overlapping by construction.
4. You know it worked when `kubectl get pods -o wide` shows pod IPs inside the cluster's pod CIDR rather than the node CIDR (alias IPs in action):
```bash
gcloud container clusters get-credentials gke-cluster-1-